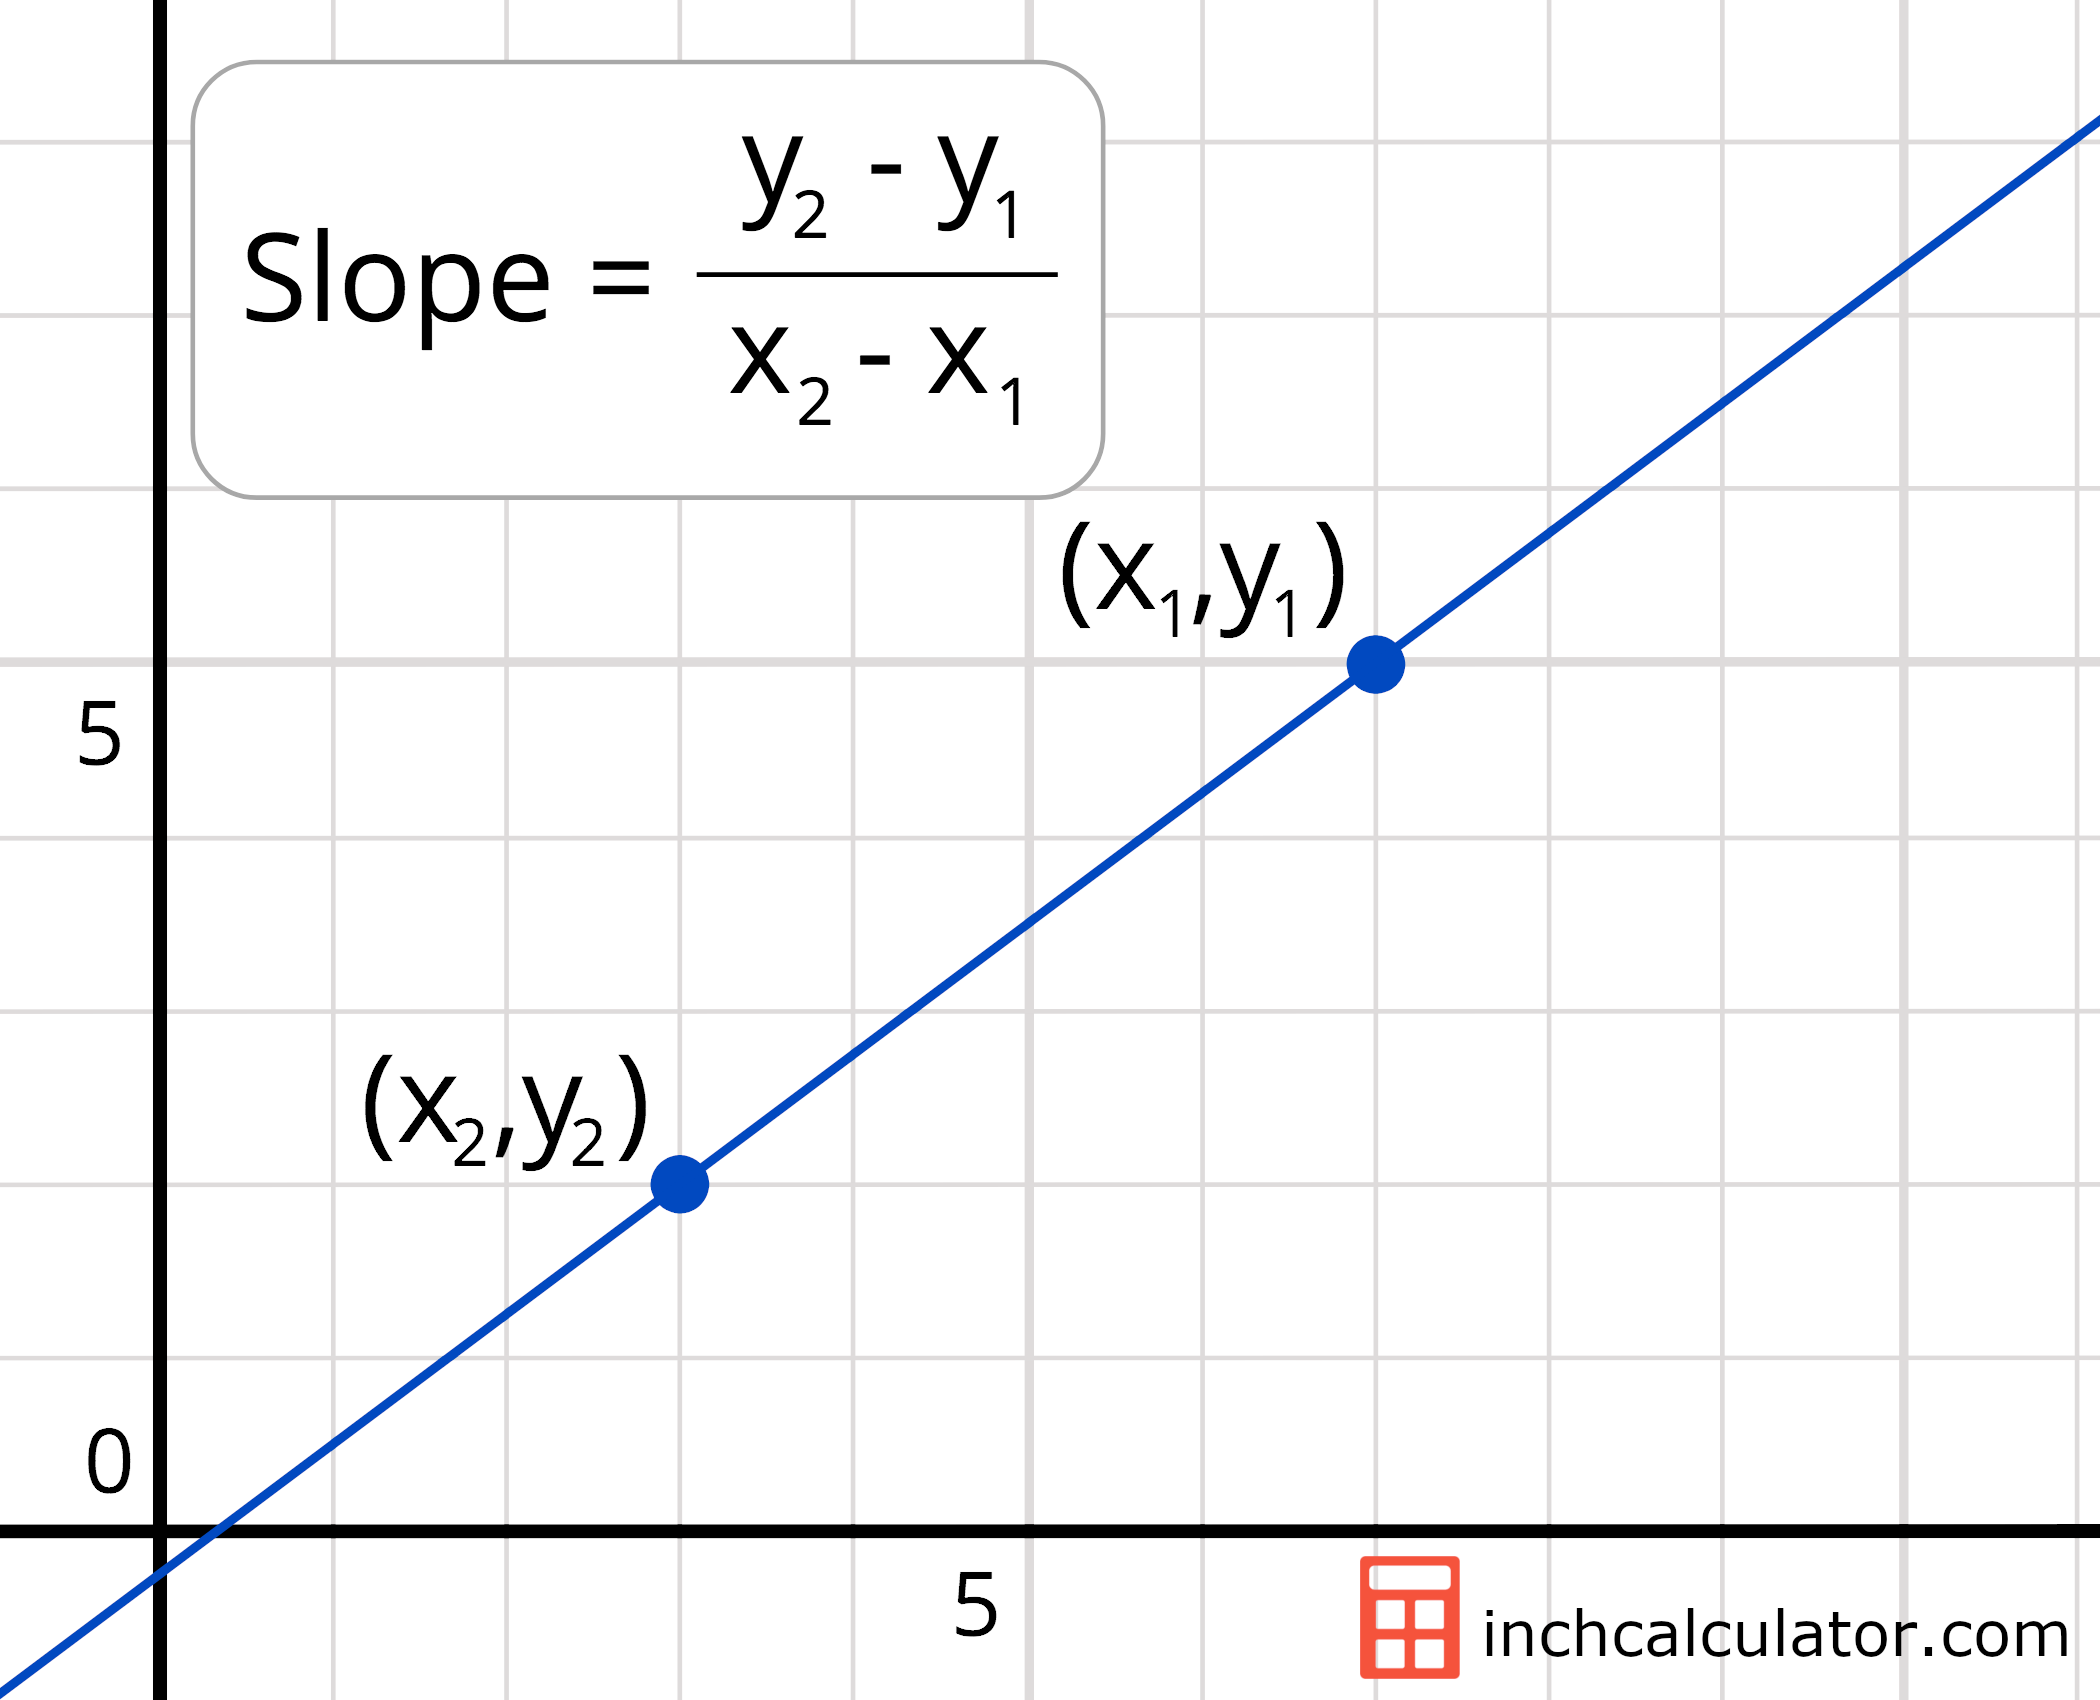Getting the slope right the first time
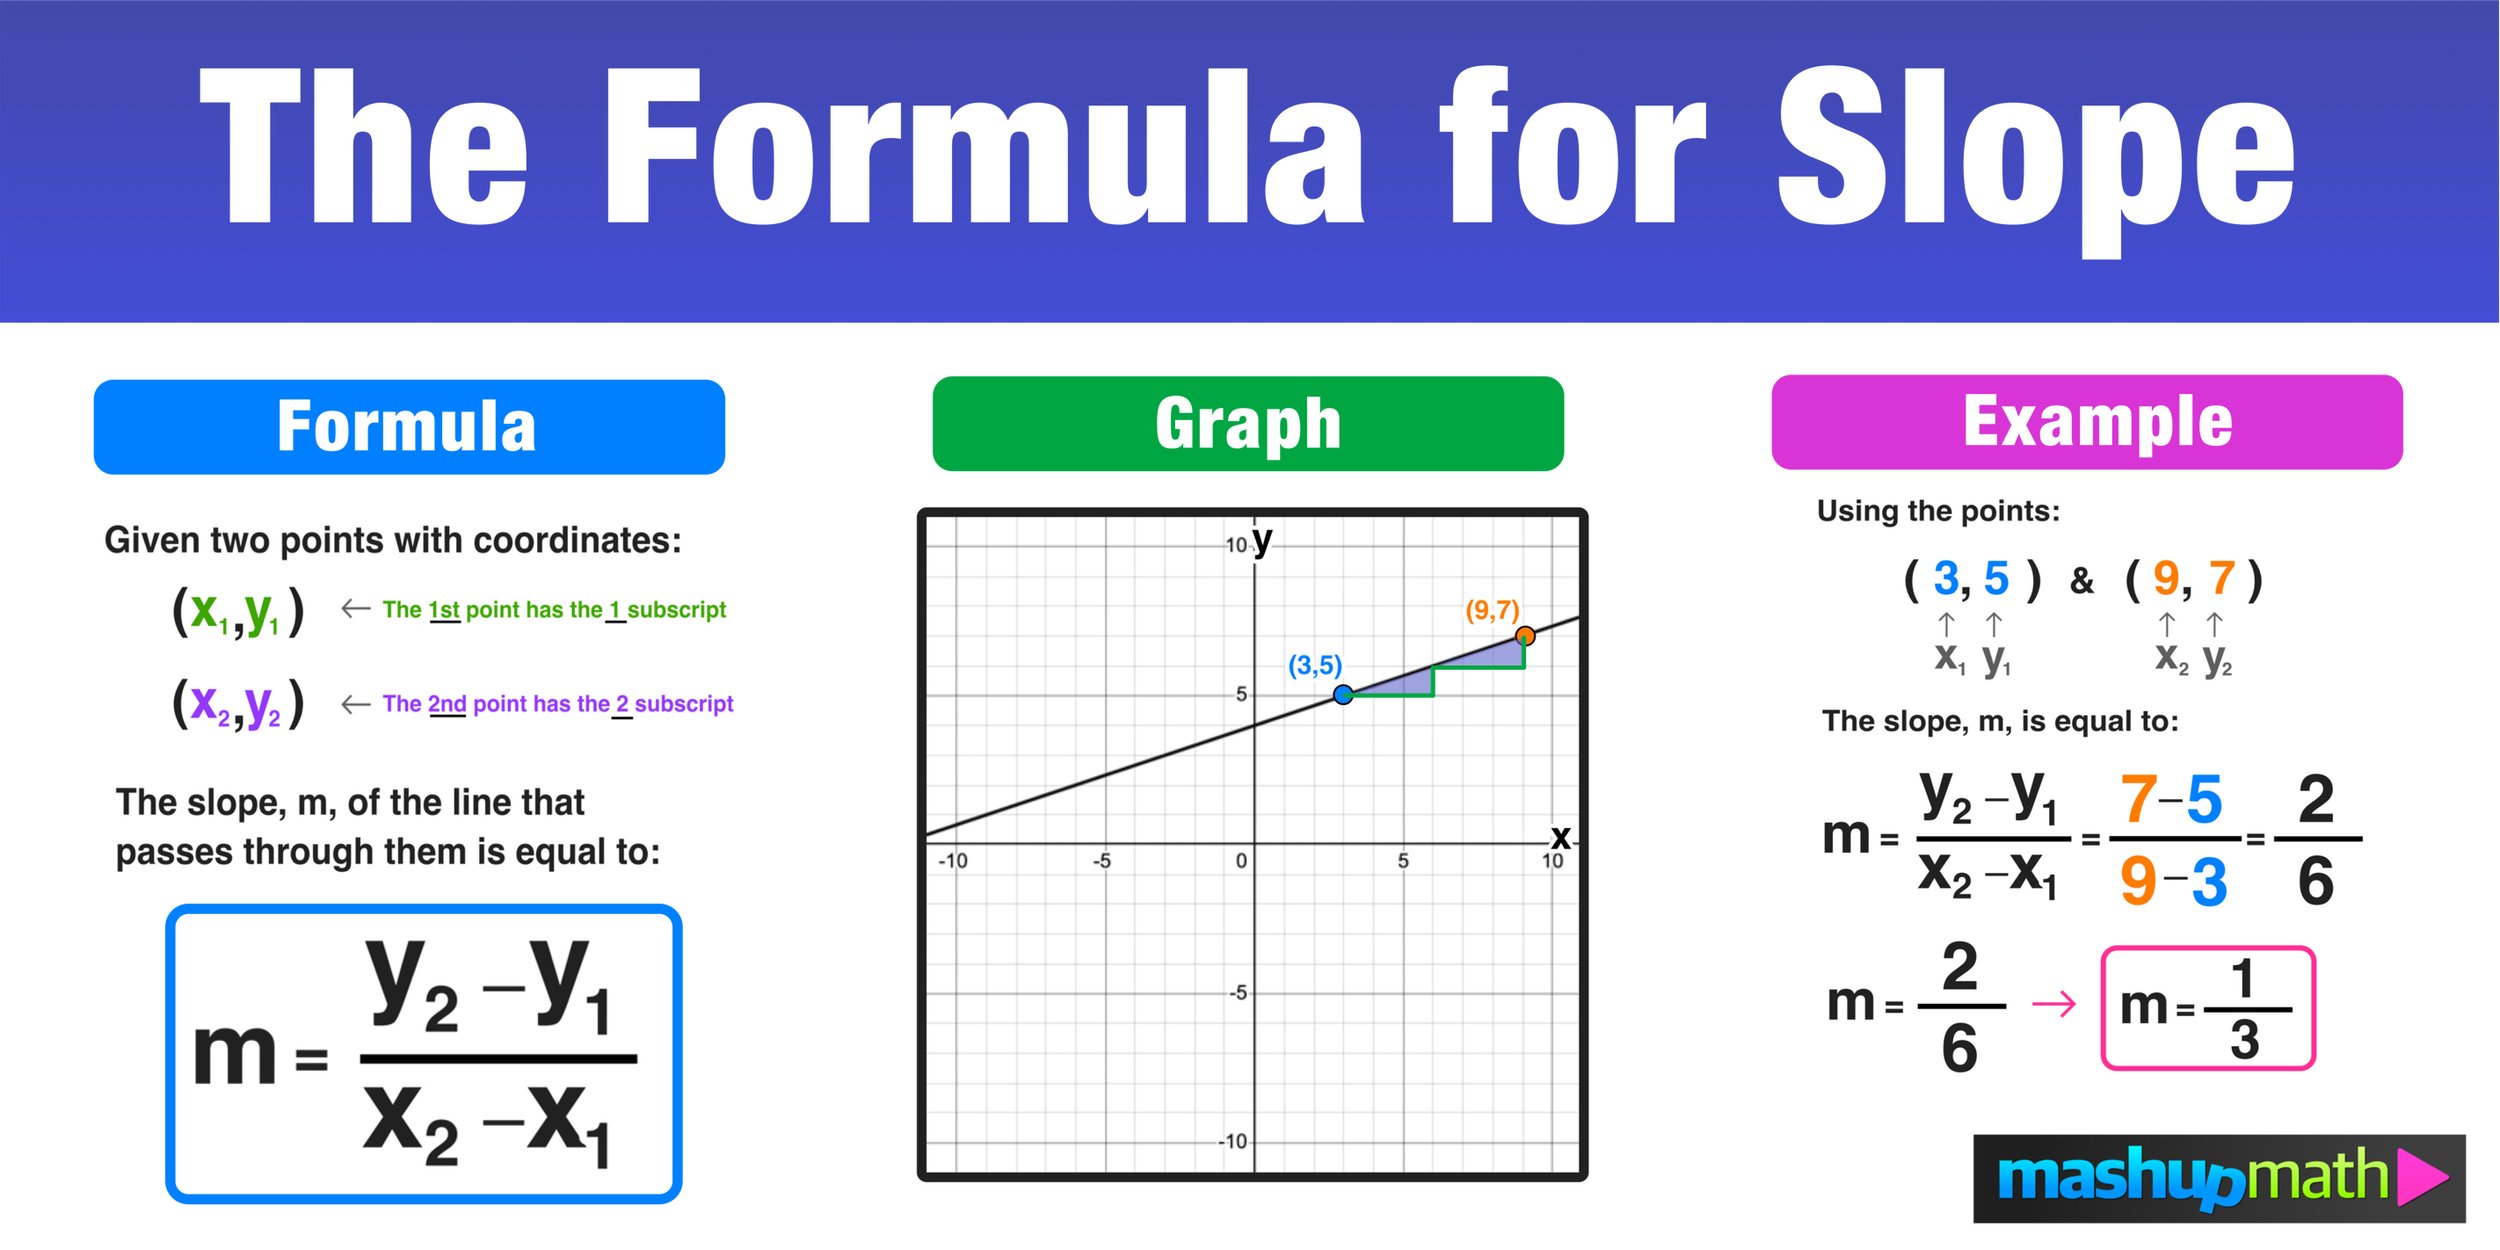
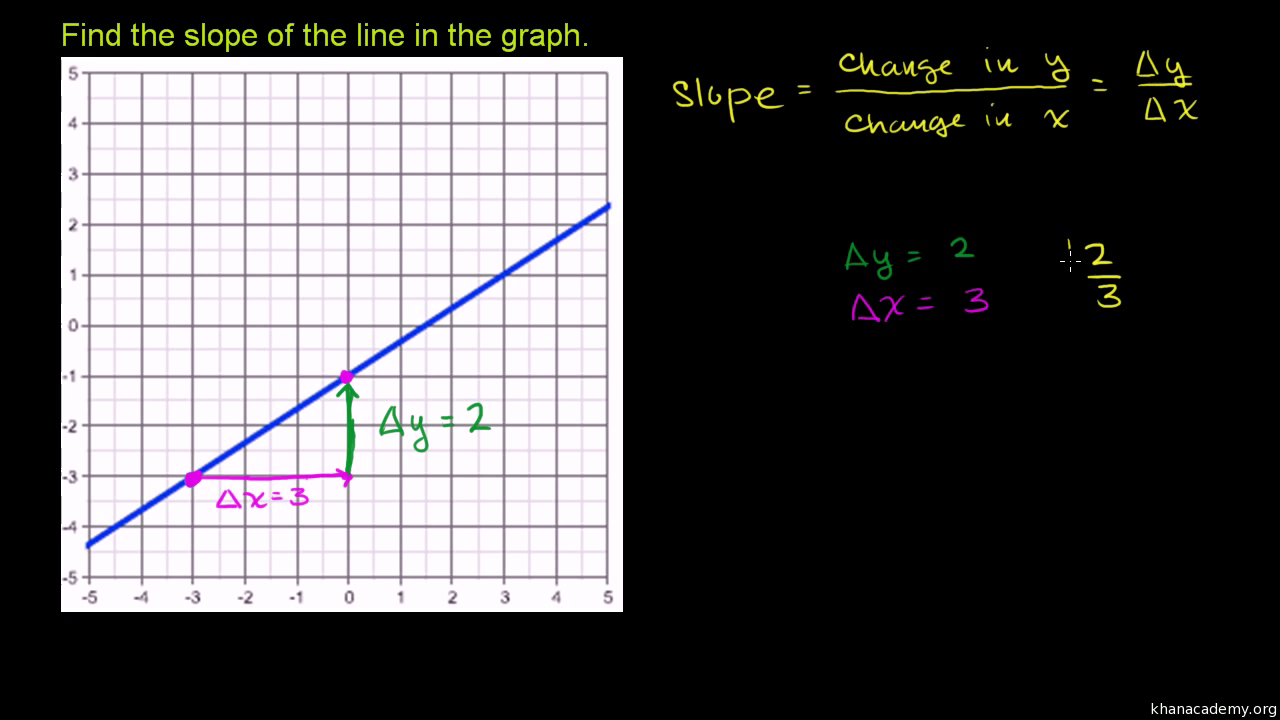
The slope of a line tells you how much y changes for each unit of x. That is it. Most people learn it as rise over run, plug numbers into a formula, and call it done. The formula is straightforward: take two points on the line, subtract their y values, divide by the difference of their x values, and you are done. But real data is rarely that clean, and treating slope as just a formula gets you into trouble fast. At its core, slope is a rate. When a graph plots one variable against another, the slope at any point is the instantaneous rate of change, which is the derivative if the function is smooth, or just the average rate between two measured points if you are working with raw data. On a straight line, the slope is constant everywhere. On a curve, it changes from point to point, and you need calculus or a local linear approximation to find it. I have seen people treat every graph as if it has a single slope. That assumption is only valid for linear relationships. Most engineering and scientific plots are not linear over their full range. A load-deflection curve starts stiff, softens, then yields. A temperature response to a heater ramps up exponentially and then plateaus. Declaring one slope for that entire curve is wrong, and the error compounds when you use it to predict anything beyond your measured range.
Here is the practical method I use when someone hands me a graph and asks for the slope. First, identify the region of interest. Second, verify linearity in that region by checking whether the data actually hugs a straight line. Third, pick two points that are far apart within that region to minimize rounding error. Fourth, compute the rise divided by the run. If the data is scattered, fit a least squares line and report the fitted coefficient rather than eyeballing two points. The fitted slope is the best estimate under the standard assumptions of normally distributed residuals with constant variance. Let me walk through a concrete example. I had a sensor dataset where voltage was recorded against strain. The first 100 data points looked roughly linear on paper. I plotted them, computed the correlation coefficient, and got about 0.998. Then I fitted a simple linear regression and got a slope of 0.472 volts per microstrain with a standard error of 0.003. That gave me a usable calibration factor for that range. If I had just picked the first and last point in that set, I would have gotten 0.468, which is close but not identical, and it would have been more sensitive to any noise at the endpoints. There is a common pitfall that catches people regularly. When axes are not plotted from zero or use a non-linear scale, the visual slope is meaningless. A log-log plot of a power law will look like a straight line, and its slope is the exponent. A semi-log plot of an exponential will look linear, and its slope encodes the time constant. If you read the visual steepness directly without accounting for the axis scale, your number will be off by orders of magnitude. Always check the axis labels and the tick spacing before computing or interpreting slope from a plot.
Another issue I run into constantly is unit confusion. If the x-axis is in milliseconds and the y-axis is in millivolts, the slope you compute is in millivolts per millisecond. People often forget to convert these to base units and then wonder why their result does not match the published value. In my experience, carrying the units through the entire calculation and writing them on every intermediate step cuts down debugging time significantly. It also makes it obvious when a sign error flips your direction, which happens more often than most people want to admit. When dealing with noisy experimental data, the naive approach of averaging local differences between adjacent points produces a terrible slope estimate. The noise gets amplified because you are dividing tiny differences by tiny deltas. Instead, use a proper linear fit over a reasonable window. For time-series data, a rolling regression with a window size chosen based on the signal-to-noise ratio gives you a local slope track that is stable enough to analyze without smoothing away real dynamics. I usually pick a window that covers at least ten times the dominant noise period, which keeps the variance of the slope estimate manageable while preserving the underlying trend. The slope of a horizontal line is zero. The slope of a vertical line is undefined because the run is zero and division by zero is not allowed. This is not a trick question. I have seen engineers plug vertical segments into code that assumes finite slopes and then spent hours chasing segmentation faults or NaN outputs. If your data includes vertical transitions, detect them explicitly and handle them as a separate case before any downstream computation touches them.
Get the Full Details

Here is an edge case that cost me a day once. I was analyzing a pressure-transient test where the gauge switched ranges automatically. The raw data looked continuous, but at the switch point the x-axis values had a small offset due to a timestamp alignment bug in the logger. The visual graph showed a sharp kink, and when I computed the slope across that point, I got a number that implied the system was destabilizing. It was not. It was a one-point timing glitch. I found it by overlaying the raw timestamps, computing the first difference of the x values, and looking for outliers. The fix was to flag and interpolate across the affected interval before fitting. If you ever see a slope that contradicts physical intuition, check the raw data alignment before blaming the model. For curves, you can approximate the slope locally using a small delta. The smaller the delta, the closer you get to the true derivative, but noise becomes dominant as the delta shrinks. There is a tradeoff here. In practice, I use central differences with a delta chosen to balance truncation error against measurement noise. For most lab data sampled at a few hertz, a delta of five to ten samples works well. If you are working with high-frequency data, the optimal delta shifts higher because the noise floor is fixed while the signal changes faster. Another advanced nuance that people miss is that slope depends on which variable you put on which axis. Mathematically, you should put the independent variable on x and the dependent variable on y. But in many instruments and published plots, that convention is ignored. If you compute the slope by swapping axes, you get the reciprocal of the correct slope, which is only acceptable if you explicitly intend to invert the relationship. I once saw a report where the authors regressed x on y instead of y on x and reported the slope as if it were the forward relationship. The numbers were reciprocals, and the conclusions were reversed. Always verify the regression direction matches the causal or experimental setup.
Software tools make this easy, but they also make it easy to be careless. Most graphing packages have a trendline feature that fits a line and reports the slope. That is convenient, but the default behavior varies by program. Some fit by least squares in y, some in x, some use orthogonal regression. Read the documentation or inspect the method. A quick way to check is to perturb one point and see how the reported slope moves. If it moves in a way that does not match your expectation for a standard fit, the software is doing something non-obvious. If you need the slope for a discrete dataset without fitting, the fastest reliable approach is to bin the data into intervals, compute the mean x and mean y in each bin, and then apply the two-point formula to the binned centers. Binning reduces noise and gives you a slope that represents the trend over the chosen range. The bin width should be large enough to suppress noise but small enough to capture the feature you care about. As a rule of thumb, aim for a bin count between twenty and fifty for typical engineering datasets. More bins than that and noise resurfaces. Fewer bins and you lose resolution. One more practical note about reporting. Always include the units, the fitted method, the confidence interval or standard error, and the range over which the slope was computed. A slope without context is just a number. Two slopes that look similar can mean completely different things if one was measured over a narrow calibrated range and the other was extrapolated far outside the data. I have rejected papers and reports on exactly that basis. Slope is not a single property of a graph. It is a property of a model fitted to a specific region, under specific assumptions.