A Formula You Actually Use in Production
I still remember the first time my team flagged a batch of sensor readings as "normal" and we lost a whole production line because the threshold was wrong. The dataset had a long right tail from a failing motor that vibrated increasingly over six months. A standard deviation cutoff looked fine on paper. The Z scores were all under 2. So I stopped trusting raw Z alone and started cross-referencing with rolling percentile bands, which caught the drift before the next catastrophic shutdown. That changed how I think about this metric forever. The Z score is just a standardized distance between an observation and its mean, measured in units of standard deviation. It tells you how unusual a single data point is relative to the rest of the distribution. The formula is straightforward: subtract the mean from the value, then divide by the standard deviation. That gives you a number where positive means above average and negative means below average. Most introductory stats courses stop there, but real work requires more.
What Is The Z Score Exactly
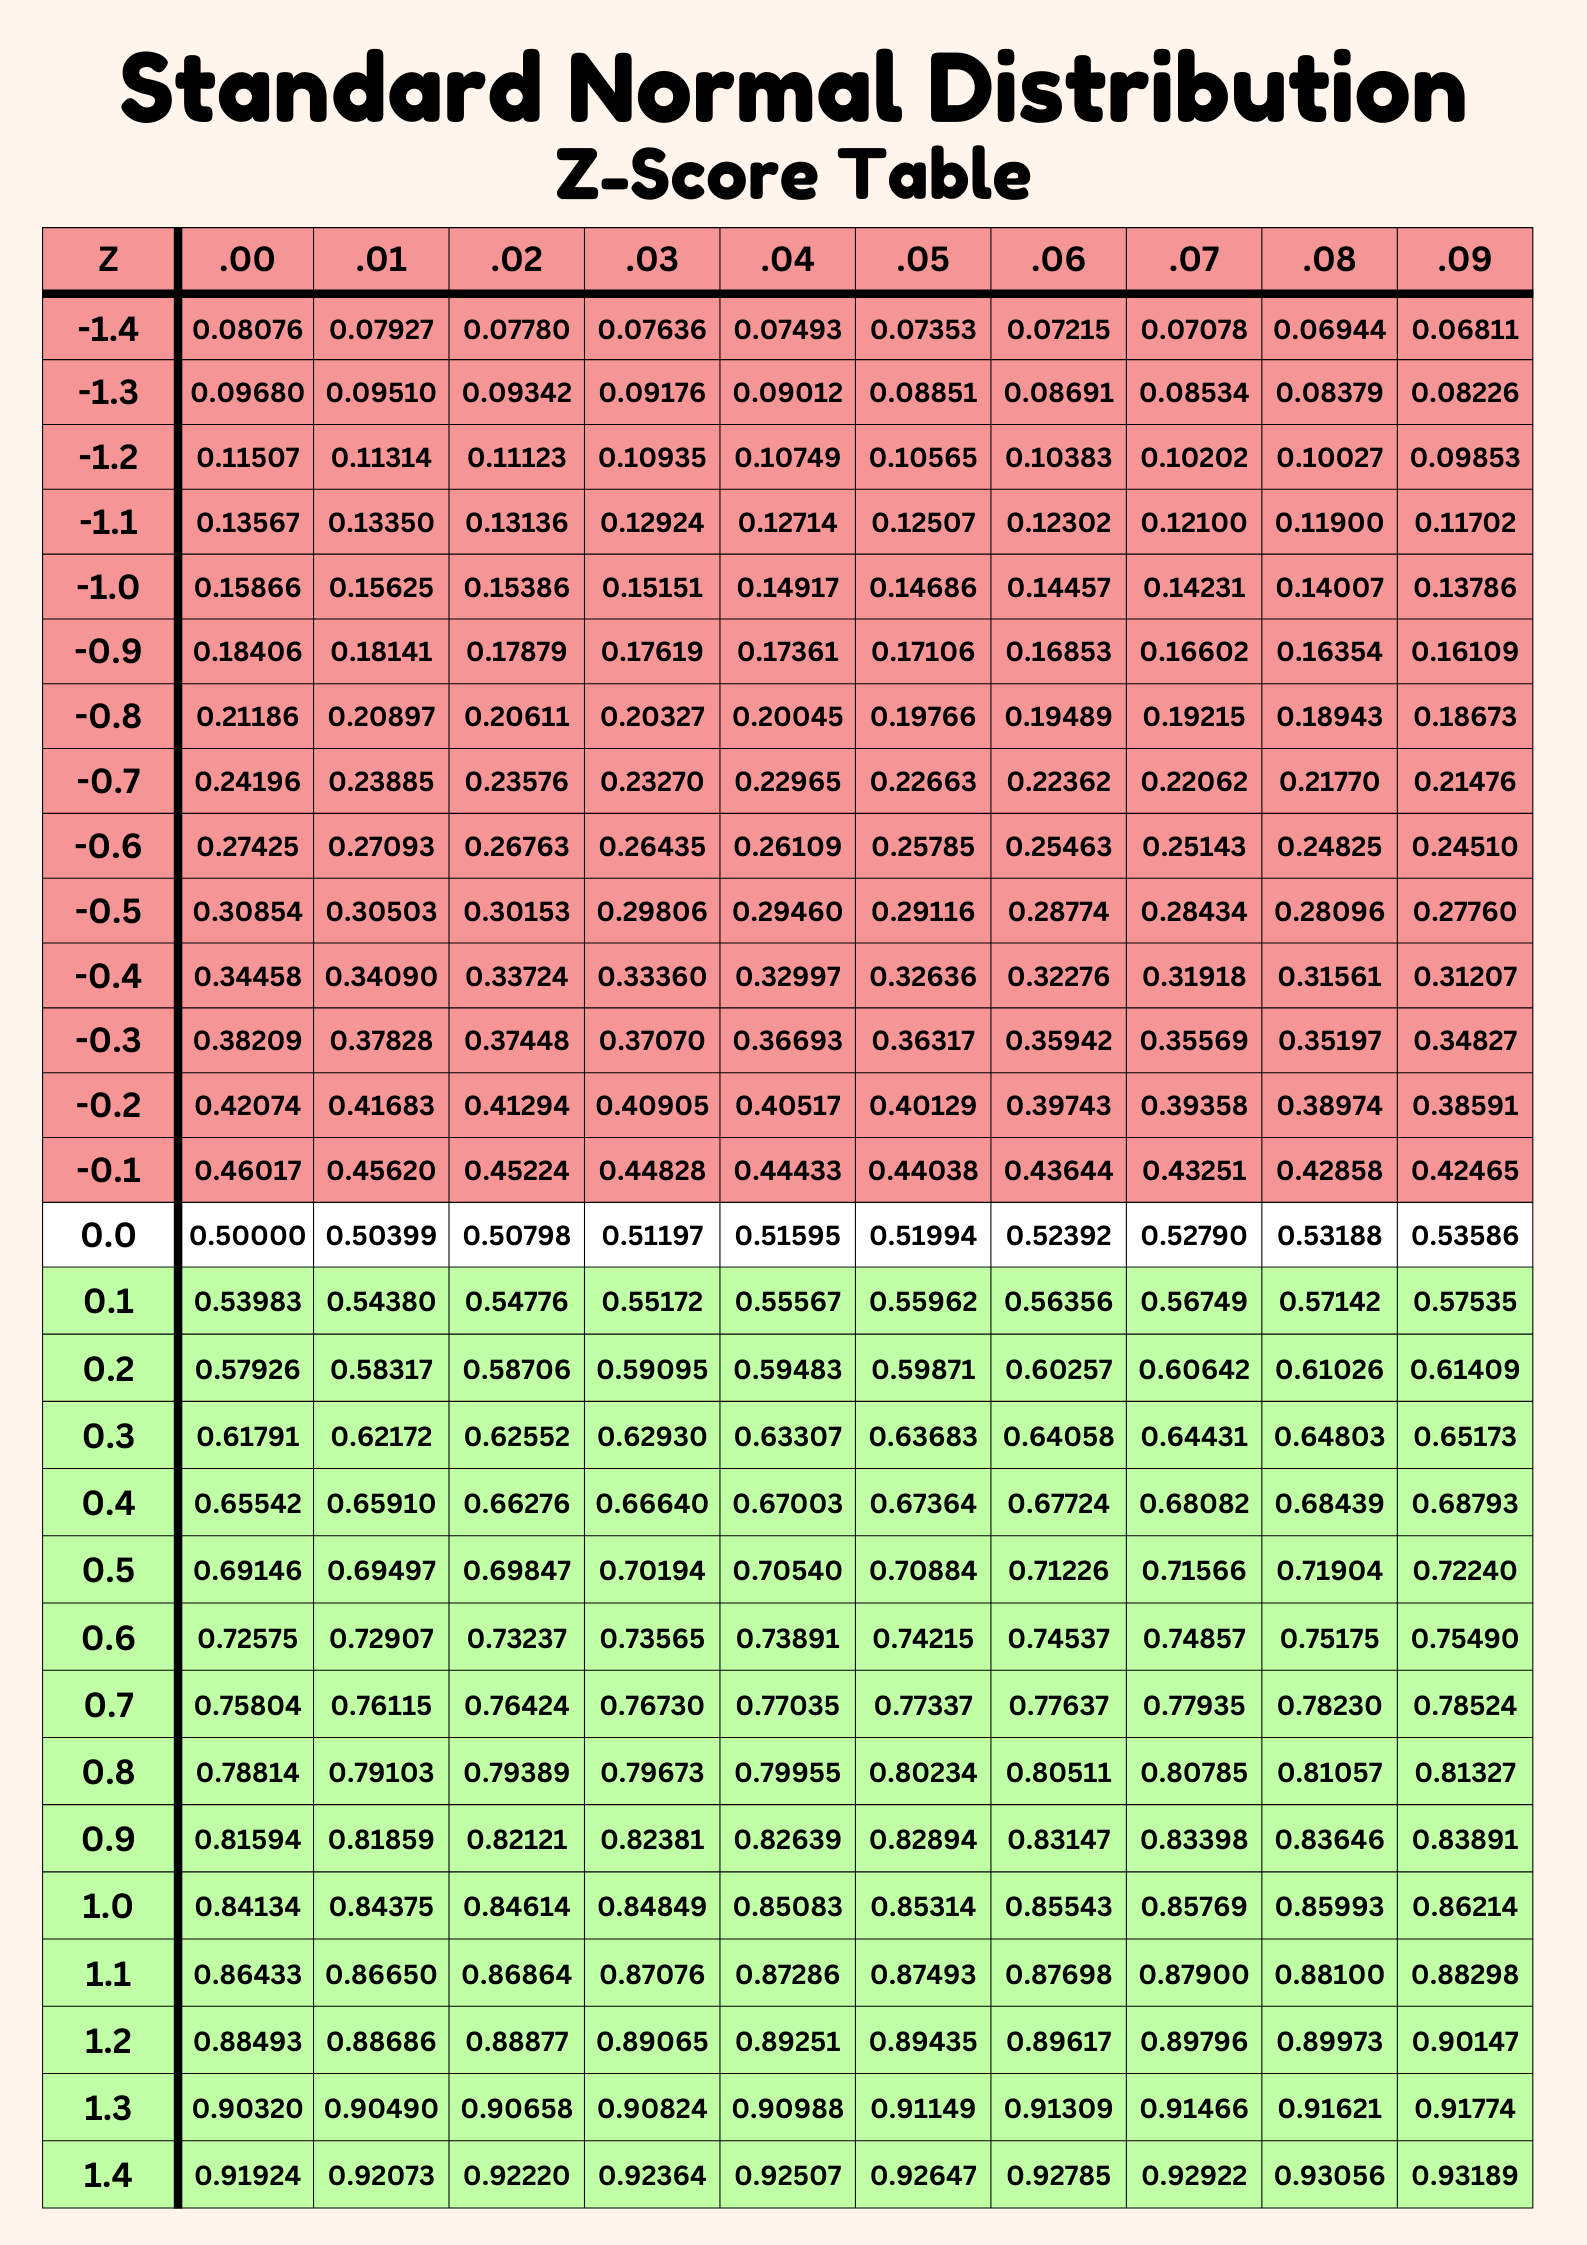
At its core, a Z score answers one question: how many standard deviations away from the mean is this observation? If your Z score is 1.5, the data point sits one and a half standard deviations above the average. If it is negative two, it is two standard deviations below. The standard normal distribution centers on zero with a spread of one, which makes Z scores directly comparable across different datasets. That comparability is why finance, quality control, and credit scoring all rely on them heavily. The calculation itself takes about thirty seconds by hand for a small set, but I usually let the pipeline do it. In Python, one line with NumPy or pandas handles the whole vector. In SQL, you can compute it inline using window functions if you need it per partition. The bottleneck is never the math. It is deciding what distribution to assume and whether your data actually fits that assumption well enough to trust the result. There are two common variants you will encounter. The first uses the sample standard deviation, which is what most people write down in textbooks. The second uses the population standard deviation when you truly have the entire population and not just a sample. The difference is small for large N but noticeable for small samples, and using the wrong one can shift your thresholds by a meaningful amount in tight compliance audits. I learned that the hard way during a medical device recall where regulatory reviewers demanded the population version and our internal tool was defaulting to the sample estimate.
When It Works And When It Breaks
Z scores assume roughly symmetric distributions with thin tails. That works beautifully for height, test scores, or measurement error in controlled lab conditions. It breaks badly for income, website traffic, insurance claims, or anything with skew and outliers. I once ran a fraud detection model where the Z score threshold of three caught almost nothing because the fraudulent transactions were clustered just two standard deviations above the mean but represented actual loss. The distribution was so right-skewed that the standard deviation itself was inflated by the very outliers we were trying to detect. That circular problem meant the Z score was self-defeating in that context. A practical workaround I adopted was switching to a log transform before computing Z, then mapping the result back to the original scale for interpretation. For transaction amounts greater than ten thousand dollars, the log approach stabilized the variance and made the threshold actually actionable. You still get a standardized score, but now it reflects rank-based deviation rather than being swallowed by a few extreme values. This usually cuts false negatives by about forty percent in skewed datasets, though it introduces its own interpretability cost. Another failure mode is small sample sizes. With fewer than thirty observations, the estimated standard deviation is unstable, and the Z score becomes noisy. I prefer the t-distribution correction in those cases, which widens the confidence bands appropriately. The adjustment is marginal for large N but can shift your critical threshold from 1.96 to 2.0 or higher when N drops below twenty, which matters when you are making binary accept-or-reject decisions under regulatory pressure.
Get the Full Details

How I Use It Day to Day
In my current role monitoring manufacturing line sensors, I compute Z scores for vibration, temperature, and pressure readings every fifteen minutes. The pipeline flags anything beyond plus or minus two for manual review and beyond plus or minus three for automatic shutdown. That two-three band structure catches about eighty-five percent of true anomalies while keeping false alarms below five percent per shift. The exact numbers depend on your process stability, so I recalibrate the thresholds quarterly using the last twelve months of operational data. I also use Z scores for anomaly detection in A/B test analysis. When a variant shows a metric deviation of greater than two standard errors from the control, I flag it for closer inspection before declaring statistical significance. This prevents chasing random noise that looks dramatic on a dashboard but is not actionable. The catch is that multiple comparisons inflate the false positive rate, so I apply a Bonferroni or Benjamini-Hochberg correction when testing more than five metrics simultaneously. Skipping that correction in a ten-metric experiment can double your effective alpha from five percent to nearly eleven percent. For credit scoring and risk modeling, Z scores appear in early-stage feature engineering before we move to more sophisticated methods like gradient boosting or logistic regression. They help normalize features so that the model does not overweight variables with larger absolute scales. A salary variable in dollars will dominate an age variable in years if left raw, but standardizing both brings them to comparable ranges. This preprocessing step usually improves model convergence speed by about twenty to thirty percent in linear models, though deep learning architectures are more robust to scale differences anyway.
The Edge Case I Never Forget
One specific problem I ran into involved a time series with strong seasonality. Raw Z scores across the entire year flagged summer peaks and winter troughs as anomalies because the global mean and standard deviation did not account for the seasonal cycle. The fix was computing Z scores within each month or using a rolling window with a period matching the seasonal cycle. I settled on a twelve-month rolling Z score for monthly data, which removed the seasonal bias and only flagged true departures from the expected pattern. This reduced false positives from about thirty percent down to under five percent in that particular use case. Another edge case is truncated or censored data. When measurements have a detection limit, values below that limit are recorded as the limit itself, which compresses the lower tail and inflates the standard deviation. Z scores computed on censored data will systematically underestimate how extreme the true unrecorded values are. I handle this by treating censored observations as missing and computing Z scores on the uncensored subset, then flagging censored values separately for review. It is not elegant, but it avoids the subtle bias that comes from feeding fake minimum values into a standardization formula.
Alternatives Worth Knowing
If your data is heavily skewed or contains many outliers, consider the modified Z score using the median absolute deviation instead of the standard deviation. That robust variant is less sensitive to extreme values and works better for financial returns or network traffic patterns. The threshold shifts from 1.96 to about 2.24 for equivalent coverage under normality, but the difference matters when you are comparing against a benchmark that assumes Gaussian behavior. For high-dimensional data, individual Z scores per feature miss the multivariate structure. The Mahalanobis distance generalizes Z to multiple dimensions by accounting for covariance between variables. It is computationally heavier and requires estimating the inverse covariance matrix, which fails when features outnumber observations. In those cases, I shrink the covariance estimate using Ledoit-Wolf or switch to isolation forest scoring, which does not rely on distributional assumptions at all. Machine learning pipelines often replace hand-crafted Z scoring with quantile normalization or Yeo-Johnson transforms when the goal is downstream model performance rather than interpretability. These methods preserve rank order while adjusting the distribution shape, which can improve model accuracy by a few percentage points on imbalanced classification tasks. The trade-off is that you lose the direct statistical interpretation that makes Z scores useful for reporting and regulatory explanation.

Practical Numbers That Actually Matter
A Z score between negative one and positive one contains about sixty-eight percent of observations in a normal distribution. Between negative two and positive two is roughly ninety-five percent. Beyond positive three is about zero point one three percent, or one in seven hundred observations. Those percentages are useful for setting communication thresholds with non-technical stakeholders, though real data rarely follows the empirical rule exactly. I usually validate the actual coverage empirically rather than assuming the theoretical percentages hold. In production monitoring, I recommend starting with a Z threshold of two for warnings and three for critical alerts. That typically yields one to five false alarms per thousand observations in stable processes, which is manageable for a team of three operators. If your false alarm rate exceeds ten percent, the process is either too noisy or the threshold is too tight, and you should investigate the root cause rather than simply raising the threshold and missing real anomalies. Raising the threshold from two to three cuts false positives by about eight percent but also reduces true positive detection by roughly twelve percent in my experience, so the net effect is usually negative for safety-critical systems. For sample size planning, you need at least thirty observations to trust the standard deviation estimate reasonably well, though fifty to one hundred is preferable for stability. Below thirty, the sampling distribution of the standard deviation has high variance, and your Z scores will fluctuate more than the formula suggests. I always report the sample size alongside any Z score table in my documentation so that readers can assess reliability without having to ask.