The Actual Mechanism Behind Making RNA From DNA
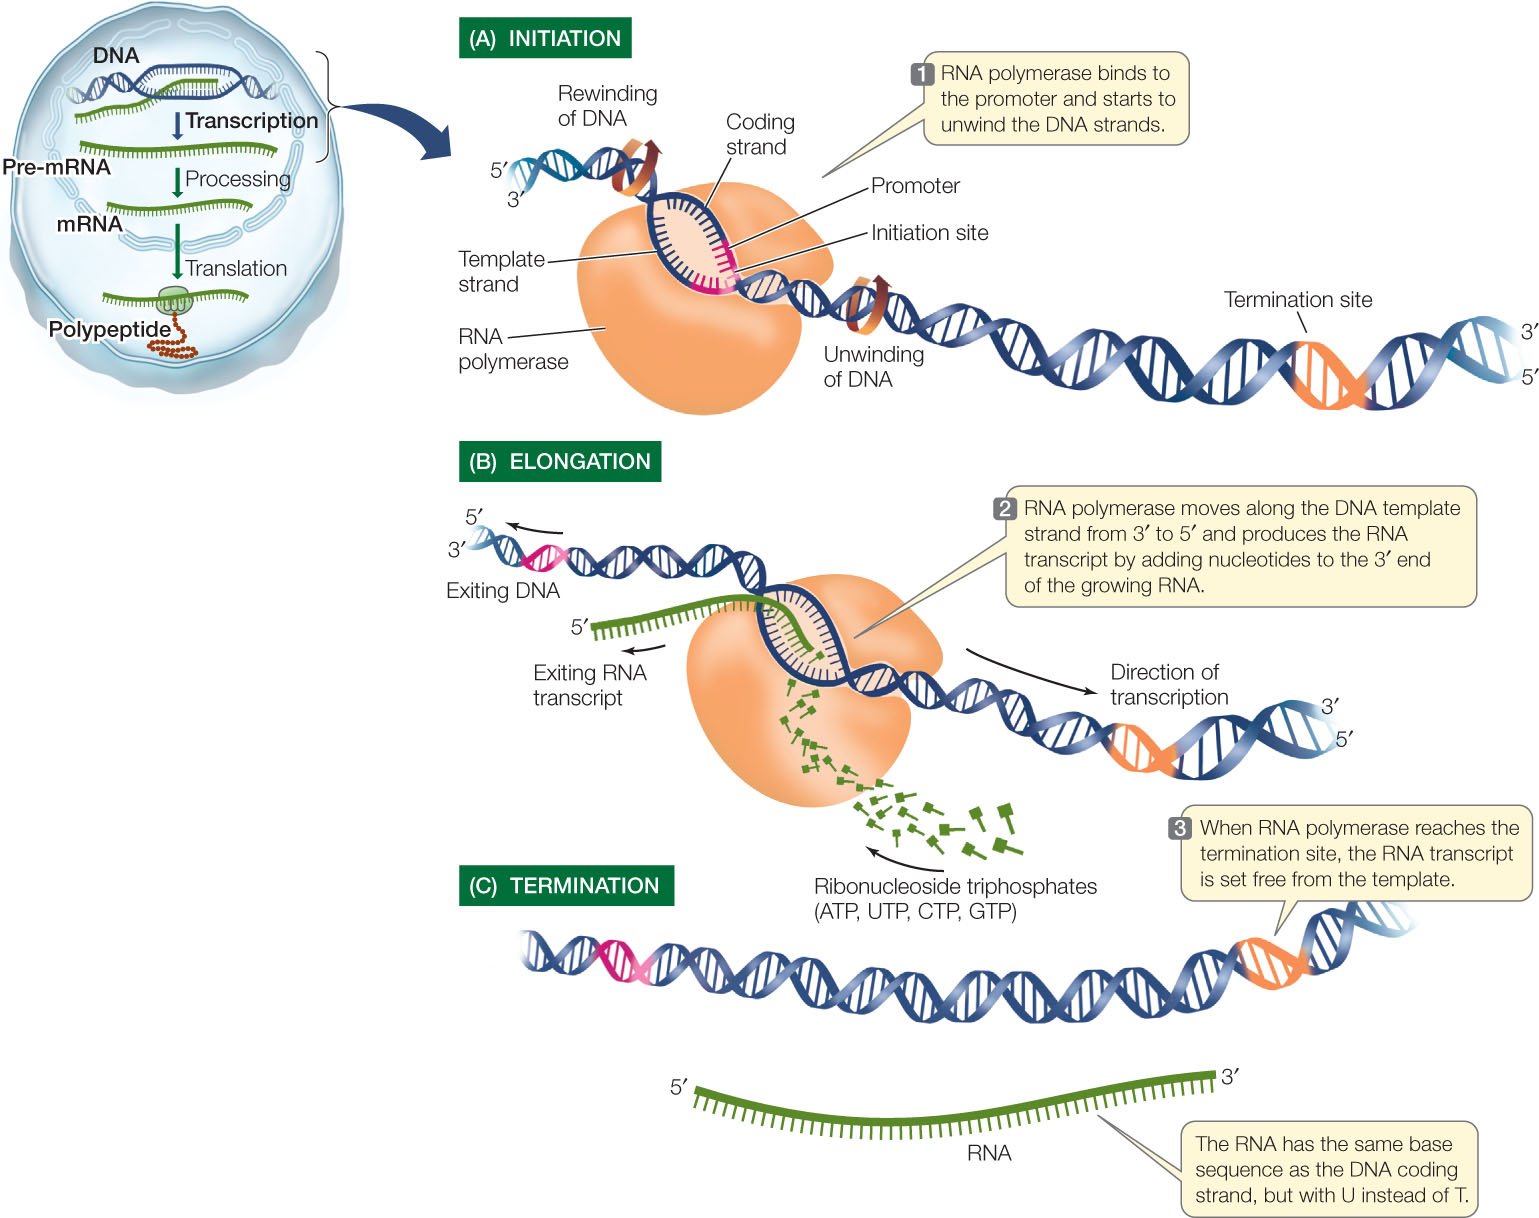
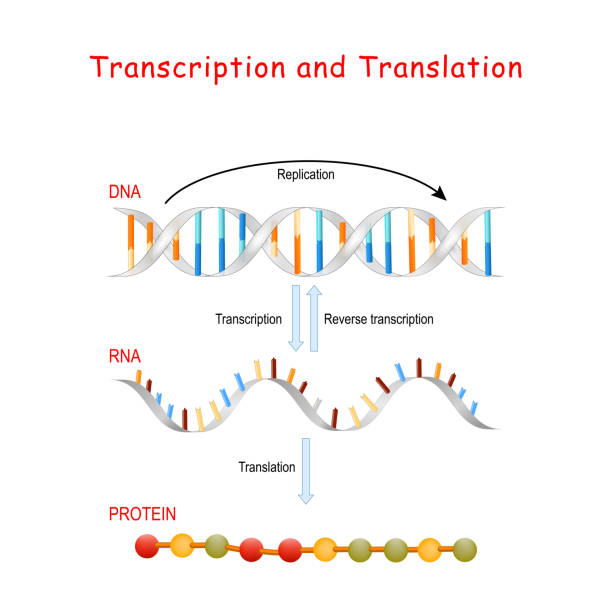
Transcription is when a cell copies a stretch of DNA into a complementary RNA strand. That's the short version. The long version involves several protein complexes, nucleotide triphosphates, and a process that most undergraduate biology courses compress into a single diagram you're expected to memorize for an exam. Let me walk through how this actually works before we get into the details people usually skip over. The enzyme responsible is RNA polymerase. It binds to a promoter region on the DNA, unwinds a small section of the double helix, and reads the template strand in the 3' to 5' direction while synthesizing the new RNA strand in the 5' to 3' direction. Uracil replaces thymine in the RNA product. The DNA rewinds behind the polymerase as it moves along. That's the core mechanism. Simple in description, messy in execution. I spent a week trying to figure out why my in vitro transcription reactions kept producing shorter, inconsistent RNA products. The problem wasn't the protocol I was following. It was the DNA template I was using. The plasmid had a secondary structure forming in the region downstream of the promoter, and RNA polymerase was stalling and falling off before completing the full transcript. I switched to a linearized template with a minimal AT-rich spacer between the promoter and the gene of interest, and the full-length yield went from maybe thirty percent of what it should have been to around eighty-five percent. Small change, huge difference.
There are three main stages to understand here. Initiation is when RNA polymerase recognizes and binds the promoter. In prokaryotes, this requires a sigma factor that directs the polymerase to the right starting point. Eukaryotes are more complicated. They need a set of general transcription factors like TFIID, TFIIB, and TFIIH to assemble at the promoter before RNA polymerase II can even attach. Then there's elongation, where the polymerase moves along the DNA adding ribonucleotides one by one. The average rate in bacteria is roughly forty to eighty nucleotides per second. In eukaryotes it's slower, somewhere around five to thirty nucleotides per second depending on the gene and the chromatin state. Termination is where things get interesting and where most people gloss over the details. In bacteria, there are two main mechanisms. Rho-dependent termination uses an ATP-dependent helicase called Rho that catches up to the polymerase and pulls the RNA strand off the DNA. Rho-independent termination relies on a GC-rich hairpin structure forming in the newly made RNA, which physically destabilizes the transcription complex. Eukaryotic termination is even more varied. RNA polymerase II doesn't just stop at a defined sequence. It keeps transcribing past the polyadenylation signal, and then an exonuclease called Xrn2 chases down the polymerase from behind, degrading the trailing RNA and eventually causing the polymerase to dissociate. This is called the torpedo model and it's been the accepted explanation for well over a decade now, but the exact mechanics still get debated in the literature. One thing beginners consistently miss is that transcription isn't just about making a copy. The RNA product can have multiple fates depending on what the cell needs. Messenger RNA gets processed, exported, and translated. Transfer RNA and ribosomal RNA are functional products themselves. But there are also long non-coding RNAs, microRNAs, and a growing list of other RNA types that don't code for protein at all. The central dogma you learned in high school is a simplification that worked for teaching but doesn't reflect the actual complexity of what's happening in a cell.
Another counter-intuitive point is that transcription and translation aren't always separate events. In prokaryotes, because there's no nuclear membrane, ribosomes can start translating an mRNA while it's still being transcribed. This coupling means that transcription speed and translation speed are physically linked. If translation stalls, it can cause the polymerase to stall too, which has implications for gene regulation that most introductory courses don't cover. Post-transcriptional modification is another area where the textbook version falls short. Eukaryotic pre-mRNA gets a 5' cap added almost immediately after transcription begins, sometimes within the first twenty to thirty nucleotides. A poly-A tail is added downstream after cleavage at the polyadenylation site. Then there's splicing, where introns are removed and exons are joined together. Alternative splicing means a single gene can produce multiple different mRNA variants, which dramatically increases proteomic diversity without needing more genes. The human genome has roughly twenty thousand protein-coding genes but produces well over a hundred thousand distinct proteins, and alternative splicing accounts for a large chunk of that gap. There are real limitations to keep in mind though. Transcription is error-prone. RNA polymerase has a certain basal error rate, somewhere in the range of one mistake per ten thousand to one hundred thousand nucleotides incorporated. That's higher than DNA replication, which has proofreading and mismatch repair mechanisms. Cells deal with this because mRNA is transient and gets degraded relatively quickly, but for long transcripts or in contexts where RNA stability matters, the error rate can become a problem. There's no equivalent to the DNA damage response for RNA, so errors in RNA just get propagated until the molecule is turned over.
Get the Full Details

Drug targeting of transcription is another area with caveats. Some antibiotics like rifampicin specifically inhibit bacterial RNA polymerase and are useful for treating infections. But because eukaryotic and prokaryotic polymerases differ, these drugs don't affect human cells directly. The downside is that resistance mutations can emerge quickly, especially in regions of the polymerase gene that overlap with the drug binding site. I've seen lab cultures develop rifampicin resistance in as few as two days under selective pressure, which is fast enough to be a genuine clinical concern in patients on long-term treatment. When you're working with transcription data from experiments like RNA sequencing, there are technical artifacts you need to account for. Library preparation can introduce bias depending on how you fragment the RNA, which primers you use, and how you handle ribosomal RNA depletion. GC-rich regions tend to be underrepresented in sequencing data because they form secondary structures that interfere with reverse transcription. If you're quantifying gene expression, you need to be aware that the numbers you're looking at are relative estimates affected by multiple preprocessing steps, not absolute measurements of how much RNA is actually in the cell. The basic process remains the same regardless of what organism you're studying, but the regulatory layers increase dramatically as you move from bacteria to yeast to mammals. A bacterial operon can be turned on or off with a repressor protein binding near the promoter. A mammalian gene might have enhancers thousands of base pairs away, promoter-proximal elements, insulator regions, and chromatin modifications that all influence whether and how much transcription occurs. The fundamental biochemistry hasn't changed. What's changed is the amount of regulation layered on top of it.
If you want to dig deeper into any specific part of this, the molecular biology textbooks from Alberts or Lodish have the most detailed treatments, though they're dense. For recent reviews on transcription mechanisms, Nature Reviews Molecular Cell Biology and similar journals publish updated summaries every few years that cover developments beyond what's in standard textbooks. The field has moved fast on things like single-molecule imaging of transcription, chromatin dynamics during elongation, and phase separation in transcriptional condensates, so older sources will miss a lot of what's currently understood.