Understanding How Data Points Scatter
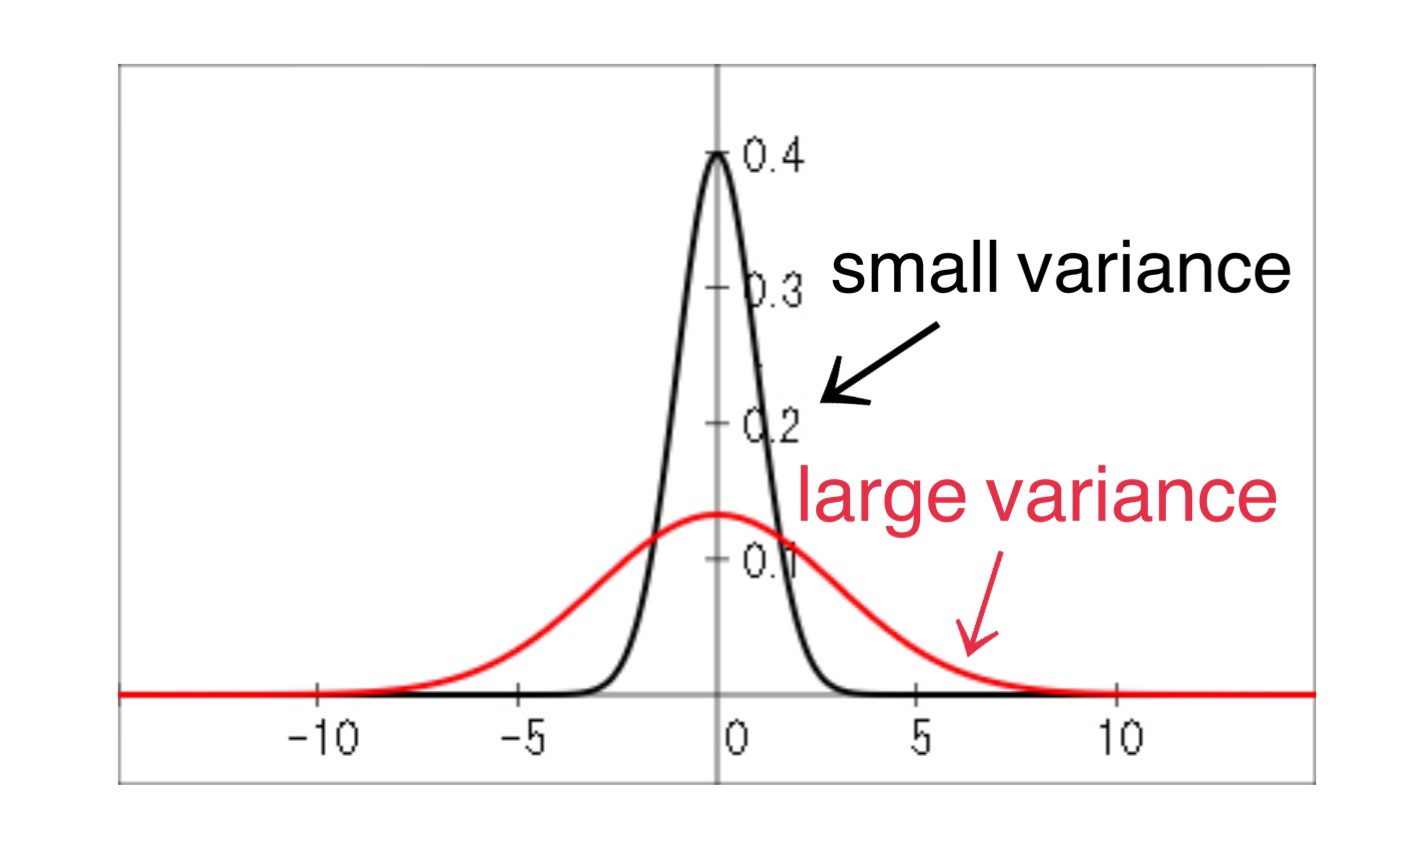
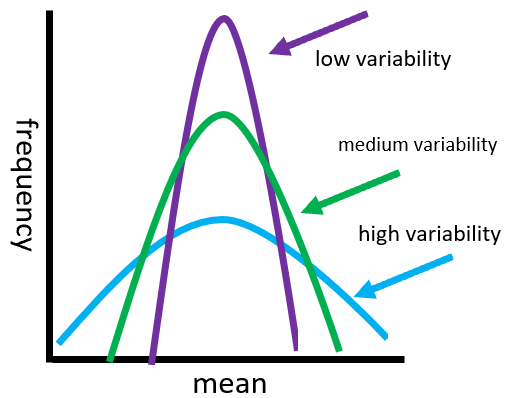
When you're dealing with real numbers, looking at the average is rarely enough. The mean tells you where the center of your data sits, but it says absolutely nothing about how the individual values behave around that center. If you're tracking weekly production output and your average is 1,000 units, you might assume stability. But if some weeks you produce 980 units and others 1,020, that's one story. If some weeks you produce 500 and others 1,500, that's a completely different operational problem that the average hides entirely. Variability is simply the measure of that scatter. It describes how much the data points diverge from each other and from the central value. Low variability means the numbers are tightly clustered. High variability means they are spread out over a wide range. This distinction matters because it affects how much you can trust a single measurement or an average as a predictor of future performance.What Is Variability In Math
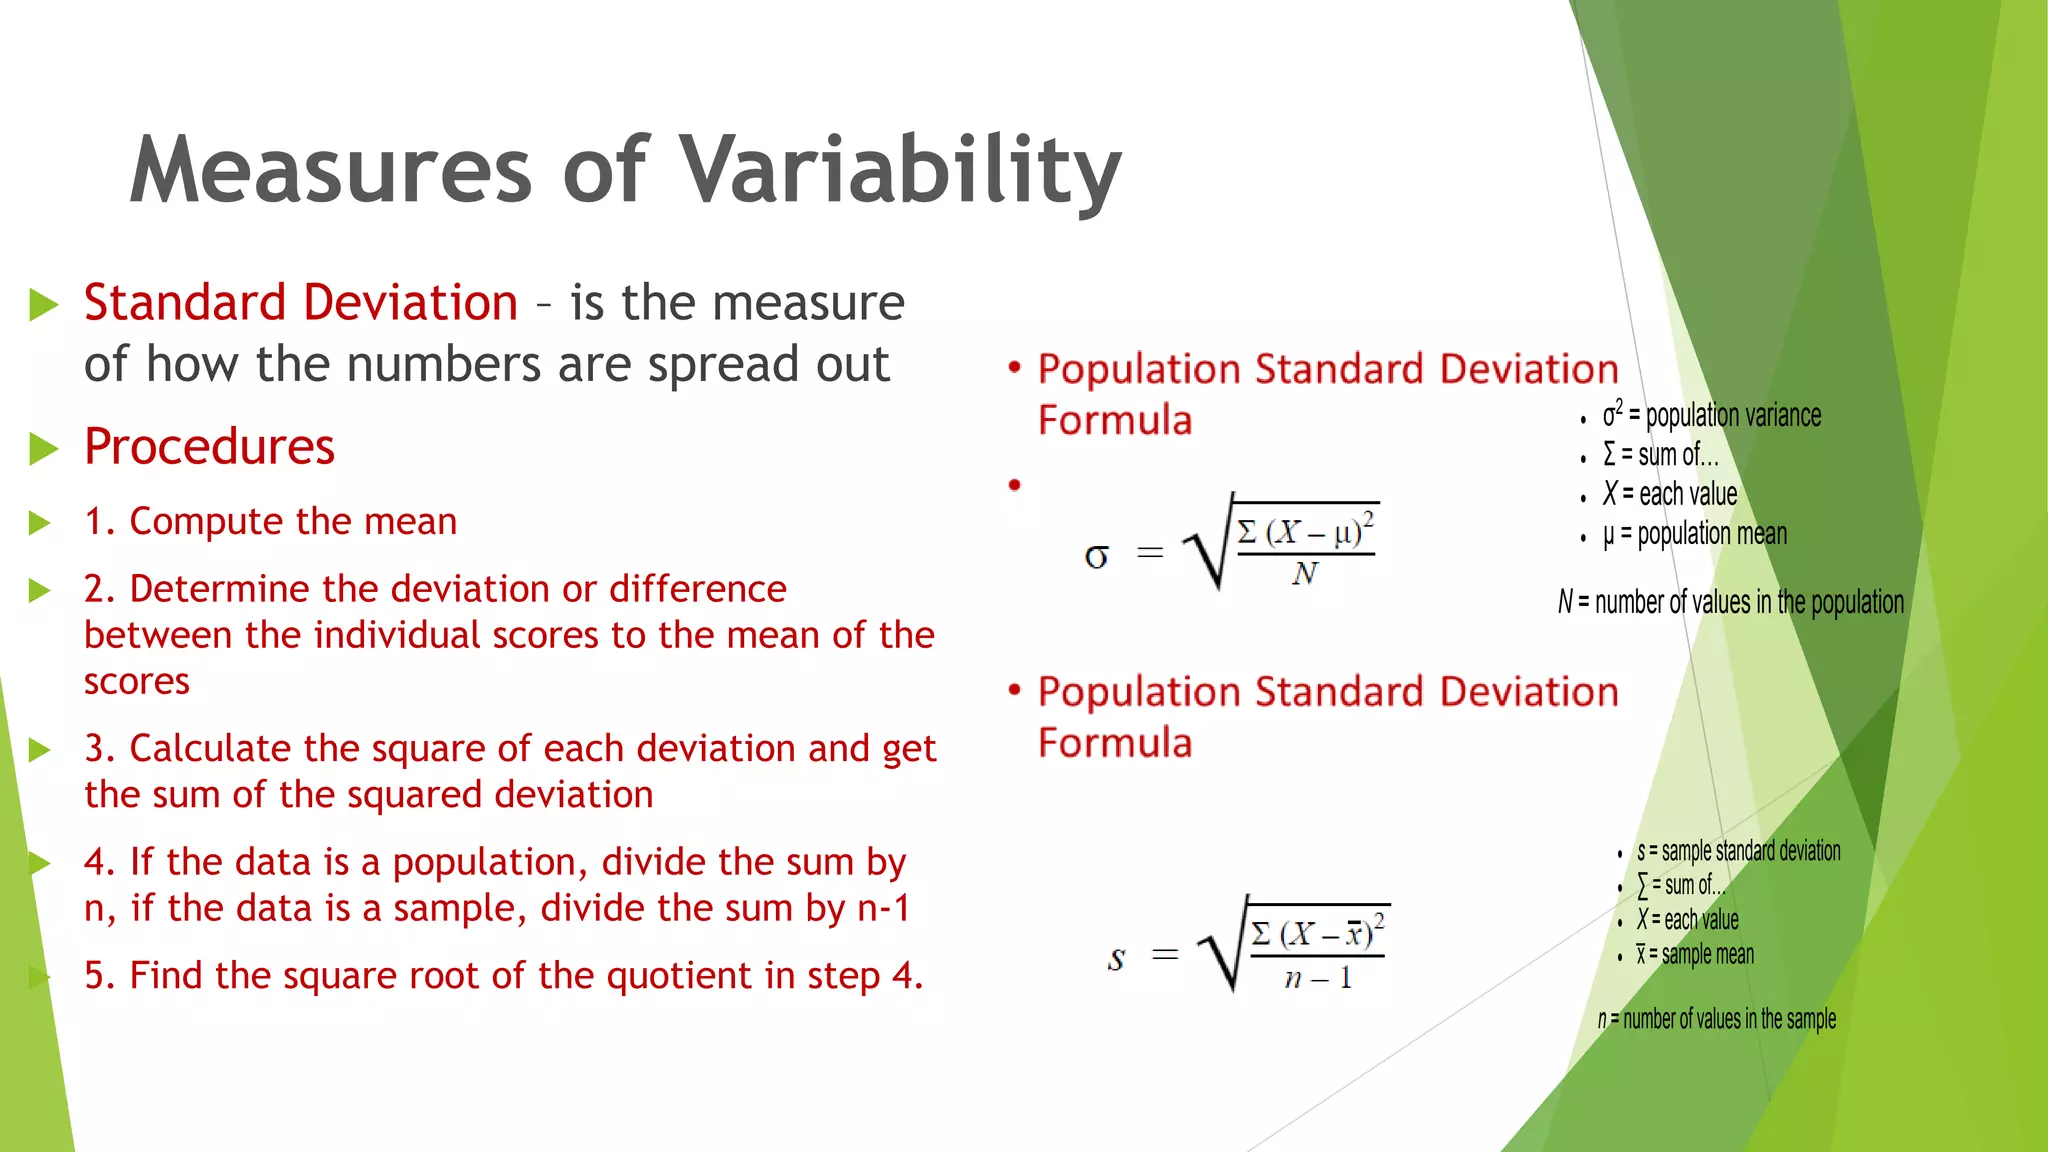
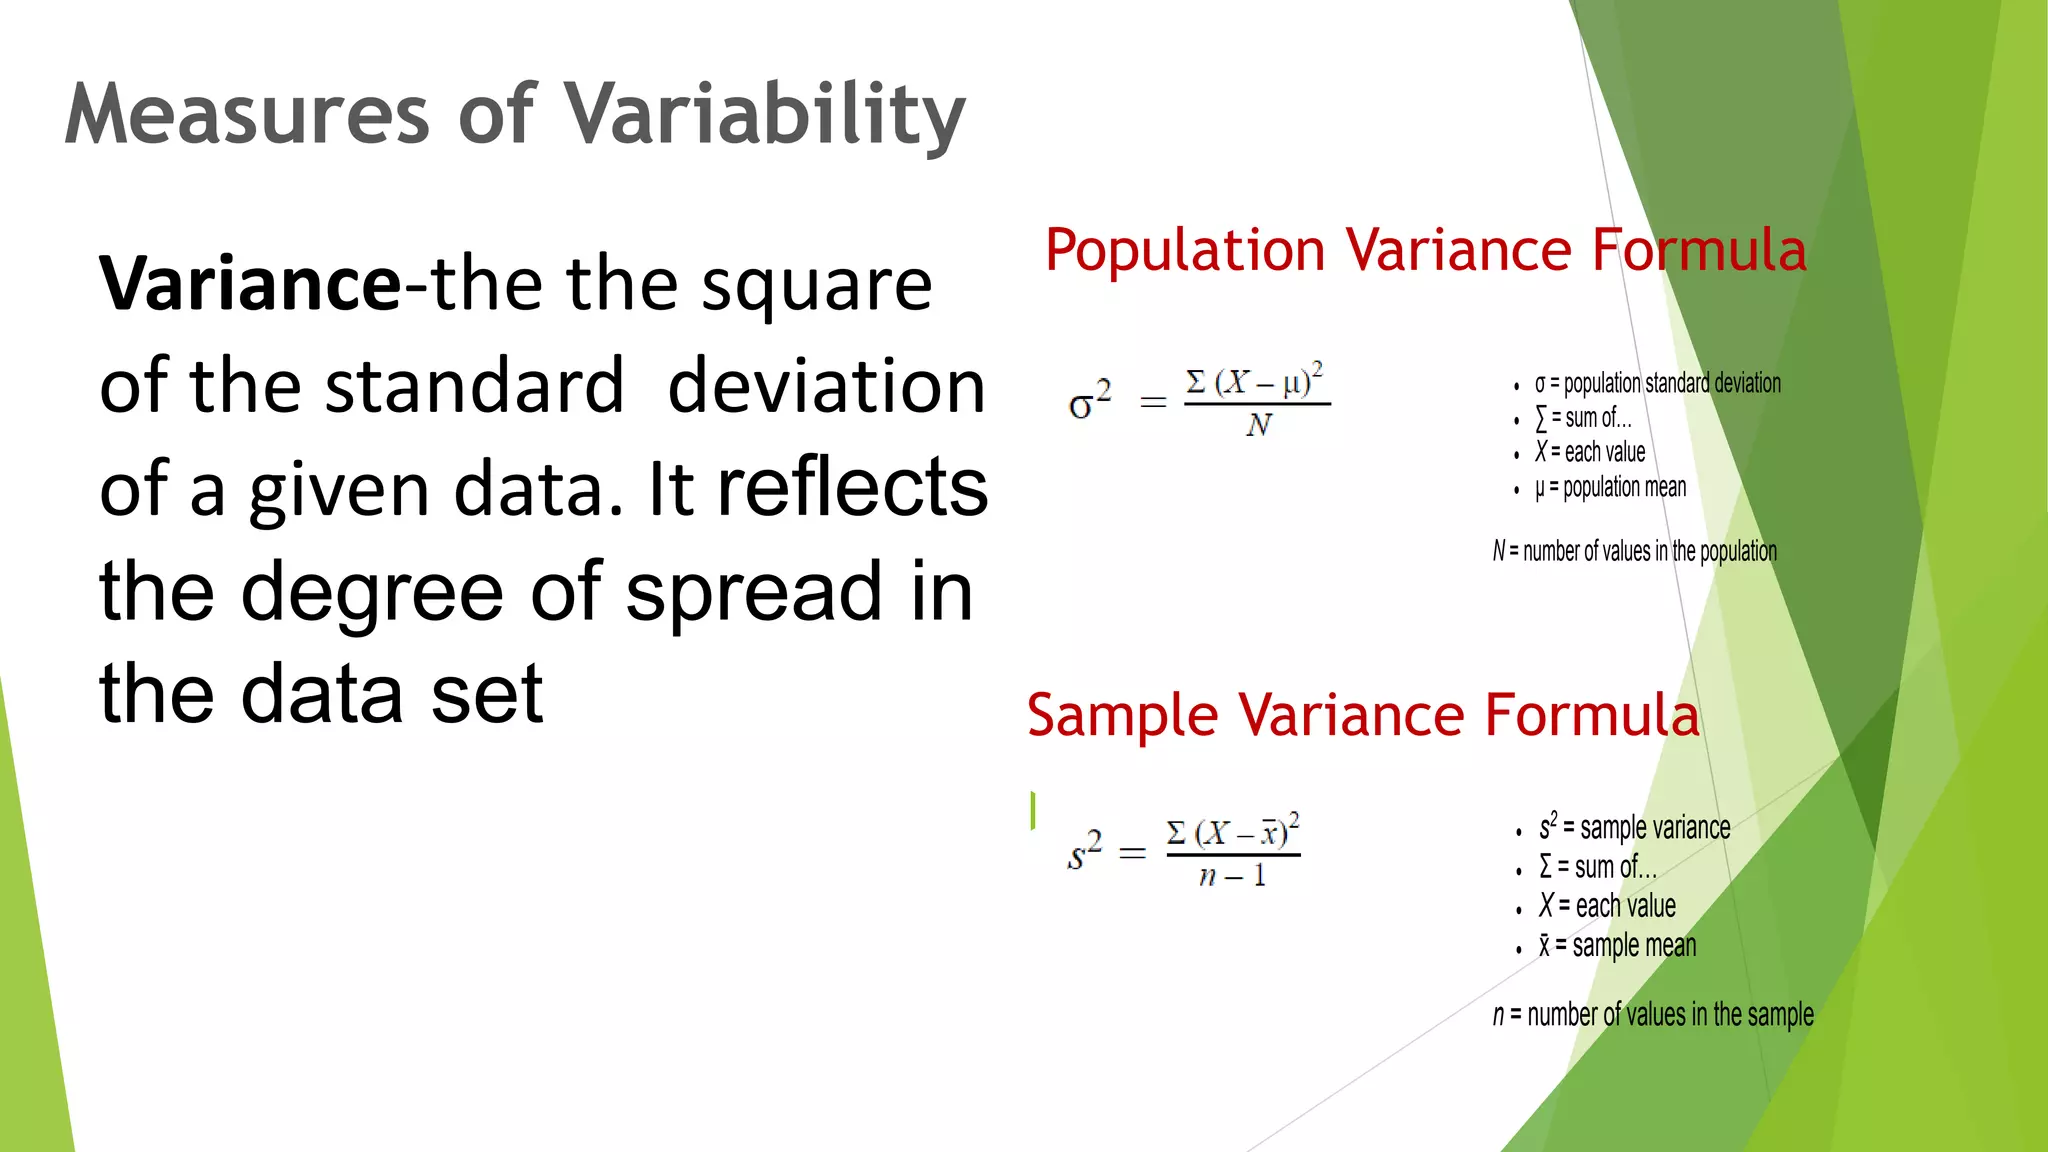
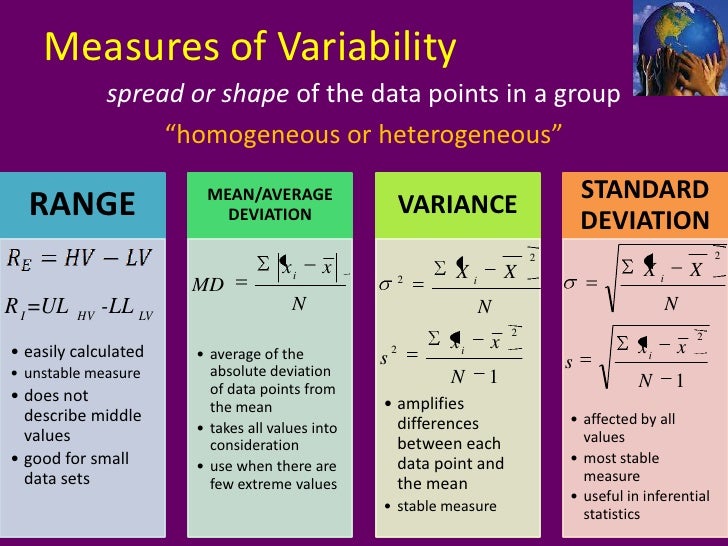
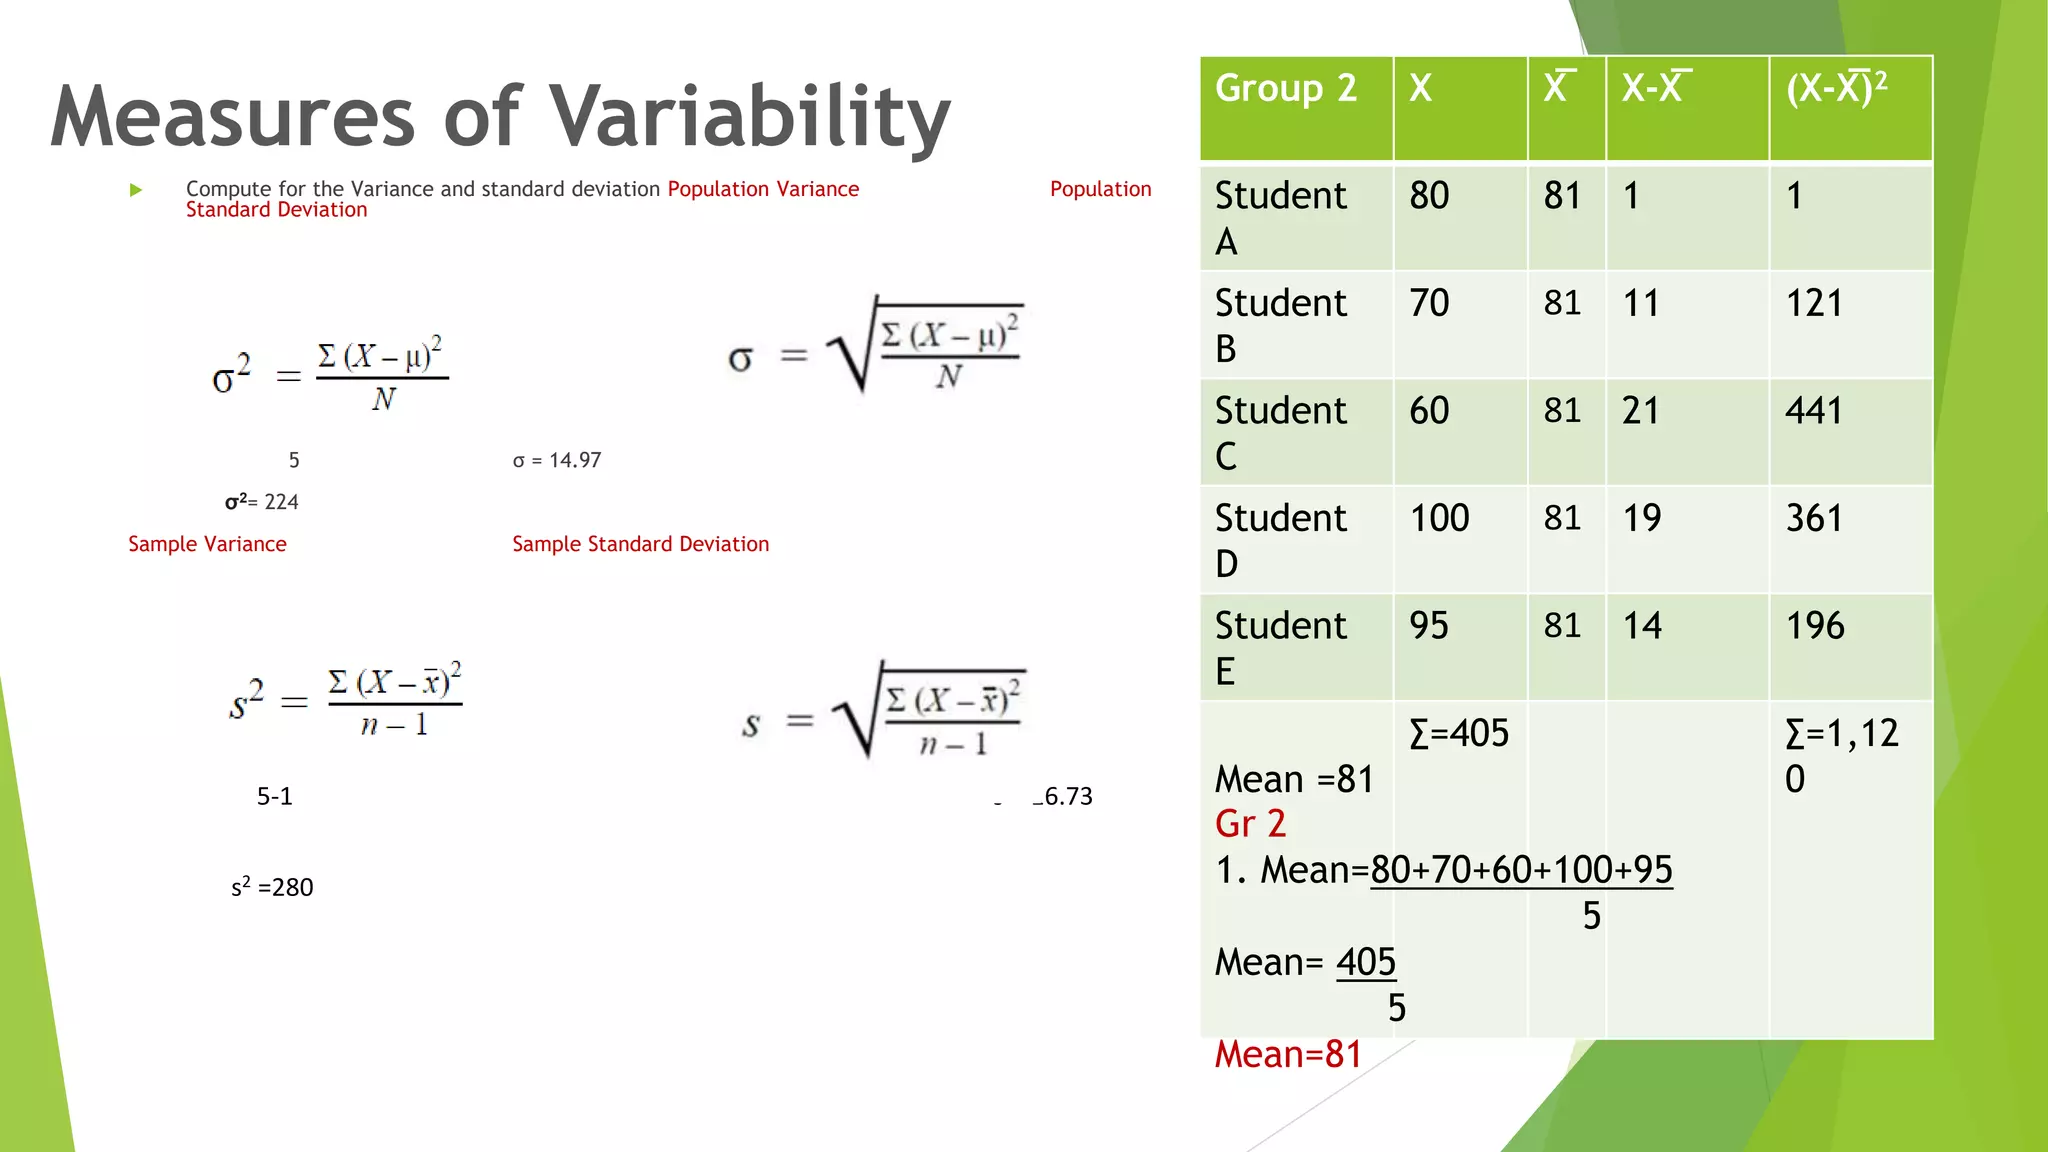
The core mathematical goal here is to quantify dispersion using specific metrics. I usually start by calculating the range, which is the difference between the maximum and minimum values. It's the simplest thing you can do, but it's also fragile because a single outlier distorts it completely. For a more stable picture, I move to the interquartile range, which looks at the middle fifty percent of the data. This ignores the extreme tails and gives me a clearer sense of the typical spread. To get the actual variance, you take each data point, subtract the mean, square the result, and then average those squared differences. Squaring is necessary because if you just averaged the raw differences, the positive and negative deviations would cancel each other out and you'd end up with zero. The resulting number is in squared units, which is awkward to interpret, so you take the square root to get the standard deviation. This brings the scale back to the original units of your data. The relationship between these measures is strictly hierarchical. Range gives a broad boundary. Interquartile range gives a robust core. Variance and standard deviation give a precise, arithmetic description of the total spread, assuming the distribution is roughly normal. If the data is heavily skewed, the standard deviation becomes less useful because it gets pulled toward the long tail.I remember working on a project involving latency logs from a legacy server system. The standard deviation of response times was massive, suggesting severe instability. However, when I plotted the data, I saw a long right tail caused by a specific scheduled batch job running every night at midnight. The standard deviation was being inflated by a handful of extreme outliers rather than reflecting the general variability. I solved this by calculating the median absolute deviation, which ignored those outliers and gave me a realistic picture of the typical fluctuation. The workaround was to use robust statistics whenever I suspected heavy-tailed distributions rather than relying on the default variance calculation.
< strong >Practical Limits of Standard Deviation< /strong > The most important thing to understand is that variance and standard deviation describe only the second moment of a distribution. They treat all deviations from the mean equally, which is why they are so sensitive to extreme values. If you have a dataset with a few catastrophic failures mixed with mostly normal operations, the standard deviation will be high even if ninety-nine percent of your operations are perfectly stable. In those cases, using a box plot to visualize the quartiles is much more informative than just citing a single standard deviation number. You also need to watch out for autocorrelation in time-series data. If your measurements are sequential and each one depends on the previous value, the variability you calculate might reflect a trend rather than random noise. A sequence that slowly drifts upward will show high variance even though there is no actual instability at any given moment. Always check for trends before you trust the spread metric.Another subtle issue is that identical means and variances can hide completely different data structures. I once compared two manufacturing processes that had the same average output and the same standard deviation. Process A produced consistent results within a tight band. Process B switched randomly between two distinct modes, creating a bimodal distribution. The standard deviation could not distinguish between the smooth consistency of Process A and the two-state switching of Process B. You have to look at the raw data or use higher-order moments like skewness to catch that kind of pattern. Variability is not just about a single number; it is about the entire shape of the distribution.