Mean, median, and mode explained without the fluff
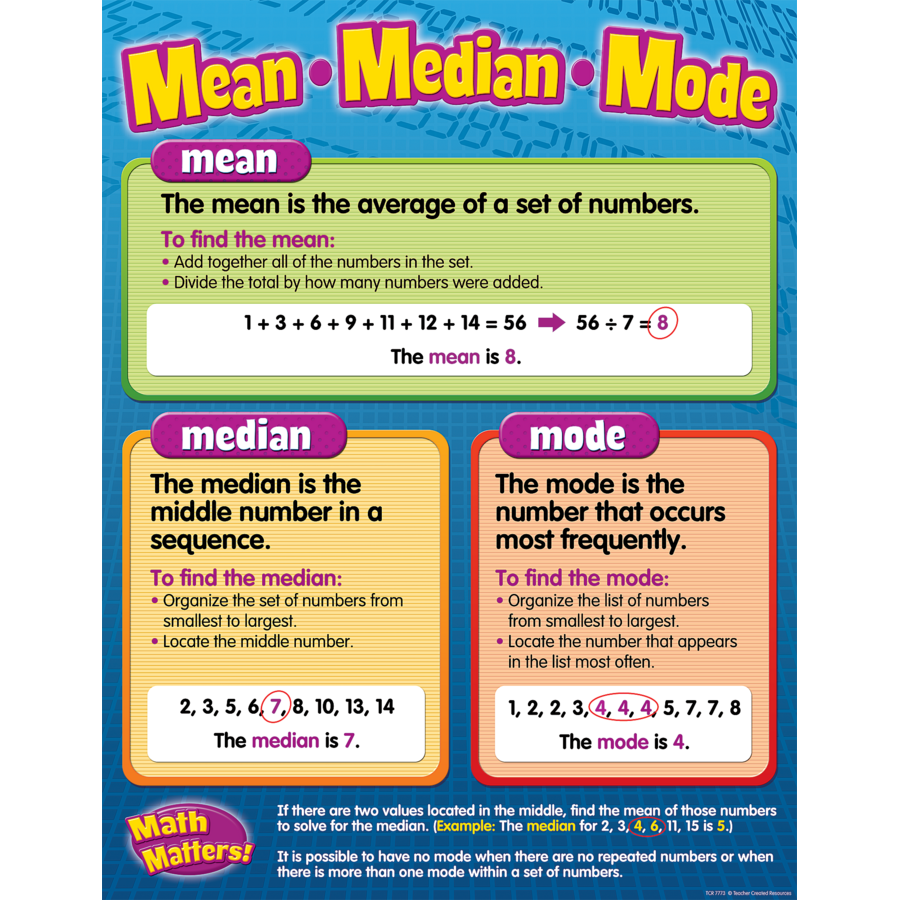
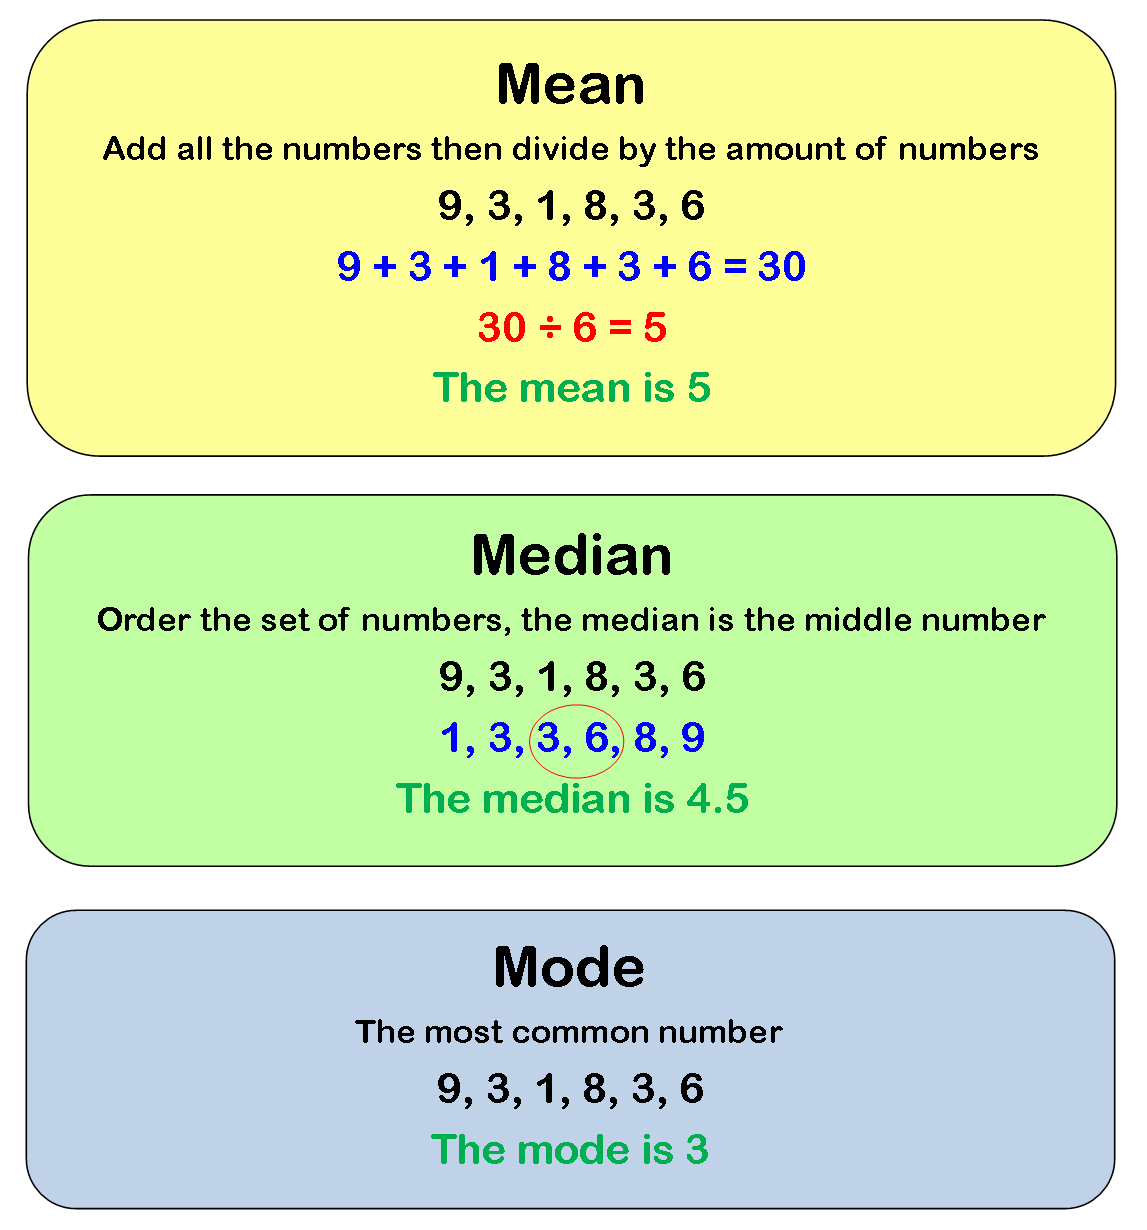
These three terms keep coming up in basic statistics, data analysis, and any spreadsheet work you do with real numbers. I see people mix them up constantly, which is fine, because the difference between them actually matters in practice. The mean is the arithmetic average, the median is the middle value when your data is sorted, and the mode is simply the value that appears most often. That's the definition. What I need to tell you is why it matters and when each one fails. I used to calculate these by hand in college, which is how you learn to appreciate Excel. Now I rarely touch raw data without first checking what the distribution looks like, and most people skip that step entirely. They take the mean and call it done. This gets you in trouble when your data isn't normally distributed, which is almost always.
How to find What Mean Median Mode for a dataset
Let me show you a real example from a project where I was analyzing support ticket resolution times. We had 1,200 tickets logged over a quarter. The raw numbers were all over the place. Some tickets closed in 20 minutes, others sat open for three weeks because they got reassigned between teams. Here's what the three measures gave us: The mean resolution time came out to about 4.7 days. You calculate that by adding every single ticket's resolution time together and dividing by 1,200. The median was 1.2 days. That means half the tickets were resolved faster than that, half slower. The mode was 0 days, which sounds ridiculous but actually makes sense because we had a large cluster of tickets that were auto-closed by the system after 24 hours without anyone touching them. So which number is right? They're all right. They're measuring different things. The mean gets dragged upward by the few extremely long resolution times. The median ignores the extremes entirely. The mode is useful here because it shows you how many tickets are getting auto-closed, which is an operational insight you'd miss if you only looked at averages.
Where these measures break down in the real world
The biggest mistake I see people make is assuming the mean is the default and everything else is optional. That assumption is wrong in most practical situations. The mean is the most mathematically convenient, but it's also the most fragile. A single outlier can shift it dramatically. I once saw a dataset where removing one entry changed the mean by over 30%, and nobody noticed because they didn't run diagnostics first. The median is more robust, but it has its own blind spots. If your data is bimodal or multimodal, the median sits between peaks and tells you almost nothing useful about either group. I worked on a pricing analysis once where the median price made it look like we had a single consistent price point, when in reality we had two completely different customer segments paying two completely different prices. The mode would have been clearer here, but it only becomes useful if one value actually dominates, which is rare in continuous data. The mode is often dismissed as simplistic, and honestly, it can be. But in categorical data, it's frequently the most informative measure of central tendency. If you're looking at product colors sold, or ZIP codes of customers, or support ticket categories, the mode is usually what you actually want to know. The mean of a ZIP code is meaningless. The median of a product color category is also meaningless. The mode is your only option there.
Get the Full Details
When to use each measure and when to ignore it entirely
Here's the practical framework I use now, after making all the obvious mistakes early in my career. If your data is roughly symmetric and doesn't have extreme outliers, the mean is fine and gives you the most mathematical flexibility for further calculations. If your data is skewed or has clear outliers, switch to the median. If you're dealing with categorical or discrete data, start with the mode and move up from there. There are edge cases where all three fail you. Highly irregular distributions with no clear center, datasets smaller than about 30 observations, and heavily censored data where you don't actually know the true values for a significant portion of your records. I dealt with censored data recently when tracking software license expiration dates, but some licenses had unknown renewal status. Neither the mean nor the median could reliably represent that dataset without making assumptions, so I just reported the distribution separately and left it at that. The takeaway is straightforward. Calculate all three when possible. Report the one that matches your data's structure. Don't default to the mean out of habit. Check for outliers first. And when the data is categorical, stop trying to force a mean into it.