Communication Breakdowns Happen Before You Even Start Talking
I spent three years debugging what I thought was a protocol issue between two microservices. The logs looked clean, the latency was fine, the error rate was zero. But data was consistently arriving at the wrong destination under certain conditions. It wasn't a routing problem. It wasn't a serialization issue. It was the naming convention on the message fields. One service called a property "user_id" and the other expected "userId" — they were using JSON, which doesn't enforce field names the way a strongly typed language does. The messages were technically valid. They were also completely useless to the receiving system. That experience shaped how I think about What What Is Communication, because most people treat communication as the act of sending information rather than the act of ensuring it lands correctly. The sending is the easy part. The hard part is every variable between point A and point B — context, assumptions, formatting, timing, and the recipient's ability to interpret the signal accurately.
What What Is Communication
At its most practical level, communication is the process of transferring meaning from one entity to another. That sounds simple, and it is, until you actually try to do it at scale or across different systems. The definition breaks down when you consider that "meaning" isn't inherent in the message itself. It exists in the head of the receiver. If the receiver reconstructs something different from what the sender intended, communication has technically occurred, but functionally it has failed. That distinction matters more than you'd think. In technical systems, this translates directly to protocols, schemas, and agreed-upon conventions. When two services communicate, they need to agree on format, encoding, field names, error handling, and message structure before a single byte is exchanged. In human contexts, the agreements are usually implicit and assumed rather than documented, which is where most breakdowns originate.
The Models Most People Get Wrong
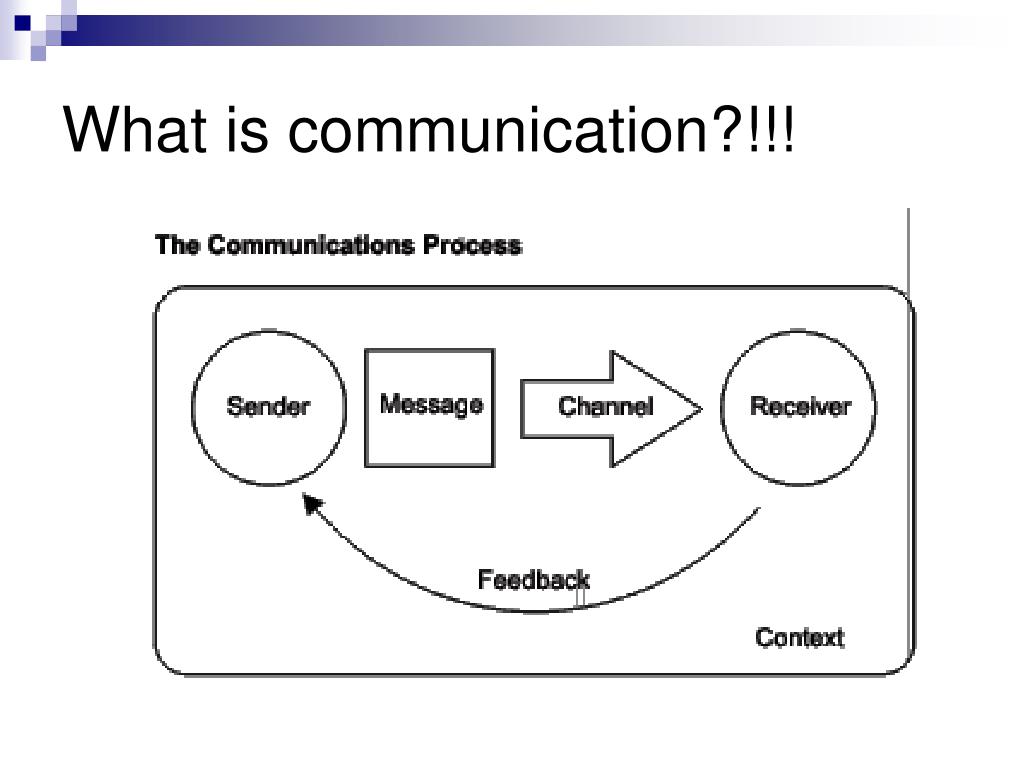
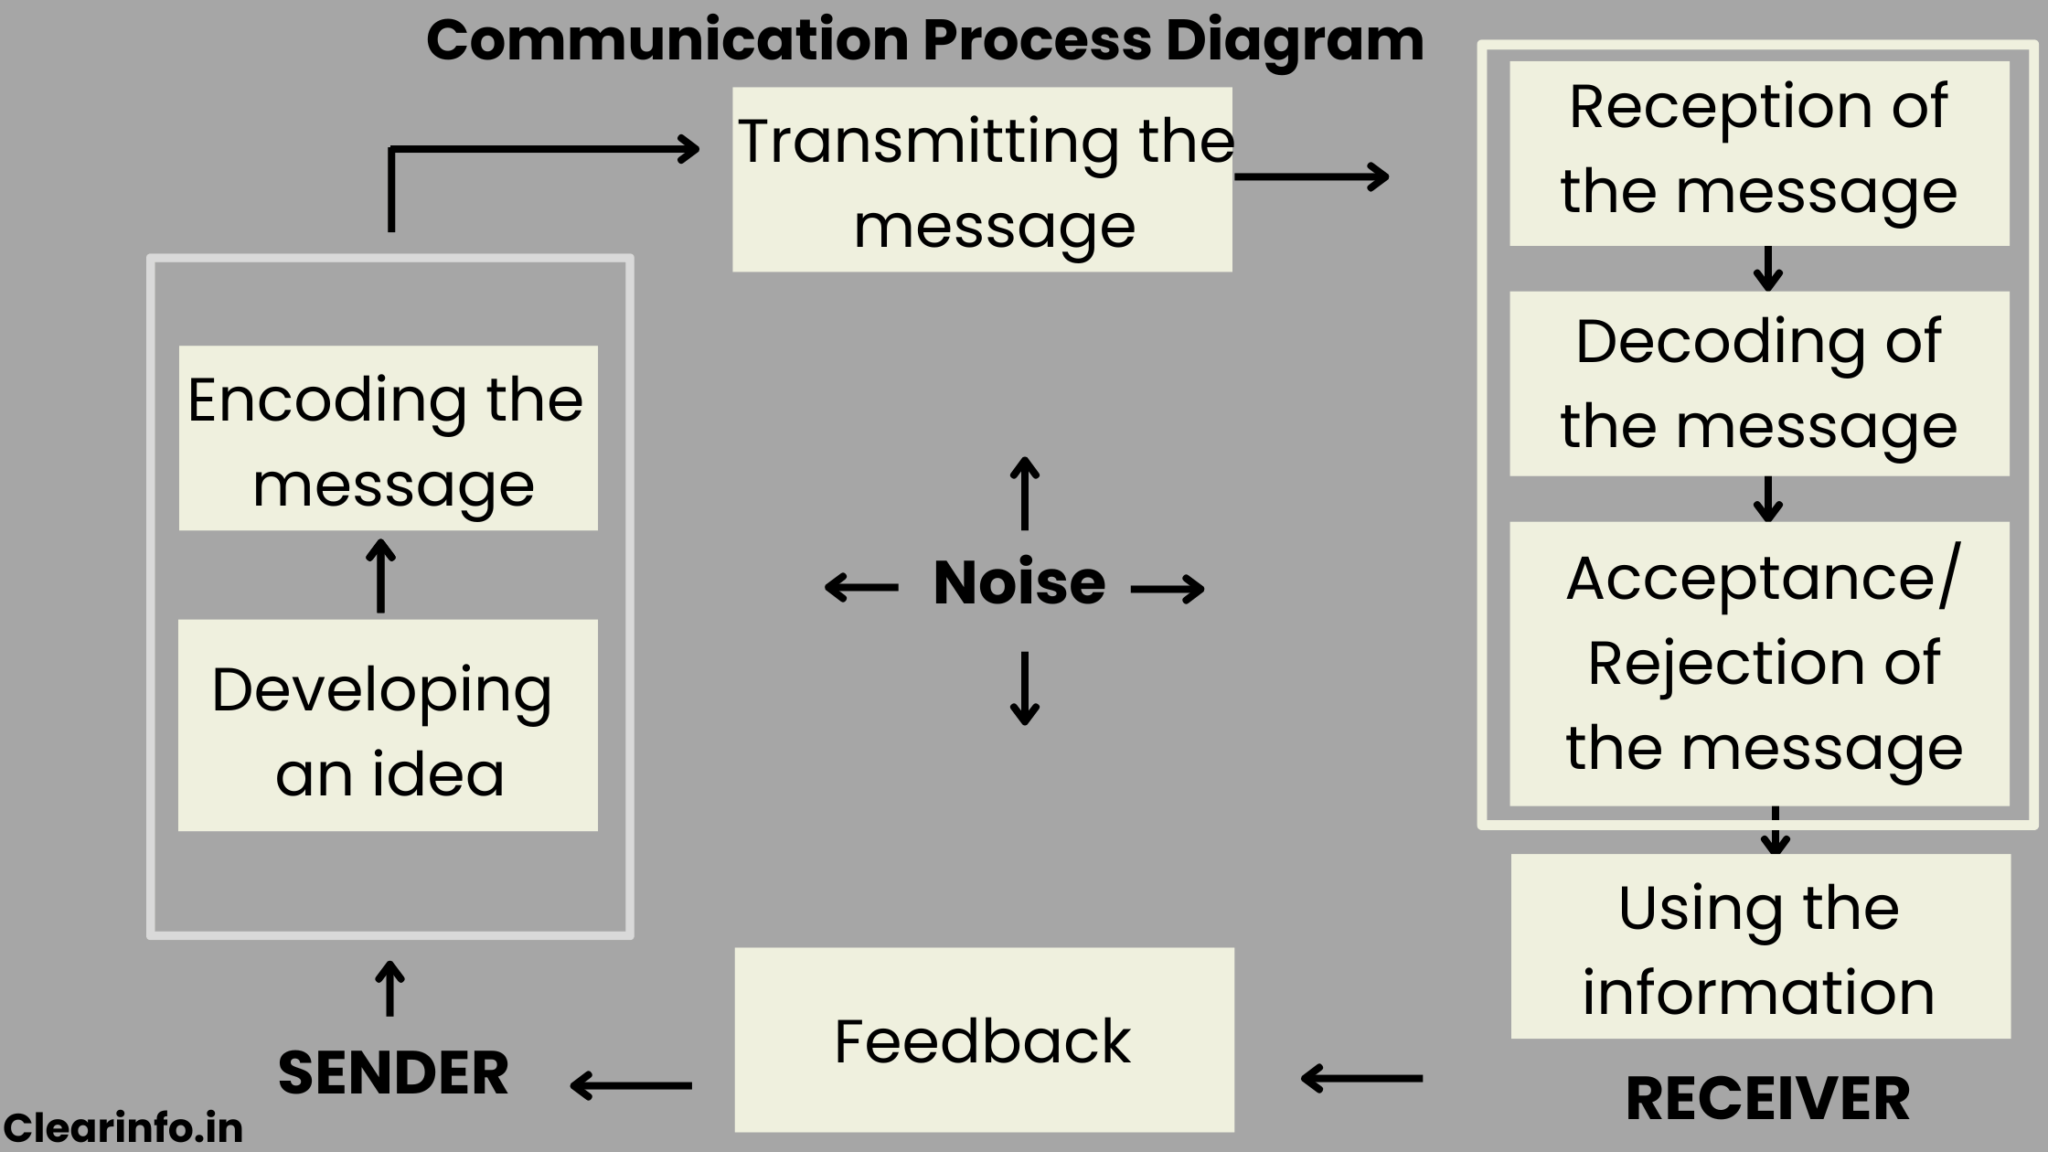
The Shannon-Weaver model gets taught in every introductory course. Sender, encoder, channel, decoder, receiver. Noise gets added somewhere. It's useful as a starting point, but it treats communication as linear and transmission-focused. That's not how real systems work. Real communication is iterative, contextual, and often asynchronous. A message sent today might be interpreted based on a message that was received three weeks ago, or a configuration change that happened yesterday, or an undocumented assumption that nobody bothered to write down. The transactional model is closer to reality but still abstract. It accounts for feedback loops and simultaneous sending and receiving, which is more accurate for human conversation. For system-to-system communication, neither model fully captures the problem. You need something that accounts for schema evolution, backward compatibility, partial failures, and the fact that silence itself is a message. When a service stops responding, that's not an absence of communication. It's a signal, and most systems don't handle that signal correctly.
Get the Full Details
Practical Framework for Structured Communication
If you're building systems that need to communicate reliably, start with the contract before you write any code. A contract defines the shape of the data, the allowed values, the error responses, and the versioning strategy. Without one, you're flying blind. I use something close to OpenAPI for HTTP services and Protocol Buffers for internal gRPC communication. Both enforce schema validation at compile time, which catches mismatches before deployment instead of after. Protobuf also handles backward compatibility through field numbering — you can add fields to a message without breaking existing consumers as long as you don't reassign field numbers. That rule alone prevents about sixty percent of the integration issues I encounter. For async communication via message queues, the pattern changes. You need idempotency guarantees, message schemas, and explicit handling for dead-letter queues. I once had a system where a payment processing service would silently drop messages that didn't match the expected schema. No error, no log entry, just disappearance. Those messages accumulated in a dead-letter queue that nobody monitored. We lost approximately four percent of all transactions for three weeks before anyone noticed. The fix was straightforward — add schema validation at the ingestion point with immediate alerting on rejections, and route invalid messages to a separate queue with logging. But the cost of that gap was significant. Versioning is where most teams struggle. The naive approach is to deploy v2 alongside v1 and gradually migrate consumers. That works until v1 and v2 both need to talk to the same downstream service, and the downstream service can't tell which version is which. The clean approach is content-based routing or explicit version headers on every request. Neither is perfect. Version headers add coupling. Content-based routing adds complexity. Pick the problem you can live with.
Edge Cases That Documents Never Cover
Here's a specific scenario I ran into last year that still makes me uncomfortable. We had two services communicating over a message bus. Service A published events about user account updates. Service B subscribed and maintained a search index. Everything worked fine until we deployed a schema change to Service A that added a new optional field. The field was nullable, so old messages from Service B's consumers that didn't include it were still valid. Or so we thought. The message bus we were using — a Kafka cluster — had a schema registry that enforced compatibility rules. The change we made was marked as backward compatible by the registry, but Service B's deserialization library didn't handle the new optional field gracefully. It threw a runtime exception on deserialization, not a compile-time error, not a schema validation error. A runtime exception in a message handler means the entire partition could stall if the message couldn't be deserialized. The workaround was to add a defensive deserialization layer between the message bus and the business logic. This layer caught deserialization errors, logged them with full message context, and routed the problematic messages to a dead-letter queue instead of letting them poison the consumer. It added about two hundred lines of code and increased latency by roughly 3ms per message. Those two hundred lines prevented a complete service outage that would have taken hours to diagnose and fix. Another edge case that deserves mention: clock skew. When services communicate asynchronously and rely on timestamps for ordering or deduplication, even a few hundred milliseconds of clock difference between servers can cause messages to arrive out of order or get deduplicated incorrectly. NTP helps, but it doesn't eliminate the problem entirely. Lamport timestamps or logical clocks are the proper solution for ordering-dependent systems, but they add complexity that most teams aren't prepared to handle. If your system can tolerate some reorder, document that assumption explicitly. If it can't, don't pretend NTP is good enough.
Common Pitfalls That Wreck Integration Projects
The biggest mistake I see is treating communication as a one-time setup. It isn't. Data formats evolve. Business rules change. Teams merge and split. A schema that worked perfectly six months ago might be the source of your current production fires. Regular contract testing catches these drifts before they hit production. I use Pact for consumer-driven contract testing, and it has saved us from deploying breaking changes at least a dozen times. The setup takes about a day, and the maintenance overhead is minimal — mostly just updating test data when the business logic changes. If you're not doing contract testing, you're deploying on luck. A second mistake is ignoring error communication. Most teams define success paths and leave error handling to chance. They expect errors to be rare and self-explanatory. They're not. Errors are frequent. They're rarely self-explanatory. The difference between a five-minute incident response and a five-hour one is often whether the error message contains enough context to act on. Include correlation IDs, timestamps, the name of the failing component, and a machine-readable error code alongside the human-readable message. The human-readable message goes in the logs. The machine-readable code goes in the response payload so the caller can handle it programmatically. The third mistake is assuming that connectivity equals communication. Two services can be connected and exchanging data and still not be communicating effectively. This happens when the data being exchanged doesn't match the actual needs of the consuming service. We saw this when a monitoring service was pulling metrics from a dozen source services. The metrics were technically correct — the field names matched, the types matched, the values were in the right format. But the monitoring service needed hourly aggregates and the source services were only providing raw per-request data. The consuming service had to aggregate everything client-side, which meant it couldn't do real-time alerting. The source services weren't communicating badly. They were communicating efficiently — just not usefully. The fix was to add aggregation endpoints to each source service. It took two weeks of work across six teams, and it eliminated the need for client-side aggregation entirely.
When Communication Protocols Fail Completely
There are scenarios where no amount of schema definition, contract testing, or error handling will prevent breakdowns. Network partitions are the most common. When two services can't reach each other, there's no protocol that makes that disappear. You can implement retries, circuit breakers, and fallback strategies, but you're managing the symptom, not solving the problem. During a partition, some systems choose to fail closed — reject all requests and wait for recovery. Others fail open — process requests without validation and reconcile later. The right choice depends entirely on your business context. For a payment system, fail closed. For a recommendation engine, fail open. There's no universal answer, and pretending there is will get you in trouble. Distributed consensus is another area where communication hits hard limits. The CAP theorem isn't theoretical — it's a daily constraint. You pick consistency or availability when the network partitions, and there's no way around it. Paxos and Raft help with consistency, but they introduce latency. Eventual consistency with conflict resolution helps with availability, but it introduces complexity in handling conflicts. I once worked on a system where we chose eventual consistency for a user profile service, and the conflict resolution logic ended up being more code than the rest of the service combined. The trade-off was worth it for availability, but nobody warned us about the implementation cost. If you're dealing with high-stakes communication where data integrity is non-negotiable — financial transactions, healthcare records, safety-critical systems — consider using a more rigid protocol like MQTT with QoS level 2 or a custom protocol built on top of TCP with explicit acknowledgments. HTTP-based approaches with retries and idempotency keys can work, but they introduce ambiguity that rigid protocols eliminate. The downside is that rigid protocols are harder to implement, harder to debug, and harder to integrate with existing tooling. You're trading flexibility for certainty.
Building for Long-Term Communication Health
Documentation is the first thing teams skip and the first thing they regret. I don't mean API documentation generated from annotations. I mean a living document that describes the intent behind the communication contract — why certain fields exist, what assumptions the consumer should make, what the error semantics are, and how the contract is expected to evolve. Generated docs tell you what the API looks like. Intent documentation tells you what it means. Those are different things, and having both saves enormous amounts of time during onboarding and incident investigation. Monitoring communication health is just as important as monitoring service health. You need to track message latency, error rates per endpoint, schema validation failures, and dead-letter queue depth. These metrics tell you about the quality of communication between services, not just whether services are up. A service can be healthy and still communicating poorly. That's the metric most dashboards miss. Finally, plan for the deprecation of communication channels. Every interface you build will eventually need to be replaced or retired. Document the deprecation timeline, provide migration guides, and maintain backward compatibility for a reasonable period. Rushing deprecation creates chaos. Ignoring it creates technical debt. The sweet spot depends on your user base and the cost of migration, but two to three release cycles of coexistence is a reasonable minimum for most internal systems.
The fundamental truth about communication — technical or human — is that it requires explicit agreement on meaning. Without that agreement, you're just generating noise and hoping something useful comes out of it on the other end. The work of defining, enforcing, and maintaining that agreement is the actual job. Everything else is implementation detail.