What Your Ransomware Response Training Is Actually Telling You to Do
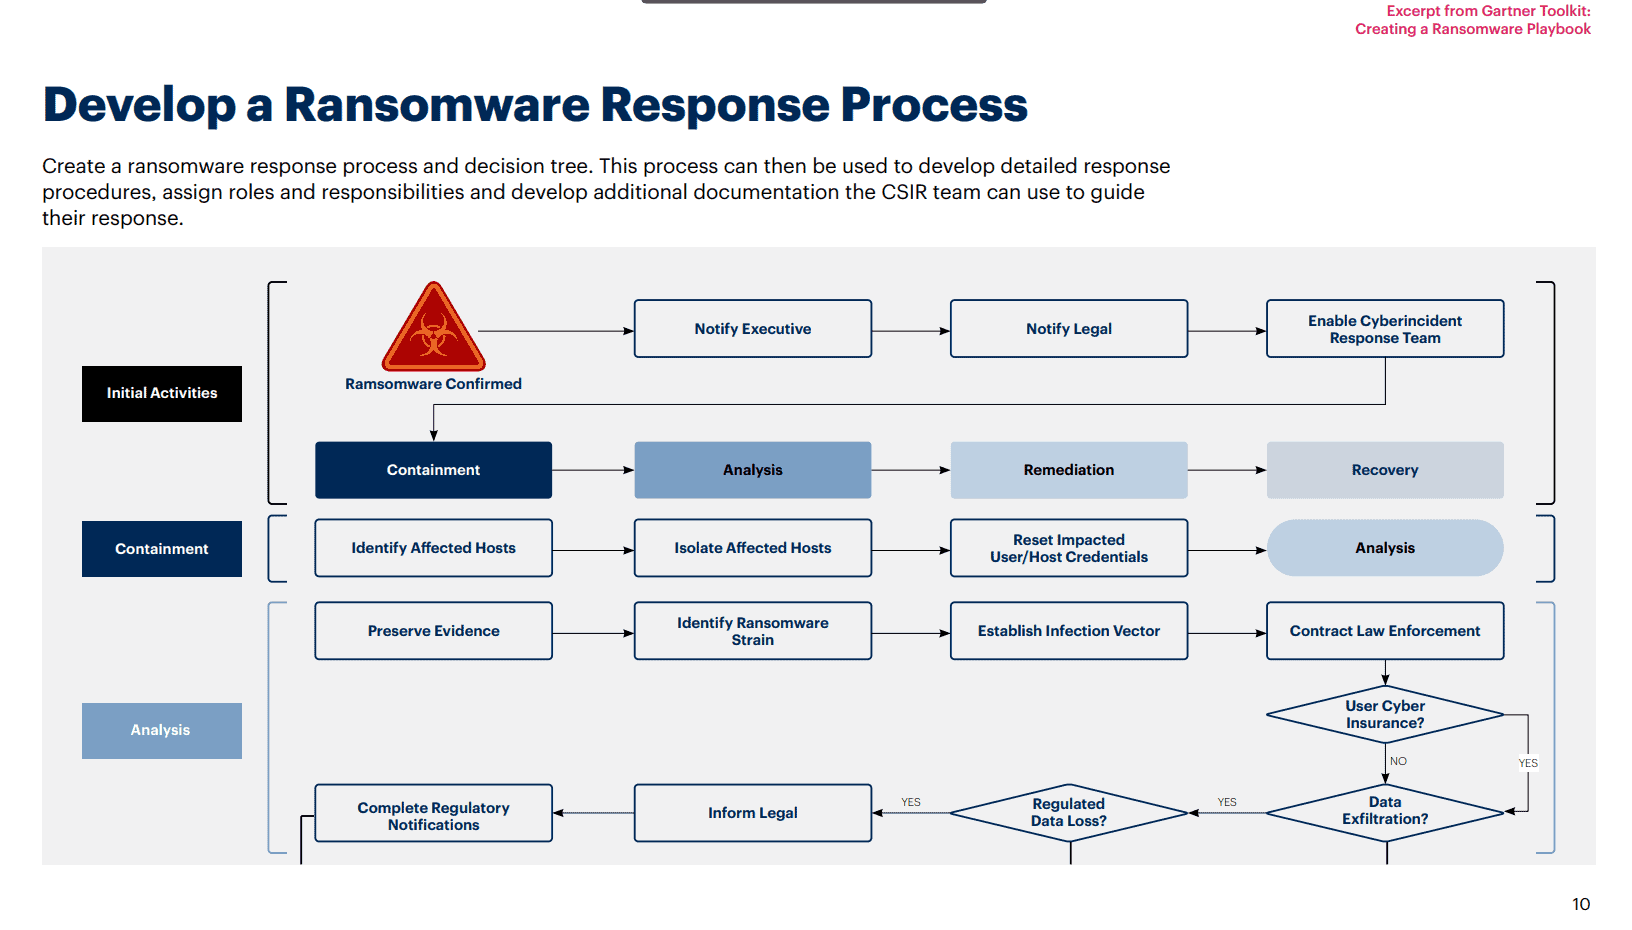
When you are sitting at your desk at 2 AM with a notification that something is encrypting your file servers, the playbook matters more than anything else. Most organizations have training materials on ransomware response, but the gap between reading that training and executing it under real pressure is where things fall apart. This isn't about fear-mongering. It is about understanding what your training actually recommends and where that advice breaks down in practice. Your incident response training will likely start with isolation. Disconnect the affected systems from the network immediately. This means pulling ethernet cables or disabling switch ports, not just turning off Wi-Fi. The reasoning is straightforward: ransomware propagates laterally using SMB, RDP, and various remote execution methods. Every second those machines stay connected gives the encryption process more territory. I have seen teams waste precious minutes trying to determine exactly which systems are infected before pulling the plug. They lose twenty or thirty minutes that way. Just isolate first and figure out the scope after. After isolation comes identification and scope assessment. You need to know what strain of ransomware is running, which systems are affected, whether data has been exfiltrated before encryption begins, and what the estimated recovery timeline looks like. Your training will emphasize documentation here. Write down timestamps, system names, user accounts involved, and any indicators of compromise you can see. This documentation matters for your post-incident review and any law enforcement engagement. It also matters for your insurance claim. Cyber insurance providers will ask for a detailed timeline and I have watched claims get delayed or reduced because the documentation was sloppy.
The third major recommendation in most training programs involves communication protocols. Your team needs a predefined communication tree. Who gets called first? What is the escalation path? Do you contact your incident response retainer immediately or do you bring in legal counsel first? Different organizations have different answers to these questions and they should all be documented before an incident occurs. I worked with a company once where the CISO and the IT director spent forty-five minutes arguing over whether they had authority to engage their IR firm without board approval. The ransomware was still encrypting files during that argument. Have the escalation paths mapped out and signed off before you need them.
What The Training Gets Wrong Or Leaves Out
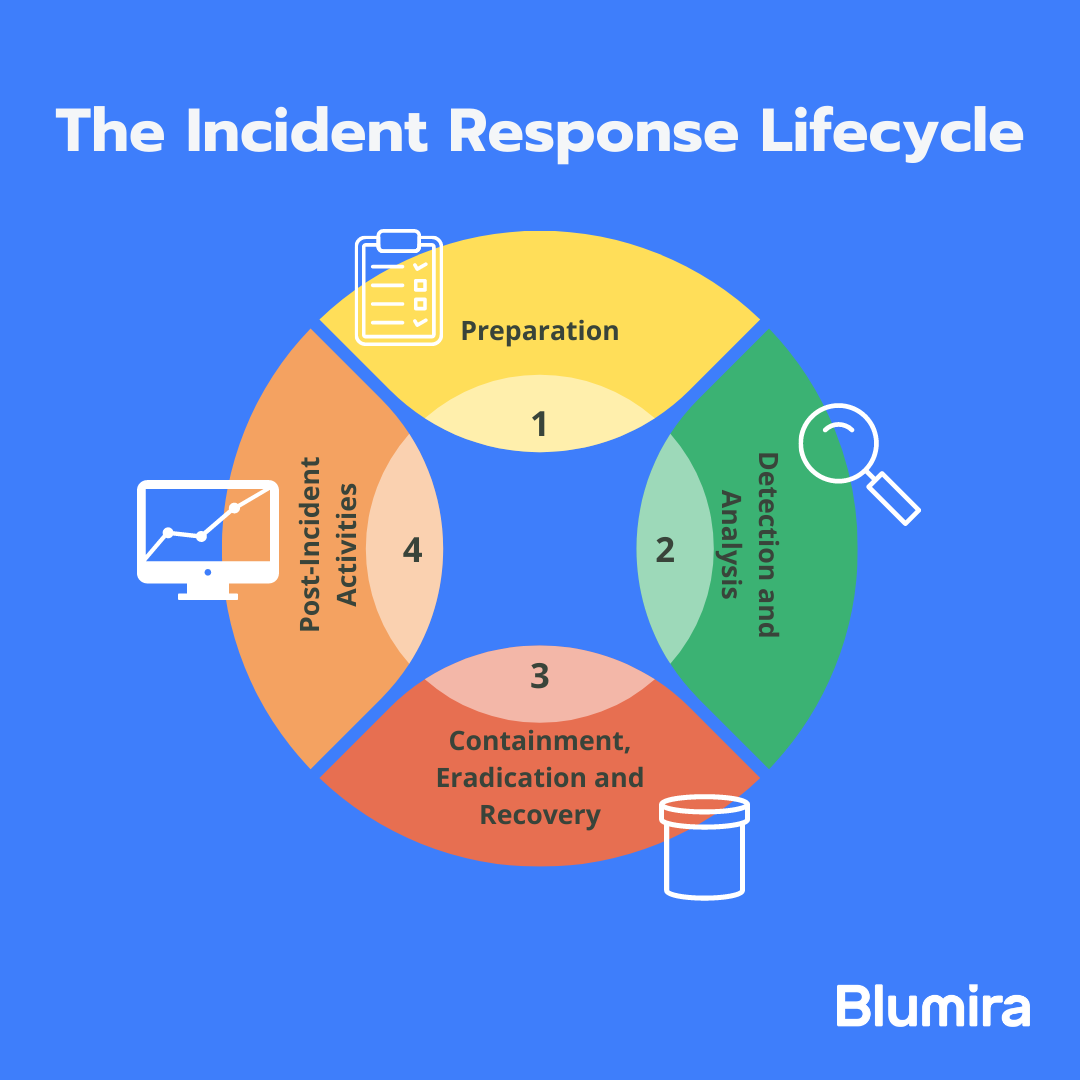
Most training materials treat ransomware response as a linear process. Isolate, assess, contain, eradicate, recover. Real incidents are messier than that. Here is what your training probably does not emphasize enough. Backup verification is critical and almost always handled poorly in practice. Your training will tell you to restore from backups. The part it leaves out is that you need to verify those backups actually work before you depend on them. I spent three days trying to restore a SQL Server database from what my team thought was a clean backup. The backup had been corrupted for two weeks. The backup job was completing successfully, the logs showed green checkmarks, but the actual data inside was unreadable. We found it because I insisted on a test restore of a random selection from each backup set before we committed to any recovery plan. Testing your backups takes time you do not think you have during an incident, but attempting a restore without testing costs you significantly more time if the backup is bad. Another thing training rarely covers is the psychological dimension of ransomware incidents. People make terrible decisions under stress. Your incident commander needs authority to make calls without committee input. I have seen teams paralyze themselves by trying to get consensus on whether to disconnect a production server. Production was already compromised. Consensus building during an active incident is a luxury you cannot afford. Designate a single incident commander in your training and make sure everyone knows that person has final authority during the response window.
Get the Full Details

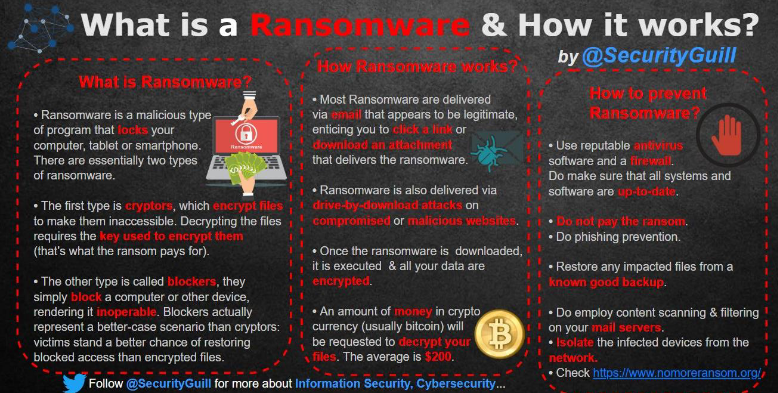
There is also the issue of encrypted versus unencrypted data. Your training may not address the scenario where attackers exfiltrate data before encrypting anything. This is increasingly common with double extortion ransomware variants. The encryption becomes secondary. The primary threat is data exposure. If your training only covers the encryption scenario and not the exfiltration scenario, you are underprepared for a significant portion of modern ransomware attacks. Check your backups, check your data loss prevention logs, and assume data may have left your network even if nothing is encrypted yet.
Practical Execution Details That Matter
Network segmentation is the single most effective preventive measure and most organizations fail to implement it properly. Your training should recommend dividing your network into separate zones with strict access controls between them. Production systems should not have unrestricted access to domain controllers. File servers should not be directly reachable from user workstations without going through a jump box or similar control point. I audited a company's network segmentation after a minor incident and found that every machine on the network could reach every other machine. Their segmentations were logical in documentation but nonexistent in actual firewall and switch configuration. Six months of work closing unnecessary routes reduced their blast radius from the entire network to roughly one percent of it. Endpoint detection and response coverage is another area where training advice and reality diverge. Your training will likely recommend having EDR deployed across all endpoints. The reality is that many ransomware variants now have techniques to detect and disable EDR agents before encryption begins. Agentless detection, hardware-based monitoring, and detection of EDR process signatures are all methods attackers use. Your training should push for defense in depth rather than reliance on a single tool. Network-level detection, behavioral analysis, application allowlisting where feasible, and regular penetration testing to validate your controls matter more than any individual product. The decision to pay ransom is covered in most training with a blanket recommendation against payment. This is generally sound advice. Payment does not guarantee recovery, funds criminal activity, and may violate sanctions depending on your jurisdiction. But there is an edge case that training rarely addresses. If you have a small business with no viable backups, no redundancy, and a ransom demand that is survivable, the training recommendation to never pay may not serve your organization's best interest. This is a business decision, not a technical one, but it should be part of your planning. Document your position on ransom payment before an incident occurs so you are not making that decision while panicked.
Post-Incident Recovery Priorities
Recovery is where most organizations lose momentum. The training will tell you to restore systems and return to operations. What it often omits is the importance of a structured recovery sequence. Restore systems in priority order based on business impact, not convenience. I have seen teams restore everything simultaneously because they thought parallel restoration would be faster. They ended up with resource contention, longer total recovery time, and multiple systems failing validation because no one was testing them properly. Restore critical systems first. Validate each restore before moving to the next tier. Document everything during recovery just as rigorously as you documented during the initial response phase. Root cause analysis should not be skipped after recovery. This is the step most organizations rush through or skip entirely. You need to understand how the ransomware entered your environment. Was it a phishing email? A vulnerable exposed service? A compromised credential? A supply chain vector? Without understanding the entry point, you are simply waiting for the next incident. I recommend allocating at least two weeks for a thorough root cause analysis after an incident. Rushing this process means you will likely miss subtleties that matter for preventing recurrence. Finally, update your incident response plan based on what you learned. Most training documents become obsolete the moment you use them. The gap between your documented procedures and what you actually had to do during the incident is your improvement backlog. Fill it. Document what worked, what did not work, and what you wish you had known before the incident started. This turns a painful experience into a genuine strengthening of your security posture.