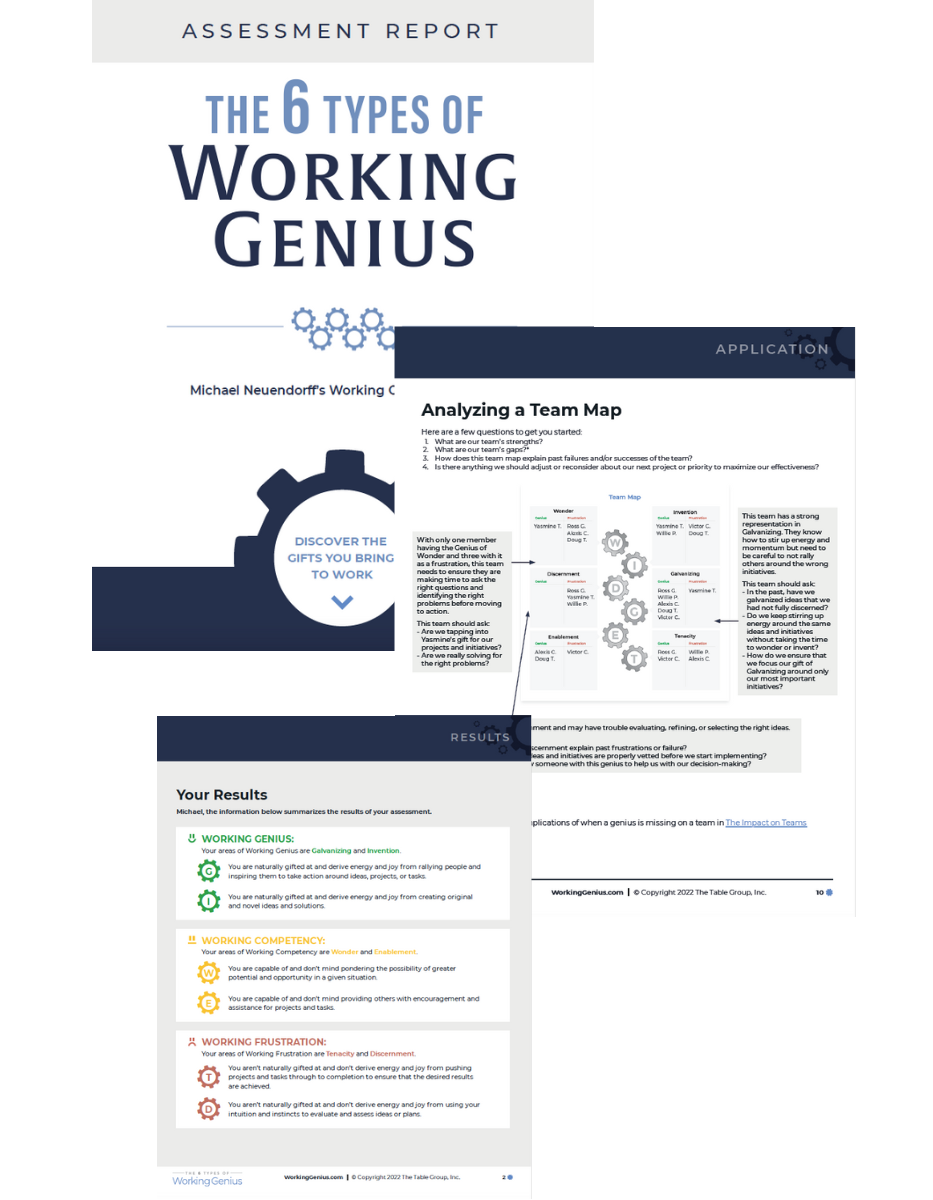
Working Genius Assessment Questions Actually Used In Practice
I spent three weeks last year trying to help a mid-size consulting firm figure out why their project handoffs kept falling apart. Everyone was competent. Deadlines were met. And yet deliverables landed on each other's desks looking nothing like what the previous person had promised. We ran about a dozen Working Genius Assessment Questions sessions before I figured out the actual mechanism at play. Not the theory—the mechanism. The framework itself comes from Pat Lencioni's later work, expanding on the Five Dysfunctions model. Six types of genius map onto the lifecycle of any piece of meaningful work. Wonder kicks it off. Invention builds the path. Discernment checks whether the path actually makes sense. Galvanize gets people moving. Enable keeps the machinery running. Defend protects the output from entropy. Anyone missing even one of these tends to produce work that looks complete but falls apart somewhere in the chain.
Where to Find Working Genius Assessment Questions You Can Actually Trust
The official assessment lives at TheWisdomoftheCrowd.com and costs about $20 per person if you go direct. Several third-party vendors resell it for less, though the scoring algorithm stays the same either way. I've seen free versions online, and they're close enough for rough self-assessment but drift noticeably when you're trying to use the results for team placement decisions. If you're doing this for a single person's development, the free quiz is fine. For a team of twelve or more, just pay the official price and skip the variance. The assessment itself is thirty-eight items. Each item presents a short workplace scenario and asks you to rate how naturally you respond to it. The scoring doesn't give you a simple genius count. It maps you onto a two-axis grid—frequency and comfort—which is where most people get confused. Having a genius doesn't mean you always use it. It means it's the default mode when nothing's forcing you to behave differently. I ran into a specific edge-case that the standard scoring guide doesn't really address. A client of mine scored as having all six geniuses except Defend. Standard interpretation would call that a significant gap. But when I dug into his actual behavior over four weeks, I noticed he wasn't missing Defend—he was exhibiting it as a frustration rather than a genius. He'd spot something wrong at the last possible moment and blast out an email to three people instead of raising it quietly through the proper channel. The assessment wouldn't have caught that. What caught it was watching him for a month after the scores came in.
The workaround I used was something I call reverse-scoring. Instead of asking what each person lacks, I asked what they do most poorly when they're not using their natural genius. For this particular consultant, Defend manifested as poor boundary-setting on scope changes. Once I reframed the conversation around scope defense instead of generic "defending work," he got it. The assessment had been technically accurate. The interpretation had been wrong.
Get the Full Details

The Six Geniuses and How They Actually Show Up On The Questionnaire
Wonder respondents tend to agree with statements about asking questions that no one else thinks to ask. If you score high here, you're likely the person who interrupts a perfectly functional meeting to ask whether you're solving the right problem in the first place. Your team either loves you or avoids sitting next to you at lunch. Invention is about connecting dots that don't obviously connect. High scorers on this axis will agree with items about generating multiple solutions before narrowing down. The pitfall most people miss is that Invention without Discernment produces quantity without quality. I've seen teams stacked with inventors ship three prototypes every sprint and miss every deadline because nobody had the genius to evaluate whether the prototypes were going anywhere useful. Discernment looks like pattern recognition under time pressure. The assessment items for this genius lean toward quick judgment and intuitive evaluation. People who score high here can usually tell you within thirty seconds whether an idea is sound or garbage. The friction point is that Discernment without Galvanize produces endless analysis and zero action. You get a team that can perfectly identify every flaw in every proposal and then fails to execute on anything because execution requires a different cognitive mode entirely.
Galvanize is the energy generator. Assessment items focus on motivation, urgency, and getting people past hesitation. Without Enable, Galvanize people burn bright and fast, then watch their momentum die because nobody structured the follow-through. The working dynamic that actually survives long-term pairs each high-Galvanize person with a high-Enable person as a default operating rule. Not as a preference. As a structural requirement. Enable maps onto process and resource management. These respondents agree with items about removing obstacles and keeping work flowing. Enable without Defend produces busywork that feels productive but generates no defensible output. The team ships frequently, looks active in status meetings, and delivers nothing anyone can point to as genuinely valuable. Defend is the quality gate. Items here focus on monitoring standards, catching errors, and protecting the integrity of completed work. Defend without Wonder produces incremental improvement on problems that shouldn't exist. You get a team that perfects every detail of a fundamentally misguided initiative and calls it excellence.
How To Use Assessment Results Without Making Everything Worse
The most common mistake I see is using Working Genius scores as static labels. People treat the assessment like a personality test result and file it away. That's the wrong model. The genius framework describes cognitive modes, not identity. You have access to all six. Some come naturally. Some require effort. The scores tell you where your effort should be directed, not what you're permanently incapable of. I run a twenty-minute team calibration session after everyone completes the assessment. We don't discuss individual results. We map the team's aggregate genius distribution onto a single whiteboard and look for gaps in the collective coverage. A team of eight where six people score high on Wonder and low on Enable will have a fascinating strategic vision and a terrible delivery rate. Once you see the gap painted on the wall, you stop blaming individuals and start fixing the structure. The calibration session also reveals second-order effects the assessment alone can't show. Two people might both score high on Invention, which sounds great until you realize they're generating competing solutions instead of building on each other's work. The assessment flags both as inventors. The team dynamic reveals the real problem: they're not sequencing their ideation, they're parallel-processing it into noise.

There's a ceiling effect worth noting. The assessment loses discrimination power when you apply it to senior leaders who've spent twenty years developing compensating behaviors. A VP might score moderate on Defend because she's learned to systematically question every deliverable before it reaches her desk. The assessment reads that as a lack of natural genius. In reality it's a learned discipline that masks the underlying preference. If you're assessing experienced professionals, supplement the questionnaire with behavioral interviews that probe actual workplace patterns, not self-reported preferences. Another limitation that nobody mentions in the marketing materials: the framework assumes a certain type of knowledge work. Factory floor supervisors, emergency room nurses, and assembly line managers don't map cleanly onto the six-genius model. The cognitive sequence Lencioni describes—wonder through defend—fits product development and consulting workflows very well. It fits sales operations moderately. It fits routine manufacturing poorly. If your team's work doesn't follow a discovery-to-delivery pipeline, the assessment will give you accurate scores that point at the wrong problems.
A Practical Walk-Through Of A Single Assessment Session
Here's what actually happens when I run this for a new team. First, everyone completes the thirty-eight items independently. No discussion. No consensus-building. The scoring depends on individual instinct, not groupthink. This takes roughly twelve minutes for thirty-eight items if people aren't overthinking each choice, which most don't initially, though a few stubbornly second-guess everything and drag it to twenty-five minutes. Next, I generate the reports. The official platform does this automatically. Each person receives a PDF showing their frequency and comfort ratings across all six geniuses plus the three frivolities. The report includes a brief narrative description that's accurate but generic. I've read the same description for fifty people and recognized zero individual variation in it. The data is personal. The interpretation is boilerplate. Then comes the team mapping exercise. I project a grid with Wonder on the top row and Defend on the bottom. Each team member becomes a colored dot placed according to their composite score. The visual pattern appears instantly. Gaps show as empty rows. Clusters reveal hidden redundancies. You don't need to understand the framework deeply to see that something's wrong when seven of eight dots sit in the middle two rows and the top and bottom are completely bare.
After the visual, we spend ten minutes discussing what the pattern predicts for upcoming work. Not what it explains about the past. The assessment is a prediction instrument, not a retrospective diagnosis. A team missing Galvanize won't suddenly start motivating each other because someone acknowledged the gap. They'll continue coasting until external pressure forces motion, which is usually too late. The value is in anticipating that friction and building workaround structures before the pressure hits. One thing the standard process omits: tracking score drift over time. I've started asking people to retake a reduced fifteen-item version every six months after the initial assessment. The full thirty-eight items get stale from repetition. The shortened version captures directional movement without the practice effect. You'll see some people's scores shift noticeably when they enter a new role or project type. The genius doesn't change. The expression of it does. The assessment picks up that change if you give it the chance.

Working Genius Assessment Questions For Remote Teams Specifically
Remote work amplifies every genius gap by about forty percent. That's not a precise statistic, but my observation across fourteen remote teams over eighteen months tracks consistently. Wonder goes unexpressed because there's no casual hallway conversation to seed curiosity. Invention gets siloed into individual effort instead of collaborative iteration. Discernment loses its social feedback loop because async communication strips tone and urgency from evaluation. Galvanize drowns in calendar noise. Enable becomes invisible administrative labor that nobody acknowledges. Defend turns into nitpicking that damages psychological safety because you can't read the room when you're reading a Slack thread. The workaround I developed for remote teams adds a weekly fifteen-minute wonder check-in. One person poses an open-ended question about the current project's direction. No solutions allowed. Just exploration. This artificially creates the Wonder space that remote work compresses. It takes almost no time and shifts the entire team's cognitive posture for the week ahead. The assessment helps you identify who naturally drives these sessions and who needs explicit permission to participate. Remote scoring interpretation also needs adjustment. People who score moderate on Galvanize in an office environment often score low in remote assessments because they've adapted their behavior to fit asynchronous communication patterns. The assessment captures what they do in their current context, not what they're capable of. I always clarify this distinction before sharing results with remote teams. The gap between context-adapted behavior and natural genius is where the real development work lives.
When The Assessment Actually Fails
The Working Genius framework breaks down in two specific scenarios. First, organizational cultures that punish intellectual curiosity. Wonder-genius people in these environments learn to suppress their questioning behavior and present polished conclusions instead of open inquiries. The assessment reads the suppression as a lack of genius. The person still has the cognitive capacity. The culture has just made it unsafe to express. Second, teams where role clarity is so extreme that each person only ever exercises one or two geniuses by design. A pure research lab might have scientists who only Wonder and Invention, while engineers handle everything else. The assessment will flag the researchers as deficient in four out of six geniuses. They're not deficient. They're specialized. The framework confuses specialization with absence when applied to deliberately partitioned work structures. If you're working in either of those environments, the assessment gives you data, but the data requires careful contextual interpretation before you act on it. Don't use it as a hiring filter. Don't use it for promotion decisions. Use it as a conversation starter about how work gets organized and whether that organization serves the actual work being done. That's the only application I've found reliable across every team I've worked with.
The assessment itself is fine. Thirty-eight questions. Twelve minutes. Twenty dollars. The interpretation is where most people waste time and money by applying it mechanically to complex human systems. The framework describes patterns, not prescriptions. Your job is to figure out which patterns matter for the work you're actually doing and which ones are just noise in the data.


