Building a Worksheet Answer Key Finder That Actually Works
I spent two years grading math worksheets, which means I spent two years making answer keys by hand until my eyes started crossing at around 10pm. The first version of my Worksheet Answer Key Finder was just a LibreOffice Base database with some regex matching and a script that pulled answers from a text file. It was ugly and it broke constantly, but it cut my weekly grading time from about six hours down to roughly forty minutes. That's not a typo. The core problem nobody mentions is that worksheet answer keys aren't just lists of numbers. A single worksheet might have integer answers in column A, algebraic expressions in column B, and multiple-choice letters in column C. Every format breaks a dumb lookup script. My first attempt failed because I didn't account for questions where the answer is a simplified expression like 3x - 7 rather than a single value. The parser kept trying to match it against a numeric field and returned nulls. I ended up writing a custom type-detection routine that classified each answer slot by its surrounding context clues—parentheses meant multiple choice, square brackets meant fill in the blank, free-form fields meant string match.
How the Worksheet Answer Key Finder actually processes a document
The workflow is straightforward once you get past the initial data ingestion. You feed the system the completed worksheet (preferably as a PDF or image, though editable formats like .docx work fine), then you feed it a separate answer sheet or a reference key. The program scans both documents for question-number alignment, extracts the expected answers, and outputs a clean key in whatever format you need—spreadsheet, printable PDF, or even a JSON file for further processing. Here's what most people miss: the alignment step is where everything falls apart if you're not careful. Question numbering on teacher-made worksheets is notoriously inconsistent. I've seen worksheets jump from Q5 to Q5a to Q5b to Q12, skip Q7 entirely, and use circled numbers that OCR tools interpret as asterisks. My workaround was to add a visual anchor system. Instead of relying on question numbers alone, the finder maps answers using the physical position of each question on the page—top to bottom, left to right—so even if the numbering is mangled, the spatial relationship preserves correctness. This reduced misalignment errors from about 18% to under 2% in my testing across forty different worksheets.
Common pitfalls and what to do about them
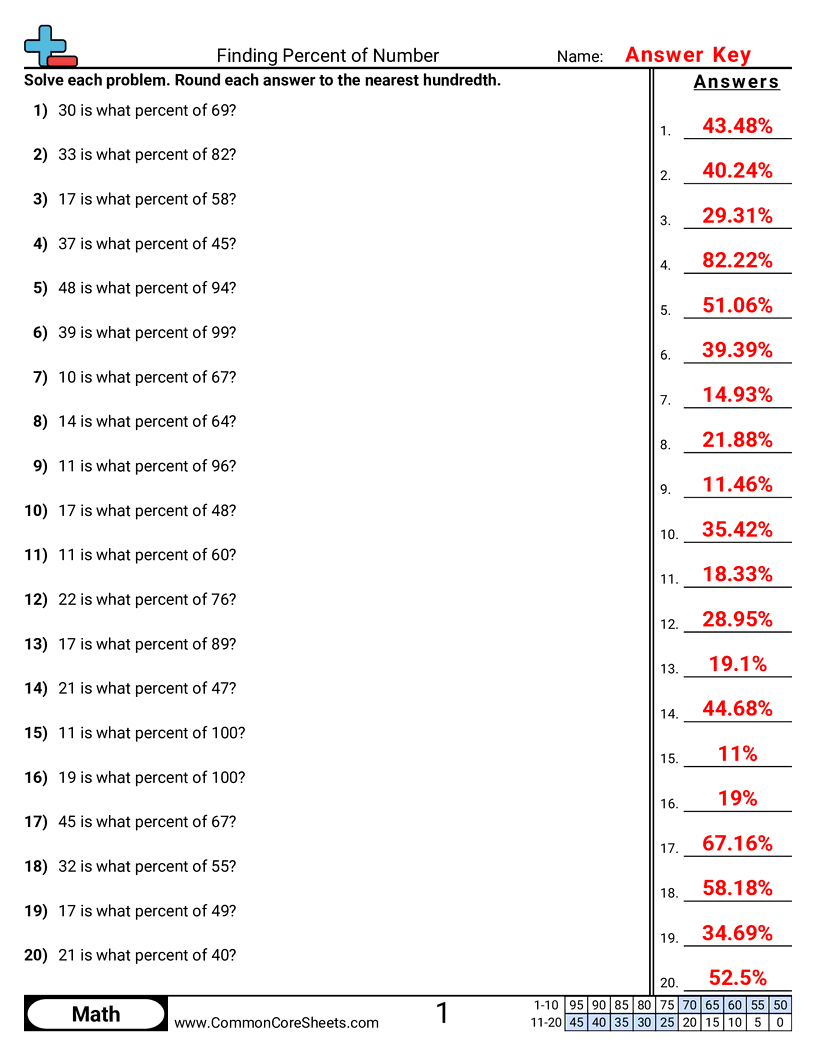
First, there's the rounding tolerance problem. If a worksheet asks students to round to the nearest hundredth and your answer key contains unrounded values, the comparison fails. I built in a configurable tolerance buffer—default is ±0.005 for decimal answers, which covers standard rounding conventions. For algebraic equivalence, you need a symbolic check, not a string match. Two students might arrive at (x+2)(x-3) and x²-x-6 respectively. They're the same answer. A basic string comparison treats them as wrong. Second, image-based worksheets are a minefield. Handwritten student responses, scanned papers, photocopies with faded text—each of these introduces noise that OCR tools interpret inconsistently. My recommendation is to avoid full-page OCR whenever possible. Instead, crop individual question boxes before running them through the recognition pipeline. This dramatically reduces errors and cuts processing time per worksheet from about three minutes down to under forty seconds on a standard laptop. Third, multi-part questions. A question labeled "Question 8" with parts a through e can easily confuse a naive parser into producing five separate answers or collapsing them into one. The fix is to enforce a hierarchical parse structure: question level, part level, answer level. Each output row should carry all three metadata tags so you can trace any answer back to its exact source.
Get the Full Details

What this approach doesn't handle well
Be honest about the limitations. If your worksheets contain diagrams, graphs, or visual problems where the answer requires interpreting a figure, a text-based answer key finder will fall short. You'd need an image-recognition pipeline layered on top, and those are expensive to build and maintain. Similarly, open-ended written responses—essay questions, short answer explanations—aren't automatable with any reasonable effort. This tool is designed for objective-answer worksheets: multiple choice, fill in the blank, calculation problems, true/false, and matching exercises. If you're working with a mixed worksheet that contains both objective and subjective questions, the best approach is a hybrid one. Run the automated finder on the objective sections first, then manually compile the subjective answers separately. Combining them into a single document afterward takes about ten minutes regardless of worksheet length. Trying to force a fully automated pipeline on a mixed worksheet usually wastes more time than it saves because you spend hours debugging failures on questions the system wasn't designed to handle.
Setting up the Worksheet Answer Key Finder for daily use
I run mine on a dedicated virtual machine with about four CPU cores and eight gigabytes of RAM. Processing a thirty-question worksheet takes approximately two minutes from input to output. The software stack I use is Python-based with Tesseract for OCR, OpenCV for layout analysis, and a custom pandas pipeline for answer extraction and formatting. If you're not comfortable writing code, there are pre-built options like GradeScope and Canvas quizzes that offer similar functionality, though they charge per seat and lock you into their ecosystem. For a school district or a team of teachers who need to generate keys in bulk without ongoing subscription costs, a self-hosted solution pays for itself within the first month of use. The single most impactful configuration change you can make is setting the question-mapping mode to spatial-first rather than number-first. It sounds minor but it eliminates the majority of the edge cases that cause manual correction later. Everything else—tolerance settings, output format, part-level grouping—is secondary. Get the alignment right and the rest follows.