Worksheet For Statistics Modern: What It Actually Is and How to Use It Without Losing Your Mind
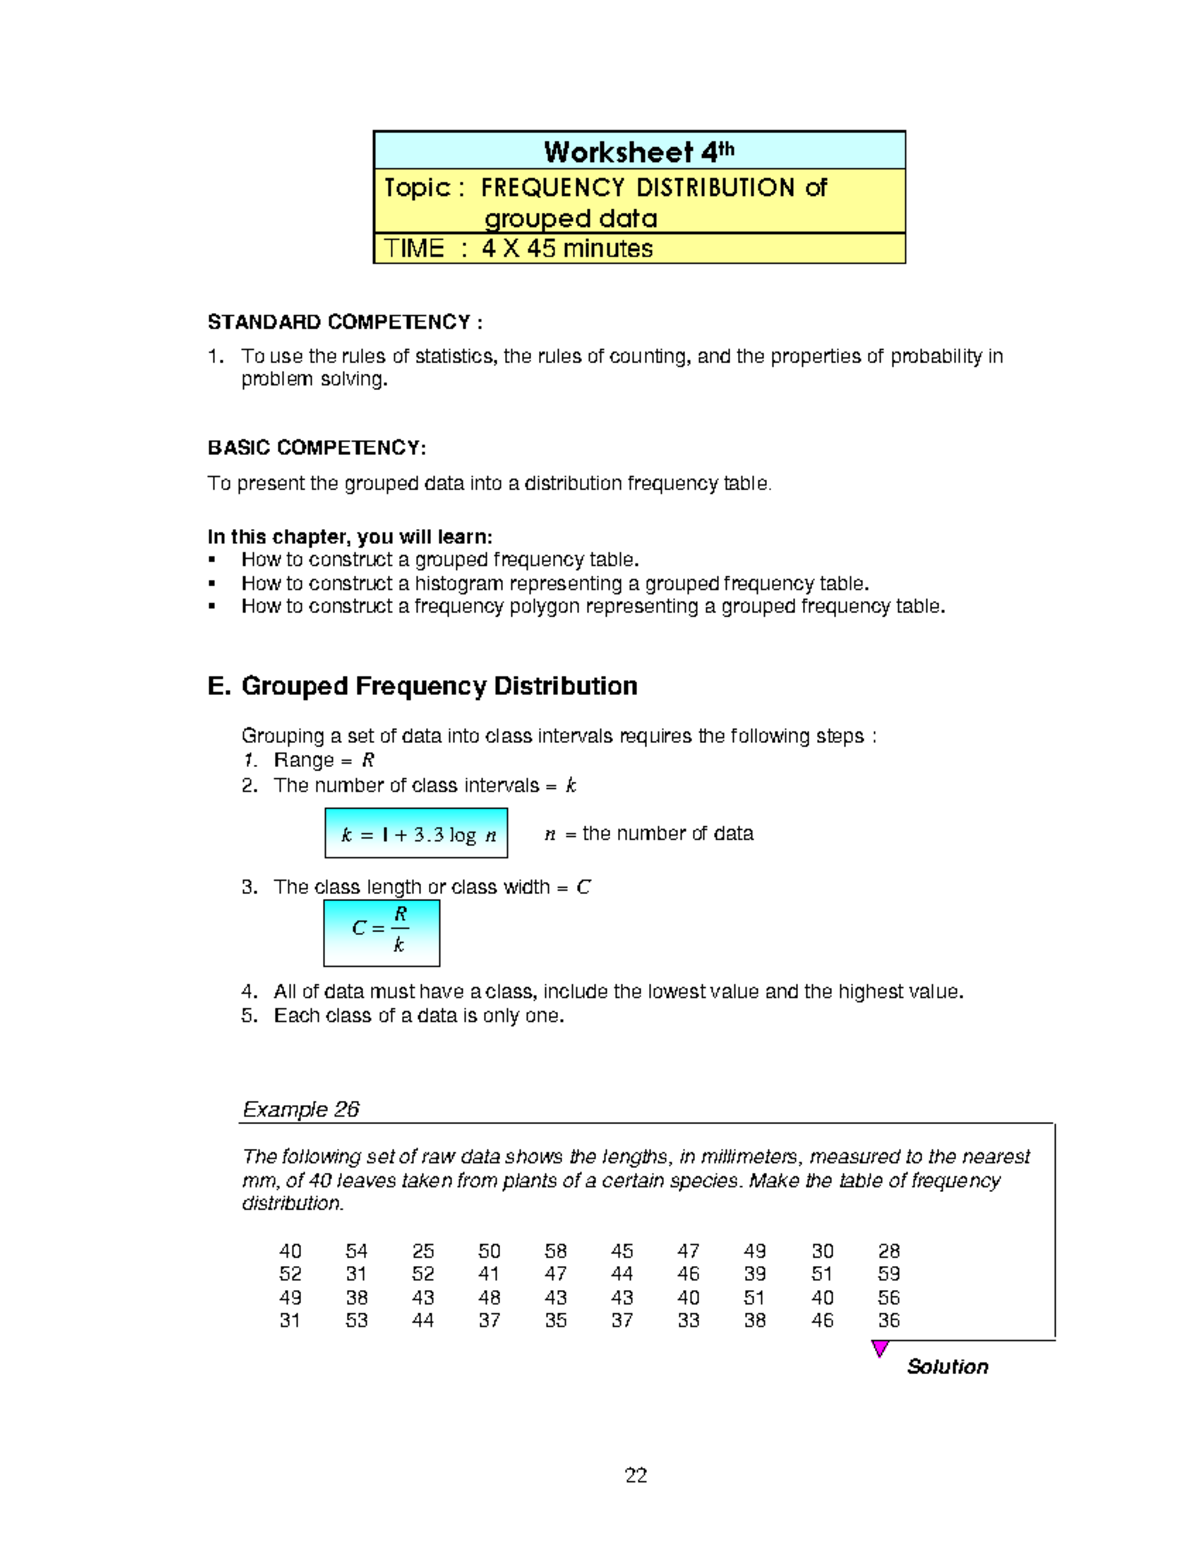
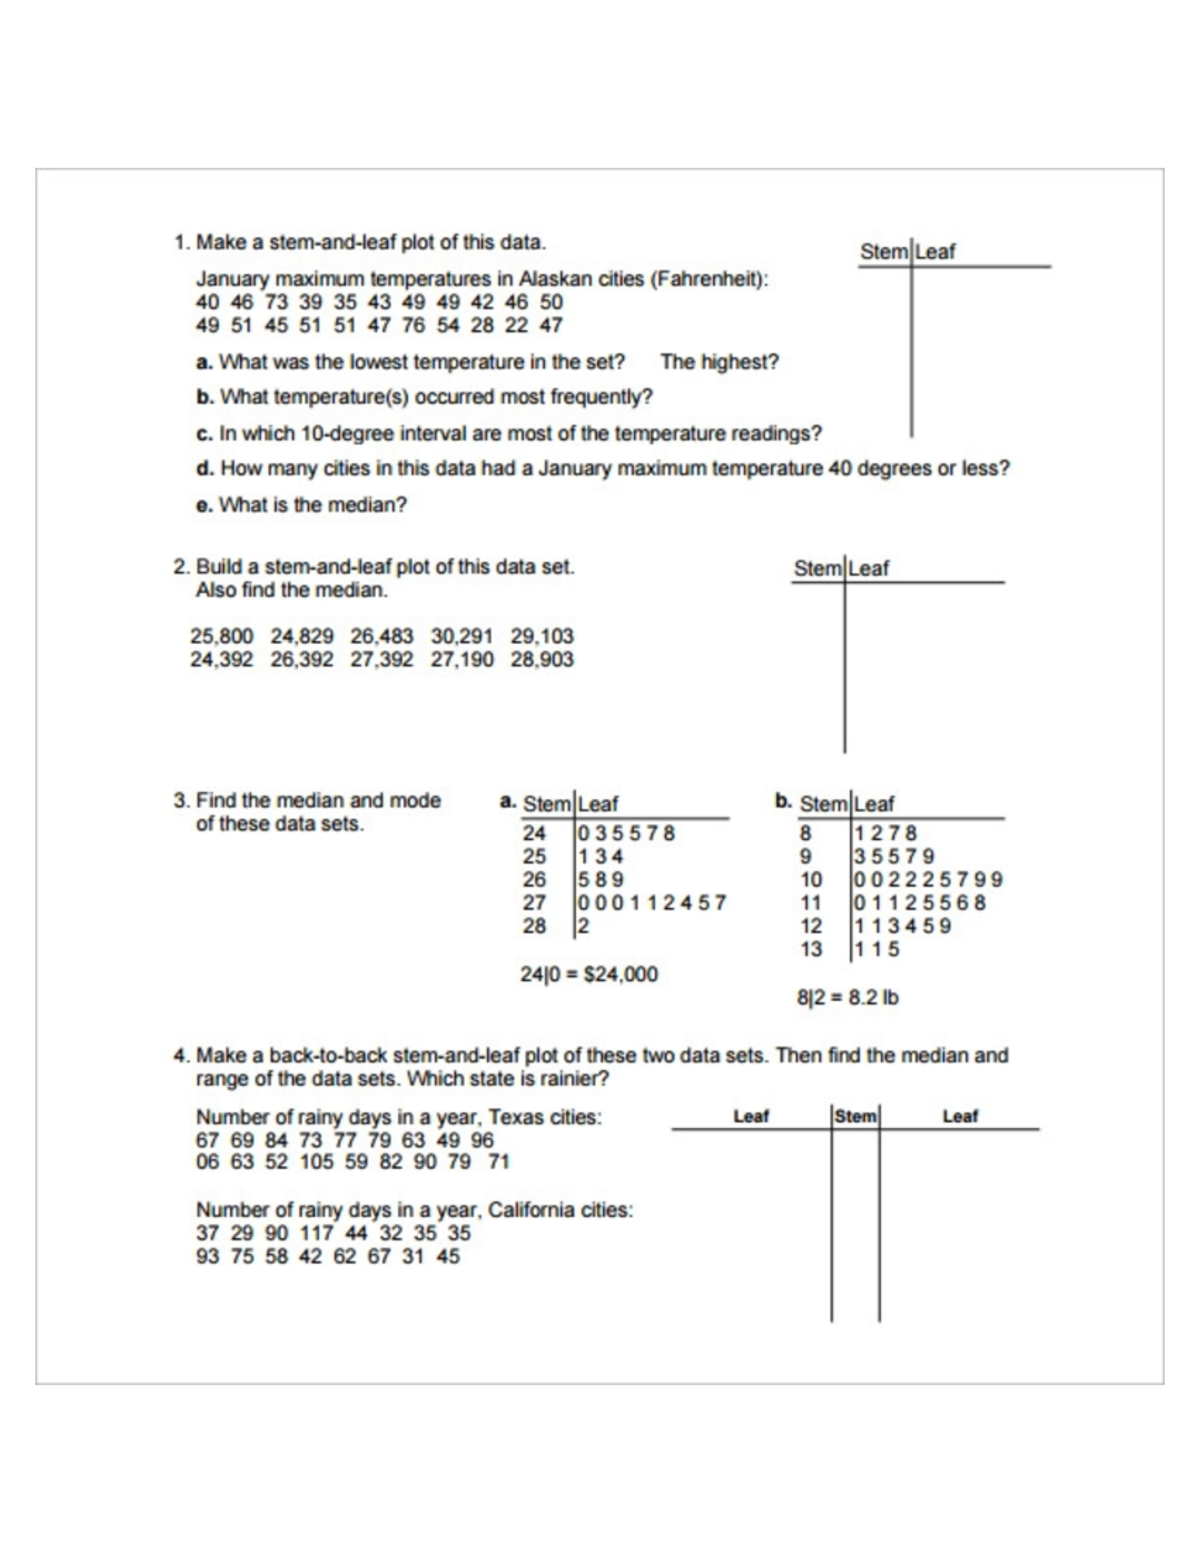
A statistics worksheet is just a structured document that walks you through statistical procedures step by step. The modern version takes that concept and applies it to current methods like regression, hypothesis testing, ANOVA, confidence intervals, and basic machine learning preprocessing. Most of these worksheets are built for Excel, Google Sheets, or sometimes R/Python environments. They save time but they also bake in assumptions you need to understand or you will get wrong answers with zero warning. Start with your raw data. I usually pull it into a clean table where each row is an observation and each column is a variable. No merged cells. No blank columns interrupting the range. Everything in one contiguous block. Then you pick which statistical test or method you need. The worksheet should have sections for input data, formula references, output results, and interpretation notes. For hypothesis testing, I set up the worksheet with columns for the null hypothesis value, sample mean, standard deviation, sample size, significance level, and the calculated test statistic. The formulas follow directly. In Excel that means something like T.TEST or manually computing the t-statistic using AVERAGE, STDEV.S, and SQRT. The worksheet makes it repetitive work transparent instead of burying it in a single cell.
I learned the hard way that modern worksheets fail silently when assumptions are violated. Here is a specific example: I was running a two-sample t-test worksheet for a clinical dataset with unequal variances and skewed distributions. The worksheet computed the p-value correctly under the equal variance assumption and gave me a result that looked significant. It was not. I caught it because I added a column that calculated the F-statistic for variance equality and flagged cases where the ratio exceeded four. That workaround took me five minutes and prevented a completely wrong conclusion. For regression worksheets, you want columns for each predictor variable, the response variable, coefficient estimates, standard errors, confidence intervals, R-squared, adjusted R-squared, and residual diagnostics. The worksheet should compute VIF values for multicollinearity checks. Most people skip that part and then wonder why their coefficients flip signs when they add one more variable. When I build these, I include a section for residual plots or at least a text-based summary of normality checks. Shapiro-Wilk or Kolmogorov-Smirnov statistics in the worksheet itself. If the data are clearly non-normal and your sample is small, the worksheet should recommend a nonparametric alternative or a transformation. It should not just spit out a parametric result and pretend everything is fine.
Counter-Intuitive Things Most Beginners Miss
First, a worksheet that automates calculations does not replace understanding the statistical method. I have seen people run an entire ANOVA worksheet and report the F-value as proof of difference between groups without checking homogeneity of variance or normality of residuals. The numbers come out clean. The analysis is still garbage. Second, adjusted R-squared is not always better than plain R-squared. In small datasets with few predictors, adjusted R-squared can be misleadingly low because the penalty for degrees of freedom is too harsh relative to the information content. I had a dataset with twelve observations and three predictors where adjusted R-squared came out negative. The model was still useful for prediction within the observed range. The worksheet flagged it as a failure by default and I had to override the interpretation. Third, most modern worksheets assume your data are independent. That assumption breaks constantly in practice. Time series data, clustered samples, repeated measures, hierarchical structures. A worksheet that does not account for the design structure will give you standard errors that are too small and p-values that are too optimistic. I once analyzed survey data with a worksheet designed for simple random samples and ended up with confidence intervals that were half the width they should have been. The fix was switching to a mixed-effects approach or at minimum using robust standard errors. No standard statistics worksheet handles that automatically.
Get the Full Details

Limitations and When It Completely Falls Apart
Worksheet-based approaches break down fast when your dataset exceeds spreadsheet row limits. Excel tops out at roughly a million rows. Google Sheets is similar. Once you hit that wall, you are stuck either truncating data or moving to a proper statistical environment. A worksheet cannot scale past that point no matter how well designed it is. Another failure mode is missing data handling. Most worksheets either delete rows with any missing values or require you to fill gaps manually beforehand. Listwise deletion can destroy your sample size and introduce bias if the data are not missing completely at random. I spent weeks dealing with a dataset where the worksheet silently dropped thirty percent of the records because of a few missing values in one column. The workaround was building a multiple imputation step into the worksheet before the main analysis ran. Over-reliance on p-values is a third weakness baked into most modern statistics worksheets. They produce p-values for everything because that is what users expect. The result is analysts treating p = 0.051 as a binary failure instead of a point on a continuum. The worksheet does not care. It just computes.
For complex designs like multilevel models, survival analysis, or Bayesian inference, a spreadsheet worksheet is genuinely inadequate. You need specialized software. R with lme4, Python with statsmodels, or dedicated tools like JASP or SPSS. No amount of clever Excel formulas will make a worksheet equivalent to a proper mixed-effects model builder.
Practical Recommendations
If you are doing basic descriptive statistics, t-tests, chi-square tests, simple linear regression, or one-way ANOVA, a well-built Worksheet For Statistics Modern in Excel or Google Sheets will serve you fine. It cuts a typical analysis from two hours of manual calculation down to about fifteen minutes once the template is ready. That time saving is real. Before you trust the output, check the assumptions. Run diagnostic columns. Verify your data structure matches the test requirements. Add variance ratio checks for t-tests, residual summaries for regression, and normality statistics wherever applicable. These extra steps add maybe ten minutes but they prevent catastrophic errors. For anything beyond basic methods, invest time in learning R or Python. The initial learning curve is steep. A couple of weeks of practice gets you further than months of wrestling with spreadsheet formulas. The statistical community has better tools now. A worksheet is fine for introductory work and quick exploratory analysis. It is not a long-term solution for real research.