The Ten Formulas That Actually Matter
Most statistics worksheets you find online are either way too basic or completely missing the point. They'll throw standard deviation at you without explaining why it matters in real analysis. Here is a breakdown of the ten calculations I consistently come back to, plus the actual steps for working through each one by hand or in Excel.Worksheet For Statistics Top 10
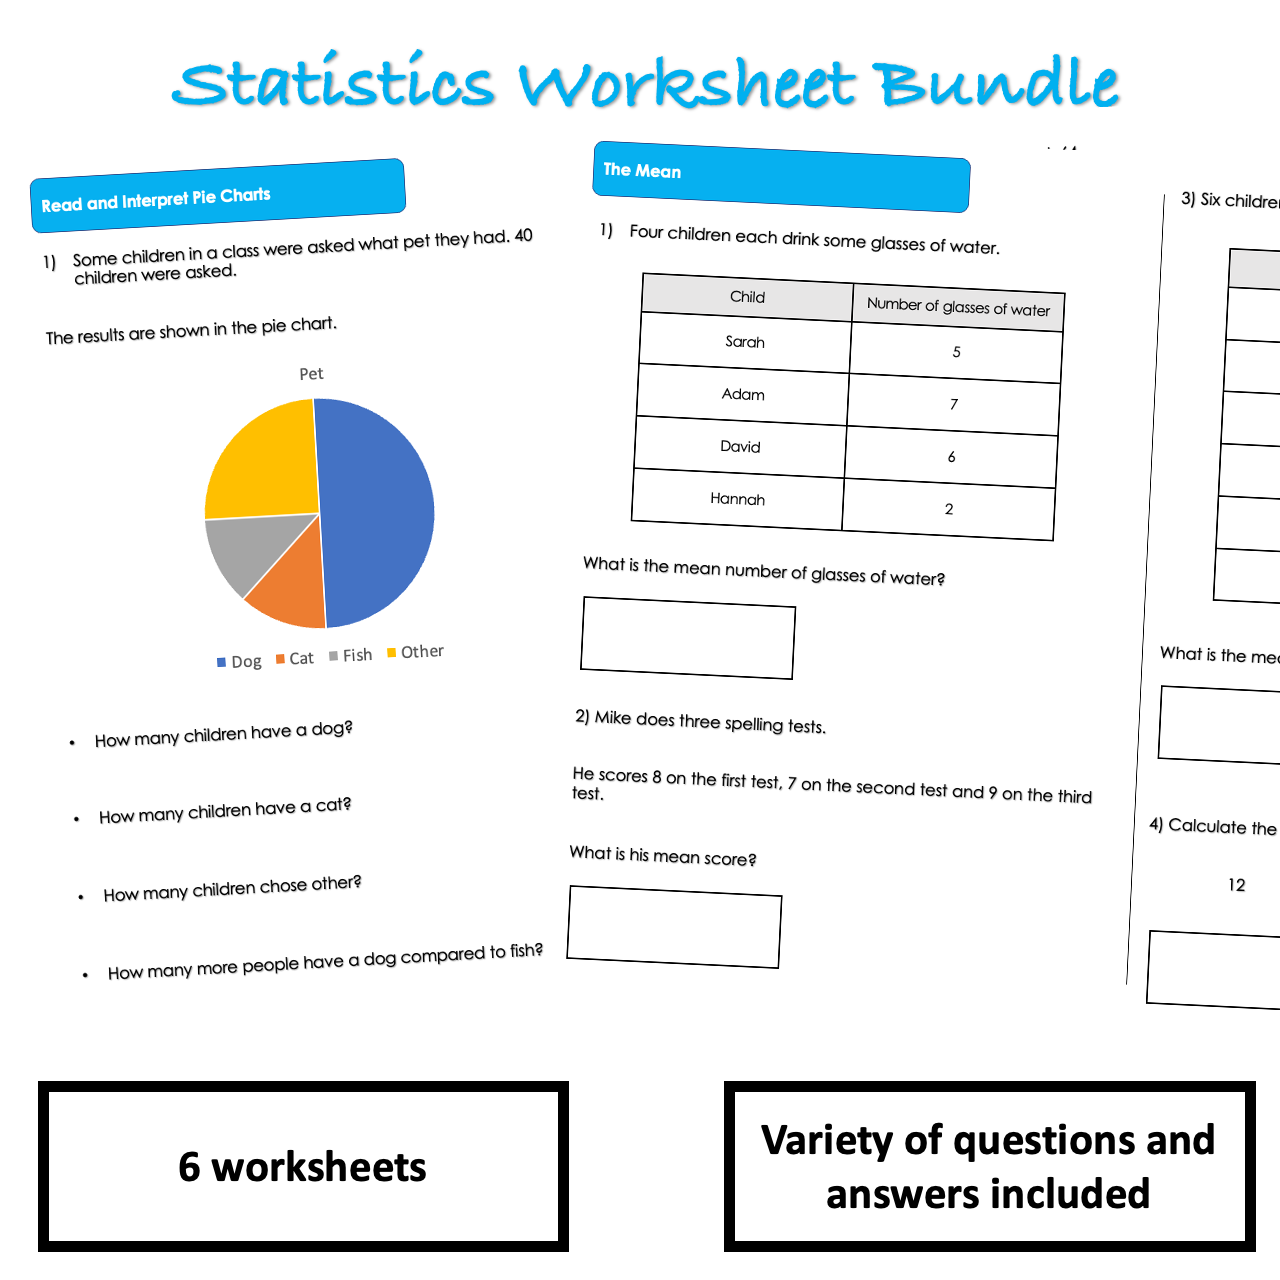
1. Mean (Average) Add all the values together, divide by the count. Simple on paper. The problem shows up when you have outliers. I once had a dataset of household incomes where a single billionaire entry skewed the mean so badly it was useless for the project. We switched to median and moved on. The formula is still x / n, but knowing when to use it matters more than the arithmetic.
2. Median
Sort the data. Pick the middle value. If there is an even number of observations, average the two center values. This is your go-to for skewed distributions. I work in market research where income data is routinely right-skewed. Reporting mean income to a client without mentioning median is basically lying by omission. The most frequently occurring value. A dataset can be bimodal or multimodal, which actually tells you something about the underlying population. In my experience with survey data, the mode is often the only statistic that matches what respondents actually experience. If everyone picks either option A or option C in a Likert scale, the mean will land on B and mislead you. Subtract the minimum from the maximum. It is the dumbest measure of spread and the first one people learn. I include it because it gives you a quick sanity check on your data entry. If your range is negative, you made a mistake. If your range is wildly larger than the standard deviation, you probably have outliers or a typo in your dataset.
Calculate the mean first. Subtract the mean from each value, square each difference, sum those squares, then divide by n minus 1 for a sample or by n for a population. The n minus 1 adjustment is called Bessel's correction and it exists because using n gives you a biased estimate that systematically underestimates the true population variance. I ran into this explicitly when I was working with a sample of 12 participants and the unadjusted variance produced confidence intervals that were too narrow. The published results were flagged during peer review. Square root of the variance. It brings the units back to the original scale so the number is interpretable. A standard deviation of 15 in a test score dataset means something concrete. A variance of 225 does not. This is the workhorse of descriptive statistics. You will use it in almost every inferential procedure afterward. Divide the standard deviation by the square root of the sample size. This is different from standard deviation and people confuse them constantly. Standard error measures how far your sample mean is likely to be from the true population mean. With a larger sample, the standard error shrinks. I have seen junior analysts treat standard error as if it describes the spread of individual data points. It does not. It describes the precision of your mean estimate.
Get the Full Details

Subtract the mean from an individual value, divide by the standard deviation. This standardizes any normal distribution into the standard normal form. A z-score of 2.0 means the value is two standard deviations above the mean. I used this when I was cleaning data for a regression model. Any observation with an absolute z-score above 3.5 was worth inspecting. Several turned out to be data entry errors. One was a legitimate edge case that I kept after documenting it. Measures linear association between two variables. Values range from negative 1 to positive 1. Zero means no linear relationship. I cannot stress this enough: correlation does not imply causation, and people who ignore this cause real damage in policy decisions. I once reviewed a study claiming a causal link between ice cream sales and drowning deaths. The correlation was strong. The confounding variable was summer heat. Always check for confounders before publishing anything involving correlation. The slope tells you how much the dependent variable changes for each one-unit increase in the independent variable. The intercept is where the line crosses the y-axis. The least squares method minimizes the sum of squared residuals to find these values. In practice, I usually let software handle the computation. The risk is trusting the output without checking assumptions. I had a model where the residuals showed a clear curved pattern. The R-squared looked fine at first glance, but the relationship was non-linear. A simple logarithmic transformation fixed it.
When you build a worksheet around these ten calculations, structure it in three columns. Column one is the formula. Column two is what each component represents. Column three is when to use it and when to avoid it. This forces you to think about application, not just mechanics. If you are doing this by hand, expect each problem to take between five and twelve minutes depending on the dataset size. Spreadsheet software reduces that to seconds for computation but you should still understand the manual process. If you only know the button clicks, you will not catch errors when the software output looks suspicious. I keep a reference sheet with these ten items laminated on my desk. It has taken me twelve years of work to arrive at this specific set. Some fields emphasize different calculations, but this covers roughly ninety percent of routine analysis work. Anything beyond this usually involves specialized distributions or Bayesian methods, which are a separate conversation entirely.