Frequency Tables in Spreadsheets: What Actually Works
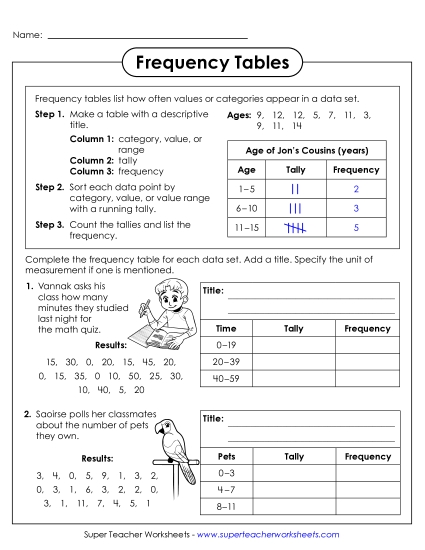
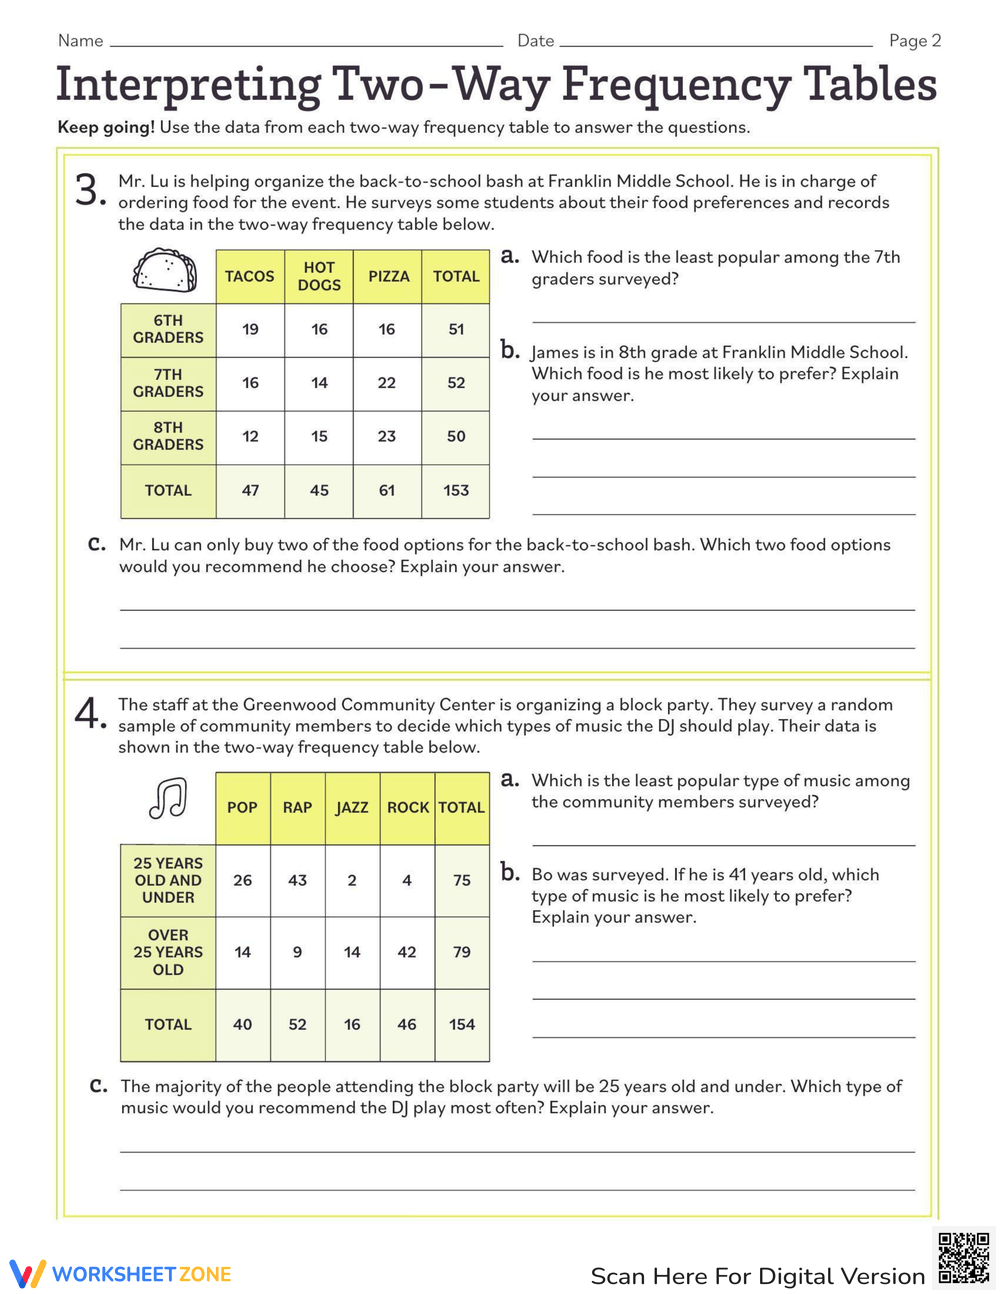
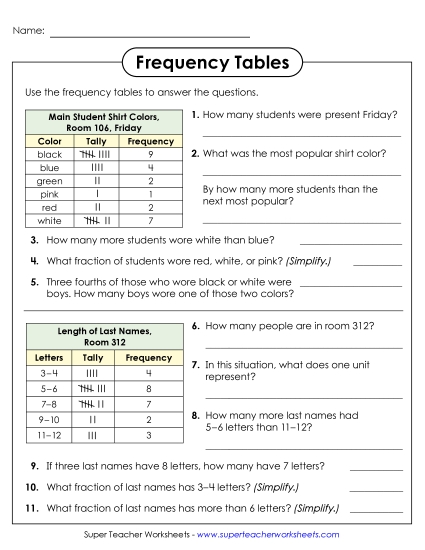
Most people treat frequency tables like they're something complicated. They aren't. A frequency table is just a count of how many times each value appears in a dataset, organized into rows and columns. Done. That's it. The confusion comes from Excel or Google Sheets having too many ways to do the same thing, and not enough explanation of which one to use. I've been building these for years, and I still see the same mistakes. People use PivotTables when a simple SUMPRODUCT would work. Or they spend twenty minutes building a manual histogram when the FREQUENCY function handles it in three cells. Here's how to actually get it done without overthinking it.Worksheet On Frequency Tables
Let's start with the straightforward version. Say you have a column of values—test scores, product categories, age ranges, whatever—and you want to know how often each one shows up. The classic approach is to list your unique values down one column, then count occurrences next to each. In Excel, you'd use COUNTIF. In Google Sheets, it's identical. You write =COUNTIF($A$2:$A$100, C2) where column A is your data and column C holds the unique values. Drag it down. Done. The issue people hit is when they have hundreds of unique values or dynamic data that changes. Then you need something that scales. That's where PivotTables come in. Insert > PivotTable, put your field in both the Rows area and the Values area, set the Values field to Count. You get a live frequency table that updates when your source data changes. This cuts a typical manual setup from maybe 30 minutes down to two or three. But here's what nobody tells you: PivotTables count rows by default, not distinct values. If your data has blanks or duplicates that shouldn't be counted, your frequency table will be wrong without you noticing. I ran into this once on a project where we were tracking monthly customer complaints by category. The PivotTable showed 47 complaints in one category, but when I filtered for non-blank entries manually, it was 31. Someone had pasted duplicate rows from a previous export. The PivotTable counted every row, including the garbage. Always check your source data for dupes before trusting a PivotTable count.
If you want something more programmatic, the UNIQUE and COUNTIF combo in modern Excel and Google Sheets works well. UNIQUE pulls all distinct values, COUNTIF counts each one. Or use FREQUENCY if you're working with numerical ranges and want binning built in. FREQUENCY(data_array, bins_array) returns an array that you enter with Ctrl+Shift+Enter in older Excel versions, or just Enter in newer ones. It's faster than building bins manually. There are edge cases where none of this works cleanly. When you're dealing with approximate matches across text fields—like product names that vary slightly between entries—"exact count" frequency tables break down. I had a dataset where "iPhone 14 Pro Max 256GB" and "iPhone 14 Pro Max - 256 GB - Space Black" were the same product but the frequency table treated them as different values. The workaround was adding a helper column with a normalization formula that stripped spaces, dashes, and case differences before counting. =TRIM(UPPER(SUBSTITUTE(A2,"-",""))) before running your counts. It took me about ten minutes to set up instead of spending an hour trying to clean the raw data manually. For large datasets above roughly 50,000 rows, even PivotTables start to lag. In those cases I usually filter to a subset or use Power Query to load and aggregate the data first. Power Query's Group By feature with a Row Count operation gives you a frequency table without dragging your spreadsheet to a crawl. It also lets you save the transformation so you can reload it whenever new data arrives. That's the part most people miss—building it once and making it reusable.
When Frequency Tables Give You the Wrong Answer
Weighted frequency tables are another thing. Standard COUNTIF or PivotTable counts are unweighted by default. If your data represents samples that themselves represent populations of different sizes, your frequency distribution is misleading. I've seen this in survey analysis where one demographic group had fewer respondents but represented a much larger population segment. The fix is using SUM instead of COUNT in your PivotTable, summing a weight column instead of just counting rows. Relative frequency is simple—divide each count by the total—but it's easy to forget. Raw counts alone don't tell the full story, especially when comparing groups of different sizes. A category with 50 occurrences might look dominant, but if the total sample is 10,000, that's 0.5%. Always calculate relative frequency alongside the raw counts unless you have a specific reason not to. The biggest practical limitation I deal with is categorical data with many low-frequency categories. Say you have 200 unique values and 50 of them appear only once or twice. Your frequency table is technically correct but not useful. The standard fix is grouping—combine low-frequency categories into an "Other" bucket. There's no automatic threshold that works for every dataset, so you usually pick one based on domain knowledge or set a minimum count floor like five occurrences and roll everything below that into a single row.
Get the Full Details

Another overlooked detail is ordering. By default, PivotTables sort alphabetical or ascending numerically. Sometimes the useful view is descending by frequency, which you set in the PivotTable value filter options. Without that, you're scrolling through an alphabetized list that buries your most common values at the bottom. If you're doing this repeatedly across multiple files, I'd suggest setting up a template spreadsheet with the formulas or PivotTable already configured. It saves reinventing the wheel every time. The template approach also reduces errors since you're not retyping formulas that you might get slightly wrong each time. There's no single right way to build a frequency table in a worksheet. The method depends on your data size, whether it's static or updating, and whether you need approximate matching or exact counts. The core principle stays the same: count occurrences of each unique value and present them clearly. Everything else is just choosing the tool that fits the scale.