What Actually Happens at a Data Science Workshop
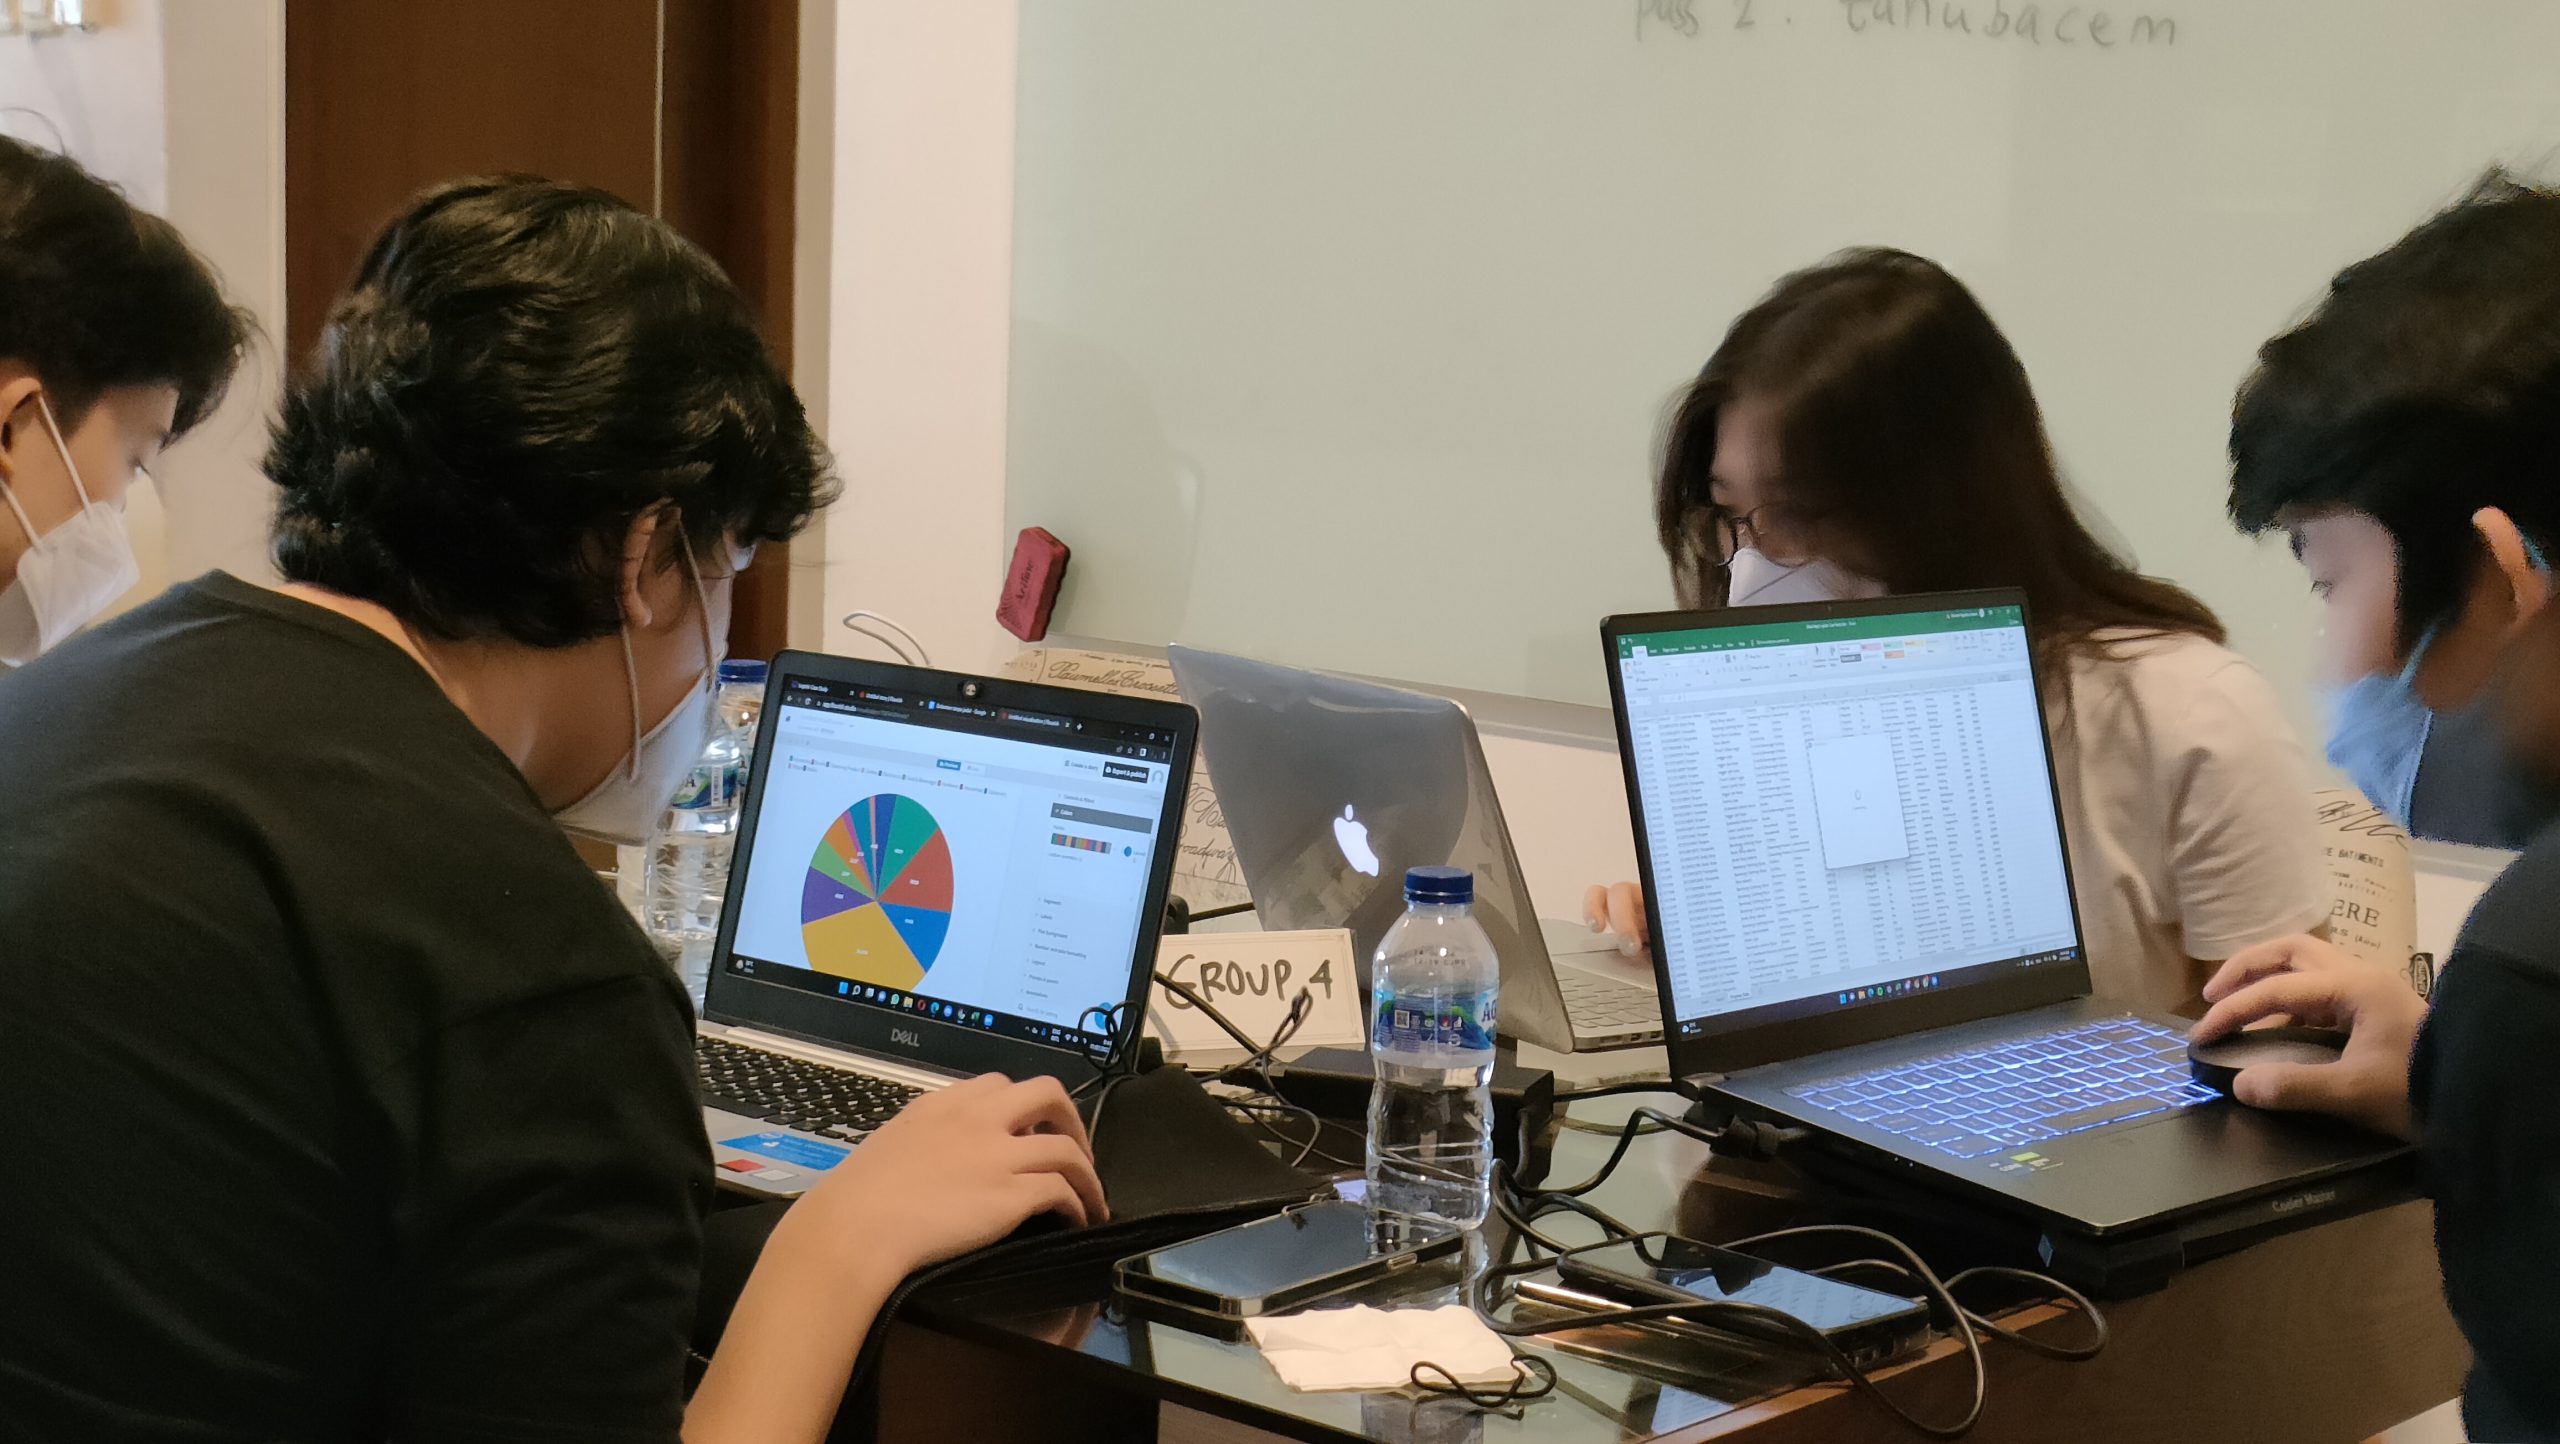
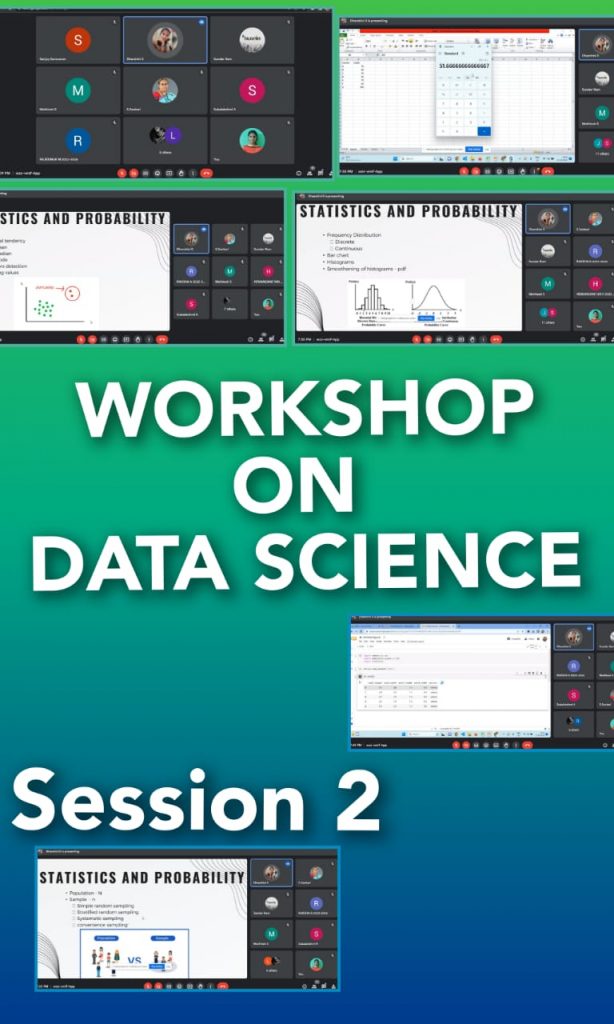
A Workshop On Data Science is usually a two to five day program where people who already know some Python or R get handed a messy dataset and expected to produce a usable model or report by the end. The promise on the brochure is always transformation. The reality is that you spend 60 percent of your time wrestling with missing values, data type mismatches, and the fact that nobody told you your database credentials won't work from the guest WiFi. I went into my third workshop thinking I was prepared because I had finished a couple of online courses. That was a mistake. The thing nobody warns you about is the environment setup. Instructors assume everyone has a recent Anaconda install, the right C compilers, and ten gigabytes of free disk space. Half the room is on a company-issued laptop with restricted admin access. You're sitting there trying to install XGBoost while someone three seats over has already started cleaning their data. Here's what I do now before registering for anything. I spin up a clean virtual environment with the packages listed on the workshop website, plus a few extras like plotly, shap, and optuna. I verify that I can import them all on the exact OS I'll be using. I also download the raw data if it's available ahead of time and load it into memory on my machine. That way if the network dies during the session, I'm not completely stranded.
Workshops typically cover a narrow slice of the pipeline. You'll see feature engineering, model selection, and basic evaluation. What you won't see is deployment, monitoring for drift, or the conversation you have with a stakeholder when the model performs perfectly on validation but fails on real traffic. That gap matters more than you think.
The tools you'll actually use
Most workshops run on Jupyter notebooks. They're convenient for exploration but a nightmare for reproducibility if you're not careful. I bring a Git repo pre-initialized with a requirements.txt and a .gitignore that blocks __pycache__ and .ipynb_checkpoints. The moment you start writing code in a notebook, you need to commit early and often. Waiting until the end to push changes is how you lose three hours of work when your kernel crashes. The typical stack includes pandas for data handling, scikit-learn for modeling, and matplotlib or seaborn for visualization. Some newer workshops have started adding streamlit or gradio for quick dashboards. It sounds helpful until you realize you've only spent twenty minutes learning the library before the session ends and you go home with a half-finished app that doesn't handle edge cases. If the workshop focuses on deep learning, expect PyTorch or TensorFlow and a GPU instance. Make sure you understand which one they're using before you arrive. I learned this the hard way when I spent the first hour trying to translate numpy matrix operations between frameworks because the instructor assumed everyone already knew the difference between eager execution and graph mode. You won't impress anyone by asking that question. You will lose time.
Get the Full Details

A specific problem I ran into and how I solved it
During a weekend workshop on classification models, our dataset had a target variable with severe class imbalance. The instructor walked through SMOTE oversampling and everyone applied it. My validation AUC jumped from 0.72 to 0.89, which looked great until I tried to apply the same pipeline to the test set. The synthetic samples leaked into the test split because the workshop code fit the SMOTE transformer before doing the train-test split. Classic data leakage. The model wasn't learning patterns. It was memorizing copied rows. The fix was straightforward but it required stopping the clock. I rewrote the preprocessing pipeline using sklearn's Pipeline object so that SMOTE only fitted on the training fold inside a cross-validation loop. I then used repeated stratified k-fold validation instead of a single split. The final AUC dropped to 0.76, which was honest. The workshop didn't cover this because the examples were designed for speed, not rigor. I ended up presenting the corrected results anyway. The instructor acknowledged the issue and spent five minutes explaining why leakage happens so frequently in teaching materials.
Counter-intuitive things that actually matter
Feature engineering is not the skill that separates good data scientists from the rest. It's the discipline to document every transformation you apply. I've seen senior engineers build impressive models that they couldn't replicate two months later because they made manual adjustments to the data without recording what those adjustments were. A simple dictionary mapping column names to their transformations takes twenty seconds and saves hours of confusion later. Another thing people miss is that cross-validation is not a substitute for a proper holdout set. K-fold gives you a better estimate of variance, but your final model should still be evaluated on data the algorithm has never seen during training or tuning. I've attended workshops where the entire grading rubric was based on cross-validated scores. That trains bad habits. Real projects don't hand you a leaderboard. They hand you a production environment and a deadline. Baseline models are more important than most attendees realize. Before you touch a random forest or a gradient boosting machine, train a logistic regression or a decision tree with depth three. If your complex model doesn't beat the baseline by a meaningful margin, you're wasting compute. I once spent an entire workshop day tuning a neural network that performed worse than a simple Naive Bayes classifier. The simpler model was faster, easier to explain to a non-technical stakeholder, and required half the memory. That's the kind of lesson that sticks with you.
When a workshop won't help you
Data science workshops are excellent for building velocity on clean problems with clear objectives. They are useless if your actual work involves unstructured data like images or documents and the curriculum is focused on tabular data. They won't teach you distributed computing or MLOps. They also won't prepare you for the political side of the job, like convincing a product manager to ship a model that's 85 percent accurate instead of demanding 99 percent. If you're looking to go deeper into production-grade systems, consider supplementing a workshop with hands-on experience deploying models through Docker containers or cloud services. Tools like MLflow for experiment tracking and Kubeflow for orchestration aren't covered in standard curricula but they're essential for anyone working in a team environment. A workshop gives you the foundation. You build the rest yourself. The best workshops treat you like someone who can read documentation and debug independently. The worst ones treat you like a tourist. Read the syllabus carefully, check the prerequisites, and don't be embarrassed to ask for clarification when the instructor assumes knowledge you don't have. Everyone else is too busy debugging their own code to judge you.

Finding a Workshop On Data Science that fits your level
Search for programs that list specific tools and a detailed project description rather than vague promises about "mastering AI." Look at the instructor's GitHub or LinkedIn to verify they've shipped real projects. Check recent reviews for comments about pace and support. Avoid anything that requires no coding background if you're already comfortable with Python. You'll be bored and you'll waste everyone's time. I've found that the workshops with the best outcomes are the ones where the instructor spends the first hour diagnosing everyone's environment and the last hour reviewing common mistakes from the group. That structure respects your time and acknowledges that learning happens through errors, not through perfect demo runs.