Understanding X Versus Y Axis in Data Visualization
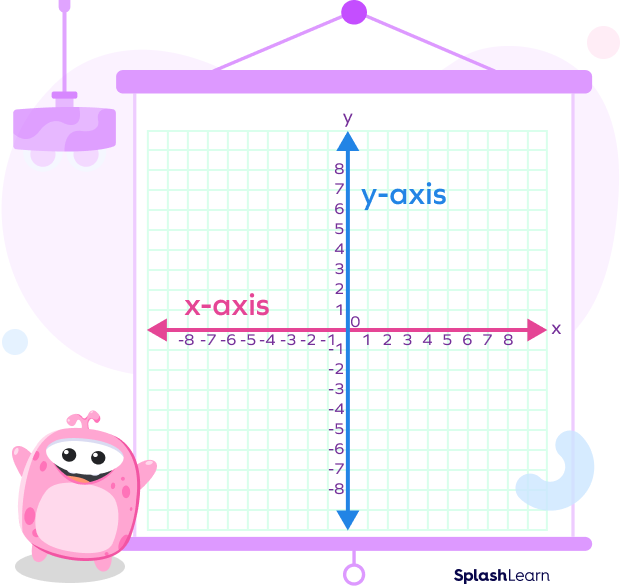
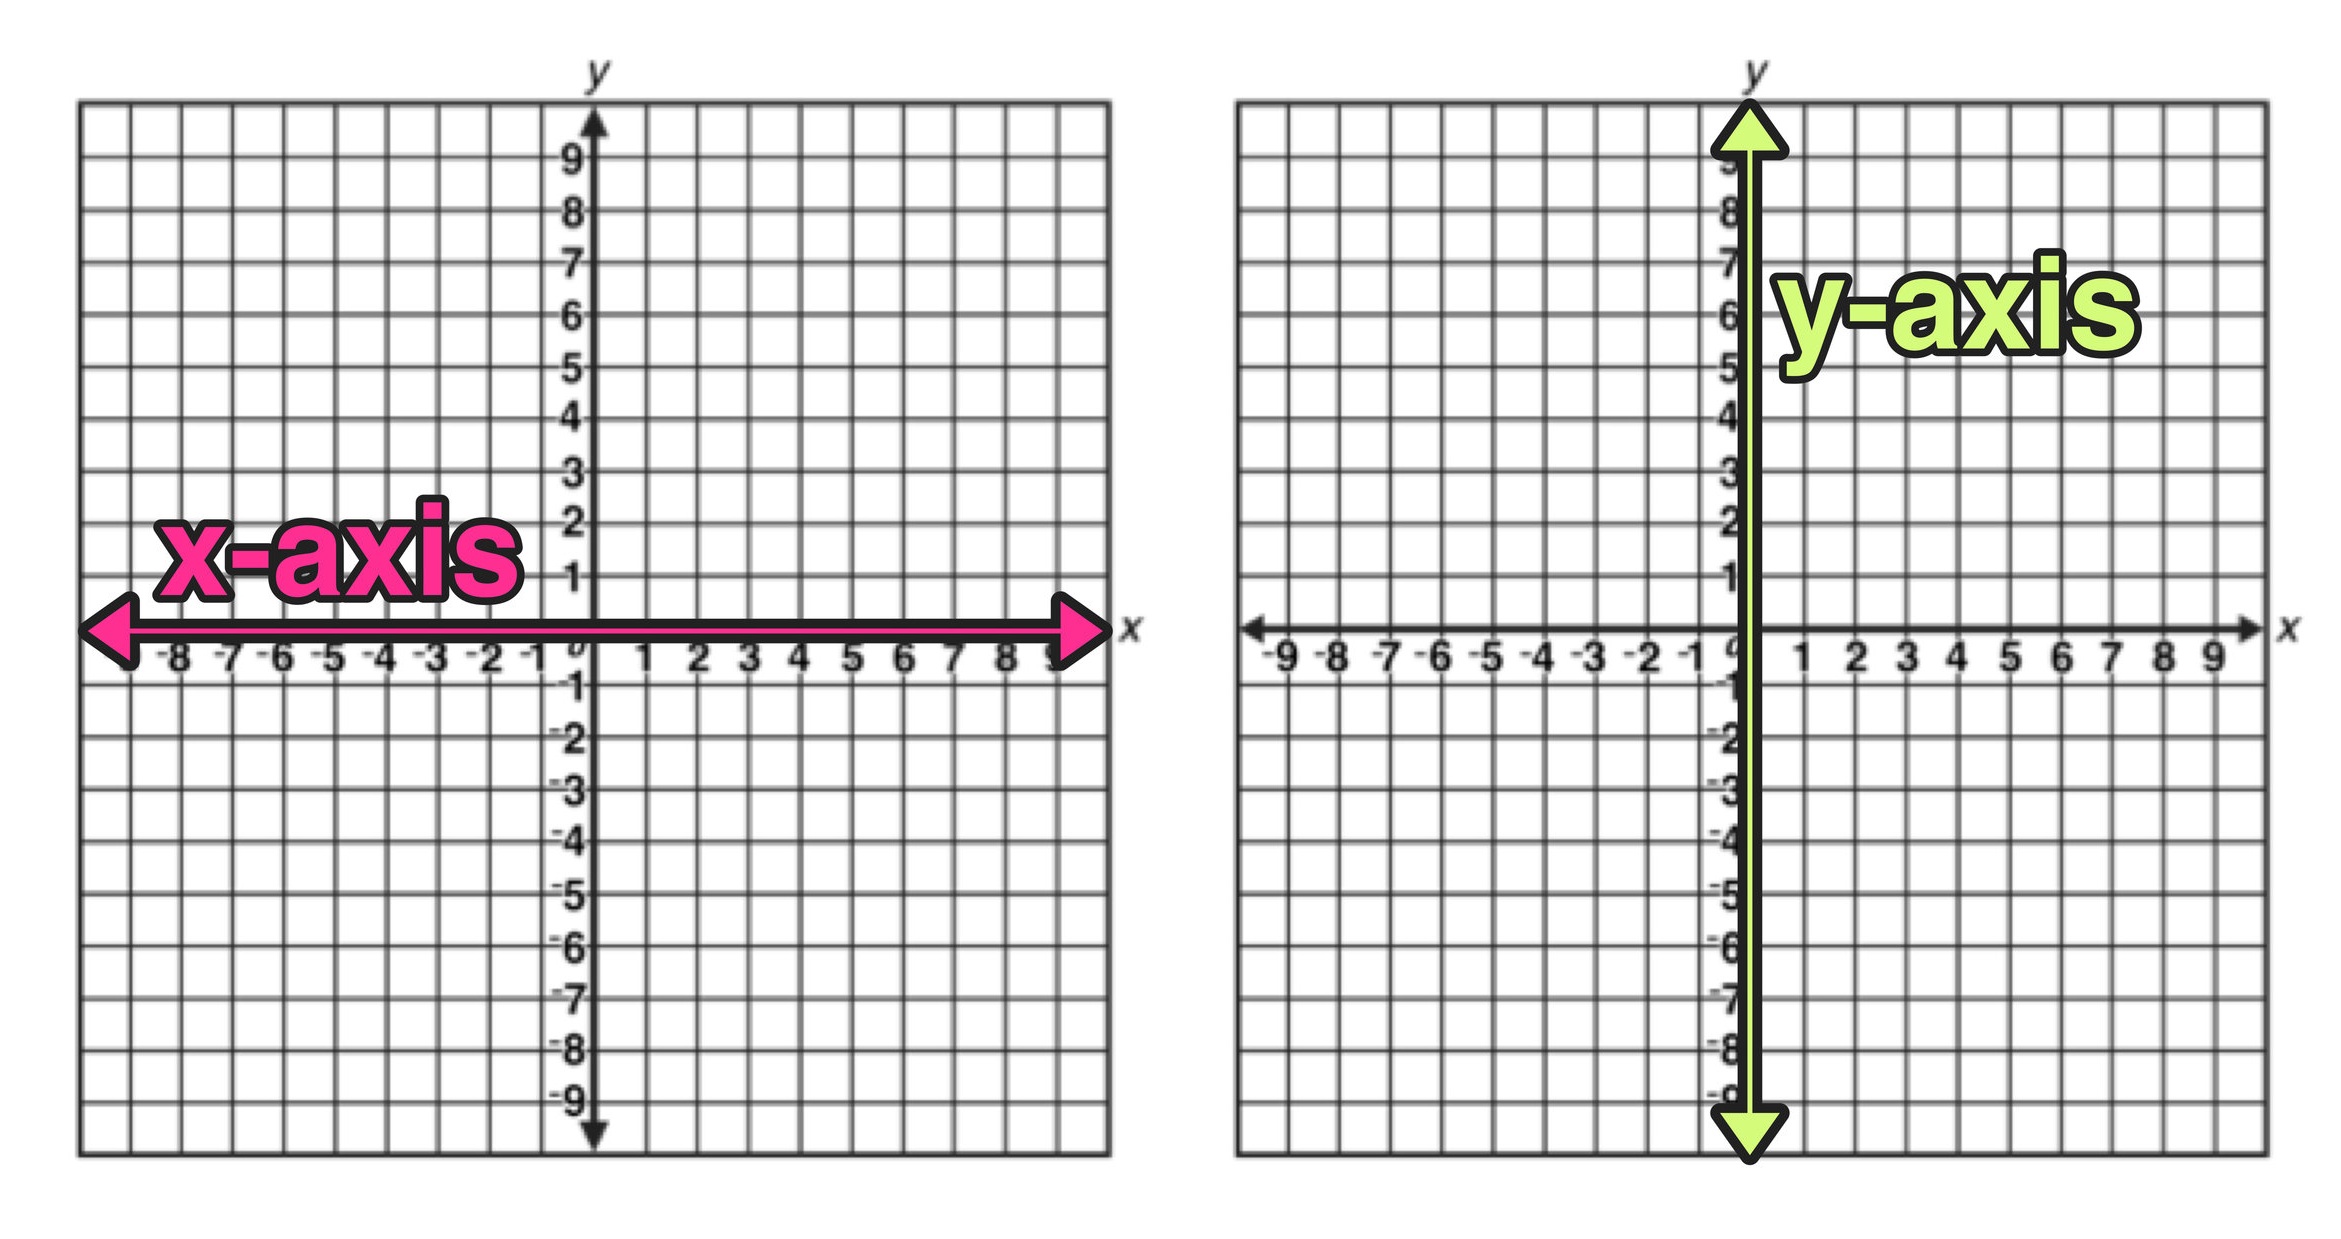
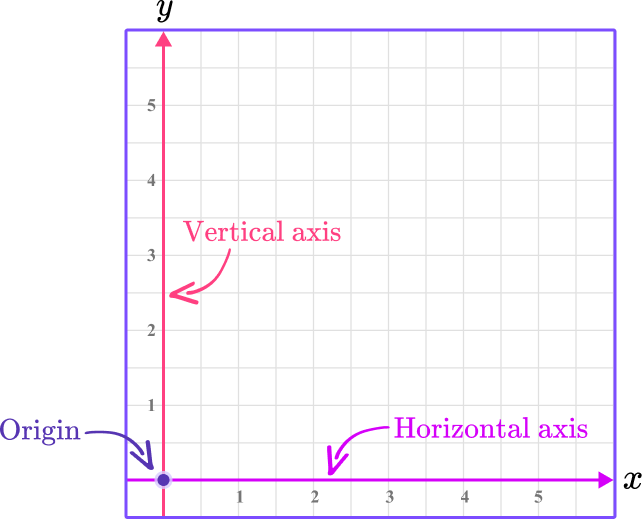
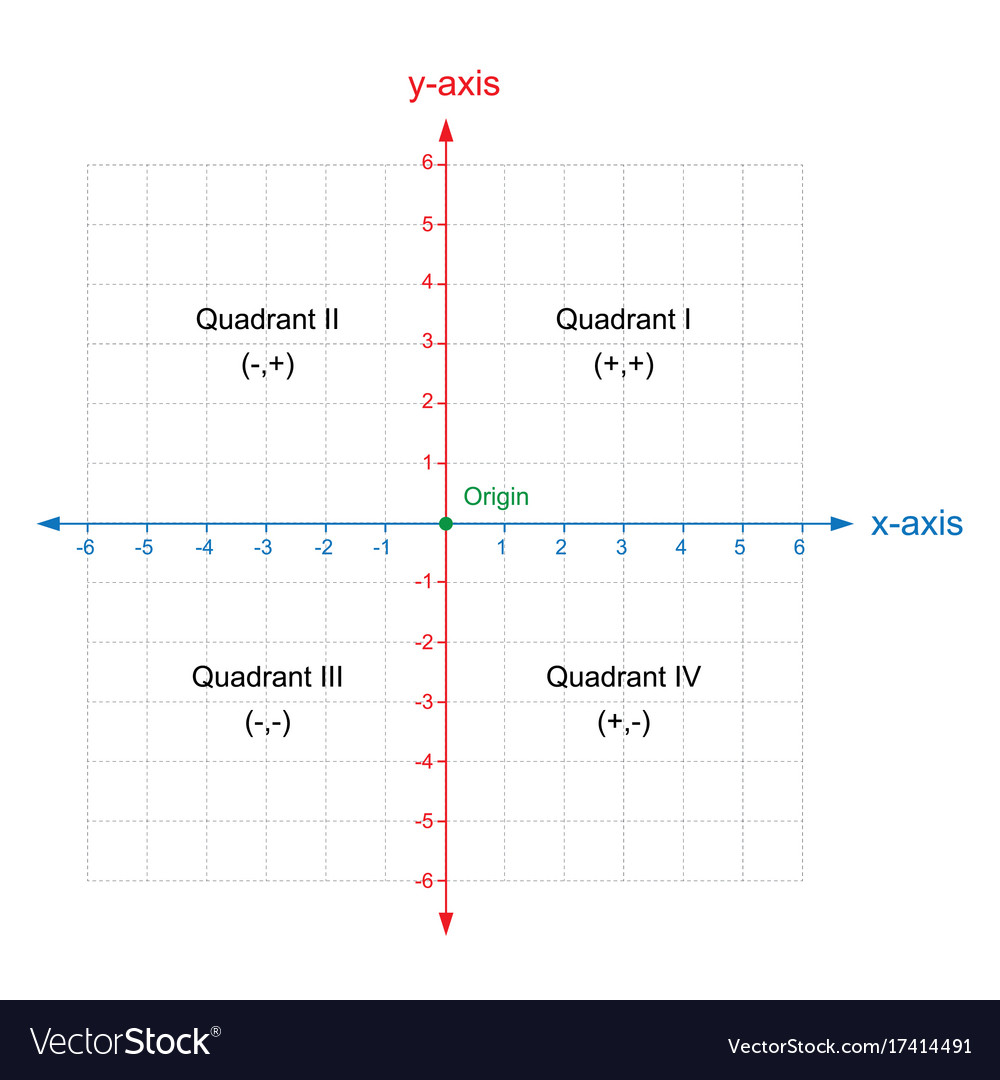
The X and Y axis are the two perpendicular lines that form the backbone of any Cartesian coordinate system. The X axis runs horizontally across the bottom, and the Y axis runs vertically up the side. This isn't really a controversial topic, but the way people actually build charts with these axes is where things go wrong. I have spent years fixing broken plots that were generated by people who understood the theory but had never built a real dashboard under deadline pressure. The most common mistake I see is treating the X axis as a mere formality. It should not be. Before you plot anything, decide what variable belongs on which axis and why. The independent variable — the one you control or that changes on its own schedule — goes on the X axis. The dependent variable — the one you measure in response — goes on the Y axis. This sounds obvious until you look at a scatter plot where someone reversed the two and then wondered why the correlation coefficient made no sense to their manager. I learned this the hard way when I was building a pricing model dashboard for a SaaS company. We tracked monthly recurring revenue against customer acquisition cost across 18 months. I set revenue on the Y axis and CAC on the X axis because that matched the standard regression format we had used for years. Then the finance team asked me to overlay a second Y axis showing gross margin percentage. That decision introduced a scaling disaster. The second axis used a completely different range, and when both were rendered on the same chart, the margin line flattened into an almost invisible strip along the bottom. It took me 40 minutes to realize the issue and another 20 to rebuild the chart using a dual-axis template with properly labeled scale breaks.
Here is what I do now before I even open the charting tool: I write down the variable names, their units, and their approximate ranges on a scrap of paper. If the ranges differ by more than two orders of magnitude, I flag that immediately. It forces me to decide early whether a log scale, a dual axis, or a completely separate panel makes more sense. That three minute step saves me hours of rework later.
How to Build a Functional X Versus Y Axis Chart
Pick your tool. If you are doing this in Excel, use a scatter plot for continuous data and a line chart only when you have a clear time series on the X axis. Google Sheets works similarly but does not give you the same control over secondary axis formatting, which means you will fight it more often. For production work I prefer Python with Matplotlib or Plotly, or R with ggplot2, because they let you override default behaviors without clicking through dialog boxes that hide important options. The steps are straightforward: Step 1: Prepare your dataset with clean column headers. Remove nulls in the axis fields before plotting. Matplotlib will silently drop those rows, and you will not notice until you compare point counts against your source file.
Get the Full Details
Step 2: Set the axis labels with units included. A label that says "Revenue" is insufficient. Write "Monthly Revenue (USD)" or "MRR ($K)". This single habit eliminates about half of the follow-up questions I get from stakeholders. Step 3: Define the axis limits. Do not let the software auto-range your Y axis unless you have verified the auto-range output. Auto-ranges sometimes start above zero even when zero is meaningful to your analysis, which distorts visual perception of the data. Step 4: Add grid lines, but use them sparingly. Light horizontal grid lines help readers track values across the chart. Vertical grid lines are usually unnecessary and create visual noise.
Step 5: Export at 300 DPI minimum if the chart will appear in a report or slide deck. Screenshots of your plotting environment at default resolution look unprofessional and introduce compression artifacts that make fine trends impossible to read.
Common Pitfalls That Nobody Warns You About
One issue that comes up constantly is overlapping data points in scatter plots. When you have thousands of observations, the plot area becomes a solid color blob and the whole purpose of the X versus Y axis layout is defeated. I solved this for a logistics analytics project by adding slight jitter and reducing marker opacity to around 40 percent. That preserved the overall distribution shape while letting individual clusters remain visible. You can also switch to a 2D hexbin plot when the point count exceeds roughly 5000, but that changes the chart type entirely so make sure your audience understands the shift. Another problem is asymmetric axis scaling. Some tools default to asymmetric tick intervals when your data has an uneven distribution. If your X axis has values clustered between 1 and 50 but extends to 500, the lower end will look compressed unless you manually set the tick positions. I use a custom tick locator in Matplotlib for this. In Excel, you have to set the axis bounds manually and then verify the major unit yourself, which is slower but achievable. The biggest trap involves categorical data on the X axis. People often treat nominal categories like a continuous scale and connect them with lines, implying a trend that does not exist. If your X axis represents product categories, regions, or survey responses, use a bar chart or a disconnected scatter layout instead. A line connecting "Electronics" to "Apparel" to "Grocery" is not a trend. It is confusion dressed as insight.

When X Versus Y Axis Charts Fail Completely
There are scenarios where a standard two-axis plot simply cannot work. If you are comparing more than four variables that all need to be shown on the same scale, the chart becomes unreadable regardless of how well you set it up. I worked on a healthcare dashboard once where we needed to track patient wait times, bed turnover, staff ratios, and readmission rates across 24 departments. Putting all four on a single X versus Y axis chart produced a mess that required three separate legends and still left stakeholders unable to draw conclusions. We ended up using a small multiples approach with four coordinated subplots, each sharing the same X axis scale but displaying only one Y variable. It took twice as long to build but cut the average question rate from about 30 per review meeting down to roughly four. Another failure mode is high cardinality on the X axis. If you have 200 unique categories, any standard chart will render overlapping labels or require rotation that makes reading difficult. I have seen people use horizontal bar charts in these cases, which helps, but the real fix is aggregation or filtering. Group the categories into meaningful buckets before plotting, or let the user filter interactively. Static charts cannot solve that problem alone. If you need a downloadable starting point, I keep a basic Python template on my GitHub that handles axis formatting, dual axis setup, and export at 300 DPI. Search for "x-y-axis-template" and you should find it. It uses Plotly for interactivity and Matplotlib as a fallback for static reports. I update it every few months when a new library version breaks something, so check the commit history before assuming it matches your current setup.