How to Actually Use Modern Evolutionary Classification Without Losing Your Mind
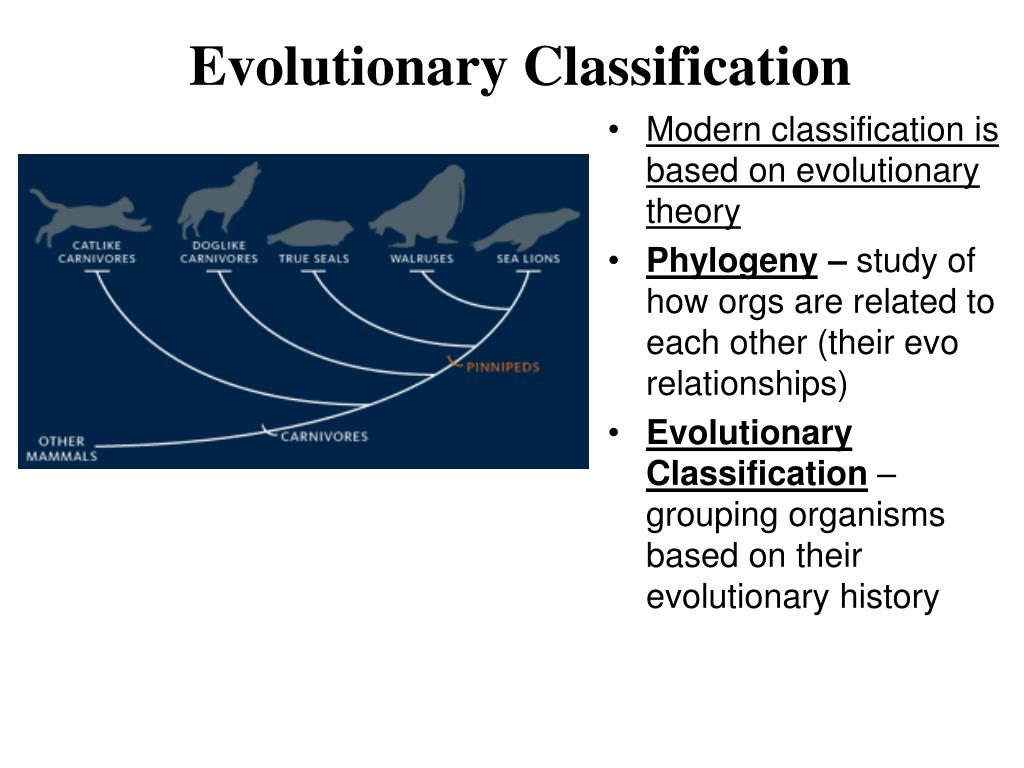
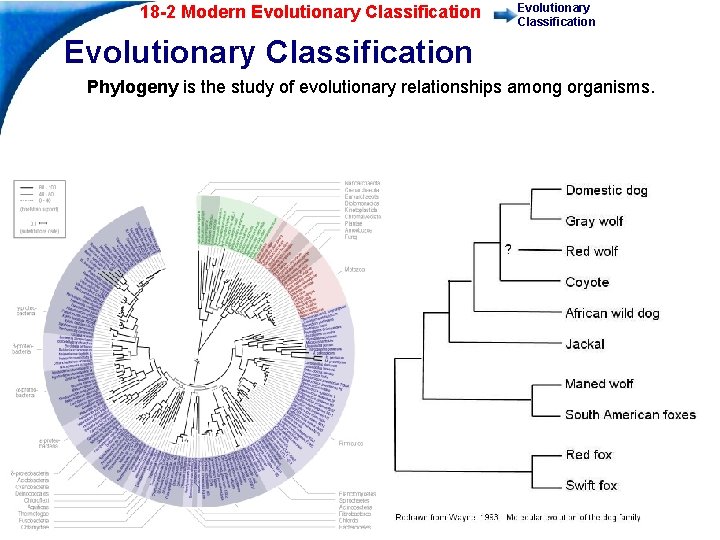
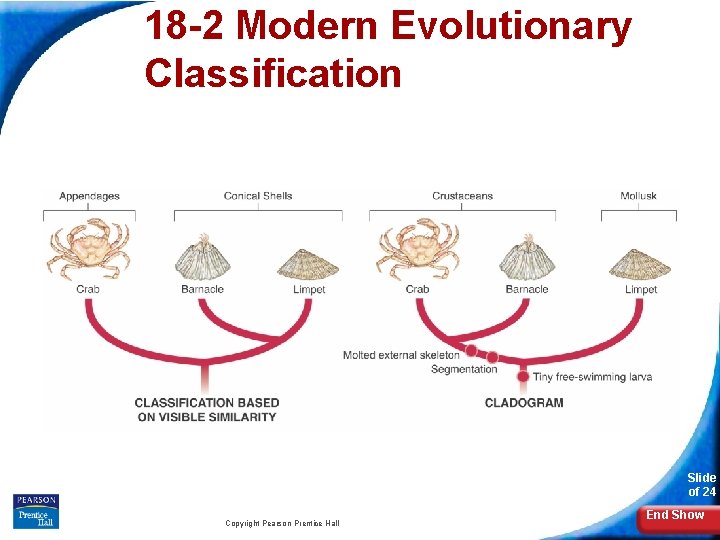
Modern evolutionary classification, sometimes called phylogenetic systematics or cladistics, sorts organisms by shared ancestry rather than just looks. It sounds straightforward until you open a software manual or try to code a character matrix at 2 AM. Here is what actually happens when you try to do this work. The approach breaks down into a few concrete steps. You pick your organisms. You pick the traits or genes you will use. You figure out which traits are ancestral versus derived. You build a matrix. You run it through a tree-building algorithm. You get a cladogram. Most people skip straight to the software and come back later wondering why their tree looks wrong. That skips the part where you decide what the tree is even supposed to show. I spent a semester trying to classify a set of freshwater snail species. On paper they looked similar enough to group together. Their shell shapes overlapped significantly, and the field guides already had them lumped into the same genus. I pulled COI and 16S sequences, ran a maximum likelihood analysis, and the resulting tree split the group into three completely unrelated clades. The shells were convergent adaptations to similar stream environments. Morphology lied. The molecular data did not. That is the first lesson you learn the hard way: physical similarity is not a reliable proxy for relatedness in anything but the most obviously conserved groups.
Cladistics and the Logic of Grouping
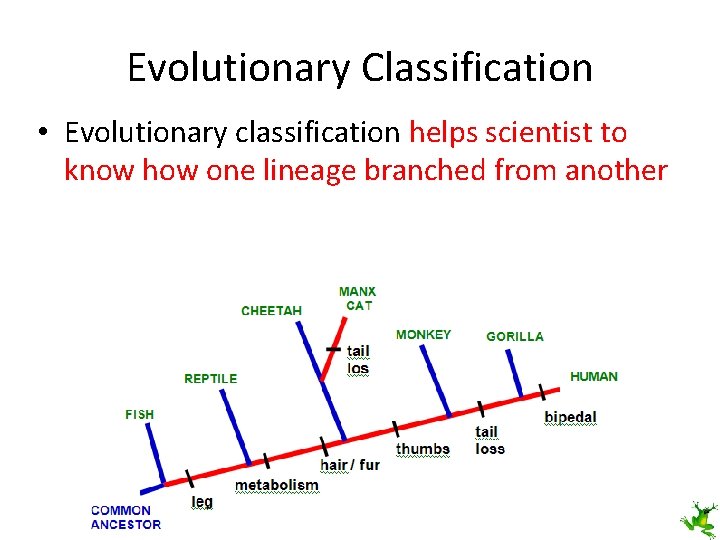
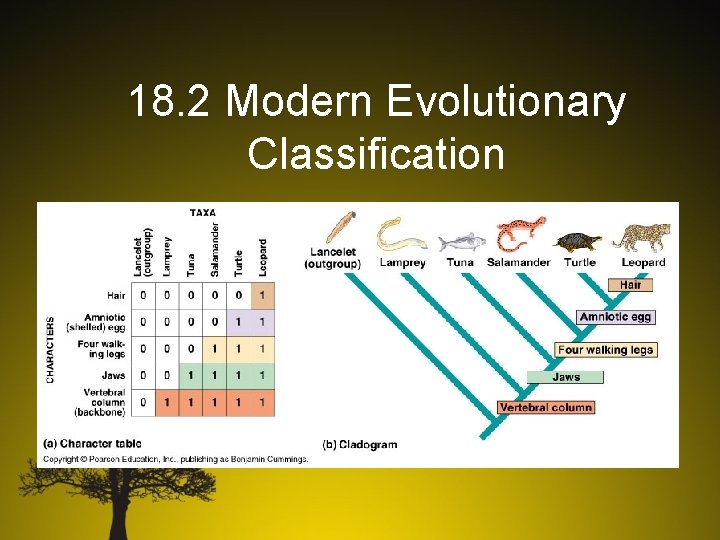
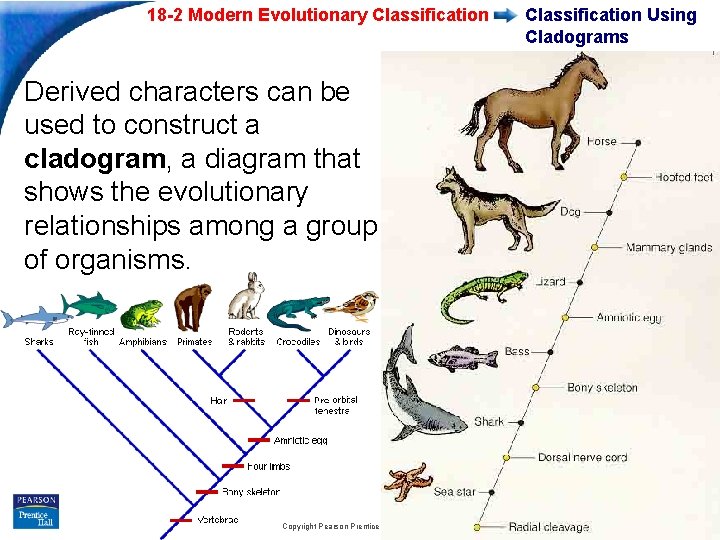
Cladistics groups organisms by shared derived characters, called synapomorphies. A synapomorphy is a trait that arose in the most recent common ancestor of a group and was passed to all its descendants. It is not the same as a symplesiomorphy, which is an ancestral trait shared across a wider range of organisms. Misidentifying these two is the most common mistake beginners make, and it produces trees that look plausible but are structurally wrong. Consider hair. Hair is a synapomorphy for mammals. It tells you that every organism with hair shares a more recent common ancestor with other mammals than with reptiles or birds. But feathers are also a synapomorphy, this time for birds and some dinosaurs. If you accidentally treat feathers as a general vertebrate trait, your tree collapses. The distinction matters because outgroup comparison is how you determine whether a trait is ancestral or derived. You pick a group known to have diverged earlier than your study group and compare trait states. The state found in the outgroup is your baseline for ancestral. Everything else is evaluated against that.
Molecular Systematics Changes the Game
Morphology is fine when you have a good fossil record and well-preserved specimens. It falls apart fast with microorganisms, soft-bodied organisms, or groups where convergent evolution is rampant. Molecular data sidesteps a lot of those problems. You sequence genes, align the sequences, and let the nucleotide differences do the sorting. The standard workhorse genes vary depending on your timescale. For deep divergences, ribosomal RNA genes like 18S and 28S are useful because they change slowly and retain signal across hundreds of millions of years. For recent splits, mitochondrial genes like COI and cytochrome b evolve fast enough to resolve population-level differences. Nuclear protein-coding genes sit somewhere in between. Choosing the wrong gene for your question is a bottleneck I see repeatedly. Someone trying to resolve species-level relationships in a genus of moths will pull 18S rRNA and get a bush with zero resolution. The gene simply does not accumulate substitutions fast enough over that timeframe. I once worked with a dataset of amphibian species where the published trees disagreed wildly. One study using morphological characters grouped two genera together. Another using mitochondrial DNA separated them. A third combining both datasets placed them in entirely different families. The resolution came from adding nuclear intron data, which provided intermediate substitution rates and broke the ambiguity. No single gene told the full story. That is a practical reality you need to accept: single-gene phylogenies are often insufficient for contentious nodes.
Get the Full Details
Building the Tree
There are several methods for tree construction, and each has assumptions you need to understand before you run the analysis. Maximum parsimony finds the tree requiring the fewest evolutionary changes. It is intuitive and fast for small datasets. It breaks down when there is high homoplasy, meaning traits evolve independently in different lineages. That is a lot of homoplasy in morphological data. You will see it in groups like cacti and euphorbias, which evolved nearly identical succulent forms independently on different continents. Parsimony will happily group them together if you are not careful. Maximum likelihood uses a model of sequence evolution and finds the tree that makes your observed data most probable under that model. It is computationally heavier but far more robust to homoplasy and varying substitution rates. The catch is that model selection matters. Using an overly simple substitution model on complex data can produce misleading support values. I learned this the hard way when a neighbor-joining tree with a Jukes-Cantor model gave 95 percent bootstrap support for a relationship that maximum likelihood under GTR+G+I pushed down to 42 percent. The simpler model was overconfident because it did not account for rate heterogeneity across sites.
Bayesian inference adds prior probabilities to the mix and produces posterior probabilities for each node. It is computationally intensive but handles uncertainty better than either parsimony or likelihood alone. The main practical issue is that setting inappropriate priors can bias results. If you have no reason to believe one tree topology is more likely than another, an uninformative prior is the safe default. Informative priors should come from genuinely independent evidence, not from hoping they will make your tree look prettier.
Outgroups and Rooting
An unrooted tree shows relationships without indicating direction. Rooting places the common ancestor at a specific point and gives the tree temporal meaning. The outgroup is how you do this. It should be closely related enough to align properly with your ingroup but clearly outside it. Pick an outgroup that is too distant and your alignment falls apart. Pick one that is too close and it may nest within your ingroup anyway, defeating the purpose. I once used a distant relative as an outgroup for a plant phylogeny and ended up with an unrooted mess because the sequences were too divergent to align confidently. Switching to a closer outgroup resolved the root and shifted the entire topology by two nodes. That is a subtle point: the choice of outgroup can change your conclusions, not just orientation. Always test multiple outgroups if possible and report which one you used.
Software and Practical Workflow
The actual workflow usually looks like this: sequence your targets, trim and align, check the alignment by eye for obvious errors, select a substitution model, run the analysis, and assess support. Tools like MAFFT or MUSCLE handle alignment. ModelTest or jModelTest picks the best substitution model. RAxML, IQ-TREE, or MrBayes run the tree inference. FigTree or iTOL visualizes the result. The step everyone rushes is checking the alignment. I have seen people feed misaligned sequences into RAxML and get clean-looking trees with nonsensical topologies. A single indel placed wrong can shift every downstream character state. Take ten minutes to visually inspect the alignment around indels and highly variable regions. It saves hours of debugging later.
Common Pitfalls
Long-branch attraction is the classic problem. Fast-evolving lineages accumulate many changes independently, and the algorithm may group them together not because they are closely related but because they both look different from everything else. This happens frequently with parasitic organisms or organisms with unusually high mutation rates. Methods that account for rate variation, like gamma-distributed rates in maximum likelihood, help reduce this effect. Adding more taxa that break up long branches is the most reliable fix. Another issue is incomplete lineage sorting. When speciation events happen in rapid succession, gene trees can differ from species trees because ancestral polymorphisms persist across speciation boundaries. This is especially problematic in rapid radiations like cichlid fishes or Darwin's finches. Single-gene analyses will give you conflicting topologies. Coalescent-based methods that model gene tree discordance are the proper solution, but they require more data and more computational effort. Hybridization and horizontal gene transfer also complicate things. In plants, hybridization is common and creates networks rather than simple bifurcating trees. In bacteria and archaea, horizontal gene transfer means any single gene tree is just one history among many. Neither situation fits neatly into the cladistic framework. You need network-based approaches or multi-locus coalescent models instead of a single concatenated alignment.
When Modern Classification Fails
The method is not universal. It struggles with extinct groups where only morphological data exists. It struggles with organisms where sexual reproduction and recombination blur species boundaries. It struggles when your sampling is sparse, leaving long branches unbroken. And it struggles when the signal in your data is simply weak, which happens with very recent radiations or very ancient divergences where multiple substitutions have overwritten the original signal. In those cases, adding more loci helps but does not always solve the problem. Sometimes the best you can do is report the uncertainty and avoid overinterpreting poorly supported nodes. Bootstrap values below 70 percent and posterior probabilities below 0.95 are usually not worth building conclusions on. A tree with mostly weak support is still a tree, but it is a thin reed to hang taxonomic revisions on.
A Note on Terminology and Communication
Phylogenetic classification does not always align with traditional Linnaean ranks. Clades do not respect classes or orders. This creates friction when you try to publish or communicate results to people who expect hierarchy. A clade-based system is more honest about relationships but harder to map onto existing names. You will encounter resistance from taxonomists who prefer familiar groupings. That is a professional and political problem, not a technical one. The science does not care about your comfort with the classification system you inherit. My advice is to build the tree first, label the clades clearly, and only then consider whether existing names fit. Forcing old names onto new clades creates more confusion than it resolves. Define your clades with node-based or stem-based definitions from the start. It makes the paper cleaner and the revisions easier later.