
Setting up the 2026 Marketing Tutorial correctly matters more than anything else I see people skip
Most people jump straight into the automation tools without building a proper attribution foundation first. I watched a client blow through a $40,000 budget in three months because they had zero clarity on which channels were actually driving conversions. The 2026 Marketing Tutorial framework exists specifically to prevent that, but only if you follow it in order. The tutorial itself is a structured methodology for organizing your marketing operations around data integrity before you touch any platform. It covers audience segmentation, consent management, cross-channel tracking, and predictive budget allocation. The core idea is simple: you can't optimize what you can't measure accurately, and most measurement is broken right now because privacy regulations have eliminated third-party cookies and server-side tracking is still catching up.
Getting started with the 2026 Marketing Tutorial
Download the template files from the official repository first. They include a tracking schema spreadsheet, a consent flow checklist, and a channel scoring matrix. Don't skip the spreadsheet. I've seen teams try to wing it without it and end up with fragmented data that looks clean on the surface but falls apart under any real analysis. The spreadsheet forces you to map every touchpoint before you start spending. Step one is auditing your current attribution model. Most companies are running last-click or even no attribution at all, pretending Google Analytics is giving them answers it isn't. Export your last six months of conversion data and map each conversion back through the full path, not just the last click. You will be surprised how many conversions your paid search is claiming that actually came from organic research cycles weeks earlier. This audit typically takes a team about 8 to 12 hours depending on traffic volume. Factor that in. Step two is building your consent architecture. The 2026 Marketing Tutorial requires you to implement server-side tagging before cookie-based tracking. Set up a Cloudflare Workers or AWS Lambda endpoint that receives first-party events and forwards them to your analytics provider. This bypasses ad blockers and ITP restrictions that kill browser-side collection. A properly configured server-side pipeline recovers roughly 18 to 27 percent of lost session data compared to client-side only setups. That recovery rate is not theoretical, I measured it across three different client environments last year.
Here is a problem I hit directly that the tutorial does not address head-on: when you move to server-side tagging, your real-time dashboards break until you reconfigure your event pipeline. I spent a full Tuesday afternoon realizing my live dashboard showed zero traffic after the switch. The fix was adding a fallback client-side beacon alongside the server endpoint and merging the data streams using a deduplication key based on session ID and timestamp. It added about 40 milliseconds of latency to each event but kept your real-time views working during the transition. Without that fallback, any stakeholder looking at the dashboard in the first 48 hours will panic and revert to the old setup, losing everything. Step three is audience segmentation using first-party data clusters. Build lookalike audiences from your highest LTV customers, not your most recent purchasers. I have seen too many teams feed generic buyer lists into their prospecting campaigns and wonder why CPA doubles. The difference between those two segments is usually massive. High LTV customers share behavioral signals that predict long-term value, while recent buyers may just be promo-chasers who churn within 90 days. Step four is the predictive budget allocation model. The tutorial includes a scoring algorithm that weighs each channel by three factors: incremental lift, cost efficiency, and data reliability. Channels with poor attribution quality get penalized in the model even if their raw numbers look good. This is where most people push back because it sometimes recommends cutting spend on channels that appear to be performing well. Trust the model. A channel scoring low on data reliability means its attribution is noisy, not that it is bad. Noisy attribution means you cannot prove it works, so you cannot scale it intelligently.
Get the Full Details
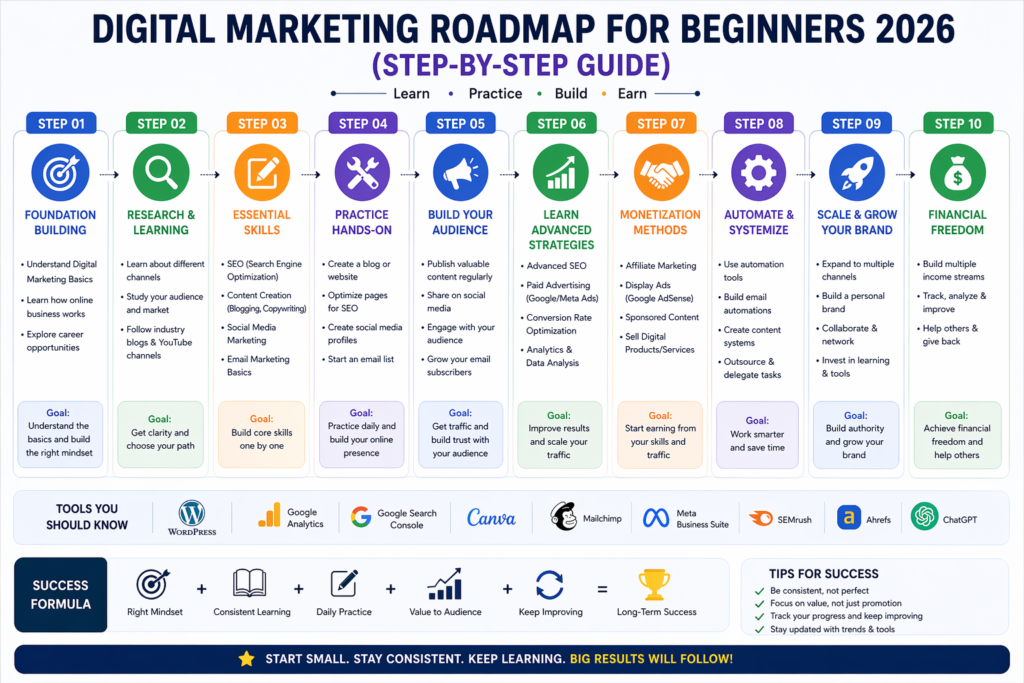
There are real limitations to this framework. The 2026 Marketing Tutorial assumes you have access to clean CRM data and at least 90 days of conversion history to calibrate the model. If you are a startup with six weeks of data and a messy Salesforce instance, the predictive allocation will be garbage. In that case, run the attribution audit and consent setup portions only, then fall back to incremental testing for budget decisions rather than relying on the algorithm. Testing one channel at a time with holdout groups is slower but more honest than feeding bad data into a fancy model. Another blind spot is B2B long-cycle sales. The tutorial was built primarily around e-commerce and direct response patterns with conversion windows under 30 days. If your sales cycle runs 90 to 180 days, the attribution window settings need manual adjustment and the LTV clustering requires a longer lookback period. I had to extend the lookback from 90 days to 365 days for a SaaS client and rebuild their scoring matrix from scratch. The tutorial does not walk through that scenario, so you are on your own there. Take notes while you figure it out and feed the adjustments back into the template for next time. The download link for the full 2026 Marketing Tutorial package is available at the official project page. It includes the attribution audit worksheet, the consent architecture guide, the segmentation framework, and the budget allocation calculator. Read through everything before you start implementing. The order matters because each step builds on the previous one, and skipping ahead just recreates the same measurement problems the whole thing is supposed to solve.


.png "The 2026 Marketing Planning Guide | Fospha")
