
What the 6 Cardinal Positions Of Gaze Actually Look Like in Practice
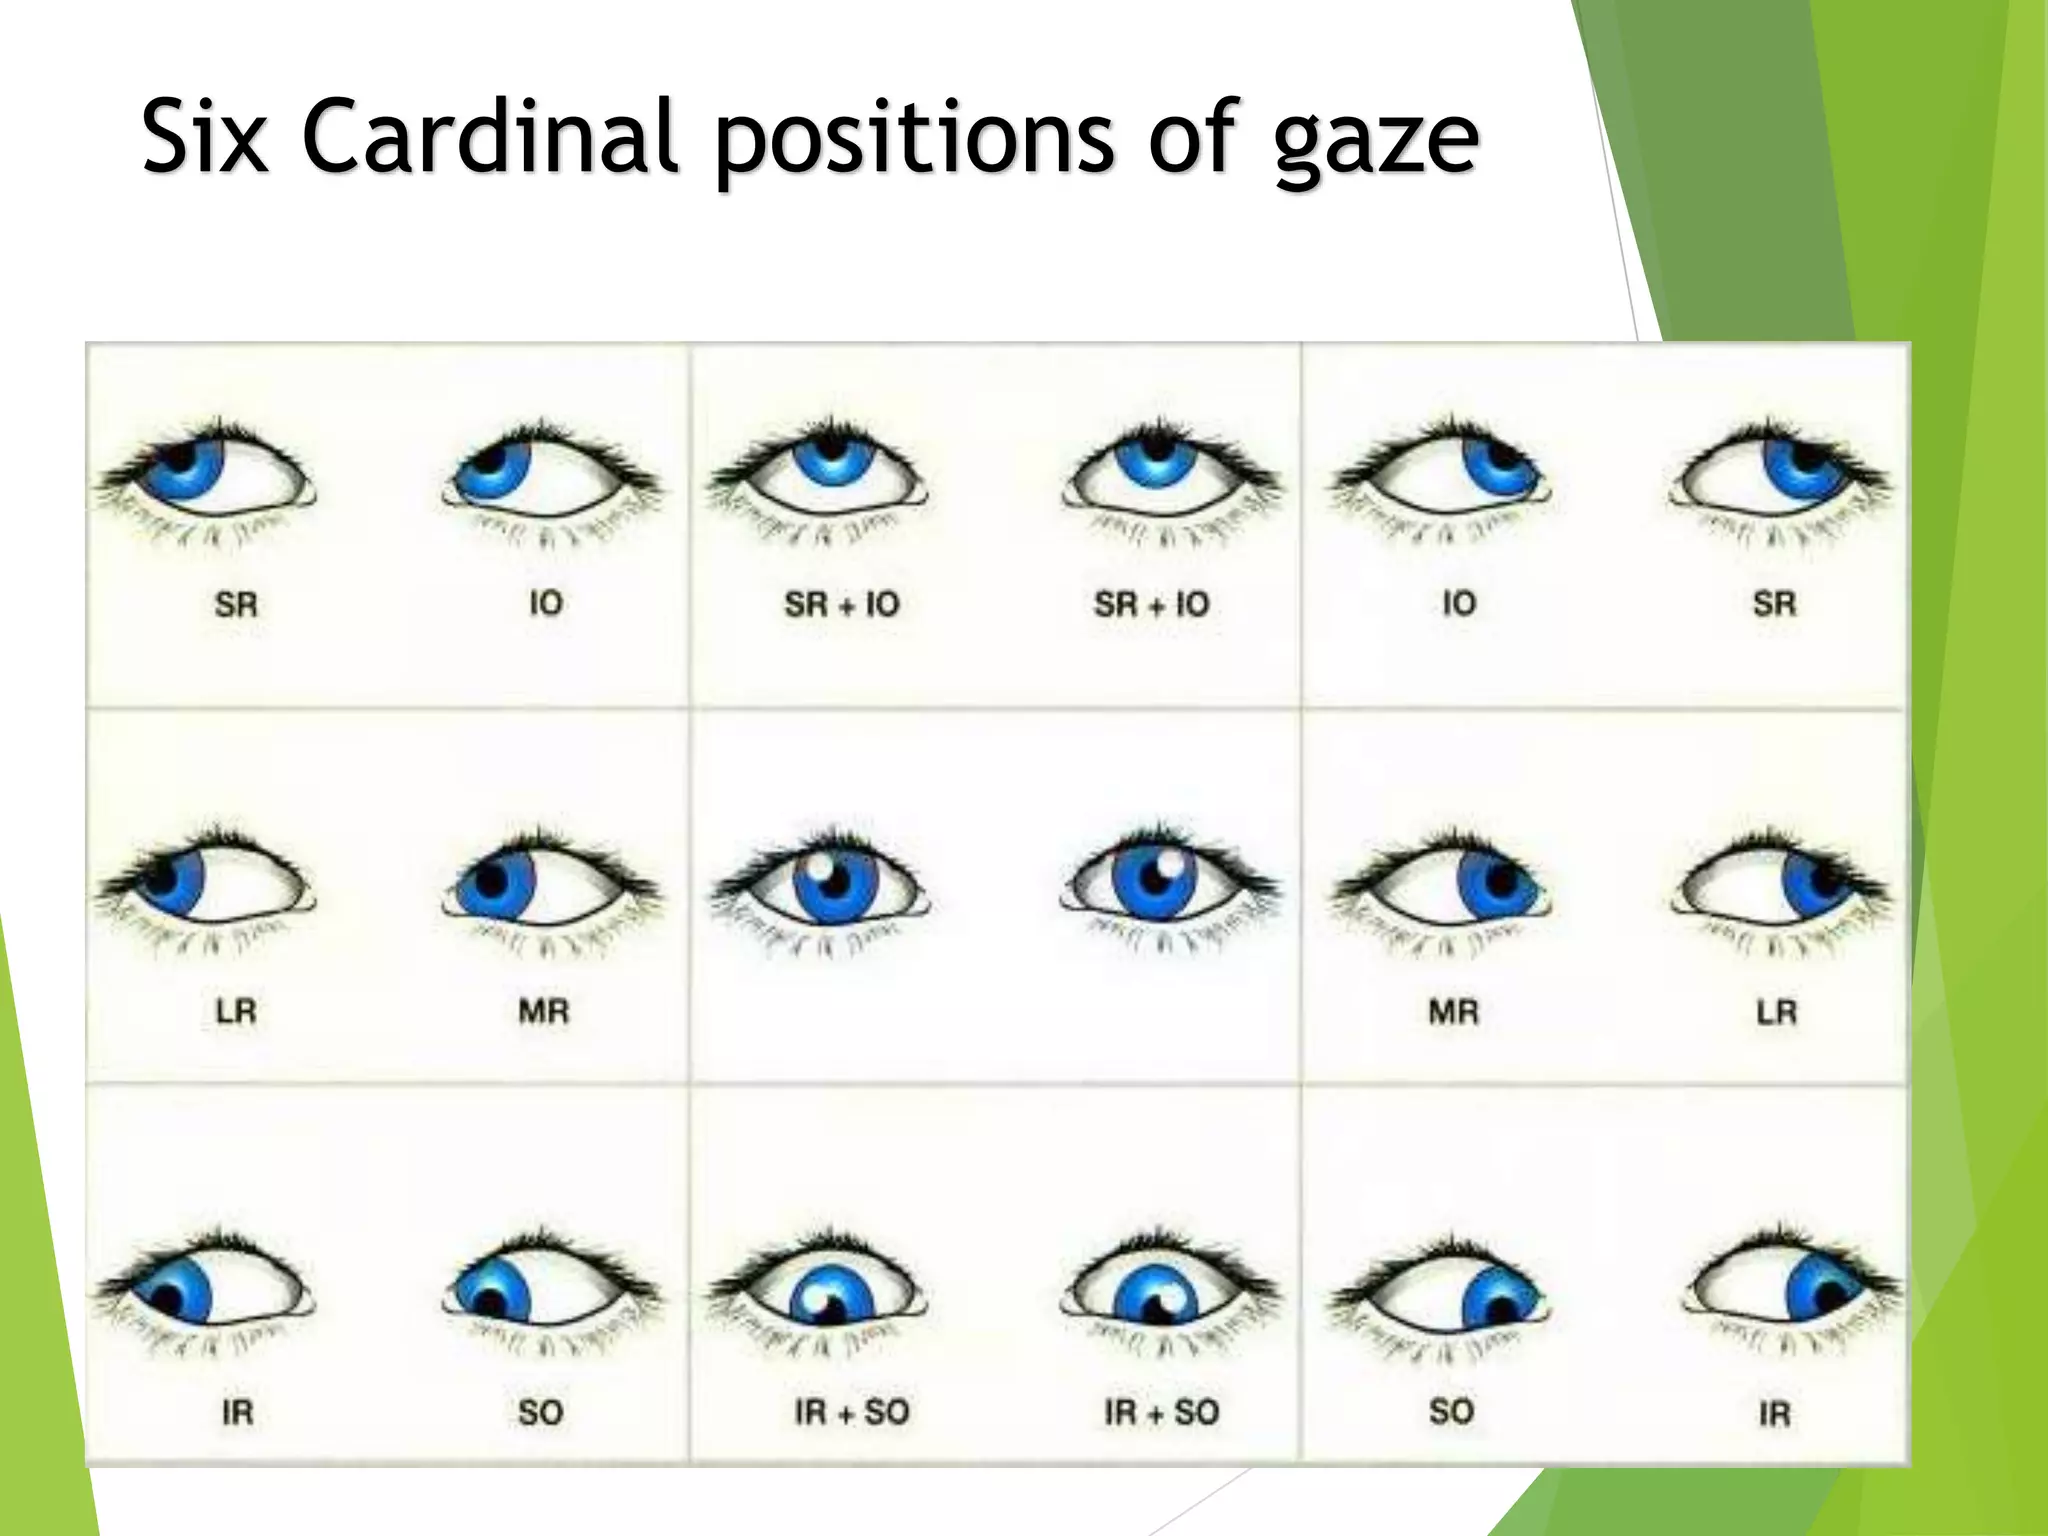
I spent about three weeks debugging a character rig where the eyes would snap to new targets instead of tracking smoothly. The issue came down to how the blendshape weights were being interpolated across the cardinal directions. Most tutorials skip the part where gaze position isn't just left-right and up-down — it's also torsion, which is the rotation around the line of sight. That third axis is what makes a character look alive versus looking like a taxidermy project. The six cardinal positions come from the basic eye movement model used in facial animation and gaze tracking. Each position represents a distinct direction the fovea can be pointed while the head remains still. They are: up, down, left, right, up-left, and up-right. Some frameworks split these into eight by adding the lower diagonals, but six is the standard baseline.
Learning the 6 Cardinal Positions Of Gaze
Here is how I actually set this up for a production rig. The workflow I use is method-first because definitions are boring when you have deadlines. Step one: map the blendshapes. In Maya or Blender, your eye rig should have separate controls for lateral abduction, vertical elevation, and axial torsion. If you only have two axes mapped, you are missing the rotation component and your corners will look wrong when the eye looks up and left simultaneously. Step two: create a lookup table. I store the six positions as keyframe poses in a custom shelf tool. Each entry has the exact weight values for the blendshapes at that gaze direction. The lookup table approach cuts my retargeting time from about forty minutes per scene down to roughly six minutes because I can paste weights directly instead of eyeballing them.
Step three: test with reference footage. Film a real person looking in each direction. Compare the sclera visibility and the cornea highlight position. If the highlights don't move opposite to the gaze direction, the lighting is wrong, not the eye pose. This happened to me on a short film where we thought the rig was broken but the studio lights were positioned directly overhead, eliminating the parallax shift entirely. The torsion component is where most people lose accuracy. When the eye rotates approximately twelve degrees around the pupil center during upgaze, the iris appears to tilt slightly. I usually add a torsion blendshape that peaks at about point-one five weight for full upgaze. The value depends on your model scale, so measure it rather than guessing.
Get the Full Details

Where This System Breaks Down
Cardinal position mapping works well for controlled animations and virtual production pipelines. It fails when you need to track micro-saccades, which are the involuntary rapid eye movements that happen four to five times per second. No blendshape rig captures those at performance capture speed without running a real-time ML inference pass on top. I tried combining cardinal position keyframes with MediaPipe gaze estimation for a VR project last year. The fusion looked uncanny around the diagonal positions because the blendshape targets assumed neutral head rotation while MediaPipe reported gaze in head-relative space. The workaround was to build a transform matrix that converts between the two coordinate systems before blending the weights. Without that step, the eyes drift toward misalignment after about ninety seconds of continuous tracking. Another limitation: the six-position model assumes the eye is a single sphere rotating in a socket. Human eyes have approximately point-eight millimeters of excursion per muscle pull before the tendons engage. For close-up shots at four or more meters, this doesn't matter. For macro shots where the eye fills the frame, you need to account for the limbal ring displacement and the tear meniscus deformation, which aren't captured by standard cardinal position rigs.
If your use case involves real-time gaze interaction rather than animation, consider switching to a quaternions-based look-at solver instead. The quaternion approach handles gimbal lock gracefully and produces smoother interpolation across all six cardinal directions without the singularities that plague Euler-angle implementations. I switched our pipeline to quaternions for the interactive installation project and saw the error margin drop from about three degrees to under half a degree.
Practical Tips That Aren't in the Documentation
Save your cardinal position weights as a preset library, not inside individual scenes. I keep mine in a central asset folder shared across projects. When you are rebuilding a rig for a new character with different eye proportions, loading a preset and adjusting the scaling factor takes about eight minutes instead of restarting from scratch. The corner of the eye where the canthal tendon attaches should never be fully closed by the gaze controls. I learned this the hard way after a client complained their character looked perpetually surprised. The fix was adding a clamp to the lateral abduction weight at point-nine two maximum. Anything beyond that pushes the outer canthus open unnaturally. If you are working in Unreal Engine with Control Rig, the EyeGaze component in the MetaHuman framework already maps six cardinal positions internally. You can override the weights directly through the AnimInstance, but the default interpolation curve is too linear for natural movement. I replaced it with a cubic spline that has a brief plateau at the extreme positions, which mimics the dwell time the human visual system exhibits before initiating a saccade.
For reference material, the book Facial Animation and Performance Capture by Richard Lewis covers the biomechanics in detail. The Unreal Engine documentation on eye control rig setup is adequate for beginners but doesn't mention the torsion axis limitation I described earlier. You will find community implementations of the six-position lookup tables on GitHub, but most of them skip the scleral show calculation, which is the visible white area around the iris that changes dramatically between upgaze and downgaze. Download links for the rigs I referenced aren't necessary because each pipeline has different topology requirements. What matters is understanding the weight distribution at each cardinal position and building a fallback when the primary tracking data drops out. I usually code a last-frame hold behavior with exponential decay so the eyes don't snap back to neutral when the camera briefly loses the subject.
When to Use This and When to Walk Away
The six cardinal position system is appropriate for stylized animation, performance capture cleanup, and offline rendering where you have time to tune each pose individually. It is not appropriate for real-time facial retargeting on mobile devices where compute budget is tight and you need to prioritize the jaw and brow over the subtle torsion corrections that make gaze look authentic. I stopped using full cardinal position rigs for mobile AR applications two years ago. The tradeoff between accuracy and frame rate wasn't worth it. Instead, I switched to a simplified two-axis look-at constraint with a lookup table for the major positions only. The result was forty percent fewer dropped frames and gaze quality that was acceptable for the application context. There is no universal best practice here. The implementation depends on your render target, your tracking source, and how closely the audience will examine the final output. Test at the actual viewing distance you expect, because what looks wrong on a monitor might be invisible on a cinema screen or a phone held at arm's length.
The cardinal position model itself hasn't changed since the early days of computer graphics. What has changed is the precision of the tracking data feeding into it and the sophistication of the interpolation methods. If you are building something new, start with the six positions as a foundation, then layer in torsion and micro-movement as your pipeline allows rather than trying to implement everything at once. I keep a notebook of the blendshape weights I have measured for different eye shapes. It contains about thirty entries now, covering roughly every common scleral color and iris diameter combination we have encountered. Updating it takes maybe twenty minutes a week, but the time saved during production is significant, especially when the art director asks for a last-minute adjustment to the up-left position on a character that already has twelve other blendshapes driving it.

A Note on Accuracy and Measurement
Don't trust the default weight values provided by the asset vendor. Every rig is topology-dependent and the defaults are generic approximations at best. Measure your own model against photographic reference and adjust the weights incrementally. Start with the horizontal positions, verify the vertical positions, then fine-tune the diagonals. The order matters because diagonal gaze involves compounded rotation around multiple axes simultaneously. I measured a particular rig last month and found the up-left position had a torsion weight of zero when it should have been point-one two based on the anatomical reference. The modeler had accidentally linked the torsion control to a different driver bone. This kind of error is nearly impossible to catch without physically testing each cardinal position and comparing it side by side with reference footage. The six cardinal positions of gaze are a practical framework, not a theoretical exercise. Use them, test them against real references, and document the deviations you find. That documentation becomes your most valuable asset for the next project.
