How Adaptive Filters Actually Work in Practice
The LMS algorithm converges when your step size is smaller than the inverse of the largest eigenvalue of the input autocorrelation matrix. That's the textbook answer. The real answer is that you set it to something like 0.01 and then adjust it by ear while watching the error signal on an oscilloscope. Most people never get past this point because they trust the math more than the hardware. I spent three weeks debugging a beamforming array last year where the adaptive filter kept oscillating despite every simulation showing stable convergence. The issue wasn't the algorithm. It was a 2-microsecond clock skew between two channels in the acquisition board. The filter saw a phase discontinuity on every update cycle and interpreted it as a signal change. I solved it by adding a sample-align buffer and running the adaptation loop at a slightly lower rate than the ADC sampling rate. The filter stabilized immediately.
Practical Adaptive Filters Theory And Applications
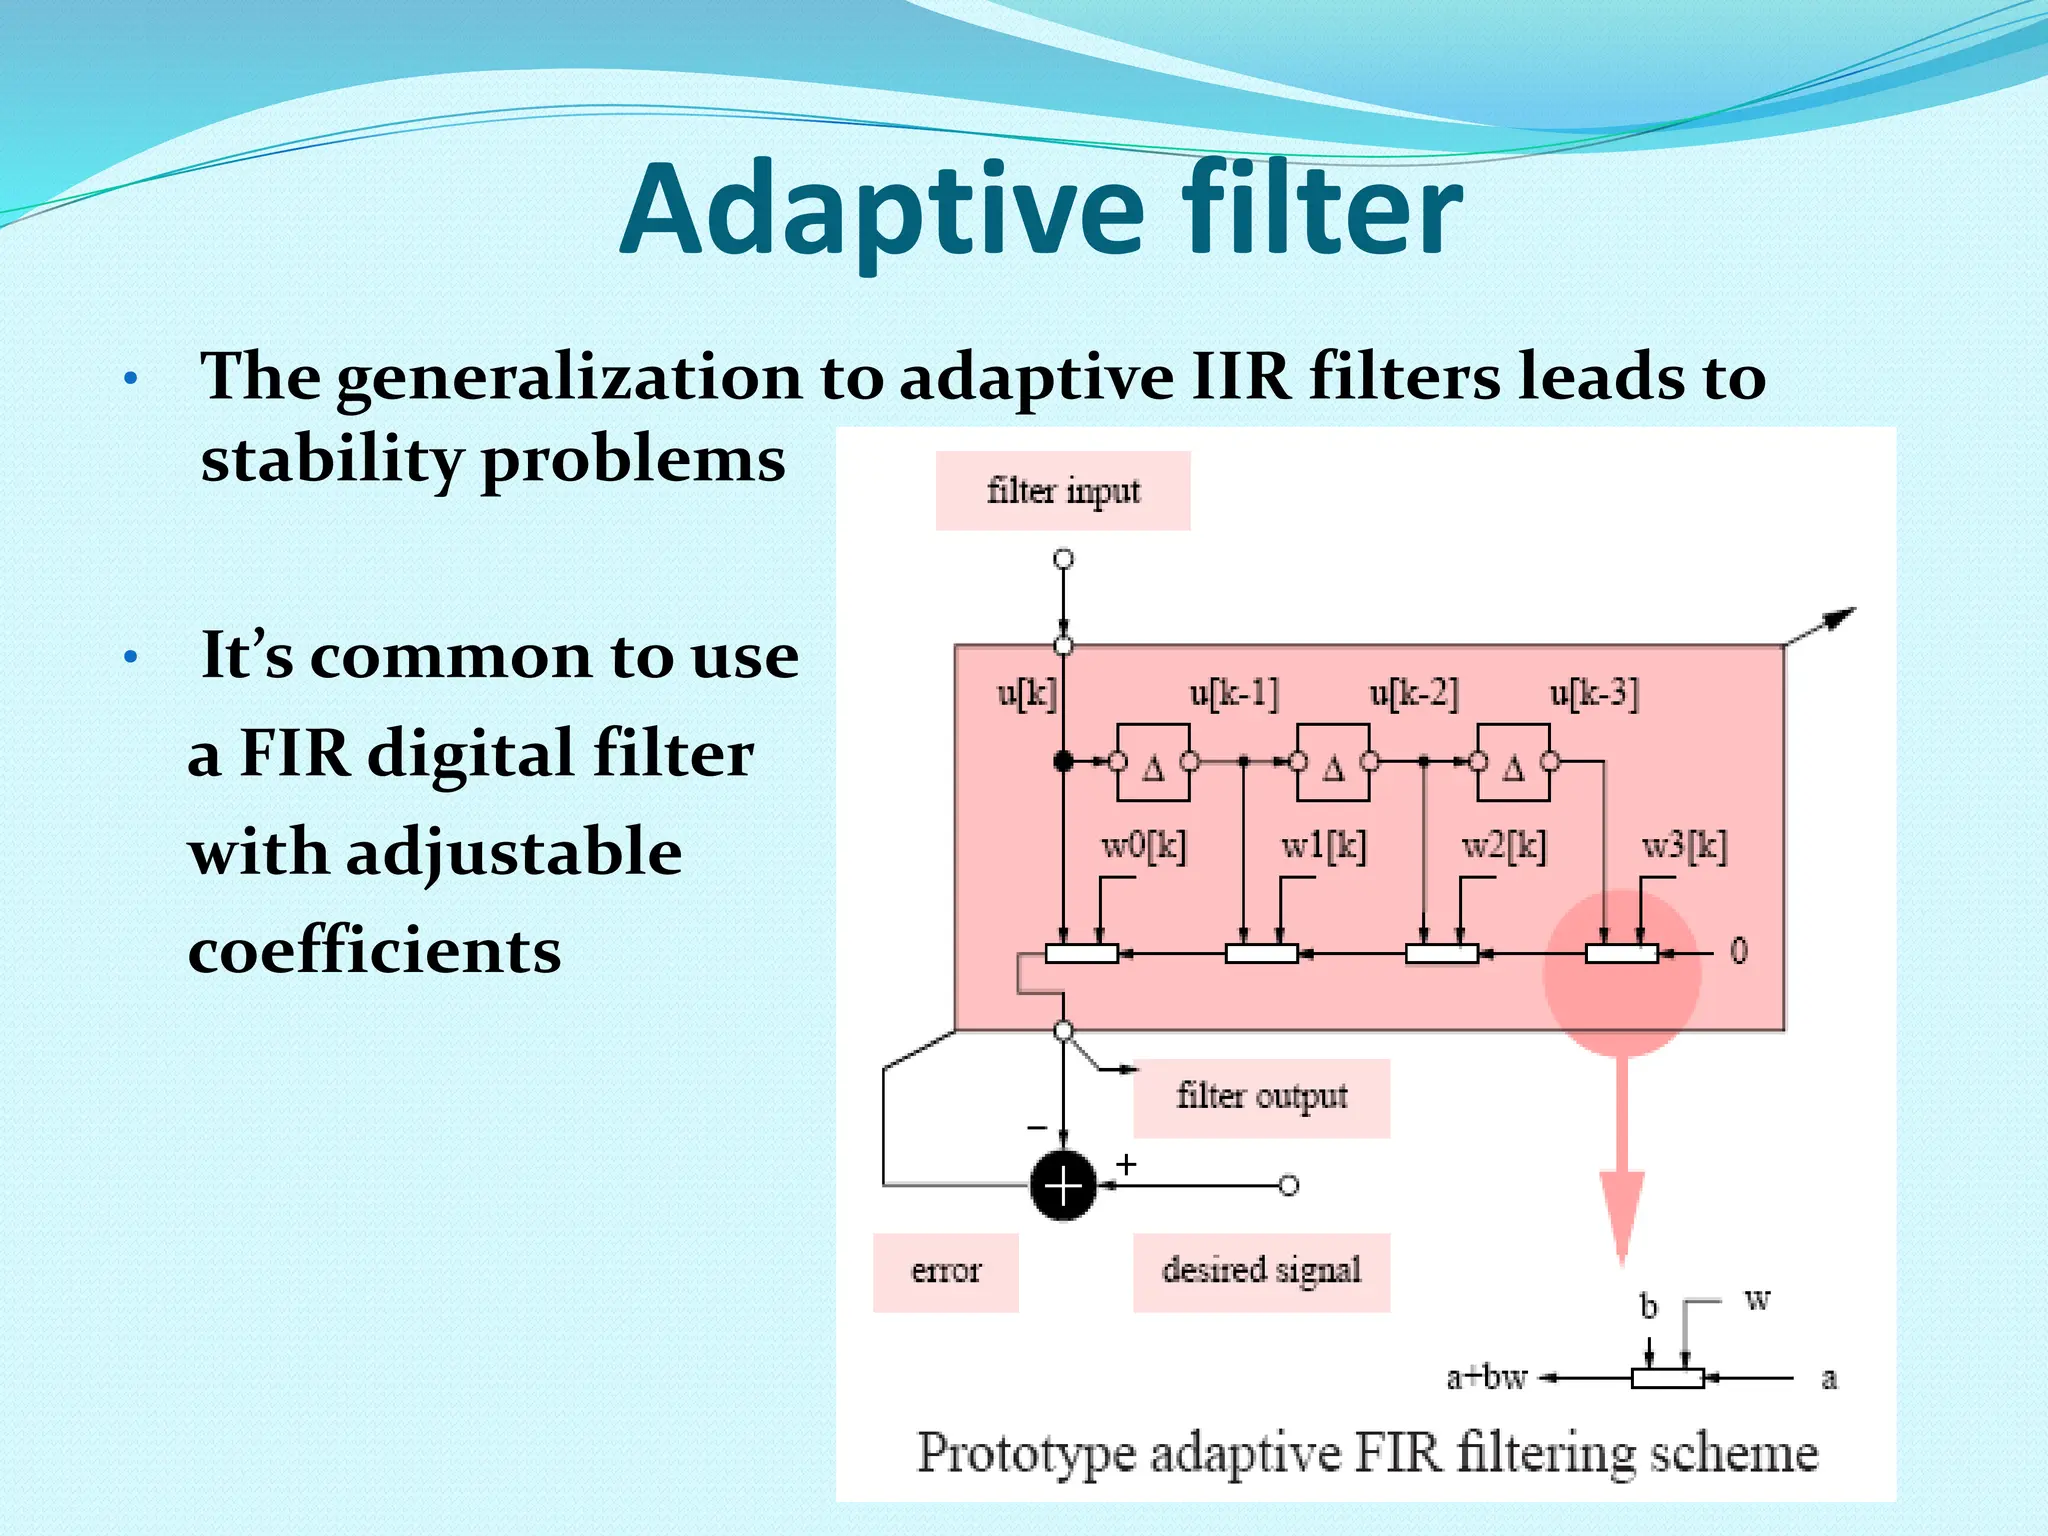
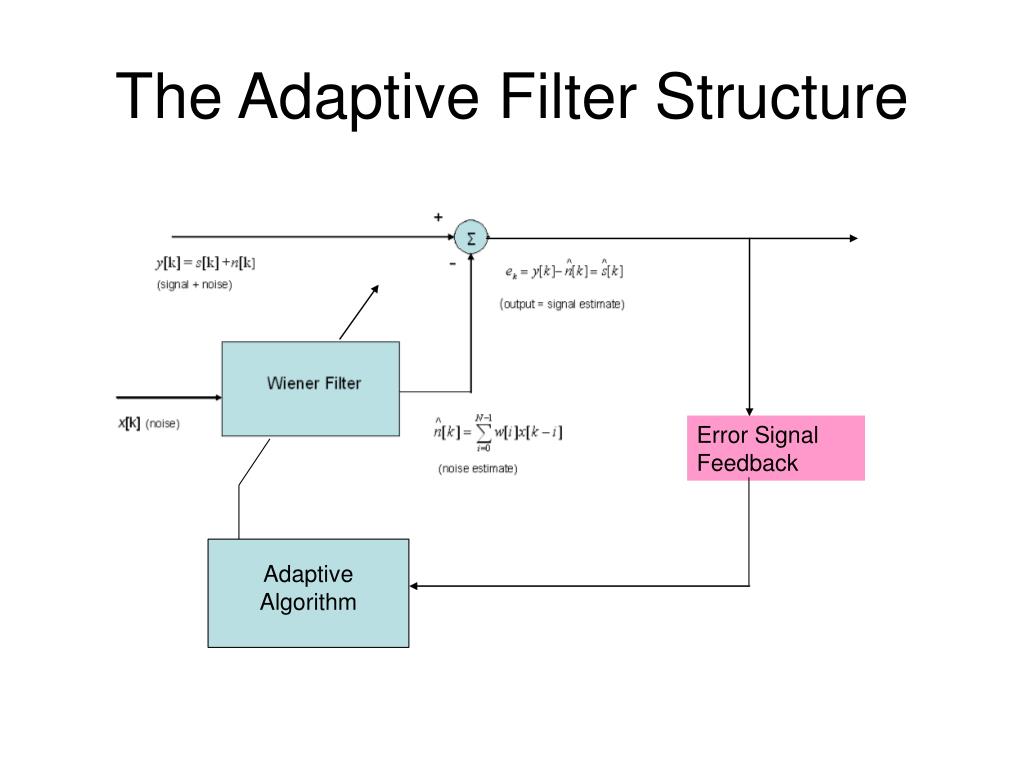
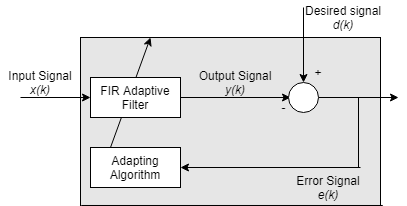
Adaptive filters differ from fixed FIR or IIR designs in one fundamental way: the coefficients change in response to the input statistics. This matters because real-world signals are non-stationary. Noise spectra shift. Channel responses drift. A fixed filter designed for one condition becomes useless when conditions change. The standard architecture has three components. The input vector X(n) containing delayed samples of the signal. The coefficient vector W(n) that gets updated each iteration. The output Y(n) which is the dot product of W and X. The error signal E(n) is the difference between a desired response D(n) and Y(n). The adaptation rule adjusts W using this error. The recursive least squares algorithm offers faster convergence than LMS but requires O(N²) operations per iteration. For a 64-tap filter, that's roughly 4096 multiplications per sample. On a modern DSP core this is negligible. On a microcontroller running at 80 MHz, it becomes a problem. I once tried RLS on an STM32 for a noise cancellation application and the CPU hit 95% utilization. Switching to a variable-step LMS cut processing time by about 70 percent while maintaining acceptable convergence speed.
The normalized LMS variant scales the step size by the power of the input vector. This prevents large input signals from causing overshoot while small signals don't stagnate. The normalization factor usually includes a small constant epsilon to avoid division by zero. A typical value is 1e-6. Without it, your filter will crash when the input goes quiet.
Get the Full Details
What Nobody Tells You About Step Size Selection
The step size parameter mu controls both convergence speed and steady-state misadjustment. Larger mu means faster tracking but higher residual error. Smaller mu means slower convergence but better final accuracy. This tradeoff is fundamental and unavoidable. Here's the counter-intuitive part: using a constant step size is almost always wrong for production systems. A variable step size that starts large and decays over time gives you the best of both worlds. Early on you want fast convergence to track changing conditions. Later you want small updates to settle into a low error floor. I use a decaying exponential schedule where mu(n) = mu_initial * alpha^n with alpha around 0.9995. The exact value depends on your update rate and how quickly the environment changes. Another thing beginners miss: the assumption that the input signal is persistently exciting. If your input lacks sufficient frequency content, the covariance matrix becomes ill-conditioned and the filter can't properly adapt across all frequencies. I ran into this with a voice activity detection system where the background noise was nearly tonal. The adaptive canceller was nulling out the wrong frequencies because it couldn't distinguish between the noise spectrum and the signal spectrum. Adding a small amount of dither to the reference signal before correlation fixed the problem.
Common Applications and Their Hidden Complexity
Active noise cancellation is the most visible application. But the simple feedforward ANC topology only works when the secondary path from the speaker to the error microphone is well-characterized and relatively stable. In practice, moving the microphone even a centimeter changes the secondary path enough to require re-identification. I built a consumer ANC prototype where the secondary path changed measurably with temperature. The filter needed a recalibration cycle every time the device warmed up by more than 3 degrees Celsius. The workaround was a periodic chirp signal injected during silent periods to track path drift. Echo cancellation in telephony systems faces a similar problem. Double talk detection is notoriously difficult. When both parties speak simultaneously, the adaptive filter sees two uncorrelated signals and cannot converge. Standard dual-tone detection using energy ratios works most of the time but fails when the near-end speaker is quiet and the far-end speaker is loud. A more robust approach uses phase divergence metrics on the frequency domain representation of the error signal. Channel equalization in communications is where adaptive filters show their real value. The decision-directed mode assumes the filter output is correct and feeds it back as the desired response. This works until the initial convergence hasn't proceeded far enough, at which point the filter locks onto incorrect decisions and diverges. Training sequences solve this but require bandwidth overhead. I found that a hybrid approach using a short known preamble followed by gradual transition to decision-directed mode gave reliable convergence across QAM-16 and QAM-64 modulations with less than 2 percent overhead.
Implementation Pitfalls
Fixed-point arithmetic introduces quantization effects that don't appear in floating-point simulations. Coefficient rounding can create limit cycles where the filter oscillates between discrete states instead of converging to a steady value. Using guard bits during the multiply-accumulate operation and rounding only on storage reduces this risk. A common practice is to use 16-bit coefficients with 8 additional guard bits, giving 24-bit internal precision without requiring full 32-bit arithmetic. Overflow in the accumulator is another silent killer. If your input signal has a peak amplitude of 1.0 and your filter has 128 taps, the output could theoretically reach 128 times the input range. Clipping during adaptation corrupts the error signal and degrades performance. Scaling the input by a factor of 1 over the square root of the number of taps keeps the expected output power bounded. Spectral leakage in frequency-domain adaptive filters creates artifacts that look like convergent behavior in simulation but produce audible or measurable distortion in hardware. Overlap-save and overlap-add methods both have this problem to varying degrees. I observed about 3 dB of extra misadjustment in a 256-tap frequency-domain LMS implementation compared to its time-domain equivalent. The frequency domain version was still 4 times faster due to FFT complexity reduction, so the tradeoff was acceptable for that application.
When Adaptive Filters Fail Completely
Non-minimum phase systems confuse adaptive filters because the optimal solution requires predicting future values of the input. The filter can only respond to past and present samples, so it converges to a suboptimal solution that may actually worsen performance in certain frequency bands. If you're designing an equalizer for a channel with known non-minimum phase characteristics, consider using a Wiener filter with known statistics instead of an adaptive approach. Highly correlated input signals cause the adaptation to become directionally biased. The filter converges faster along the eigenvector corresponding to the largest eigenvalue and slower along others. This anisotropic convergence means some filter coefficients are well-adapted while others remain inaccurate. Whitening the input or using a filtered-x LMS structure with an explicit model of the correlation structure addresses this. The filtered-x approach adds computational cost but eliminates the directionality problem. Saturated or clipped inputs destroy the gradient estimation that adaptive algorithms depend on. The error signal no longer reflects the true gradient of the cost function. This is particularly problematic in acoustic echo cancellation where loud speech can saturate the ADC. Automatic gain control upstream of the adaptive filter helps, but AGC adjustment transients can themselves disrupt adaptation. A practical solution is to freeze coefficient updates during known transient periods and resume only after the gain stabilizes.
A Working Implementation Outline
For a basic real-time adaptive noise canceller, you need two microphone inputs. One captures the signal plus noise. The other captures noise reference. The reference must be correlated with the noise in the signal path but uncorrelated with the desired signal. This constraint limits where you can place the reference microphone. The algorithm loop runs at the sample rate. Each iteration computes the filter output, calculates the error, and updates the coefficients. For an N-tap filter using LMS, the update takes approximately N multiply-accumulate operations plus one multiplication for the step size. A 256-tap filter at 48 kHz sample rate with LMS requires roughly 12.3 million operations per second. Any modern embedded DSP can handle this comfortably. The convergence rate depends heavily on the eigenvalue spread of the input autocorrelation matrix. A white noise input has an eigenvalue spread of 1, giving the fastest possible convergence. Colored inputs can have spreads exceeding 1000, slowing convergence proportionally. Pre-whitening the input through an inverse filter accelerates adaptation but requires its own design and maintenance.
Monitoring the error norm over time gives you a direct indicator of filter health. A steadily decreasing error norm indicates successful adaptation. An error norm that plateaus early suggests the step size is too small or the input lacks persistent excitation. An increasing error norm means the filter has become unstable and needs immediate intervention. Setting a watchdog threshold at three times the initial error norm and triggering a reset when exceeded prevents prolonged degraded operation. The choice between transversal FIR structures and recursive IIR structures depends on your application. FIR filters are always stable and have linear phase. IIR filters can achieve the same magnitude response with far fewer coefficients but risk instability during adaptation. For most noise cancellation and equalization tasks, FIR is the safer choice despite the higher coefficient count.