Getting Equality Right in Code
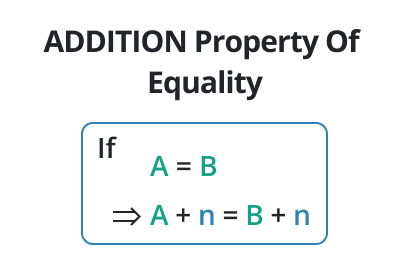
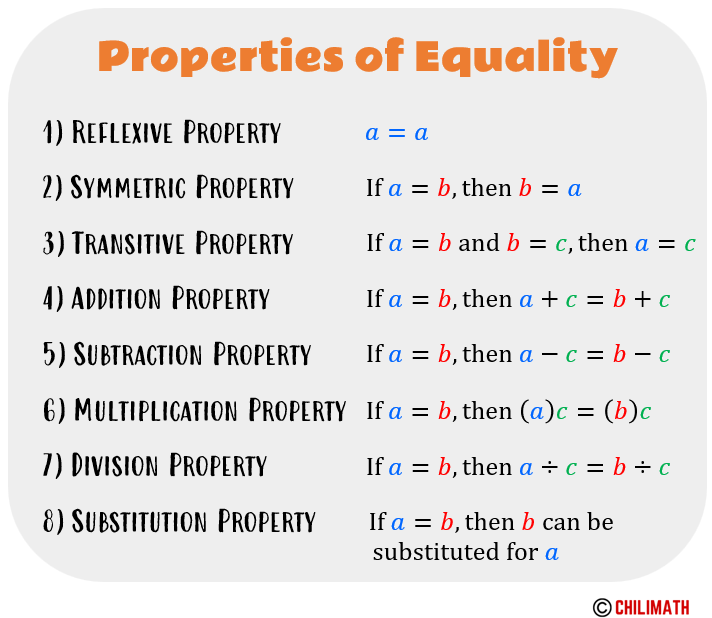
Equality is one of those things everyone thinks they understand until they actually have to implement it correctly across a real codebase. The property of equality isn't just a single rule—it's three specific behaviors that any equality system must satisfy, and if even one of them is missing, bugs appear in places you wouldn't expect. The property of equality rests on three requirements. Reflexivity means a value equals itself. Symmetry means if A equals B, then B equals A. Transitivity means if A equals B and B equals C, then A equals C. These sound obvious until you encounter a case where one of them fails quietly and your entire system starts producing incorrect results without throwing any errors. I spent two weeks tracking down a bug where a custom comparison class returned false for its own equality check under certain serialization conditions. Reflexivity was broken. The object deserialized from disk compared differently than the same object sitting in memory. This happened because the deserialization path applied a default constructor that initialized one field to null while the serialization path left it as an empty string. The class treated null and empty string as the same value for display purposes but not for equality. Fixing it meant explicitly handling that case in the comparison logic.
How equality works in practice
When you add equality to a class or data type, you are telling the system how to decide whether two distinct instances represent the same logical value. Most languages give you a default equality that checks reference identity—whether two variables point to the same object in memory. This default is almost never what you want for business logic. The practical approach is to define equality based on the meaningful attributes of your type. If you are modeling a User entity, equality should be based on the identifier, not on when the object was created or some transient cache field. If you are modeling a financial transaction, equality might depend on the amount, the currency code, and the counterparty—not the internal ledger position or timestamp precision.
Implementing it correctly
Start by identifying the fields that define identity for your type. List every field and ask whether two instances should be considered equal when that field differs. Fields that change during the object lifetime—caches, counters, timestamps, computed totals—should generally be excluded. Fields that change through legitimate business operations—like a status transition from pending to approved—require careful consideration. Once you have your identity fields, write the comparison. The symmetry requirement means your comparison cannot depend on the order in which you compare values. If you compare foo.equals(bar) by first checking bar's type against foo's type, you must also ensure bar.equals(foo) performs the same type check. Many language-specific patterns enforce this naturally through interface implementation or base class design, but when you are writing manual comparison logic, you have to be explicit about it. Transitivity is harder to verify by inspection. It requires that your comparison logic creates consistent equivalence classes. If A and B share the same identity fields and B and C share the same identity fields, A and C must also match. This breaks down when you use partial comparisons—checking some fields in one method and different fields in another, or when you introduce fuzzy matching on string fields without also handling the transitive consequences.
Get the Full Details
Where equality breaks down
The most common failure mode involves mutable fields used in equality checks. If an object is stored in a hash-based collection—dictionary, set, hash map—and then one of its equality-defining fields is modified, the object becomes unreachable or appears duplicated. This is not a theoretical problem. I had a production incident where a cache entry stopped responding to lookup requests because a background job updated a status field that was part of the equality definition. The object was still in the collection, but the hash code no longer pointed to the right bucket. Another frequent issue is mixing different equality semantics in the same hierarchy. If a base class defines equality by identifier and a subclass adds new identity-defining fields, the transitivity property fails for instances of the subclass compared through the base class reference. You end up with A equals B through base class comparison, B equals C through subclass comparison, but A does not equal C. The fix is either to keep equality definitions consistent across the hierarchy or to avoid using these types together in hash-based collections. Floating point values present a separate challenge. Exact equality checks on computed float or double values are unreliable due to rounding behavior. If your domain requires comparing computed monetary or measurement values, use an epsilon-based comparison or store values as integers in the smallest unit. The property of equality still applies—you just need to define what "equal" means in a way that accounts for precision limits.
A specific workaround from experience
In one project I worked on, we had a value object representing a time window with start and end timestamps. The initial implementation compared windows by checking whether their start and end times matched exactly. This failed in practice because two independently created windows covering the same time period could have slightly different millisecond values due to clock drift between servers. The windows were logically equal but the comparison returned false. The workaround was to normalize both windows to second-level precision before comparison. We truncated the millisecond component and performed the equality check on the rounded values. This preserved transitivity because normalization is deterministic—normalizing A gives the same result every time, and if normalized A equals normalized B and normalized B equals normalized C, then normalized A equals normalized C by construction. The symmetry requirement was satisfied because normalization is applied identically regardless of which instance is on the left or right side of the comparison. This approach has a limitation worth noting. If your business logic genuinely needs millisecond-level precision in comparisons, normalizing to seconds will hide real differences. In those cases, you need a different strategy—either storing timestamps with reduced precision from the source or using a range-based comparison that accounts for acceptable tolerance. There is no universal solution here.
Testing your equality implementation
Don't rely on manual inspection alone. Write tests that verify all three properties explicitly. Test reflexivity with a freshly created instance. Test symmetry by generating pairs of instances that should be equal and verifying the comparison works in both directions. Test transitivity with a chain of three instances. Also test the interaction between equality and hashing—if your language requires a hash code alongside equality, verify that equal objects produce equal hash codes. I usually generate test data programmatically rather than using hardcoded values. This catches edge cases that manual test writing misses, particularly around null handling, type mismatches, and boundary conditions on numeric fields. Most modern testing frameworks support property-based testing tools that automate this generation, and the extra setup time is typically worth it for anything beyond trivial data types.
When not to add equality
Sometimes the best answer is that you shouldn't implement equality at all. If your type is truly defined by reference identity—if each instance represents a unique event or resource and two instances are never meaningfully the same—then the default equality behavior is correct. Adding custom equality in this case introduces unnecessary complexity and risk. Similarly, if your type is used only as a temporary holder in a single-threaded operation where equality is never consulted, the overhead of implementing it is wasted effort. Equality is also problematic for types with large or unbounded identity fields. If your equality check requires hashing or comparing a large text payload, every comparison becomes expensive, and hash-based collections lose their performance advantage. In these cases, consider whether a secondary key or identifier can serve as the equality basis while the full payload remains part of the object's value without affecting identity comparison.