Getting Started With Ai Qualitative Data Analysis
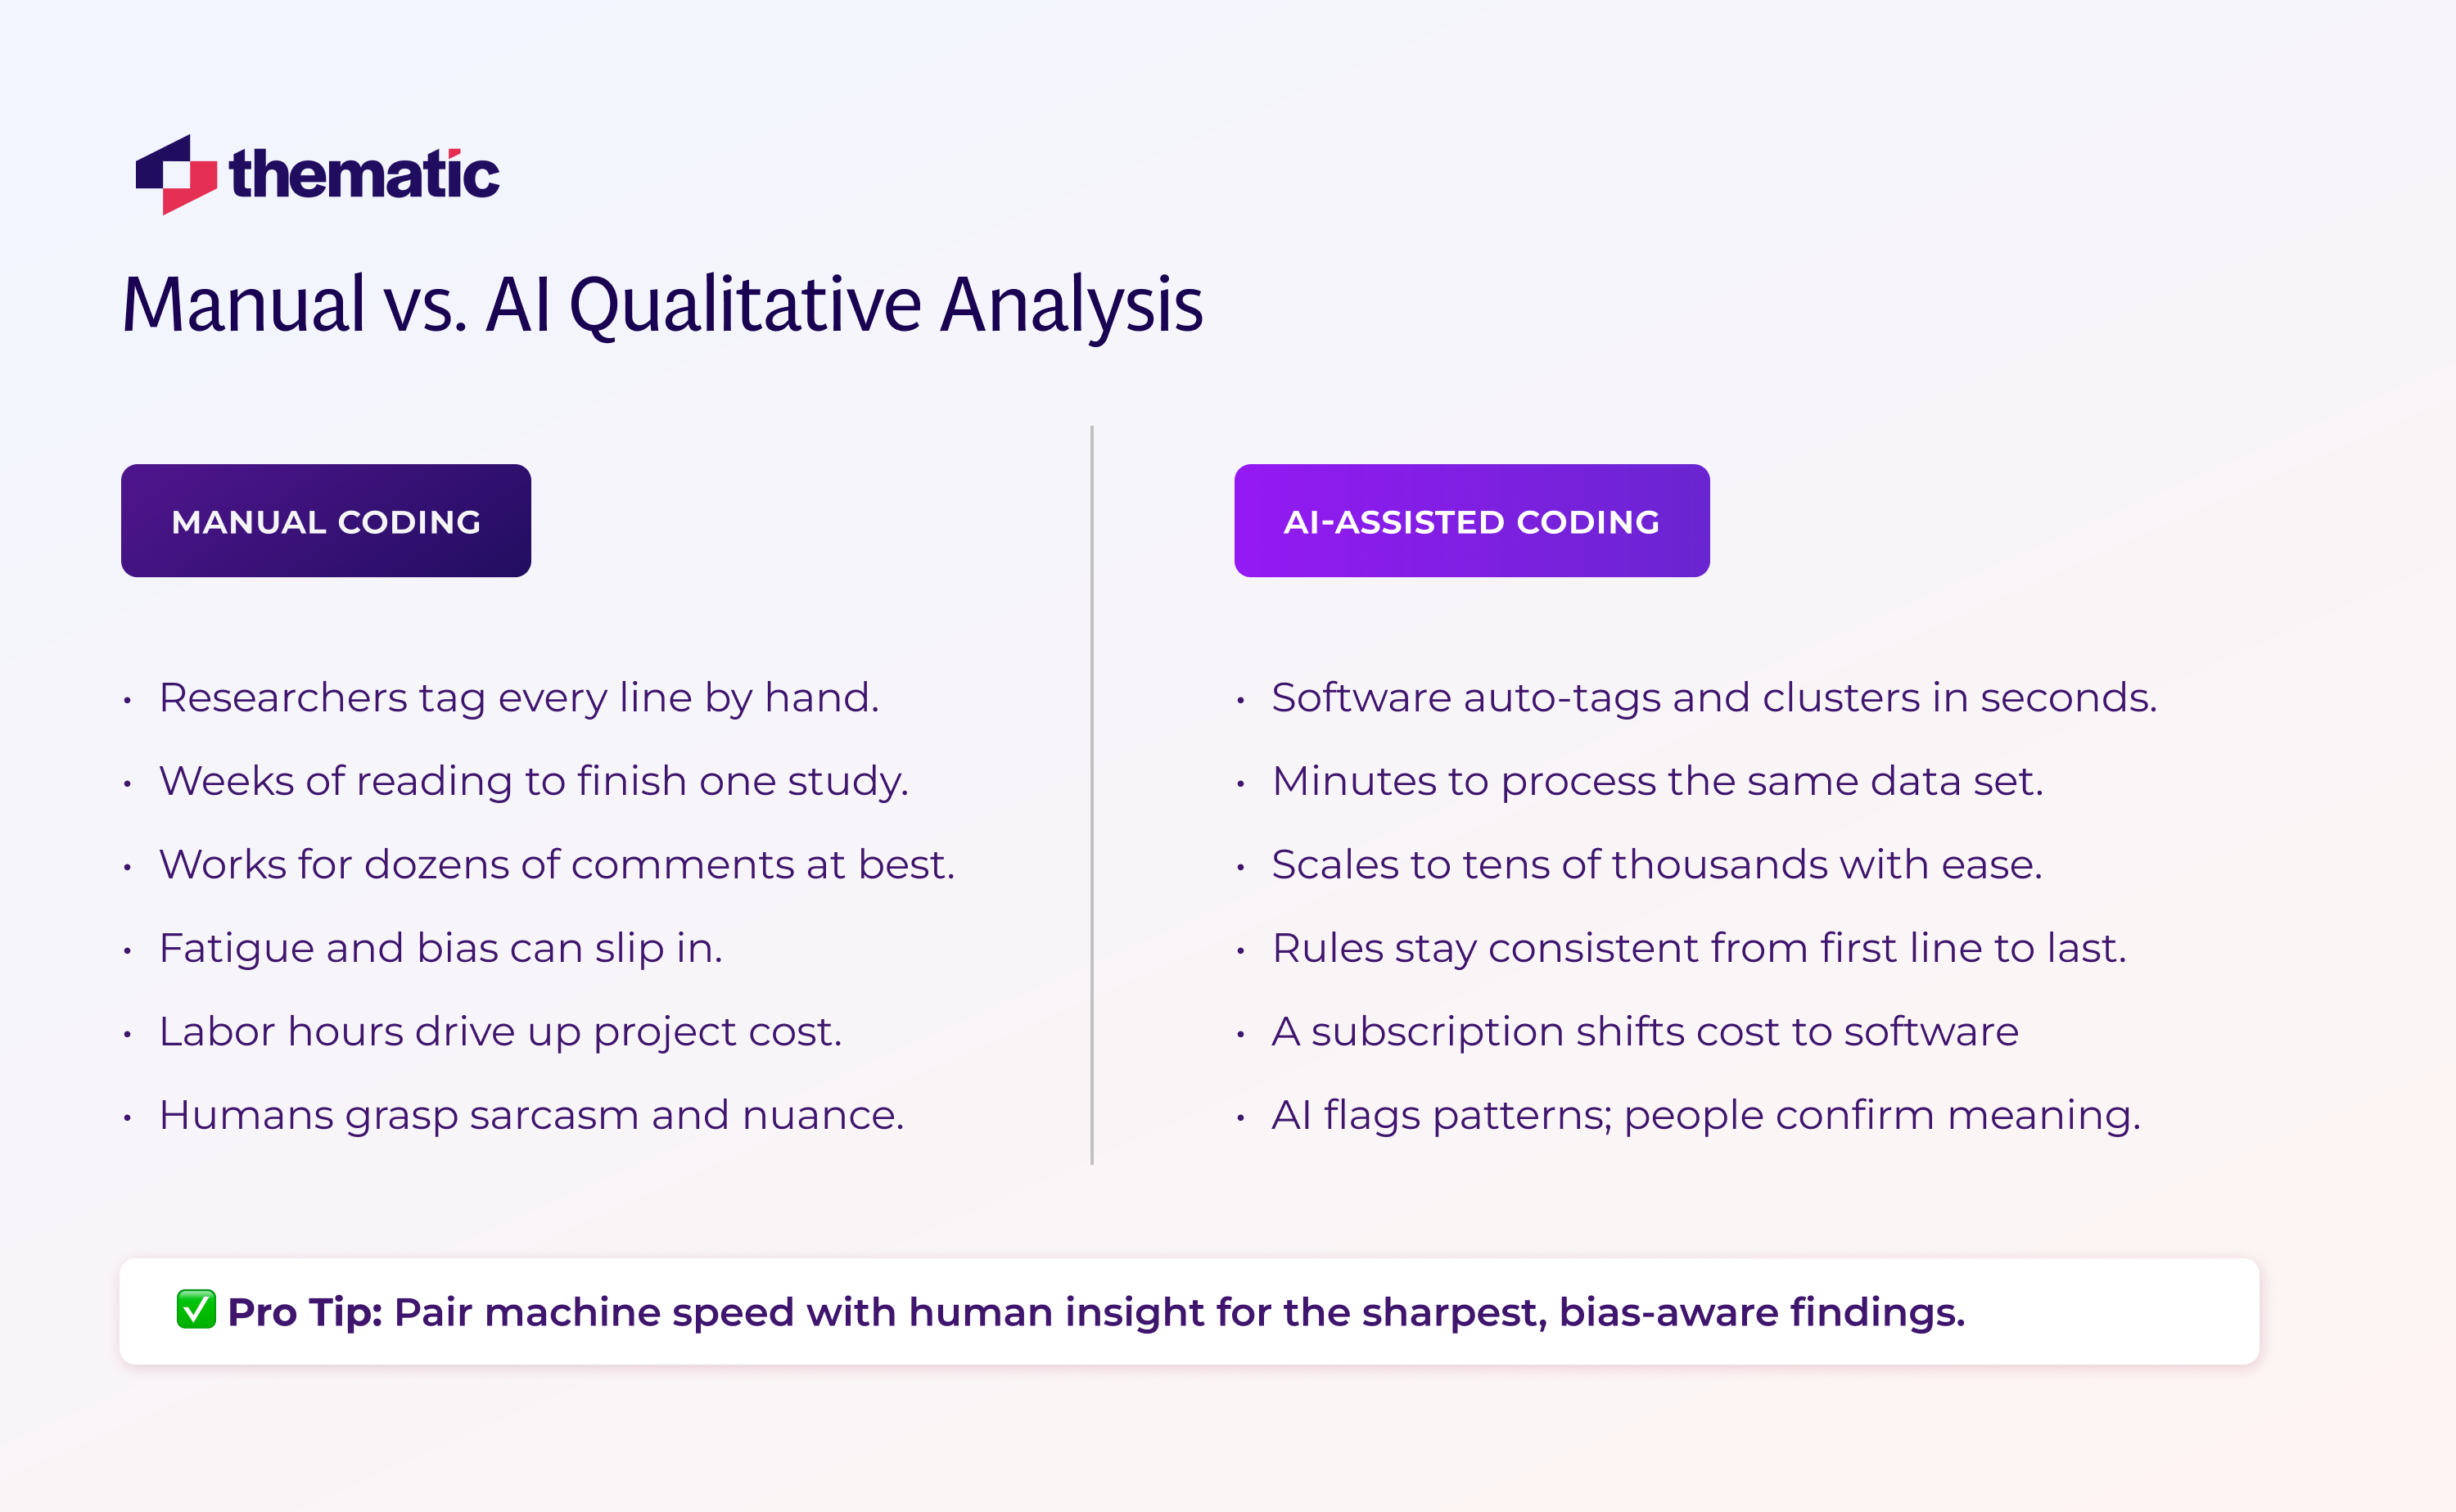
I spent three months coding interview transcripts by hand before I accepted that there had to be a better way. The process was exhausting, the coding was inconsistent, and I was constantly second-guessing whether my categories actually reflected what participants meant or just what I expected to find. Something changed when I started running these same transcripts through AI-assisted analysis tools, and honestly the shift wasn't as dramatic as people make it sound. It is a process where machine learning models help you identify patterns, themes, and meanings in non-numerical data like interview transcripts, open-ended survey responses, or focus group recordings. The AI does not replace your interpretive work. It surfaces potential themes from large volumes of text much faster than manual coding ever could, then you go in and refine, merge, discard, or reframe what the model found. Think of it as a very fast first-pass coder that sometimes misses nuance but rarely makes the same mistake twice on the same document. The tools vary. Some are dedicated platforms like NVivo with built-in AI assist features, others are pure text analysis engines like Leximancer or MonkeyLearn, and a growing number are general LLM pipelines where you paste transcripts into ChatGPT-style interfaces and ask them to code for themes. None of them produce publication-ready analysis out of the box. They produce raw material that still requires careful human judgment.
The Practical Workflow
Here is how I actually run an analysis now. I start by cleaning my data. Remove duplicates, standardize the format, strip out any metadata that could leak into the results. A transcript that contains interviewer notes like [participant crying] can confuse some models into treating emotional markers as thematic content. Delete those before anything else. Then I run the initial coding pass. I upload my documents into the tool and set the parameters. For theme detection, I usually ask for between eight and twelve initial codes on a mid-size dataset of roughly fifty transcripts. More codes than that and the model starts fragmenting themes into irrelevant subcategories. Fewer than eight and you lose the granularity you need for a rigorous analysis. Once the AI returns its coded results, I do not trust the output blindly. I open a random sample of about ten percent of the documents and check the codes against my own reading. If the accuracy is above eighty-five percent, I proceed. If it is below that, I adjust the prompt or the parameter settings and rerun. This step alone usually saves me from wasting hours on a flawed categorization scheme.
After the validation step, I review all the codes across the entire dataset. I merge overlapping themes, split themes that clearly contain two different ideas, and flag any codes that seem driven more by the tool's training bias than by the actual data. This stage is where the real qualitative work happens. The AI gives you a map, but you are the one who decides which paths are worth walking. From there, I build a codebook. I write a clear definition for every code, including the inclusion and exclusion criteria. This is critical for auditability, especially if your work will be reviewed by other researchers or stakeholders. Without a proper codebook, your analysis cannot be replicated, and replication is the baseline expectation for credible qualitative research.
Get the Full Details

One Specific Problem I Ran Into
I was analyzing interview data from healthcare workers during a pandemic study, and the AI kept splitting the same concept into three different codes because some participants described systemic issues while others described personal experiences. The underlying theme was essentially the same: organizational failure during crisis response. But the language patterns were different enough that the model could not recognize the overlap. My workaround was straightforward but not obvious. I wrote a custom prompt that instructed the model to first identify the core concept regardless of framing, then assign the appropriate code based on that concept rather than the linguistic surface. I paired this with a manual cross-reference table where I manually mapped the three split codes back to a single parent theme. It added maybe twenty minutes to the process, but it made the final analysis dramatically more coherent. The lesson here is that domain knowledge matters more than the tool's default settings. If you understand your data well enough to spot when a model is fragmenting a theme, you can fix it.
Common Pitfalls and What Beginners Miss
Most people treat AI coding as an automation shortcut and skip the validation step. That is a mistake. AI models are trained on internet-scale text, which means their default coding framework reflects dominant cultural assumptions and linguistic patterns, not the specific context of your research population. When you are working with marginalized communities, niche professional groups, or non-native English speakers, the model's default behavior can be actively misleading. Always validate against your own understanding of the data. Another pitfall is over-reliance on the frequency of code occurrences as a proxy for importance. A theme appearing in sixty percent of transcripts is not automatically more significant than a theme appearing in fifteen percent. In qualitative research, depth of meaning often matters more than breadth of occurrence. A rare but deeply articulated experience can be far more analytically valuable than a commonly mentioned but superficially discussed one. Let the data's richness guide your conclusions, not just the raw counts.
Ai Qualitative Data Analysis: Tools and How to Access Them
Dedicated tools include NVivo (with its recent AI-powered coding assistants), MAXQDA, Dedoose, and Atlas.ti, each with different pricing models and feature sets. For lighter-weight options, tools like Taguette offer free qualitative coding with some AI-assisted features. If you are working with smaller datasets and need speed, using a well-structured prompt chain with an LLM like Claude or GPT-4 can be effective, though you should always keep a copy of your original data and your prompts for transparency purposes. There is no single download link that covers all of these. Each tool has its own platform, subscription model, or free tier. Check the official websites directly. Avoid third-party download sites that bundle software, as these can introduce security risks and version incompatibilities.
Where This Approach Falls Apart
AI-assisted qualitative analysis is not a universal solution. It struggles with highly context-dependent data, irony, sarcasm, and cultural idioms that do not translate well across the model's training distribution. If your research involves analyzing humor in comedy transcripts, poetic language in literary studies, or highly localized slang, the AI will likely miss the point entirely or produce nonsensical categorizations. In those cases, traditional manual coding or a hybrid approach where the AI handles only the most straightforward segments is the better choice. There is also a transparency issue. When you use AI in your analysis, you need to document exactly what tool you used, what version, what prompts you entered, and how you validated the results. Journals and review boards are increasingly asking for this level of detail, and failing to provide it can undermine the credibility of your work regardless of how sound the analysis itself is. The bottom line is that AI qualitative data analysis is a practical tool for handling volume and speed. It is not a replacement for analytical thinking. Use it to reduce the mechanical labor, not to outsource the interpretation.