How AI Root Cause Analysis Actually Works in Production
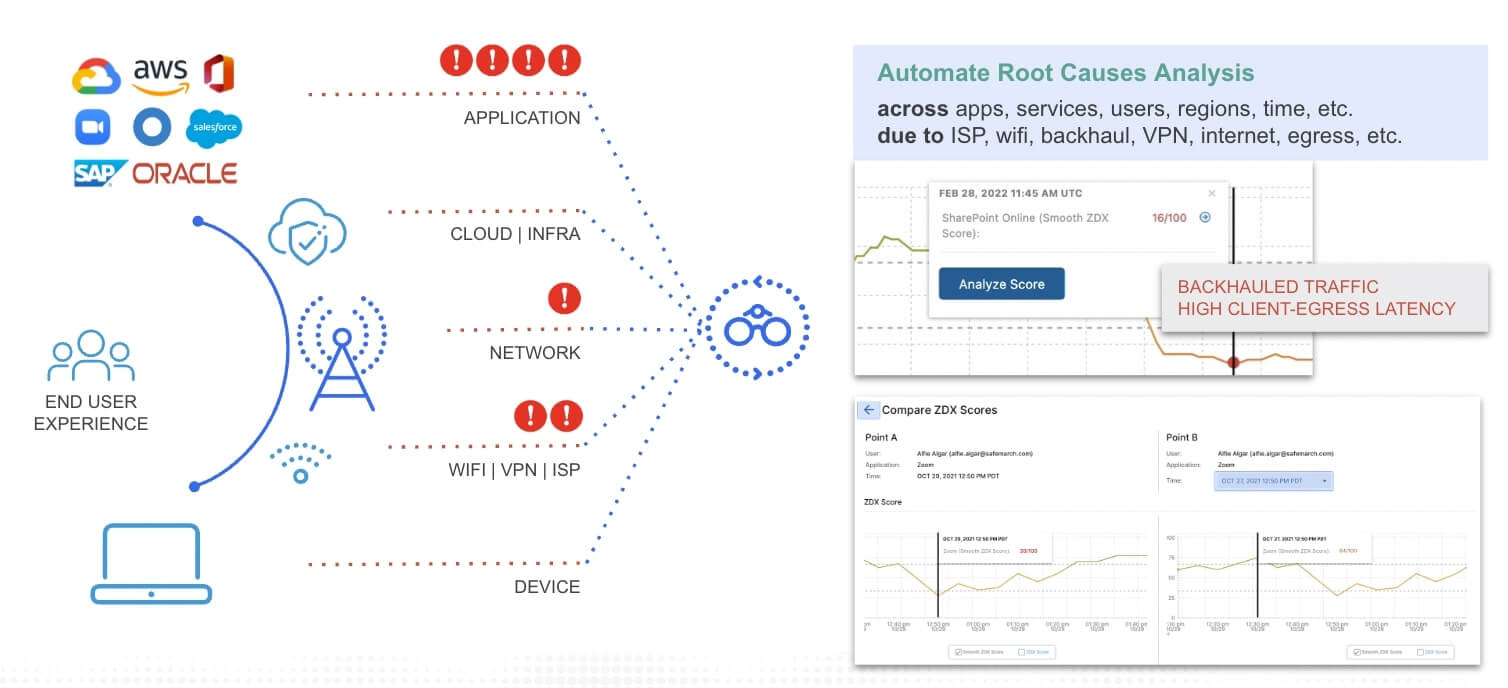
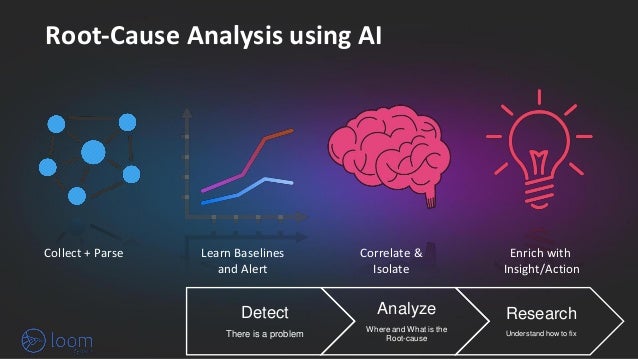
Most people treat AI root cause analysis like a magic button you press after an incident. It is not. It is a set of pattern-matching pipelines that take massive logs, metrics, traces, and deployment histories and find statistical correlations between events. The output is a ranked list of likely causes, not a definitive answer. Understanding that distinction changes how you should use these tools. The typical architecture involves a data ingestion layer that pulls from your observability stack, a feature engineering step that creates behavioral signatures from that data, and a scoring model that weights each candidate cause. Some platforms use causal inference graphs, others rely on ensemble tree models, and a growing number are layering in large language models for natural language summarization of findings. The core technique has not changed much since the first production implementations around 2019.
Setting Up Ai Root Cause Analysis for Your Stack
Start with clean data. This sounds obvious and nobody follows it. If your traces are incomplete, your metrics are not instrumented at consistent intervals, or your log schema changes without versioning, the model will find spurious correlations and present them confidently. I spent three weeks debugging an AIOps tool that kept pointing to a load balancer as the root cause of latency spikes. The real problem was a misconfigured alert threshold in CloudWatch that caused metric collection gaps during high traffic. The model had learned that load balancer flags always appeared before degradation events, which was true, but only because the alerting system was firing false positives that preceded actual issues. Here is what you need before you enable any AI RCA tool: structured logs with a stable schema, distributed tracing across all services, synthetic monitoring for critical user flows, deployment timestamps tied to every artifact, and database query performance logs. That is the minimum. Anything less and you are feeding noise into a black box. The configuration phase usually takes between two and four weeks depending on team size and data maturity. You will need a data engineer to build the ingestion pipelines, an SRE or platform engineer to define the signal boundaries, and someone with machine learning operations experience to handle the model retraining schedule. Budget time for the ground truth collection period where the model learns from historical incidents. If you skip this and just point the tool at live data, it will make confident guesses with no basis in your actual environment.
I recommended one implementation for a fintech client where they wanted to skip the ground truth phase entirely. They had two hundred microservices and wanted instant deployment. The model produced results on day one, but ninety percent of its top-ranked causes were wrong because it had no baseline of their failure patterns. We pulled it back, spent a month ingesting eighteen months of incident data, and retrained. After that, the precision hit about seventy-two percent on known incident types. Not great, not terrible, but usable. The initial deployment would have cost them credibility with the engineering team within a week.
Get the Full Details

What the Tools Actually Return and How to Read Them
A proper AI RCA output contains a ranked list of candidate causes with confidence scores, the evidence chain linking each candidate to the observed symptoms, temporal context showing when related events occurred, and a textual summary of findings. The confidence score is not a probability. It is a similarity metric against training data. A score of 0.8 does not mean there is an eighty percent chance that candidate is correct. It means the current pattern closely matches historical cases in the training set. The evidence chain is where most tools fail. They show correlation between event A and event B but cannot distinguish whether A caused B, B caused A, or both were caused by C. Causal discovery is computationally expensive and most commercial tools approximate it rather than compute it. When the tool says "deployment of service X correlated with error rate increase," verify the directionality yourself. Check the deployment timestamp against the exact moment the error rate began climbing. If the error spike preceded the deployment by even thirty seconds, the model has reversed causality. One counter-intuitive thing about these systems is that they tend to be better at identifying infrastructure-level causes than application-level ones. Memory leaks, disk saturation, network partition, DNS resolution failures, certificate expiry, upstream dependency timeouts. These leave clear footprints across metrics and logs. Application bugs, race conditions, incorrect business logic, stale data in caches, these are much harder to trace automatically because they often do not produce anomalies in the infrastructure signals that RCA tools monitor. If your incident is a logic bug, the AI will likely point you toward a related service dependency or a resource threshold and you will waste time investigating the wrong layer.
Another thing beginners miss is that these models degrade over time if you do not continuously feed them new incident data. Every major incident, every known false positive, every confirmed root cause should be fed back into the training pipeline. Without continuous retraining, the model starts confidently recommending causes that were relevant to last year's infrastructure but not to your current setup. We saw this with a SaaS company that had migrated their database from PostgreSQL to CockroachDB mid-year but never updated the model. The RCA tool continued flagging PostgreSQL-specific performance patterns as likely causes for six months after the migration.
When AI Root Cause Analysis Will Fail You
It fails on first-time novel failure modes. If nothing in your training data resembles the current incident, the model will either return garbage with high confidence or return nothing at all. This is not a software problem, it is a fundamental limitation of supervised and semi-supervised learning approaches. You cannot recognize a pattern you have never seen before. It fails on multi-layered incidents where several independent failures compound. An upstream provider goes down at the same time as an internal cache corruption event. The model will pick one and ignore the other, or worse, merge them into a single incorrect hypothesis. These scenarios require human investigation regardless of tool quality. It fails on incidents that are intentionally obscured. Security breaches, insider threats, and deliberate sabotage often bypass the metrics and logs that RCA tools monitor. The tool will search for performance anomalies while the real issue is authentication token manipulation or API abuse.
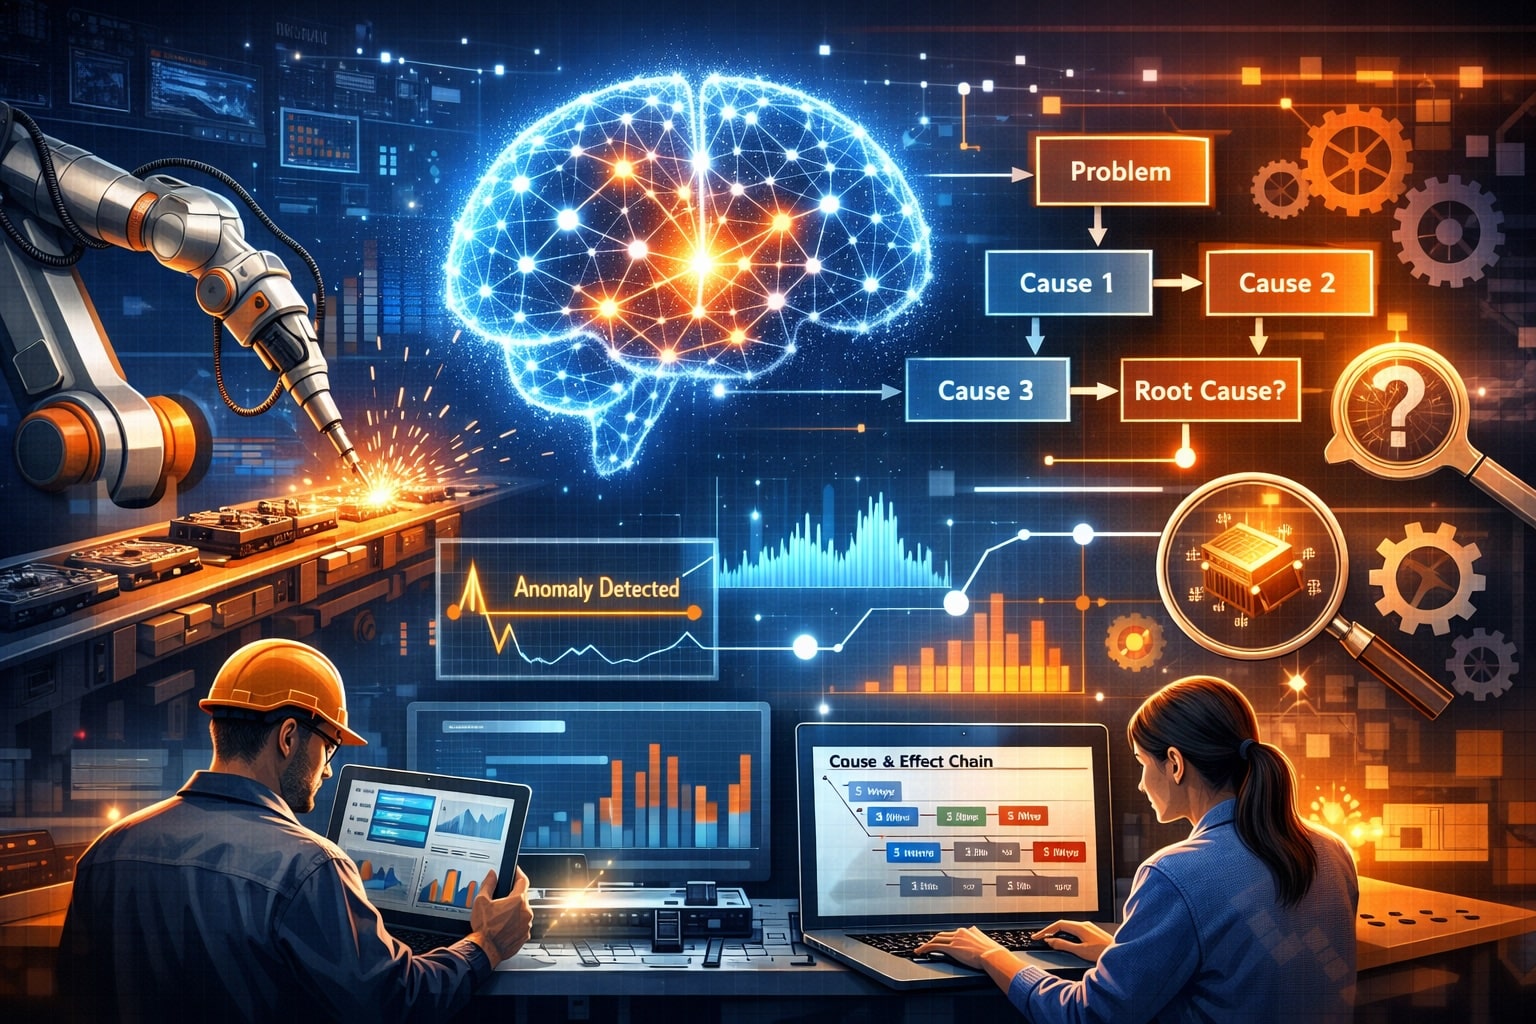
For these cases, the best approach is combining AI RCA with manual investigation workflows. Use the tool to surface likely infrastructure causes quickly, then layer in structured human analysis using techniques like fault tree analysis or the five whys method. Many teams I work with now run both in parallel. The AI produces its top three candidates within minutes, and the on-call engineer begins a manual trace of the most suspicious path simultaneously. This usually cuts mean time to resolution from about ninety minutes down to roughly twenty-five for standard incidents, though complex multi-failure cases still take longer regardless of tools involved. If you are considering implementing this, audit your data quality first. Check trace completeness, log consistency, and metric coverage. Then run a pilot on your last twelve incidents and compare the tool's recommendations against known root causes. If the match rate is below fifty percent, you need more ground truth data before going production. That is the honest baseline most vendors will not tell you.