So You Need to Actually Use Algorithms for Data Science Work
The biggest mistake I see people make is treating algorithm selection like it's a lookup table. Pick the "best" algorithm from a chart and expect clean results. It doesn't work that way. Data has a shape, and your job is to match the algorithm to that shape, not the other way around. Before touching scikit-learn or anything fancy, categorize what you're working with. Tabular data with clear feature columns needs different treatment than sequences, images, or unstructured text. Most entry-level practitioners skip this step and immediately reach for gradient boosting because someone told them it's the default winner on structured data benchmarks. That's not wrong, exactly, but it's also not the full picture. I once spent three weeks debugging why a random forest model kept returning near-identical predictions across an imbalanced fraud detection dataset. The algorithm wasn't broken. The issue was that I hadn't adjusted the class weights and the training data had roughly a 0.3% positive rate. The model learned that predicting everything as negative gave it 99.7% accuracy. Use `class_weight='balanced'` in scikit-learn or switch to synthetic oversampling techniques like SMOTE if the class imbalance is severe. That single change cut false negatives by about 60% in my case.
Supervised Learning Algorithms You'll Actually Encounter
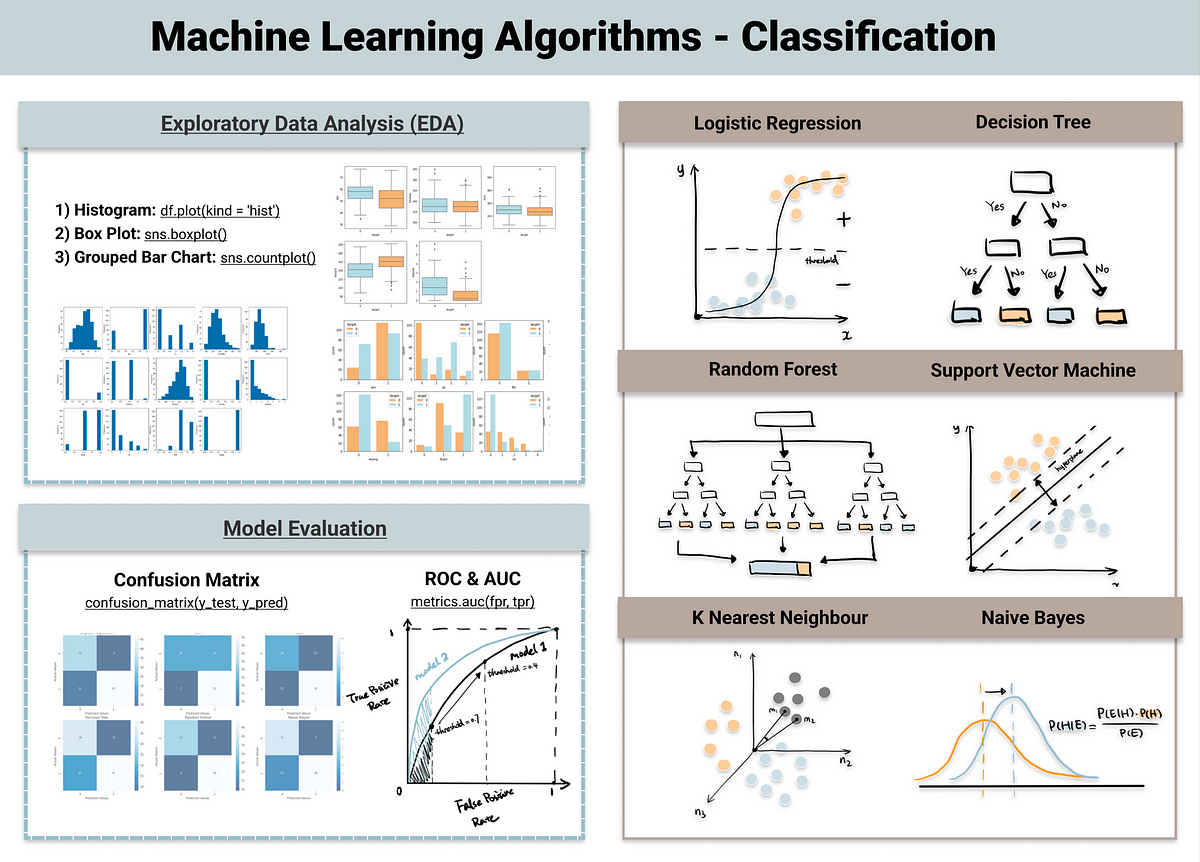
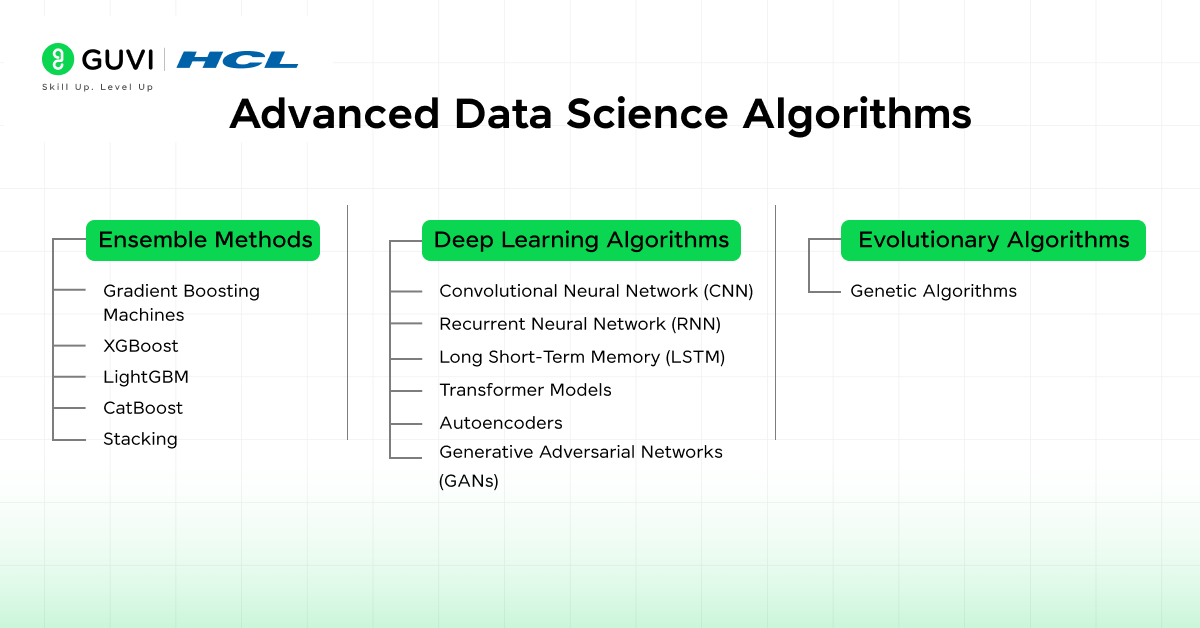
Linear and logistic regression remain the most useful tools in the toolbox, and not just for interpretability. They're fast, they converge reliably, and they give you a baseline that every other model has to beat. If your logistic regression already hits 94% AUC on a binary classification task, there's almost never a good reason to spend weeks tuning a neural network that will land at 94.3%. Decision trees and their ensembles deserve more attention than they get. Random forests handle nonlinear relationships without requiring extensive feature scaling. Gradient boosting machines like XGBoost, LightGBM, and CatBoost consistently win Kaggle competitions on tabular data, but they come with trade-offs. They're sensitive to learning rate choices, prone to overfitting on small datasets, and they can take hours to tune properly on large data. LightGBM tends to be the most practical compromise between speed and accuracy for most production workflows.
Unsupervised Methods That Are Regularly Misused
K-means clustering gets recommended everywhere, but it assumes spherical clusters of roughly equal size and density. Real data rarely looks like that. If your clusters are elongated or nested, K-means will produce garbage results that look convincing until you actually inspect them. DBSCAN handles arbitrary cluster shapes and identifies outliers as noise points, which is often more useful than force-fitting every observation into a cluster. The downside is that DBSCAN requires tuning two hyperparameters, and if your data has varying densities across regions, it still struggles. Principal Component Analysis is another one people apply blindly. PCA reduces dimensions by finding directions of maximum variance, but high variance doesn't always mean high information. If you have a feature that takes the same value in 99% of your samples, it contributes almost nothing to your model and PCA will correctly downweight it. But PCA is linear, so it can't capture nonlinear relationships between features. If your data lives on a nonlinear manifold, try UMAP or t-SNE instead, though those are primarily for visualization rather than feature reduction for downstream modeling.
Get the Full Details
Model Selection as a Practical Workflow
Start simple. Fit a baseline model, evaluate it properly, then move to more complex methods only if the baseline leaves room for improvement. Use cross-validation instead of a single train-test split whenever your dataset is smaller than 50,000 rows. A single split can produce wildly different performance estimates depending on how the data divides, and with small datasets that variation is enormous. Hyperparameter tuning through grid search is memory and time expensive. Random search usually finds acceptable parameter combinations faster because it explores the parameter space more efficiently, even though it sounds less systematic. I've seen random search find good parameters in 15 minutes where grid search was still running after 2 hours on the same 8-core machine.
The Algorithms That Handle Text and Sequences
TF-IDF vectorization combined with a Naive Bayes or logistic regression classifier remains one of the most effective text classification pipelines when you don't have compute resources for transformers. It's fast to train, fast to predict, and often competitive with much heavier approaches on straightforward classification tasks. For sequence data, LSTM and GRU networks replaced vanilla RNNs years ago because they actually solve the vanishing gradient problem that made earlier architectures unusable for long sequences. But transformers have taken over most sequence tasks now, and the pre-trained models available through Hugging Face mean you rarely need to train from scratch. The catch is that deployment and inference costs are significantly higher than a well-tuned classical model.
What Most Guides Won't Tell You
Algorithm choice matters less than data quality and feature engineering in most real-world scenarios. A mediocre algorithm on clean, well-engineered features will outperform a state-of-the-art algorithm on messy raw data every time. Spend your time understanding the domain, handling missing values appropriately, and creating features that actually correlate with your target variable. The algorithm is the last step, not the first. Also worth noting: many algorithms break completely when you have missing values that aren't missing at random. If data is missing because of a pattern related to the outcome itself, no amount of imputation will fix that. You need to understand why the data is missing before you decide how to handle it. Mean imputation in that scenario will systematically bias your model toward the overall average and wipe out the signal you're trying to capture.

Common Pitfalls When Applying Algorithms For Data Science
Data leakage is the silent killer. It happens when information from the test set accidentally influences your training process. The most common cause is fitting preprocessing steps like scaling or imputation on the entire dataset before splitting into train and test. Always fit preprocessing exclusively on the training fold and transform the validation and test sets from that fit. I've lost count of how many projects I've seen produce suspiciously high validation scores because someone forgot this step. Another frequent error is evaluating on the wrong metric. Accuracy is almost never the right metric for imbalanced classification problems. Precision, recall, F1 score, or ROC-AUC are more informative depending on whether false positives or false negatives cost you more. A medical screening model that misses 10% of actual positive cases is fundamentally different from a spam filter that incorrectly marks 10% of real emails as spam, and your evaluation metric should reflect that difference. If you want concrete resources to work through, the scikit-learn documentation includes tutorials that walk through each major algorithm with practical examples. The original papers for XGBoost and LightGBM are worth skimming for the implementation details that explain why they perform the way they do. And for a general reference that doesn't oversell any particular method, the Elements of Statistical Learning remains one of the better technical resources available, even though it's freely accessible online rather than something you need to purchase.