How to Actually Use a Codon Table Without Going Crazy
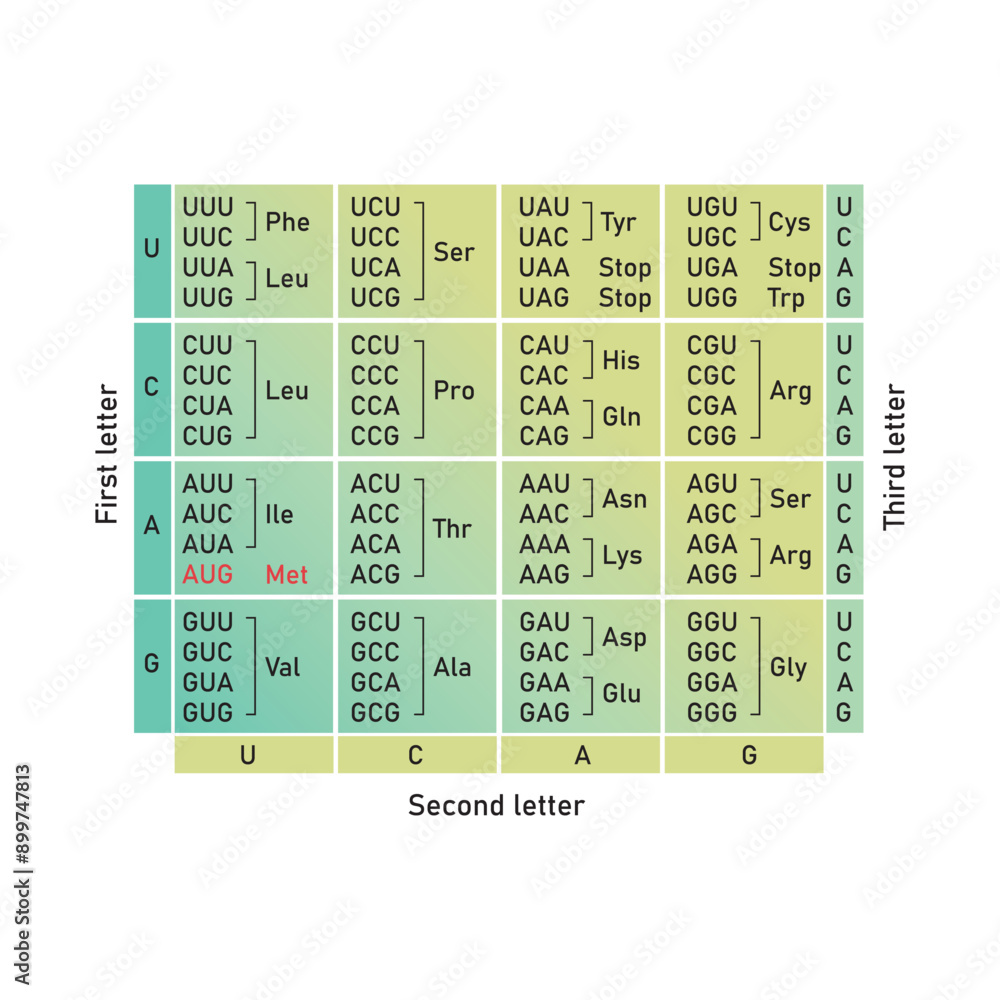
I spent three weeks debugging a recombinant protein expression issue before I realized I had been reading the wrong codon table for the organism I was working with. Most people pulling up an Amino Acid Codon Table Dna for the first time don't realize that the one in their textbook is probably the standard bacterial version, and that won't save you when you are switching to yeast or mammalian cells. The table maps 64 possible three-nucleotide combinations to twenty amino acids plus stop signals. That redundancy is not a flaw. It is the whole reason degenerate primers exist and why wobble pairing works at the tRNA level. When I see someone designing a primer without checking the third position bias for their expression host, I already know where the experiment is headed. Here is the practical part. You take your protein sequence, run it through a reverse translation tool, and then you optimize the codons based on your host organism's tRNA abundance data. For E. coli, that means avoiding arginine CGA and AGA codons if your strain lacks sufficient tRNA. For CHO cells, it means watching out for cryptic splice sites and CpG islands that trigger silencing. The table itself does not tell you any of that. It just shows you which triplets are available.
Common Pitfalls When Working With Codon Tables
The biggest mistake beginners make is assuming uniform codon usage within a species. It does not exist. Highly expressed genes in any organism skew heavily toward a subset of the available synonymous codons. The rare codons become bottlenecks during translation, causing ribosome stalling and truncated products. I ran a His-tag purification where the entire yield was a 15 kDa fragment because a single AGG arginine codon appeared three times in a row at a critical point in the coding sequence. Another thing nobody warns you about is the difference between genomic DNA tables and mRNA tables. If you are working with eukaryotic constructs, uracil replaces thymine in the transcript, and your restriction enzyme cloning strategy depends on the DNA version. Mixing these up will not break your pipetting technique, but it will definitely waste your weekend.
When the Standard Table Fails You
The standard genetic code table covers roughly 99 percent of laboratory work, but mitochondrial sequences do not follow it. vertebrate mitochondria treat AGA and AGG as stop codons instead of arginine. Some protozoa reassign entire stop codons to glutamine. If you are doing any heterologous expression in non-standard systems, you need organism-specific tables, not the textbook version. I also cannot recommend over-optimization. There is a published case where codon-perfecting a gene for a mammalian host actually reduced protein folding because the translation speed became too uniform. Slow translation at certain positions allows proper domain folding. The workaround is partial optimization, leaving rare codons intact at structurally important regions while fixing the obvious bottlenecks. I typically keep 10 to 15 percent of natural codon bias in the final construct.
Get the Full Details

Where to Find Reliable Tables
The NCBI maintains a complete codon change table with organism-specific notes, and it updates regularly as new sequencing data comes in. I use their tool when I need to verify a non-standard genetic code before ordering primers. For quick reference during primer design, the ExPASy codon usage database gives you relative synonymous codon usage values for hundreds of organisms, which is more actionable than a plain table. If you want a downloadable reference file for scripting purposes, the codon table format from the International Union of Biochemistry and Molecular Biology is the standard. It is plain text, easy to parse, and includes the non-standard codes. I keep a copy in my lab scripts directory and call it whenever I write a reverse translation function.
A Practical Walkthrough
Take a human protein sequence and prepare it for expression in E. coli BL21 DE3. First, run the sequence through a codon optimization tool using BL21 specific parameters. Filter out consecutive rare arginine or proline codons. Check for internal restriction sites that might interfere with your cloning vector. Add your tags at the appropriate terminus. Verify the final construct does not contain strong RBS-like sequences in the 5 prime UTR that could cause premature initiation. The actual table lookup happens at the beginning of this process, not the end. You need to know which codons are synonymous before you can make informed decisions about optimization. I usually print a physical copy of the relevant Amino Acid Codon Table Dna and tape it to my bench. Yes, that is old school, but it prevents the kind of error where you spend hours troubleshooting something you could have caught in five minutes by glancing at the table. Protein expression optimization takes patience and a solid grasp of the underlying genetics. The codon table is your starting point, not your solution. Use it, understand its limits, and move on to the harder parts like folding, solubility, and purification.