Setting Up an Aml Risk Assessment That Actually Survives an Audit
Most risk assessments I see are either too thin to be useful or too thick to read. The gap between what auditors want and what your operations team can actually deliver is where most of this falls apart. I spent years building these from scratch for fintechs, payment processors, and a few crypto-native platforms, and the ones that stuck had one thing in common: they were built around data you already had, not data you wished you had. Start by mapping your customer journey. I don't mean the marketing version. I mean every step from signup to transaction to escalation. If a customer can move money without providing identity, that's a risk node. If they can provide one document and then never update it, that's another. You're looking for friction gaps. This took me about two weeks for a mid-size payments platform, including time to get buy-in from product and compliance.
Conducting Your First Aml Risk Assessment
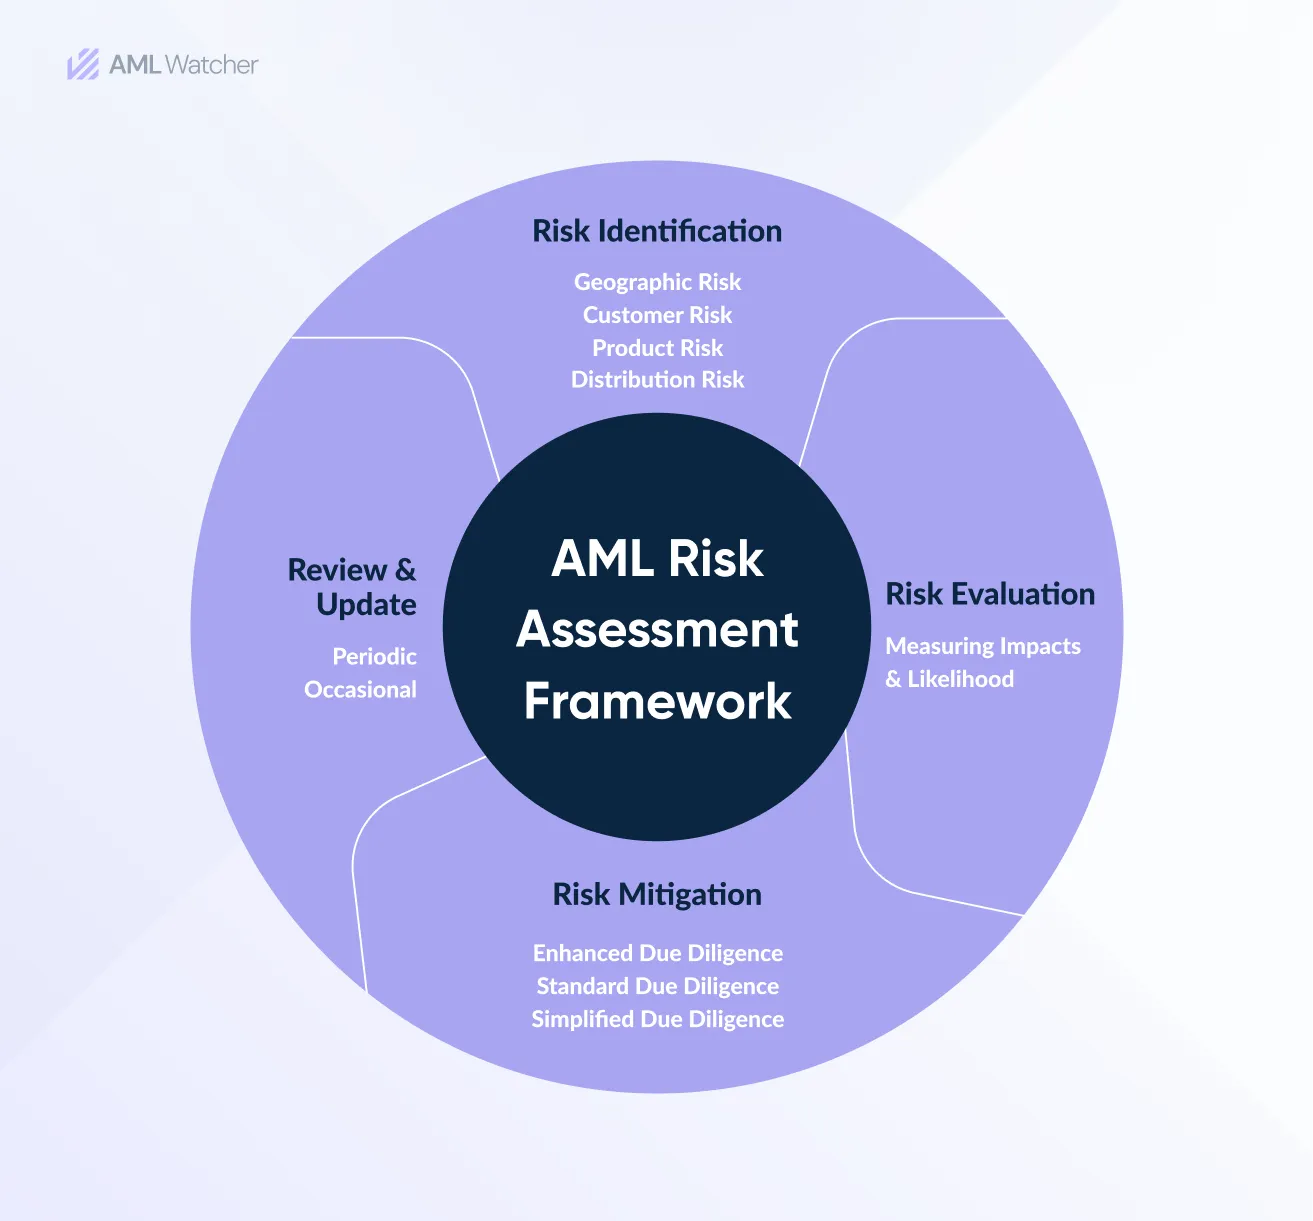
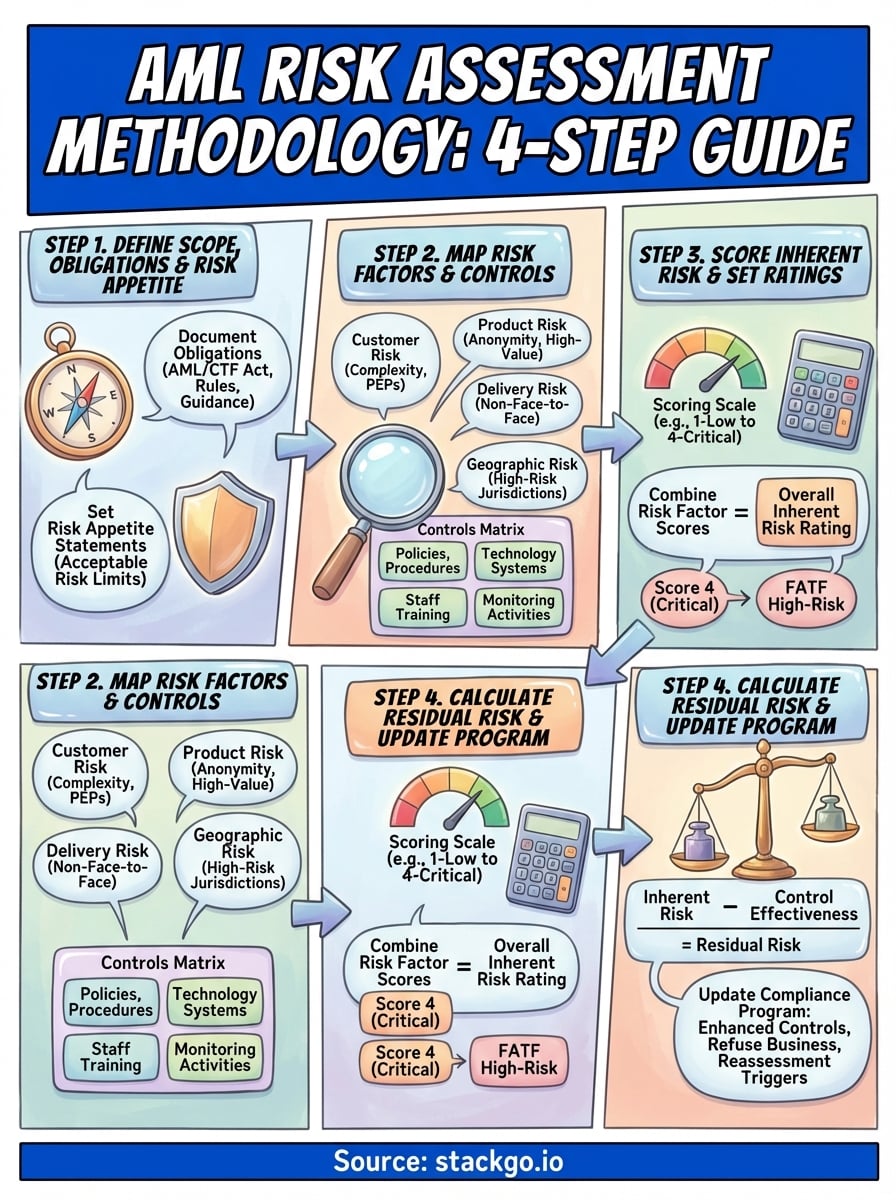
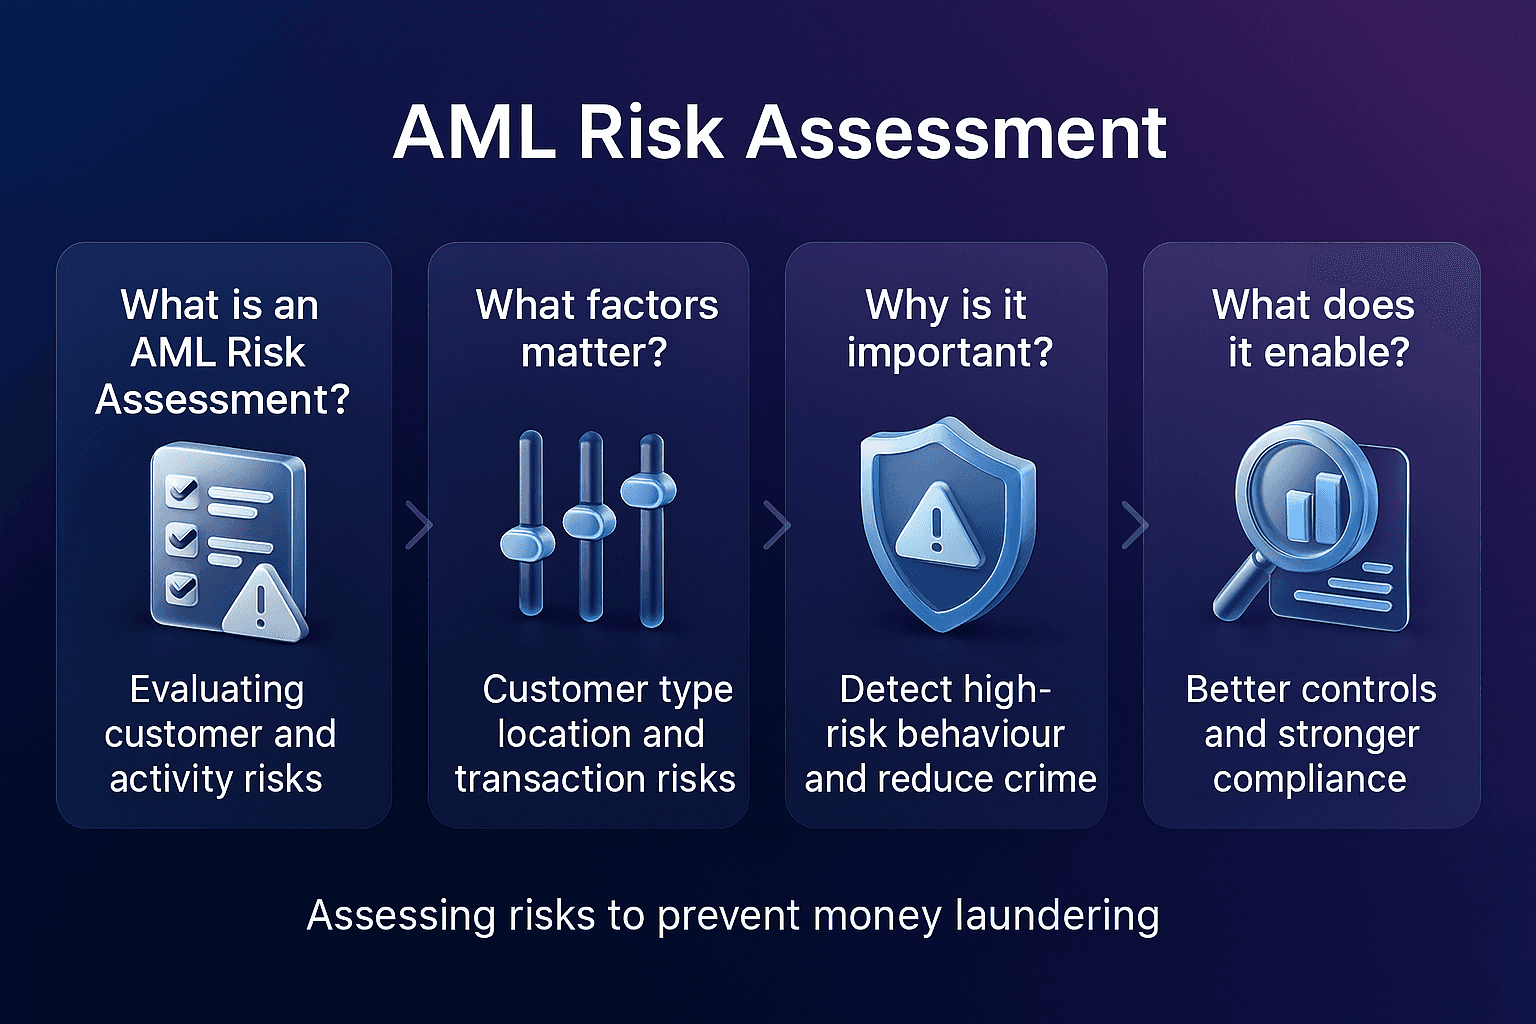
The actual assessment part breaks into four stages. First, identify the risk categories. These are usually customer risk, geographic risk, product risk, and delivery channel risk. Second, score each category on a scale. Third, weight them based on your business profile. Fourth, combine them into an overall risk rating per customer segment. Here's where people mess up. They treat all four categories as equally important. They're not. For a B2B payments platform, product risk and customer risk dominate. Geographic risk matters less unless you're operating in sanctioned jurisdictions. I learned this the hard way when a regulator flag was raised on a client because their risk model gave equal weight to high-risk countries and low-risk corporate accounts. The fix was recalibrating the weights based on actual transaction patterns, not theoretical concerns. That alone took about three weeks of analysis. The scoring framework itself is straightforward. Use a low-medium-high scale with clear criteria for each level. Don't use numeric scores that imply precision you don't have. A score of 73 out of 100 means nothing. A score of "elevated due to jurisdiction and transaction volume" means something.
One specific edge case that caught me off guard: shell companies registered in low-risk jurisdictions but with beneficial owners in high-risk ones. The automated tools flag the jurisdiction, but the real risk is the ownership structure. My workaround was layering in a beneficial ownership verification step that pulled from multiple registries, not just the one the company declared. This added about 10 minutes to the onboarding process per high-risk entity but caught three cases in my first quarter that would have otherwise passed through undetected. You'll also need a document retention strategy. Regulators ask for your risk assessment methodology during examinations, and if your documentation is scattered across spreadsheets and email threads, you're already behind. I used a single shared drive with version control and dated change logs. It was simple, and it took about five minutes per week to maintain once the structure was set up. The biggest limitation of any risk assessment framework is that it's only as good as the data feeding it. If your transaction monitoring system doesn't capture enrichment data like IP geolocation or device fingerprints, your risk scores will understate exposure. I've seen this repeatedly. The workaround is to start collecting that data immediately, even if you're not using it yet. It usually takes six to twelve months for historical patterns to become meaningful.
Get the Full Details
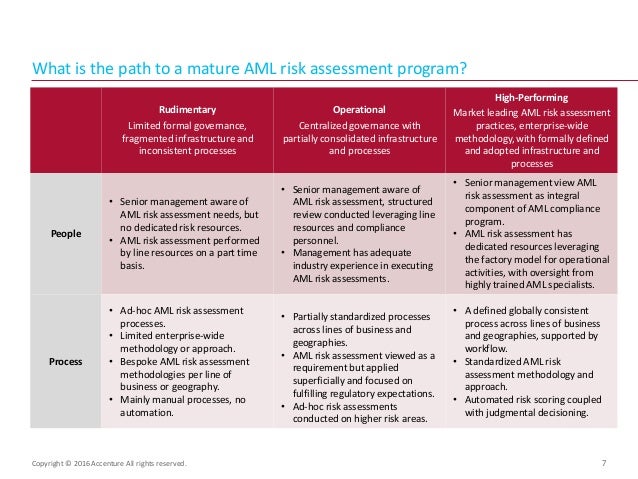
Another thing nobody talks about: risk assessments need to be dynamic, not annual checkboxes. A static assessment done once a year misses emerging patterns. I recommend a quarterly review cycle with monthly spot checks on high-risk segments. This usually cuts the remediation time from months to days when something slips through.