Getting MCA to actually work on messy survey data
MCA, or Multiple Correspondance Analysis, takes a bunch of categorical variables and projects them onto a low-dimensional space so you can see patterns. It is the categorical equivalent of PCA, and unlike PCA, you do not need to numericize anything beforehand. The standard tool is the FactoMineR package in R, which is free and well documented. You install it once, load it, and you are good. Here is the practical path. Load your data as a data frame where every variable is a factor. Run the function with the data argument and the appropriate number of components. That is the core of it. From there, you extract the coordinates, the quality of representation, and the contributions to build any kind of meaningful interpretation. A real example. I was working with a dataset of about 400 respondents and roughly 25 nominal variables covering housing type, transportation mode, satisfaction levels, and so on. The dataset had a lot of sparse categories—maybe 12% of responses fell into rare answer options. I ran MCA through the standard workflow, extracted the first two dimensions, and immediately noticed that Dimension 1 was dominated by just three variables because those variables had very high marginal totals. That skewed the whole solution. The workaround was to recode the rare categories into an "other" bin before running the analysis, which balanced the contributions and made the dimensions interpretable again.
How MCA actually computes its solution
The method constructs an indicator matrix from your categorical variables. Each row becomes a set of ones and zeros indicating which category was selected. It then applies a principal component analysis to that binary matrix. The eigenvalues come from the correlation structure of the categories, and the inertia—the categorical version of variance—is what gets partitioned across dimensions. The Burt table is the full cross-tabulation of every category against every other category, and MCA decomposes it. The correspondence analysis framework means the solution is driven by chi-squared distances rather than Euclidean distances. Analyste En Composantes Multiples is the French term you will encounter in many software implementations and academic papers. The math is identical regardless of the language label.
Interpreting the output correctly
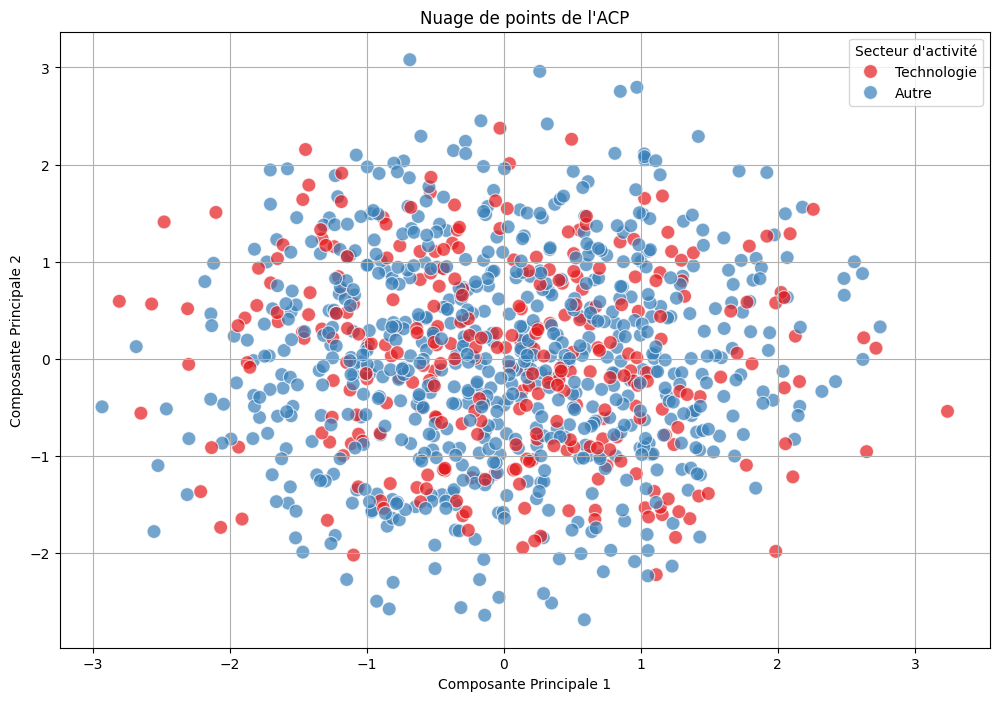
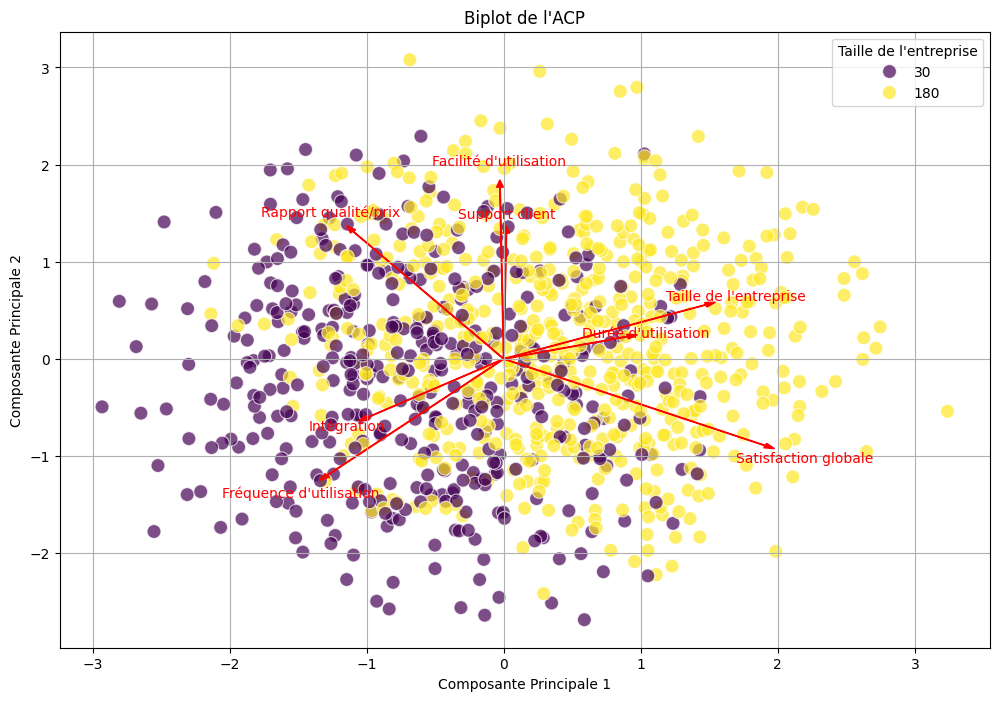
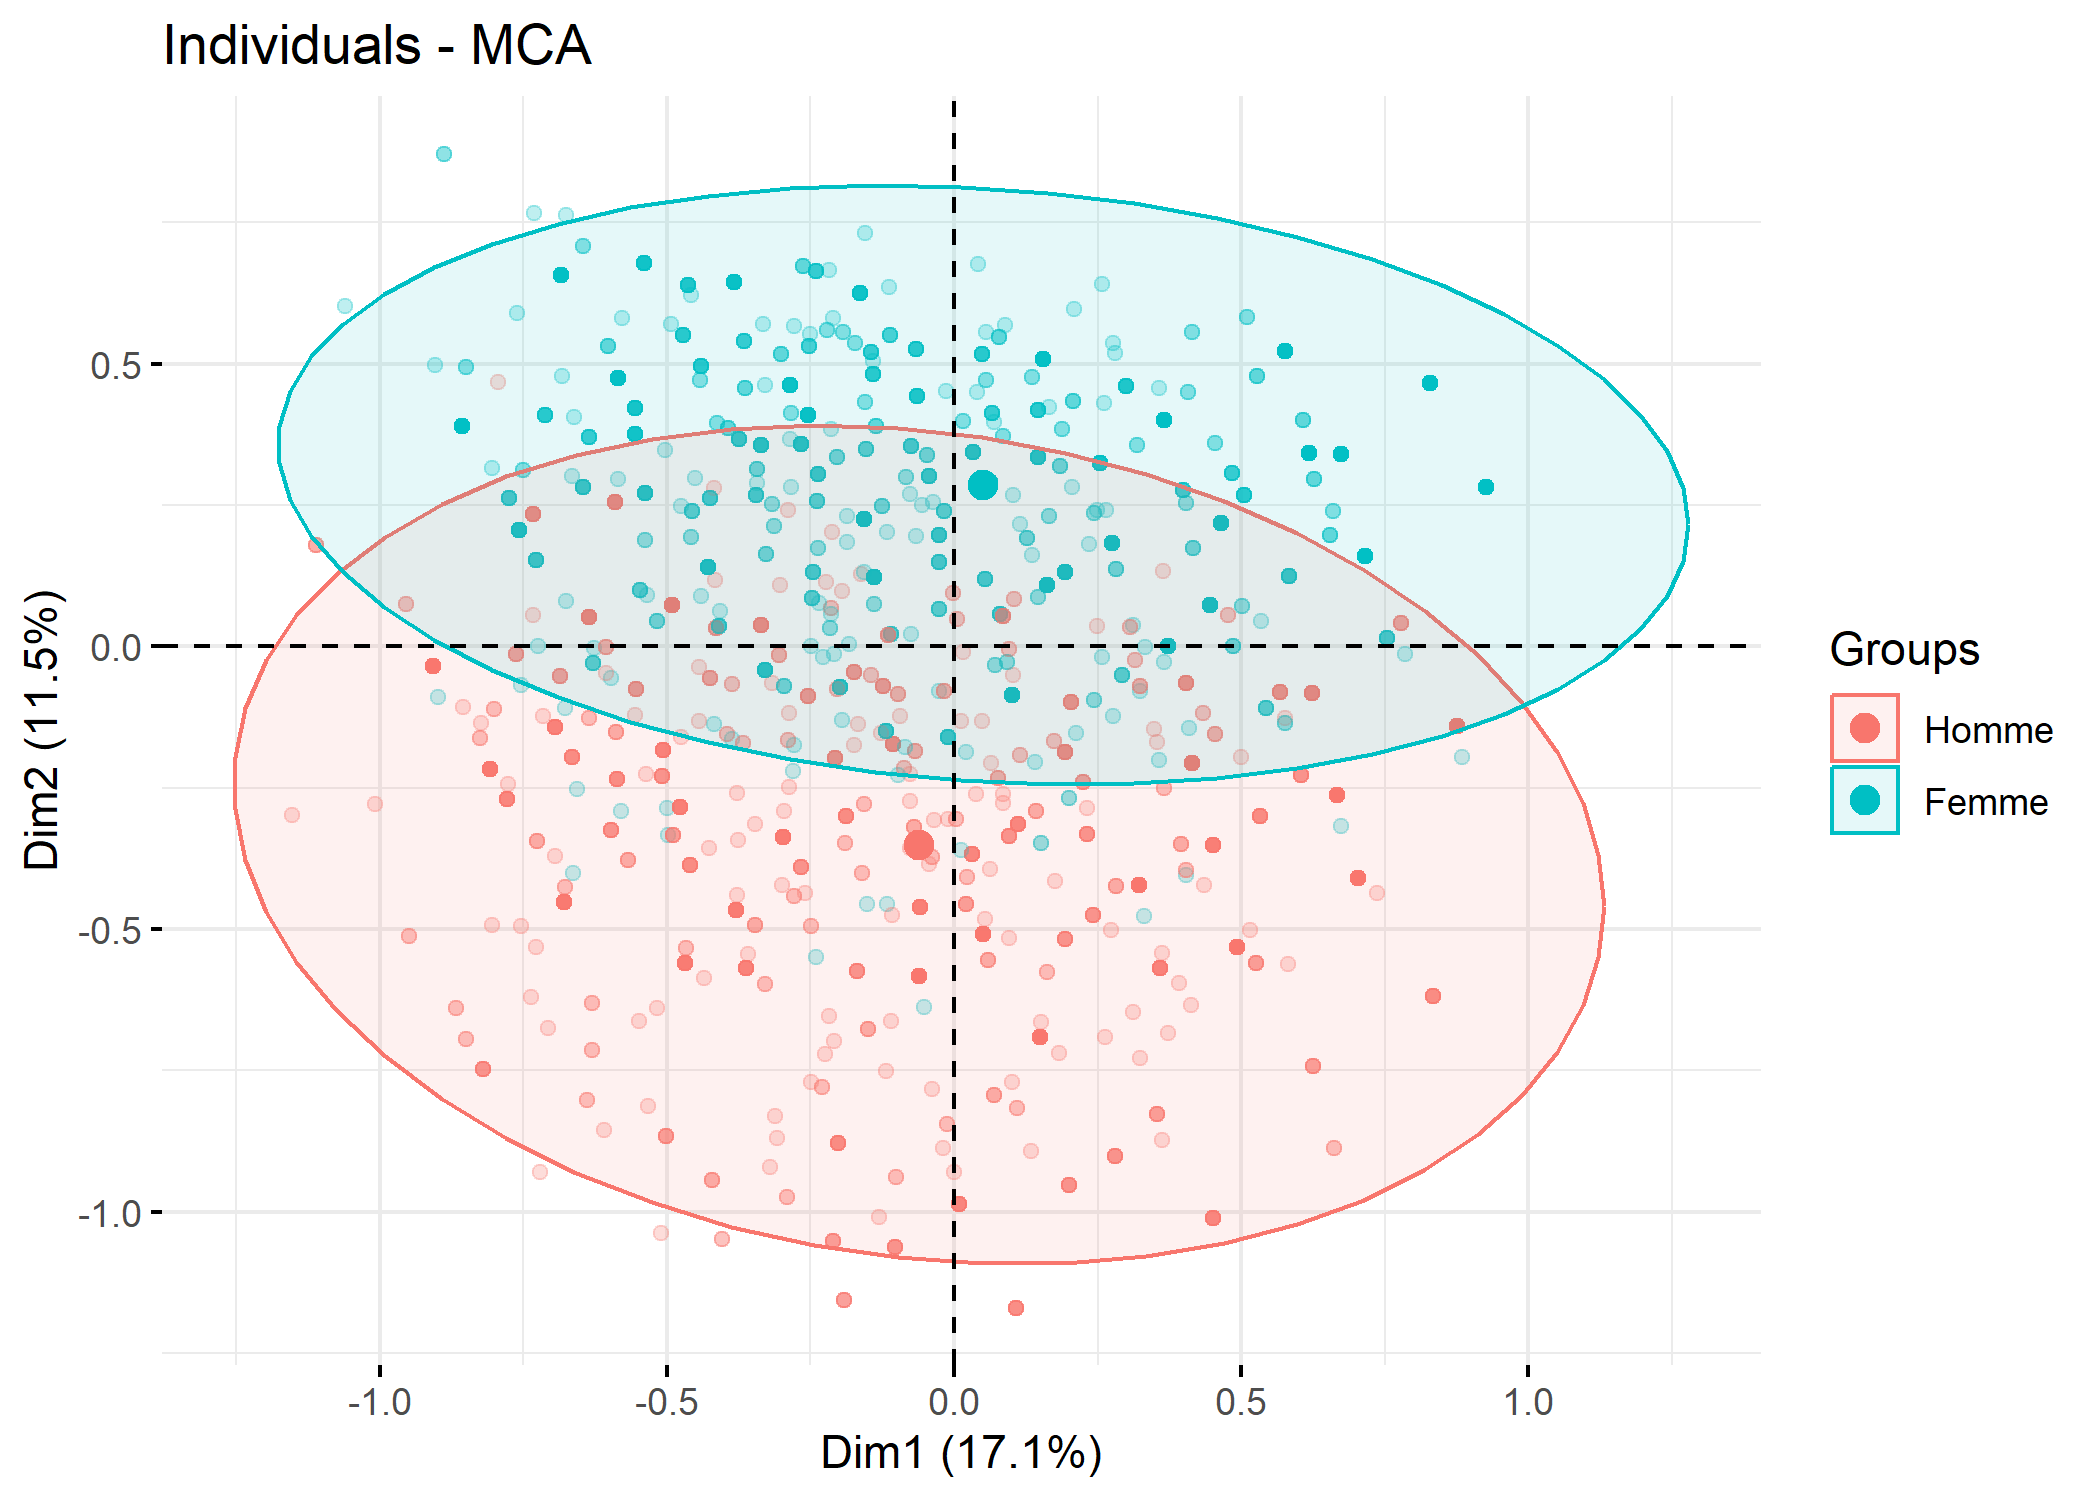
Most people stop at the scatter plot of active variables and categories. That is where it goes wrong. The coordinates tell you where each category sits relative to the origin, but the real information lives in the quality of representation values, or cos². A cos² below 0.3 on a given dimension means that point is not well explained by that axis, and placing too much weight on it is misleading. The contribution values tell you which categories are driving each dimension. If one category contributes 40% to Dimension 2, that dimension is essentially just that category versus everything else, and it is not a rich latent structure. I have seen people rotate dimensions by hand and call it refinement. Do not do that. MCA does not produce orthogonal rotations in the same way PCA does, and forcing a varimax rotation on MCA coordinates breaks the correspondence geometry.
Get the Full Details

Common pitfalls that destroy your results
The biggest issue is overfitting with too many variables. Every additional categorical variable adds categories, and sparse categories inflate the Burt table artificially. In practice, I cap active variables at around 20 to 25. Beyond that, the signal-to-noise ratio degrades quickly. Another problem is treating MCA like a clustering algorithm. It produces continuous coordinates, not clusters. If you want groupings, run a hierarchical climb on the MCA coordinates after the fact, using Ward's method on Euclidean distances. That gives you something stable. Missing data is handled automatically by MCA—missing categories just do not receive a coordinate—but if your missingness is structured rather than random, you are silently biasing the inertia distribution. I once spent two weeks chasing an odd Dimension 3 that turned out to be driven entirely by a survey design artifact where one question was only shown to half the respondents. The fix was to identify the conditional question structure and either code it as a supplementary variable or remove it from the active set.
When MCA is the wrong tool
If your variables are ordinal with many ordered levels, MCA treats them as purely nominal and throws away the ordering information. Use a polychoric PCA or a specific ordinal factor model instead. If you have a mix of continuous and categorical variables, MCA cannot handle the continuous part natively—you would need to discretize first, which introduces arbitrary breakpoints and loses information. A multiple factor analysis or a generalized PCA is more appropriate there. Key references: The factominer package documentation covers the R implementation thoroughly. For the statistical foundations, Greenacre's work on correspondence analysis is the standard reference. Lebart, Morneau, and Piron cover the French theoretical framework in detail if you need the deeper math.