Why Your PID Controller Keeps Oscillating Even After You Tune It
I spent three weeks debugging a thermal chamber controller last year. The specs looked fine on paper, the Bode plots were clean, the phase margin was 60 degrees like it should be. But when we powered it up, the temperature would overshoot by 15 degrees and then ring for nearly two minutes before settling. The problem wasn't the tuning. The problem was that the actuator had a dead zone of about 8 percent, and nobody had modeled it in the design phase. Classical methods assume linear systems. The real world doesn't care about that assumption. Classical control is root locus, Bode plots, Nyquist criteria, and lead-lag compensation. It works in the frequency domain and the s-domain. You design controllers for single-input single-output systems. Modern control is state-space, pole placement, Kalman filtering, LQR, and observer design. It handles multi-input multi-output problems and gives you direct access to internal states. In practice, most working control engineers use both. You use classical methods to get intuition about bandwidth, stability margins, and disturbance rejection. You use modern methods when the system is genuinely multi-variable or when you need optimal state estimation. The transition between the two isn't clean. That's where most people get stuck.
When Classical Methods Fall Short and What to Do About It
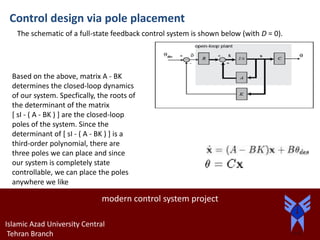
Pole placement sounds straightforward. You pick your desired closed-loop poles, solve the Ackermann formula, and you're done. It's not. The catch is that arbitrary pole placement without considering actuator saturation will give you a controller that demands more current than your motor can provide. I designed a position controller for a servo system once and placed all four poles at -5. The simulation looked perfect. The hardware response was a mess because the control signal blew past the amplifier's voltage limit on every step input. I ended up adding an anti-windup scheme and retuning the poles to -2 with a deliberate tradeoff in response speed. The system became acceptable instead of theoretically optimal. That's usually the right call. Another thing nobody warns you about early on: the difference between continuous-time design and discrete-time implementation. You design a compensator in the s-domain using root locus. You convert it to z-domain using Tustin's method with a sampling rate of 1kHz. Everything looks stable. Then you implement it and the system oscillates at high frequency. The issue was that the anti-alising filter wasn't aggressive enough before the ADC, and the sampling rate created a hidden resonance around 400Hz that the continuous design never accounted for. The fix was dropping the sampling rate to 500Hz and adding a proper analog anti-aliasing filter with a 100Hz cutoff. The controller performance didn't suffer because the system dynamics were well below 100Hz anyway.
State Observers: The Part Everyone Skips
You can't measure every state variable in a real system. Temperature sensors exist. Current sensors exist. But things like internal stress, wear-induced friction changes, or unmeasured load torques don't have cheap sensors attached to them. That's where observers come in. A Luenberger observer reconstructs unmeasured states from the measured outputs and the system model. An extended Kalman filter handles nonlinearities. A standard Kalman filter handles stochastic disturbances. Here's the practical problem: observer design requires an accurate model. If your plant model has a 10 percent error in the A matrix, your observer gains will place the estimation error poles incorrectly and your state estimates will drift. I worked on a flight control system where the observer was designed assuming linear aerodynamics across the full flight envelope. When the aircraft went into a high-angle-of-attack maneuver, the linear model broke down and the estimated angle-of-attack drifted by several degrees. We added a gain-scheduled observer that switched between three different linear models based on dynamic pressure. It wasn't elegant. It worked.
Get the Full Details

LQR and the Cost Matrix That Actually Matters
LQR minimizes a quadratic cost function J = integral of x^T Q x + u^T R u dt. Pick Q and R, solve the Riccati equation, get your gain matrix K. Simple on paper. The art is in choosing Q and R. Beginners pick identity matrices and wonder why the controller either moves too slowly or burns through actuator authority. The Q matrix weights state deviations. The R matrix weights control effort. If R is too small relative to Q, the controller becomes aggressive and saturates. If R is too large, the system responds sluggishly. I found that scaling Q by the inverse of the maximum allowable state deviation and R by the square of the maximum allowable control input gives a starting point that's usually within 20 percent of the final tuned values. From there, I run simulations with realistic disturbance profiles and adjust. This approach typically cuts the tuning time from a day of trial and error to about 30 minutes of targeted iteration.
Where Both Methods Fail Completely
Linear control theory assumes linearity. Time-invariant systems. Known disturbances. When any of those assumptions break, classical and modern linear methods either degrade gracefully or fail catastrophically. Strong nonlinearities like backlash, hysteresis, or Coulomb friction require describing functions or feedback linearization. Time-varying systems need adaptive or robust control techniques. Systems with significant unknown dynamics benefit from H-infinity synthesis or mu-synthesis, but those methods are computationally heavy and the resulting controllers are often high-order and difficult to implement on embedded hardware. Piecewise linear models work well for systems with distinct operating regions. Sliding mode control handles uncertainty aggressively but introduces chattering that can damage actuators. Model predictive control is powerful but requires solving an optimization problem at every sample time, which means you need a fast processor and you need to carefully manage the prediction horizon and constraint handling. There's no free lunch here.
A Practical Workflow That Actually Works
Start with the plant model. Get it from manufacturer data sheets, system identification, or first-principles derivation. Verify it against step response data before doing anything else. A model that doesn't match reality is worse than no model because it gives you false confidence. Design the outer loop using classical methods. Determine the required bandwidth from your specifications. Check phase margin and gain margin. Add compensators as needed. Then move to state-space representation and design the observer if you need full-state feedback. Combine the controller and observer using separation principle. Simulate with realistic initial conditions and disturbances. Implement with anti-windup, saturation limits, and a proper discretization strategy. Test on hardware and iterate. This workflow usually takes about two weeks for a moderately complex single-loop system. Multi-loop MIMO systems with observers and constraints can take six to eight weeks depending on how much model uncertainty you're dealing with. Budget accordingly.