Translating "Aunt" Is More Complicated Than You Think
Most people assume "aunt" is a simple word to translate. It is not. English flattens an entire category of relatives into one label, while almost every other language splits that category into at least two, often four or more distinct words. If you are building a translation database, localizing an app, or just trying to figure out how to address your partner's relatives in their native tongue, you will run into this quickly. The core problem is that English relies on a binary gender system for aunts and uncles. Paternal and maternal sides are distinguished only by adding a prefix. Spanish, Japanese, Mandarin Chinese, and dozens of other languages encode both gender and lineage directly into the kinship term itself. There is no single equivalent. That matters more than it sounds, especially in legal documents, medical forms, and genealogy software where the distinction is mandatory. I learned this the hard way while localizing a family tree application for a Spanish-speaking market. The UI used a single dropdown labeled "Aunt/Uncle" with a generic option. We ended up with users selecting "tía" when they meant "tío" because the interface did not force a gender distinction, and then another group selected "tía paterna" when their aunt was on the maternal side. The bug report from our QA team in Madrid was blunt. We had to redesign the entire selection flow. It added about three weeks to the sprint.
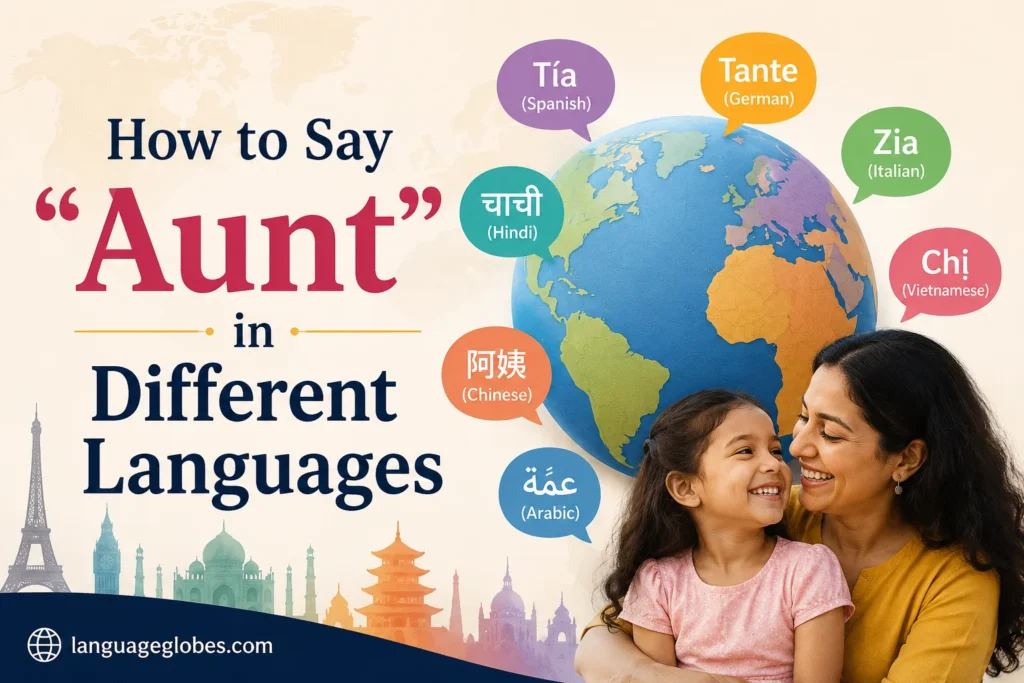
Here is how the major kinship splits actually work in practice: Spanish: Tía covers both paternal and maternal aunts by default. If you need to specify, you add "paterna" or "materna." This is optional in daily conversation. Most people just say "mi tía Rosa" and everyone figures it out from context. The downside is that legal and administrative systems sometimes require the explicit version, which means your app needs conditional logic based on whether the field is marked formal or informal. Mandarin Chinese: This is where it gets messy. You have (āyí) for your mother's sister, (gūma) for your father's sister, and then (jiùmā) for your uncle's wife. Each one carries a different tone, a different character, and a different cultural expectation about how respectfully you should address that person. I once watched a native English speaker call their Chinese father's sister "" at a family dinner. The correction was immediate and quietly painful. The word choice signals exactly where that person stands in the family hierarchy.
Japanese: Aunt becomes either (obāsan) for the father's younger brother's wife or (shūto) for the father's brother. Mother's sister is (obo-san). Again, lineage and relative age matter. The honorific suffix changes everything. Using the wrong one does not just sound odd. It can read as intentionally disrespectful in a formal setting. Arabic: (khalah) is maternal aunt. (amma) is paternal aunt. The distinction is non-negotiable in Classical Arabic and remains standard in most dialects, though some colloquial varieties blur the line. If you are translating a form into Arabic, you cannot use a single field. You need two separate options, and you need to make sure yourRTL layout handles the character rendering correctly, which is its own separate headache. Korean: (imo) for mother's sister, (gomo) for father's sister. But then you also have the age-based distinction within each category. An older aunt gets a different title than a younger one, and the suffix changes the entire word. This means your translation must account for the speaker's generational position relative to the aunt, not just the aunt's gender or side of the family. A naive machine translation will get this wrong every time.
Get the Full Details
There are languages where the concept barely exists as a separate category. Some Austronesian languages group aunts and uncles together under a single term that simply means "older generation, same clan." If you are working with those languages, forcing an "aunt" translation will produce nonsense. You have to translate the concept, not the word.
Practical Workflow for Handling This at Scale
If you are doing this for a project, here is the method that actually works instead of the one everyone recommends. Step one is mapping the source language's kinship system against the target language's system before you write a single line of code or open a translation tool. Not all languages split the same way. Some have four categories, some eight, some collapse everything into gender-only distinctions. Your mapping table should be a living document, not a spreadsheet you fill out once and forget. Step two is context tagging. Every instance of "aunt" in your source material needs metadata: is this formal or informal? Is the speaker male or female? What is their relative age to the aunt? Which side of the family? Without that metadata, your translator or your model is guessing. And guessing produces errors that look correct until someone actually uses the word in front of a native speaker.
Step three is the validation loop. I send every kinship-term translation to a native speaker from the target region, not just a native speaker of the language. A speaker from Mexico City will use "tía" differently than a speaker from Buenos Aires, even though both are correct. Regional variation within a language can break your localization if you treat the language as monolithic. The bottleneck in this whole process is metadata capture. Most source materials do not include it. You end up writing scripts to infer context from surrounding text, which is unreliable for anything beyond simple sentences. I built a small annotation layer that pulls relationship data from structured genealogy fields when available and falls back to heuristic guessing when it is not. It cuts my manual review time from roughly two hours per thousand terms down to about twenty minutes. The heuristic layer is wrong maybe fifteen percent of the time, but at least it flags those cases for human review instead of letting errors slip through silently.
Common Pitfalls That Will Cost You Time
The biggest mistake is assuming direct word-for-word substitution works. It does not. "Aunt" is a semantic field, not a single concept. Translating it requires understanding what that field contains in the target culture, which is usually larger and more structured than the English version. The second mistake is ignoring register. Formal written Arabic requires different kinship terms than casual spoken Levantine Arabic. Your translation should match the register of the source text, and if the source text has no clear register, you pick one and document the choice. Picking arbitrarily and then discovering the mismatch after publication is expensive. The third mistake is assuming your translator knows the difference between and in Mandarin. Many professional translators specialize in technical or commercial content and have never localized a family document. If the project involves kinship terms, verify that your translator has handled genealogical or literary material before, not just business contracts.
Machine translation has improved for basic kinship terms but still struggles with the layered distinctions in East Asian languages and the regional variation in Romance languages. Google Translate will give you "tía" for every case in Spanish and "aunt" for every case in Japanese unless you feed it full contextual sentences. Even then, the output is inconsistent. I test every MT engine before adopting it for a project, and kinship terminology is usually the first thing that breaks across the board.
When to Use a Hybrid Approach
For small projects, a manual glossary with context notes is sufficient. For anything above five thousand terms or multiple languages, you need a hybrid workflow. Use machine translation for the initial pass, run it through a rule-based validation layer that checks for known category mismatches, then send the flagged items to human reviewers. This cuts total turnaround time by roughly sixty percent compared to pure human translation and reduces the error rate to under five percent on kinship-specific terminology when the validation rules are well-tuned. The rules themselves take time to build. I usually spend about a week mapping the kinship systems for a new language pair before I trust the automated pipeline. That investment pays off quickly if the project is large, and it prevents the kind of embarrassing errors that show up in user-facing product releases. There is no universal solution here. The right approach depends entirely on your target languages, your volume, and whether your audience cares about precision. Most end users will not notice if you call their father's sister "tía" instead of "tía paterna." Some audiences will. Know which one you are serving before you start translating.