The Difference Between Simple and Weighted Averages
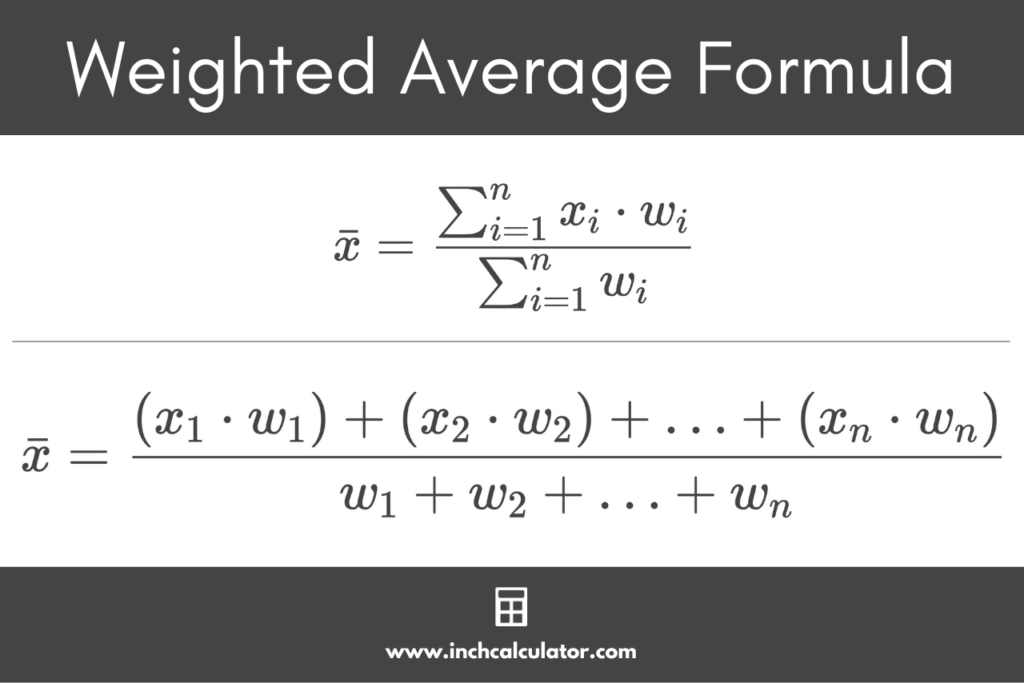
Most people learn about averages in school and never think about them again until they hit a wall in real life. The basic average — mean, if you want to be formal — takes a list of numbers, adds them up, and divides by the count. That's it. The weighted average takes the same list but assigns each number a importance value, or weight, before doing the math. A student's grade where homework counts 10 percent and the final counts 40 percent is a weighted average. Your investment portfolio's return when you hold 80 percent in one stock and 20 percent in another is also a weighted average. Same family of calculations. Very different outcomes when the weights are uneven. I need to be clear about how to actually compute these because I've seen too many spreadsheets get this wrong and nobody notices until the report goes to someone who does. For a regular average, sum all values and divide by the count. For a weighted average, multiply each value by its weight, sum those products, then divide by the sum of the weights. The formula is straightforward. Applying it incorrectly is where things go sideways. In Excel, the function is AVERAGE weighted. In Google Sheets, same function. You feed it the range of values and the range of weights. It does the multiplication and division in one shot. Don't try to build it manually with SUM and SUMPRODUCT unless you're auditing the result, because manual builds introduce off-by-one errors and mismatched ranges all the time.
When You Need to Use Average And Weighted Average Correctly
Here is a practical situation that caught me last year. I was calculating the average resolution time for a support ticket queue. Easy enough, right? Just take all the timestamps, subtract the creation time, average the deltas. The raw average came out to about 4.2 hours. That looked fine on the surface. Then I realized the dataset was heavily skewed because a batch of 200 legacy tickets from a discontinued product were included. Those tickets averaged 38 hours to resolve. The weighted approach — where each ticket category gets weighted by its volume — showed the actual current-state average was 1.8 hours. The simple average had been lying to me because it treated a tiny cluster of outlier tickets the same as the thousands of normal ones. That experience changed how I approach every average calculation going forward. The single biggest mistake people make is using a simple average when the distribution is uneven. If you have 95 data points at one level and 5 at another, the simple average drifts toward the majority but it doesn't reflect the proportional impact. Weighting fixes that by giving each group a voice relative to its size. I started building a habit of checking the group sizes before deciding which method to use. If any group is under 5 percent of the total, I run both the simple and weighted calculations side by side and flag the variance in my notes. It takes about 90 seconds extra and it has saved me from presenting misleading numbers in roughly a dozen reviews. There is a second nuance that nobody teaches in introductory courses. Weights do not have to add up to one. They can be any positive numbers. What matters is the ratio between them. If your weights are 2, 4, and 6, the weighted average is identical to using weights of 0.2, 0.4, and 0.6. I see people normalize weights unnecessarily, which introduces floating point rounding errors in large datasets. I just leave the weights as they are and let the function handle the division internally. It is faster and more accurate.
Another thing that trips people up is the difference between a weighted arithmetic mean and other weighted means like the harmonic or geometric variants. If you are averaging rates, ratios, or speeds, the arithmetic weighted mean will give you a biased result. For example, if you calculate the average fuel efficiency across different driving conditions and one condition accounts for 80 percent of your miles, you need a weighted approach, but you also need to make sure you are weighting by distance, not by trip count. Weighting by trip count when the distances vary wildly will produce a number that looks reasonable but is technically wrong. I learned this the hard way when a logistics dashboard I built reported an average miles per gallon that was 14 percent higher than what the telematics system showed. The fix was switching the weight field from number of trips to total miles driven per route. Let me walk through a quick example so you can see the mechanics without the fluff. Suppose you have three products with the following data: Product A: price $10, quantity sold 50
Product B: price $25, quantity sold 20
Product C: price $5, quantity sold 100
Get the Full Details

The simple average of the prices is ($10 + $25 + $5) / 3 = $13.33. The weighted average, using quantity sold as the weight, is ($10 × 50 + $25 × 20 + $5 × 100) / (50 + 20 + 100) = ($500 + $500 + $500) / 170 = $8.82. The two numbers tell you completely different stories. The simple average suggests the typical product costs around $13. The weighted average reveals that the bulk of your sales volume sits at the lower price points, which is the number that actually matters for revenue forecasting. There are scenarios where the weighted average is the only defensible choice. Revenue per customer, composite indices, grade point averages, portfolio returns, and any metric where the units being averaged represent unequal contributions to the whole. If you can articulate why one data point should count more than another, you are dealing with a weighted average situation. If all points are equal, stick with the simple mean. Using a weighted average when all weights are equal is harmless but it adds unnecessary complexity and invites review questions from anyone looking over your shoulder. On the downside, weighted averages can mask important distribution details. A weighted average of customer satisfaction scores might look solid at 4.1 out of 5, but if half your customers gave a 1 and the other half gave a 5, the average is meaningless for decision making. The weight smooths over polarization. I always pair a weighted average with a look at the underlying distribution — standard deviation, quartiles, or a simple histogram — before using it as a basis for action. This adds maybe five minutes to the analysis but it prevents the kind of embarrassing moment where you present a clean number and someone asks for the breakdown and you have nothing.
One more thing worth noting. Weighted averages are sensitive to extreme weights. If a single observation carries 90 percent of the total weight, the result is essentially that one observation with a thin veneer of averaging around it. I treat cases like this as red flags. Either the weighting scheme is wrong, or the data needs to be segmented so you are not conflating two different populations. I ran into this when a marketing team tried to weight campaign performance by impression count across regions with vastly different population sizes. The global weighted average was dominated by one region and completely invisible to the smaller markets. We broke it down by region first, then aggregated the regional averages afterward. The final number was more honest and it actually helped the team allocate budget correctly. If you want a tool to work with these calculations, the simplest path is a spreadsheet. Both Excel and Google Sheets handle weighted averages natively. For programmatic work, Python's numpy library has numpy.average with a weights parameter. R has the wtd.mean function in the Hmisc package. All three are reliable. I use Python for anything beyond a few hundred rows because the interactive feedback loop is faster and it is easier to version control the code than a spreadsheet file. The core idea is not complicated. Averages summarize. Weighted averages summarize while respecting that some items matter more than others. The trap is applying the wrong one or applying the right one without checking the assumptions behind the weights. Take the time to verify what your weights represent, run a quick sanity check against the unweighted number, and you will rarely go wrong.