Setting Up a Functional Workspace on Azure Data Science Vm
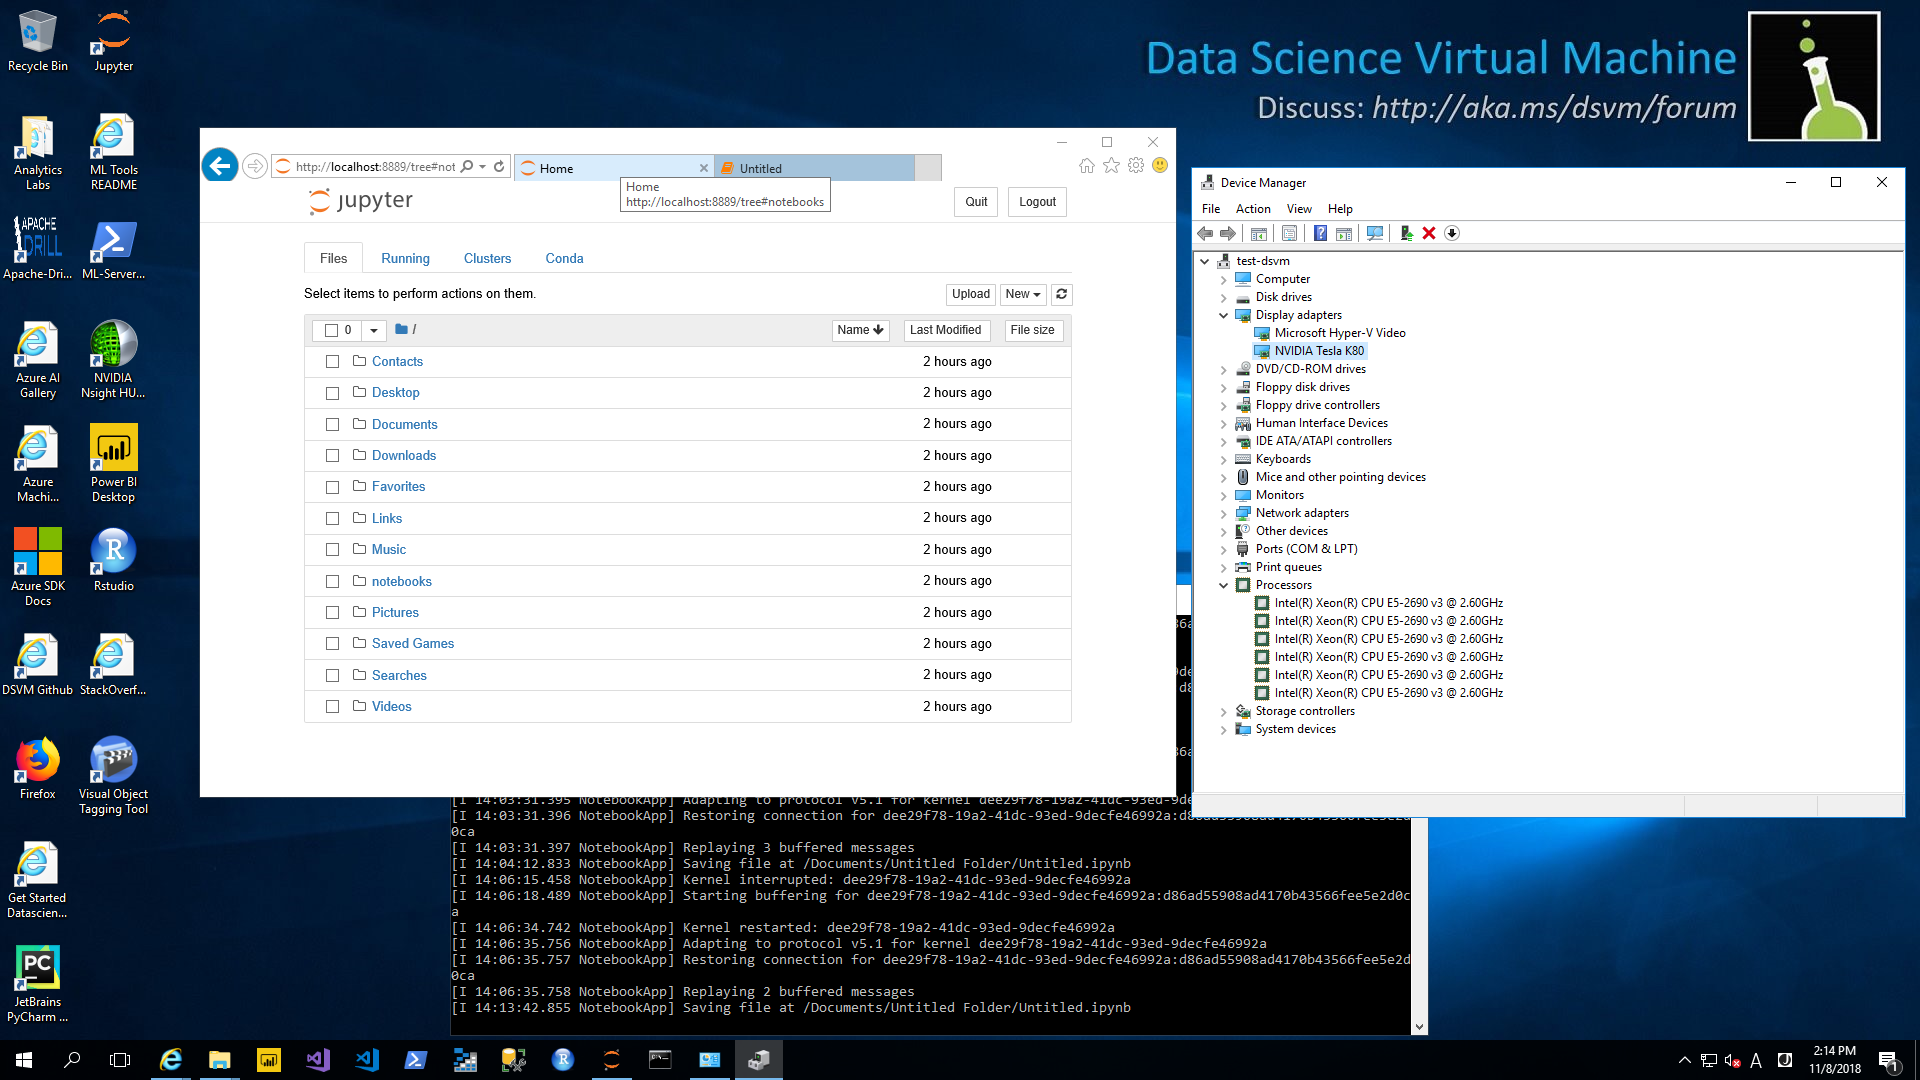
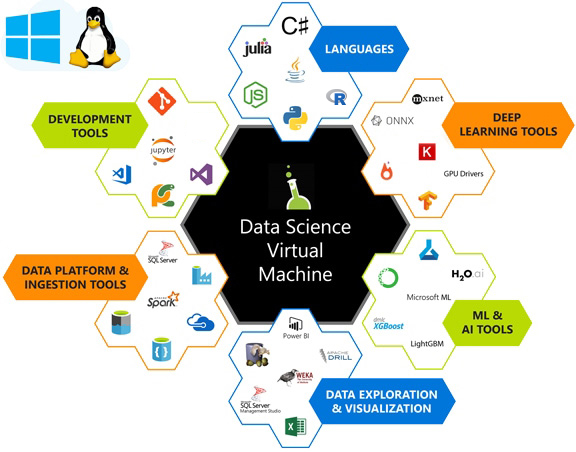
The Azure Data Science Vm is essentially a preconfigured virtual machine image that comes with Python, R, Jupyter, and a handful of data science toolkits already installed. It exists because spinning up a clean Ubuntu or Windows instance and manually installing scikit-learn, TensorFlow, PyTorch, and all their dependency chains eats half a day of productive time. Azure saves you that. But having the tools preinstalled doesn't mean everything just works out of the box. I learned that the hard way during a production model training run. To provision one, you navigate to the Azure Portal, create a new virtual machine, and search the marketplace for "Azure Data Science Virtual Machine." You can choose between Ubuntu Server or Windows Server 10 as the base. The Ubuntu image tends to be more popular in the ML community. Pick a Standard_NC-series or Standard_ND-series GPU-enabled instance if you plan to train deep learning models, or stick with a Standard_D or E-series for lighter data engineering and EDA work. Size your VM based on RAM and vCore needs, not just GPU count, because data preprocessing and large dataset loading often become the bottleneck before the actual training does. Once deployed, connect via SSH for Linux or RDP for Windows. The Linux version lands you on a JupyterLab environment that's already listening on port 80. The Windows version gives you a full desktop with Jupyter, VS Code, Anaconda, and Visual Studio preconfigured. Both require you to set admin credentials during the VM creation wizard, and both let you enable NSG rules for inbound traffic if you want to access Jupyter from outside your network.
Here is where people typically make a mistake. They assume the preinstalled conda environments cover everything they need. They don't. The base environment ships with a fixed set of packages pinned to specific versions. If your project requires a newer CUDA toolkit version than what came preinstalled, or if you need a package that conflicts with the stock TensorFlow version, you are going to spend time breaking things. I encountered this exact issue last year when trying to run a custom PyTorch distributed training job that required CUDA 12.1, but the VM shipped with CUDA 11.3 bundled into its drivers. The NVIDIA drivers on the VM were fine, but the CUDA toolkit libraries in the system path were mismatched. My workaround was straightforward but tedious: I created a fresh conda environment, installed the correct CUDA toolkit inside it using conda rather than the system install, and set the LD_LIBRARY_PATH temporarily for that session. It cost me about 45 minutes to untangle, and it cost me another hour because the first attempt overwrote some system Python paths and broke Jupyter's kernel detection entirely. I had to restore from a snapshot to get the base environment working again.
Day-to-Day Usage and Practical Gotchas
The VM is most useful as a temporary scratch environment. You spin it up, move your datasets and scripts over, run your experiments, and then tear it down. That workflow saves money because you only pay for compute while you actively use it. Stopping the VM through the Azure portal deallocates it and stops billing for compute resources, though you still pay for any attached managed disks and persistent storage. I keep my datasets on an Azure Files share or a Blob container mounted to the VM rather than storing them locally on the managed disk. That keeps the VM slim and lets me attach it to different VMs without carrying gigabytes of data with each deployment. One thing that trips up almost everyone is GPU memory management. The VM image comes with the NVIDIA container toolkit configured for Docker, which is great if you run your training jobs inside containers. But if you launch training scripts directly on the host, the GPU driver and CUDA version are shared across whatever processes you start. I once had a situation where a background Jupyter notebook was quietly holding 6 GB of GPU memory from a previous session, and my new model training script was failing with an out-of-memory error that made no sense because the model itself should have fit comfortably. Running nvidia-smi revealed the ghost process. Killing the notebook server and the orphaned Python processes cleared it up. This happens because JupyterLab does not always clean up GPU memory when kernels are closed improperly, especially after kernel crashes or force-stops. Another nuance that deserves mention is the networking setup. The default NSG rules allow HTTP and HTTPS but block most other inbound ports. If you need to run a custom REST API endpoint from Flask or FastAPI on a non-standard port, you have to add an inbound rule to the network security group. People forget this step and then spend time debugging why their model serving endpoint is unreachable from outside the VM when the issue was never about the code at all. It was just a firewall rule.
Get the Full Details

Limitations and When to Look Elsewhere
The Azure Data Science Vm is not a permanent solution. It is a convenience image, and convenience comes with tradeoffs. The preinstalled packages are useful for getting started quickly, but they are not always the latest versions. Upgrading system-level packages like TensorFlow or PyTorch can destabilize the Jupyter environment because Jupyter kernels are tightly coupled to the system Python installation. If you break the base environment, which is easy to do if you run pip install --upgrade on the root interpreter, you are back to restoring from a snapshot or redeploying the VM entirely. That recovery process takes time and interrupts work. The VM also does not include any managed services for MLOps. There is no built-in experiment tracking, no automated model registry, no CI/CD pipeline integration. If your workflow involves versioning models, logging metrics, and deploying to production, you need to bring your own tools. MLflow, Azure ML workspace, or something similar has to be set up separately. The VM handles the compute, nothing more. Some teams treat it as a full ML platform and end up frustrated when they realize it is just a VM with a toolbox. For production model serving, using the Azure Data Science Vm directly is generally a bad idea. It lacks autoscaling, load balancing, and the monitoring capabilities that dedicated serving infrastructure provides. If you are deploying a model to production, it is better to containerize the inference code and push it to Azure Container Instances or AKS. The VM should be used for development and experimentation, not for running models that real users depend on. That boundary matters more than people realize, and crossing it usually results in downtime during scale events.
Storage costs are another factor worth noting. Every attached managed disk incurs a per-gigabyte charge regardless of whether the VM is stopped. If you leave large VM disks attached and forget about them, the bill adds up quietly. I have seen teams accumulate several hundred dollars in unused disk costs simply because they deleted the VM but left the VHD behind. Always delete or detach disks you no longer need.
What Actually Makes It Worthwhile
Despite the drawbacks, the Azure Data Science Vm fills a specific gap well. When you need a sandboxed environment with a known set of tools and you cannot justify building one from scratch, it delivers. Setting up a comparable environment manually, including CUDA, cuDNN, conda, Jupyter, and the major ML libraries, typically takes three to four hours on a first attempt and longer if you hit version conflicts. The VM image compresses that into about ten minutes of provisioning time. For iterative prototyping, that speed is real and measurable. The image is also consistently updated by Microsoft, which means security patches and toolkit updates land without manual intervention. You still need to manage your own conda environments for project-specific dependencies, but the base layer stays reasonable. If you pair the VM with Azure Machine Learning workspaces for experiment tracking and with blob storage for dataset management, you get a setup that is flexible enough for most data science workflows without becoming overly complex. Just keep the scope contained to development and experimentation, stay disciplined about tearing down resources when you are done, and avoid treating it like a production hosting platform. That mindset shift alone prevents the majority of problems people encounter.