What Benfords Law Analysis Actually Is and Why People Get It Wrong
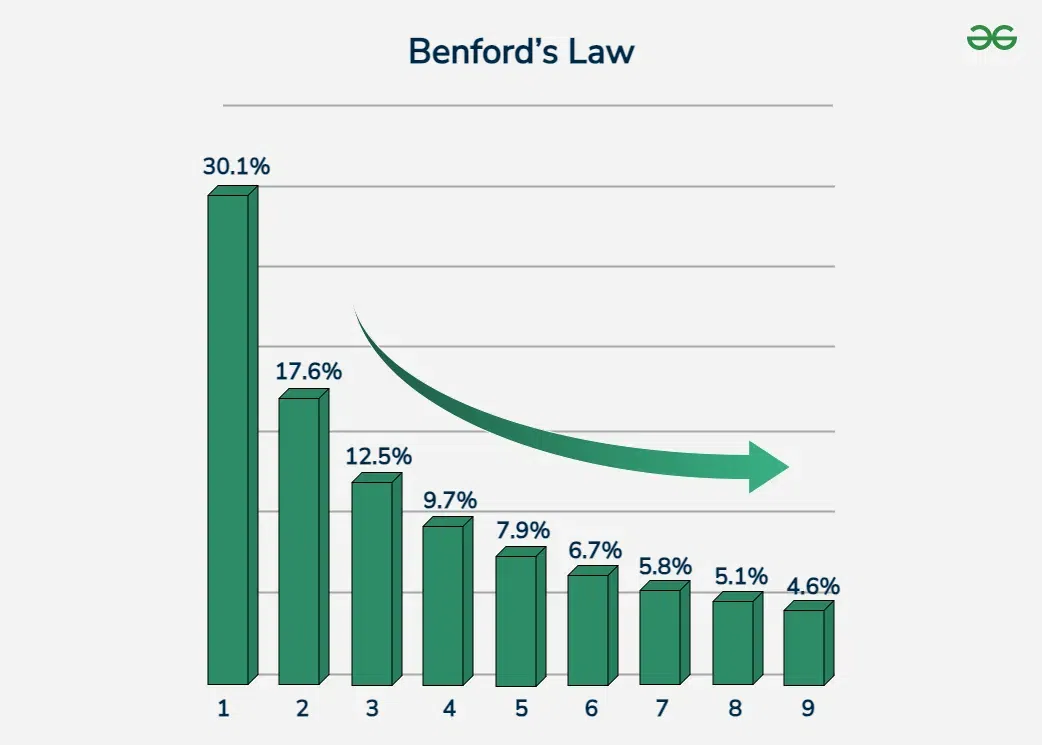
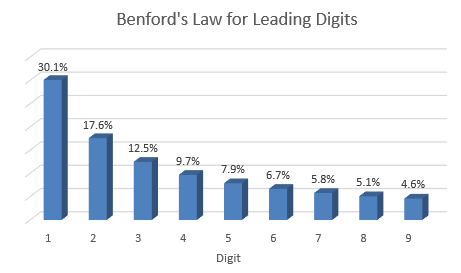
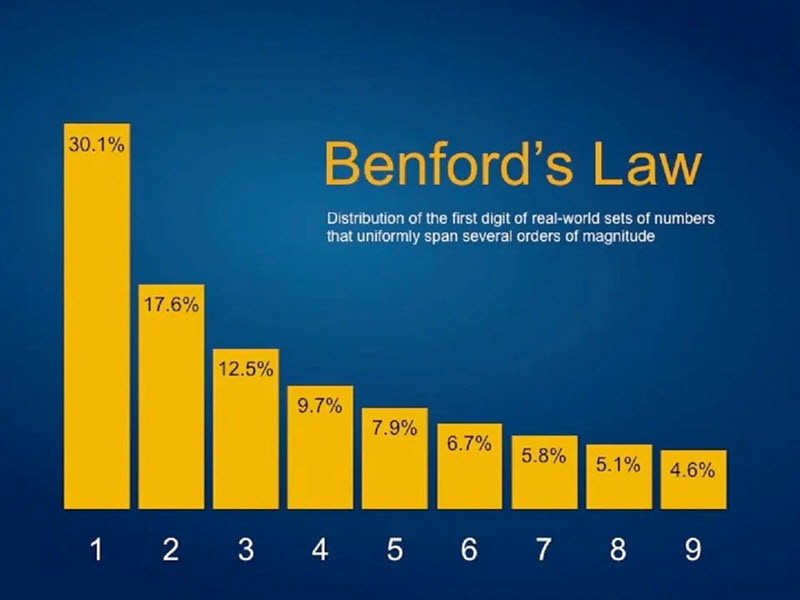
Most people encounter Benfords Law through a single sentence on a blog post that says leading digits aren't uniformly distributed, and then they assume that makes it simple to apply. It is not simple. The law itself is elegant in a mathematical sense, but the practical application is where things get messy. I first ran into this when a small accounting firm asked me to validate whether their accounts payable data showed signs of manipulation. The initial pass looked clean. The second pass, which I ran three months later after they'd added more transactions, flagged several vendors that the first analysis had missed entirely. The core principle is straightforward enough: in datasets that span several orders of magnitude and are not artificially constrained, the leading digit follows a logarithmic distribution where 1 appears about 30.1% of the time and 9 appears only about 4.6% of the time. What the principle does not tell you is which datasets qualify. A column of invoice amounts capped at $10,000 by company policy will look suspicious even if nothing is wrong. A list of employee IDs starting from 10001 will violate the law by design. The dataset has to meet certain conditions before Benfords Law Analysis is even worth running.
Running a Benfords Law Analysis From Scratch
The most common workflow people use involves pulling a raw dataset, extracting the first digit of each numerical value, and comparing the observed frequencies against the expected distribution. I tend to skip the manual spreadsheet approach because it introduces rounding errors and makes reproducibility nearly impossible. Instead, I write a short Python script using scipy and numpy. Here is what the core logic looks like: First, load your data and drop nulls. Second, take the absolute value of each number and divide by the appropriate power of 10 so everything falls between 1 and 10. Third, extract the integer part as the leading digit. Fourth, calculate the expected frequencies using log10(1 + 1/d) for each digit d from 1 to 9. Fifth, run a chi-squared goodness-of-fit test or a mean absolute deviation comparison. The MAD approach is generally more practical for forensic work because it is less sensitive to large sample sizes, which is usually a problem with financial datasets. I typically use MAD rather than chi-squared because with 50,000 transactions, even trivial deviations become statistically significant. That does not mean the data is fraudulent. It means the sample is large enough that the test detects noise. MAD gives you a single number that is easier to benchmark across different datasets. A MAD below 0.006 is generally considered a good match. Between 0.011 and 0.015 is suspect. Above 0.02 usually indicates the data is not naturally occurring or has been edited.
You can find working implementations on GitHub under repositories like benfordpy or fgbg. I also keep a lightweight Colab notebook that handles the digit extraction, expected calculation, and MAD scoring in under 30 lines. It saves me from rewriting the same boilerplate every time a new client sends a CSV.
Get the Full Details
Pitfalls That Make Beginners Look Unprofessional
The biggest mistake I see is applying Benfords Law Analysis to data that has already been filtered or truncated before the analysis even begins. Someone will pull invoices above a certain threshold, remove duplicates, or exclude a category of transactions and then wonder why the results look off. The law applies to the raw, unfiltered dataset. If you filter, you change the distribution, and the baseline expectation changes with it. Another common error is treating the leading digit test as a definitive proof of fraud. It is not. It is a screening tool. When I flagged that accounts payable dataset for the accounting firm, the initial Benfords pass showed a MAD of 0.004, which looked fine. But when I broke the analysis down by vendor and by month, two vendors in Q3 showed a clear spike in leading digit 7, which the aggregate view had smoothed out. The fraud was hidden in the subgroup, not the whole. Subgroup analysis is where the method actually becomes useful, and most people skip it entirely. There is also the issue of datasets that naturally conform to Benfords Law for the wrong reasons. Population figures, street addresses, and measurements like temperature or weight often follow the distribution without any connection to human behavior. A forensic auditor who cites Benfords Law as evidence of manipulation in a dataset of city populations is going to look foolish. The law describes the data, not the intent behind it.
When the Method Fails Completely
Benfords Law Analysis breaks down on data that is assigned rather than measured. Invoice numbers, order IDs, social security numbers, and sequential transaction codes are assigned by a system and will uniformly distribute their leading digits regardless of any underlying behavior. Running this test on those columns wastes time and generates false positives. I always check the data type and purpose before running the analysis, and I skip any column that is clearly an identifier rather than a quantity. It also fails on datasets with a narrow range. If your values all fall between 100 and 200, the leading digit will be 1 or 2 almost exclusively, and that has nothing to do with natural distribution and everything to do with the range constraint. The dataset needs to span multiple orders of magnitude. A rough rule of thumb is that the ratio between the largest and smallest value should be at least 100, ideally much larger. Below that, the law loses its predictive power. I encountered a specific edge case a while back involving a nonprofit that reported donation amounts. The Benfords analysis came back with a MAD of 0.018, which looked terrible. But when I plotted the raw distribution, I noticed a massive cluster around $50 and $100 donation prompts. Those are rounded amounts set by the organization's giving platform. The data was legitimate, just artificially rounded at common giving thresholds. I had to manually exclude those rounded clusters and rerun the analysis on the remaining irregular amounts, which brought the MAD down to 0.007. Without that adjustment, the conclusion would have been wrong.
Practical Workflow for Real Work
Here is how I structure a typical engagement when someone asks for a Benfords Law Analysis on their financial data. I start by getting the raw export with no filters applied. I verify the schema and flag any identifier columns that should be excluded. I run the initial MAD and chi-squared tests on the full dataset. Then I segment by date, by vendor, by account, or whichever dimension makes sense for the context. I compare the segmented MAD scores against the aggregate score to find where deviations concentrate. When I find a deviation, I do not stop at the statistic. I pull the actual transactions behind the flagged group and review them manually. The Benfords test tells you where to look. It does not tell you what you are looking for. In the accounts payable case, the flagged transactions turned out to be round-dollar payments to a single vendor that had recently changed its billing cycle. The pattern was operational, not fraudulent, but it required human judgment to confirm that. Automation gets you to the signal. Expertise tells you what the signal means. The method is useful because it is fast. A full analysis on a dataset of 100,000 rows takes about 15 seconds on a standard laptop. Manual review of those same rows would take hours. That speed is the real value proposition, not the statistical significance score. You use it to narrow the field, not to make a verdict.

Software Options and What I Actually Use
There are several tools available. Benford Analytics is a commercial product that many forensic firms license. It handles subgroup analysis and generates report-ready output. For lighter work, I use the benfordpy Python package, which I mentioned earlier. It installs via pip and works directly with pandas DataFrames. If you prefer R, the benford package is functional but less actively maintained. Excel-based solutions exist, but I avoid them because they force you into manual workflows that are easy to break and hard to reproduce. One thing most software does not handle well is mixed-scale data. If your dataset contains both dollar amounts and quantity counts in the same column, the digit extraction will produce garbage results. I always normalize the data by category before running the analysis. It adds five minutes to the process and prevents a lot of misinterpretation. The takeaway is that Benfords Law Analysis is a screening technique with real limitations. It works well on natural financial data spanning multiple orders of magnitude. It fails on identifiers, narrow-range data, and heavily rounded figures. The people who use it effectively are the ones who understand those boundaries and know when to stop trusting the numbers and start looking at the actual transactions.