Getting Started With Data Science Guides
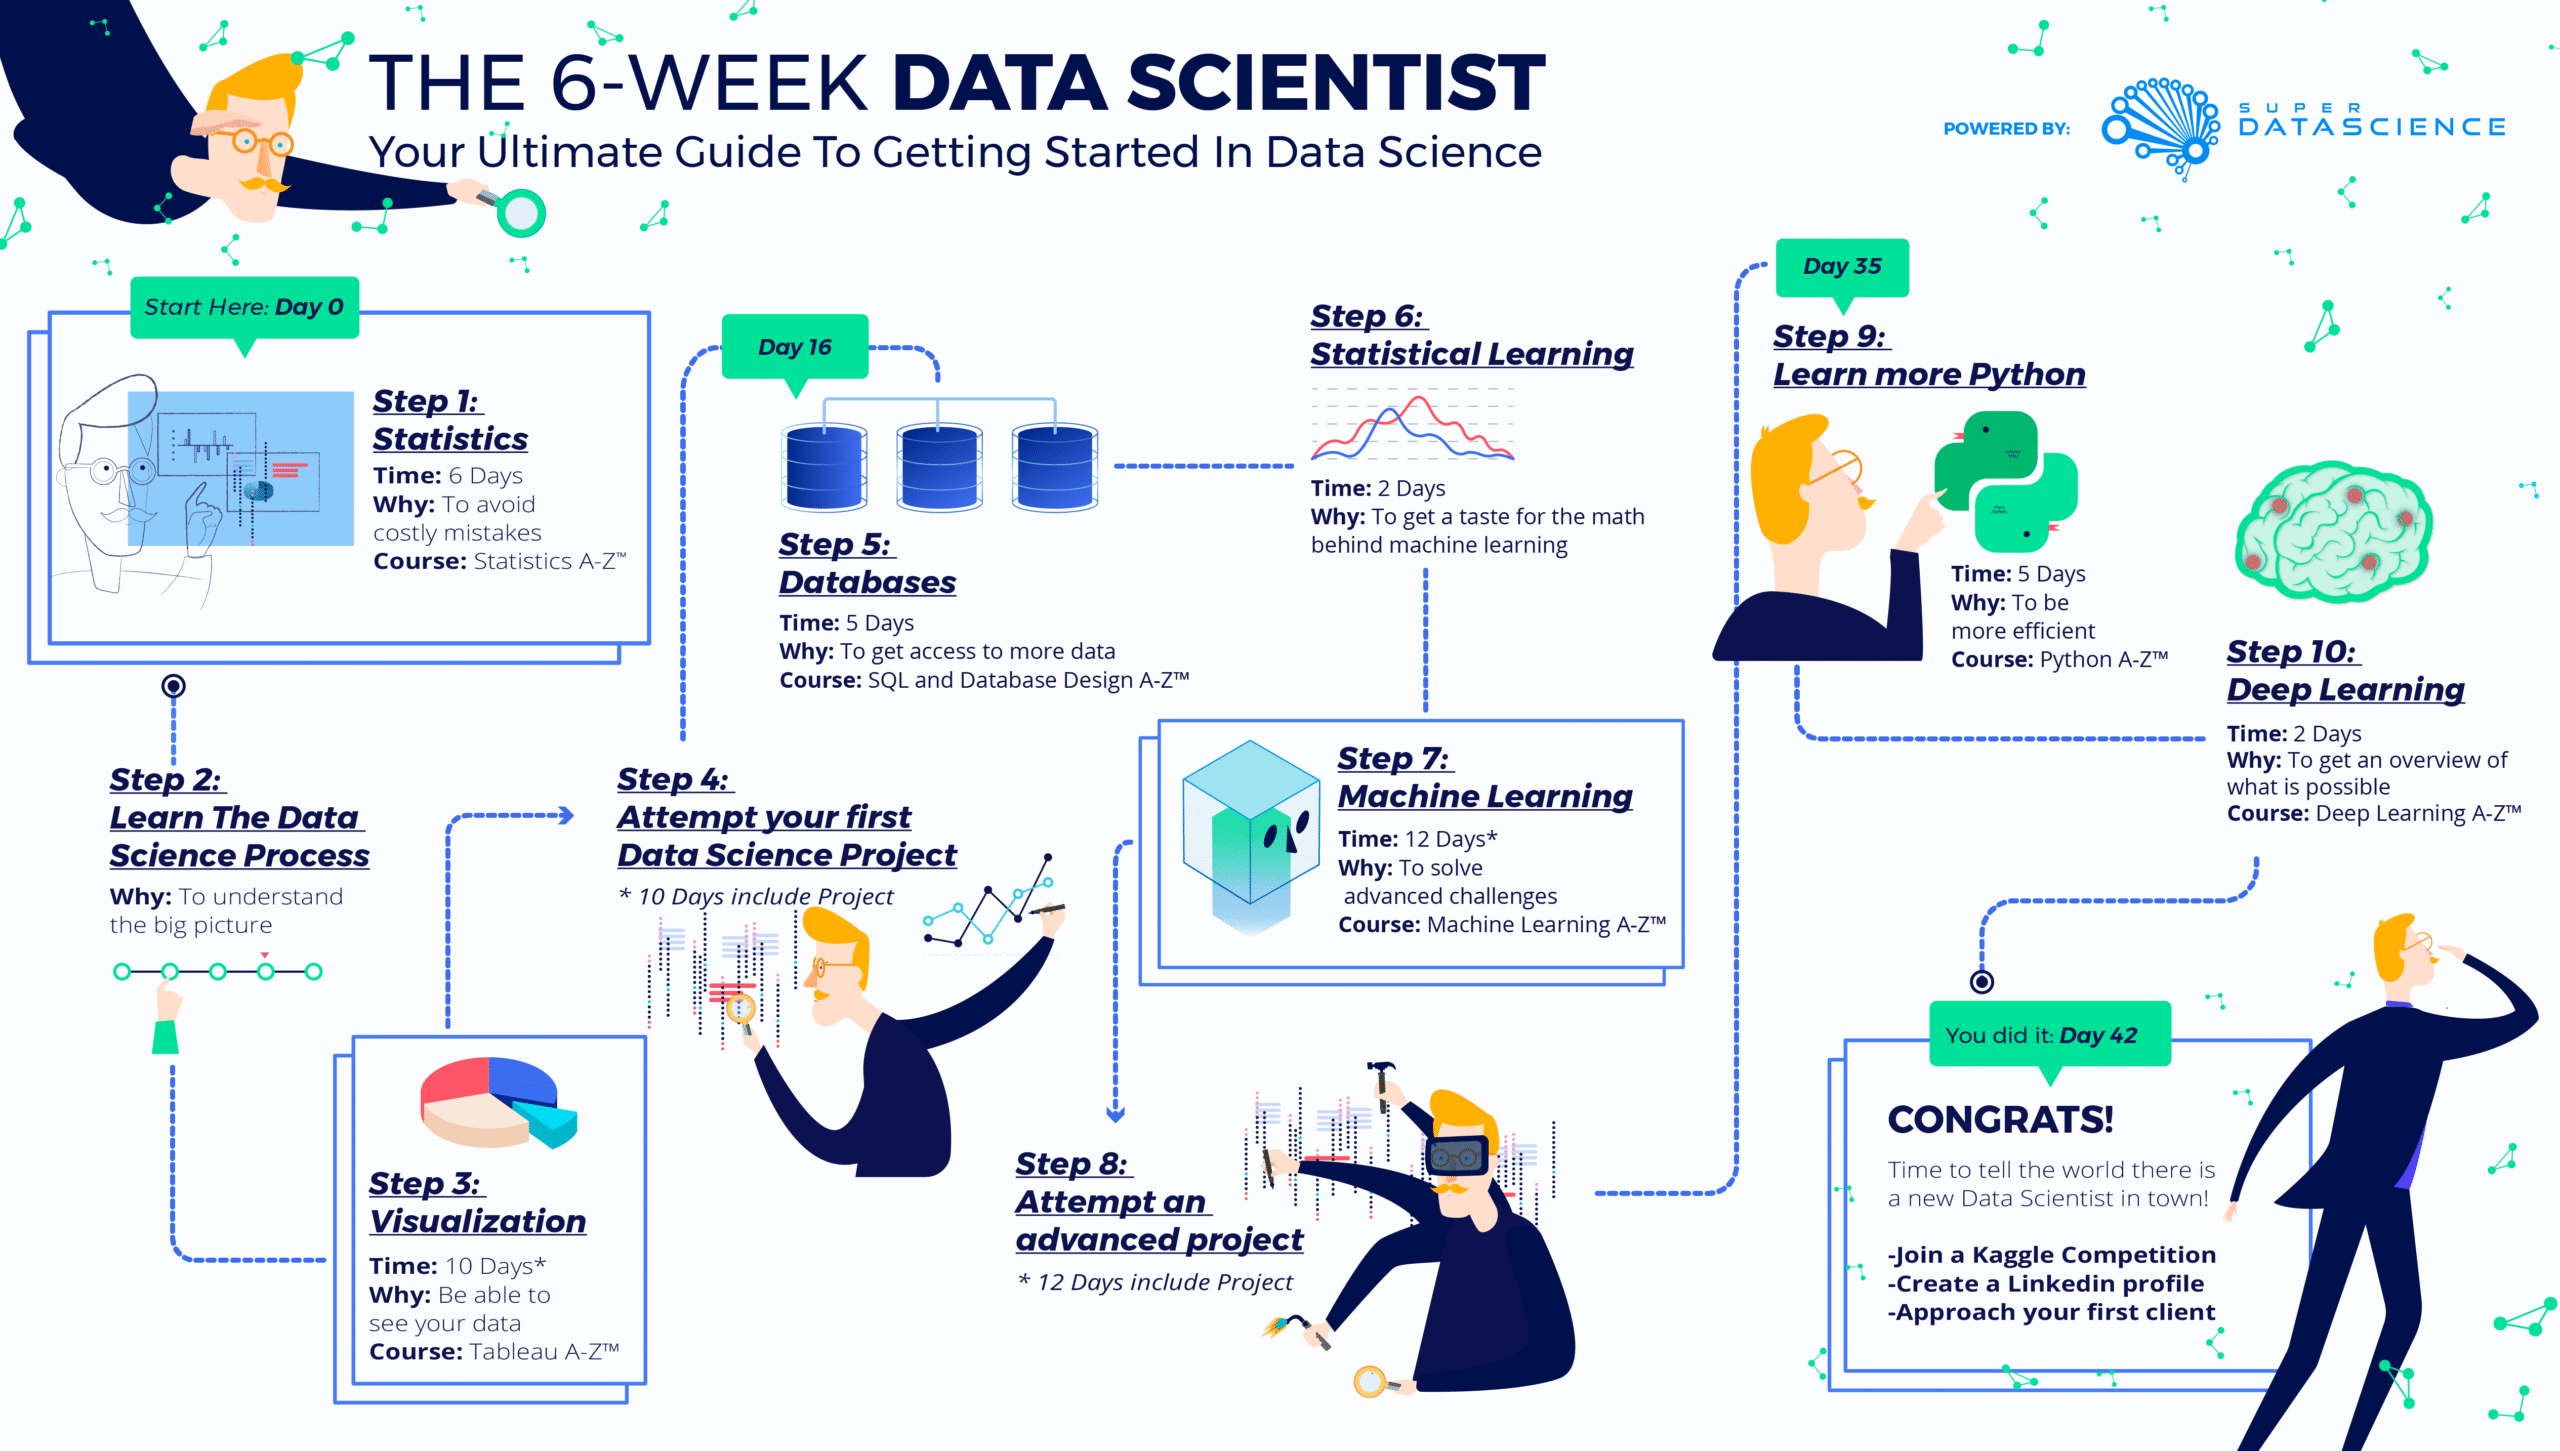
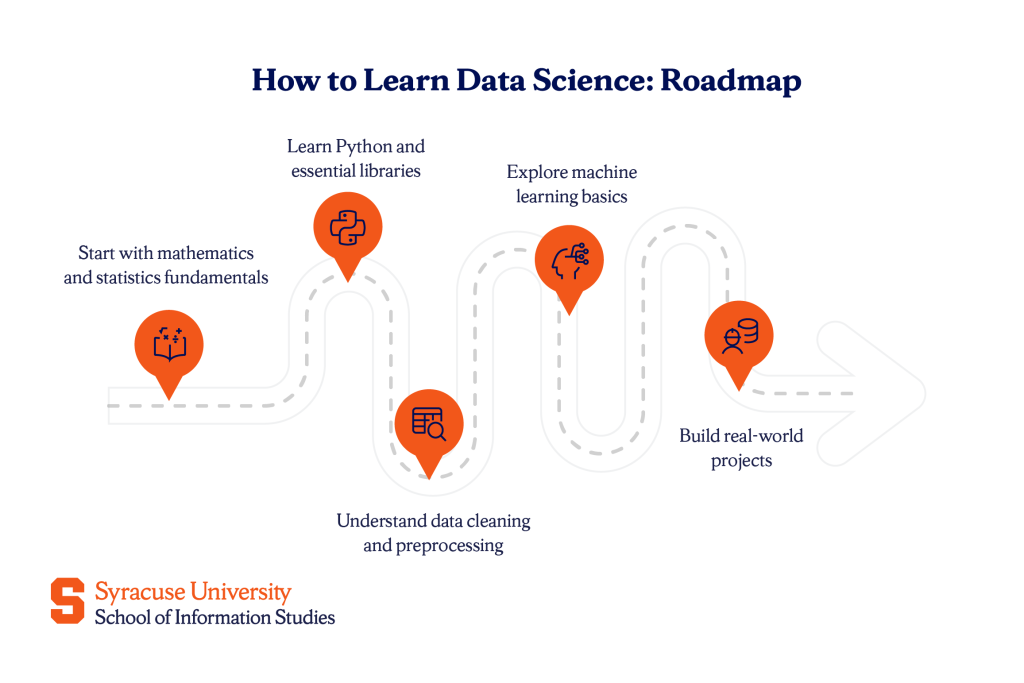
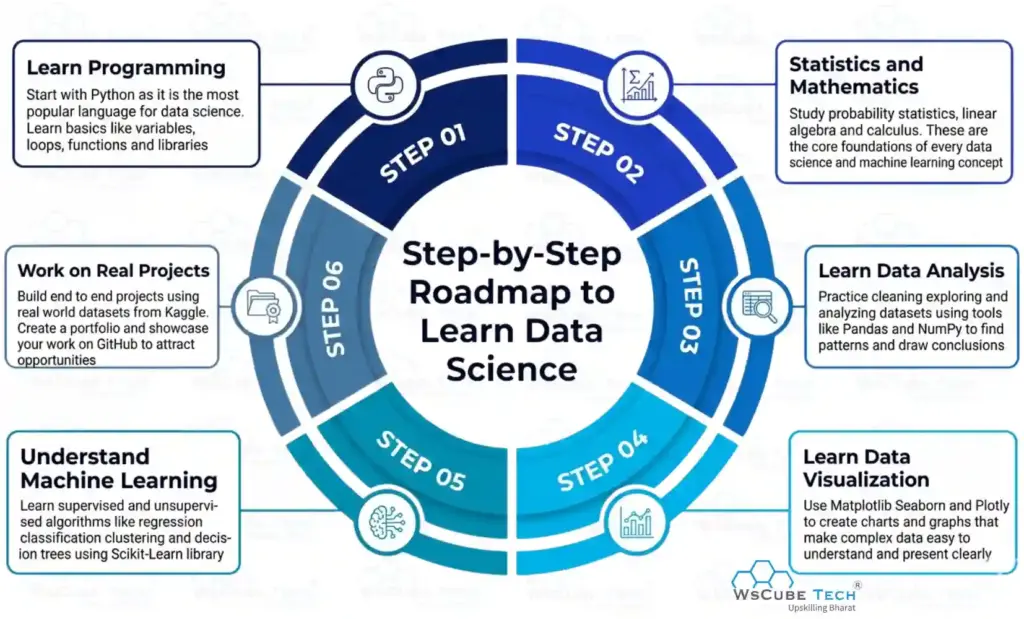
Most people approach data science guides backwards. They start by learning Python syntax, then Scikit-learn, then they stare at a blank Jupyter notebook wondering where to begin. I've seen this happen to dozens of junior analysts and it wastes months of their time. The actual problem isn't that the material is hard. It's that nobody shows you the order that makes sense. Start with a single real dataset before you touch a single line of code. I grabbed the NYC taxi trip dataset three years ago and spent six weeks reading through it. Not analyzing. Just reading. Understanding what each column meant, why certain values were missing, how the timestamps related to each other. Most people skip this step because they want to build models. But if you don't understand your data first, your model will be garbage and you won't know why. That wasted dataset taught me more than any certification course ever did. After you understand the data structure, you need basic statistics. Not the textbook version. The version you actually use every day: mean, median, standard deviation, correlation, and distribution shapes. I learned these by accident while debugging a regression model that predicted taxi fares with a mean absolute error of twelve dollars. My training set had a handful of trips that cost over four hundred dollars. Those outliers were destroying my model. Once I understood the difference between mean and median, I switched my evaluation metric and caught problems I'd been missing for weeks.
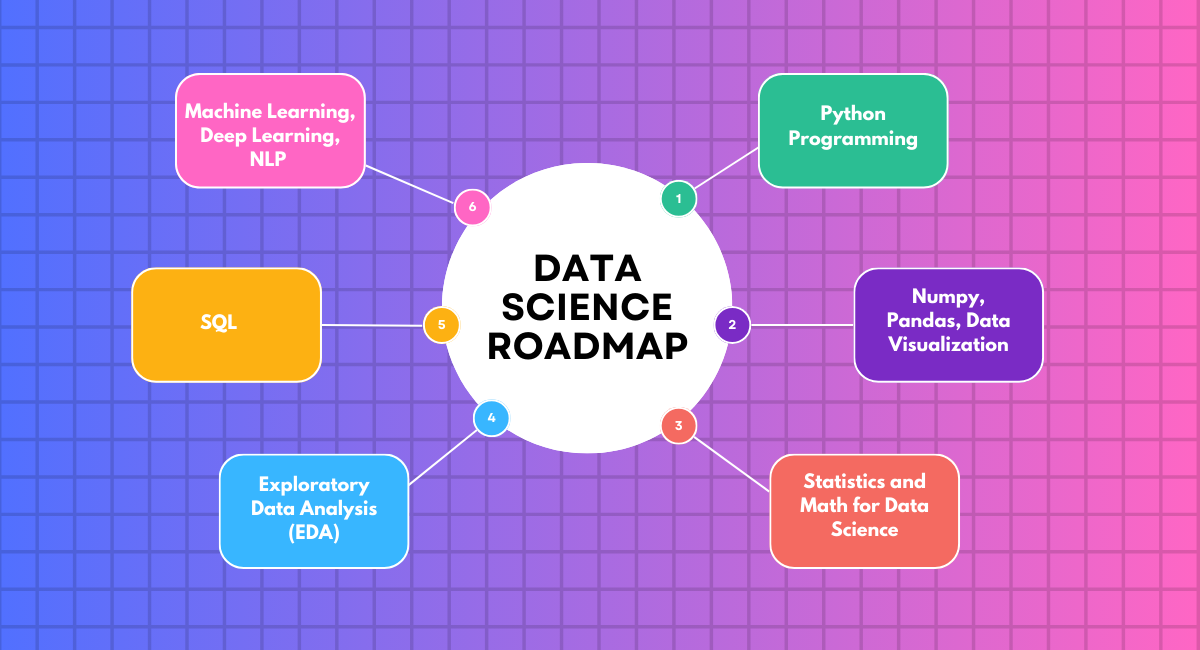
Here's what most guides won't tell you: Pandas should be your default tool, not your starting point. I watch people jump into TensorFlow or PyTorch tutorials before they know how to pivot a dataframe. That's like learning to fly a plane before you can drive a car. Learn pandas well enough that grouping, merging, and reshaping data feels automatic. Then move to visualization with matplotlib and seaborn. Then, and only then, consider machine learning libraries. The project-based approach works better than following tutorials end to end. Build something broken on purpose. I once built a customer churn prediction model that had 99% accuracy. It turned out the model was just predicting that everyone would stay because 99% of my training data was non-churners. A properly designed cross-validation approach would have exposed this in ten minutes instead of two weeks of confusion. Documentation quality matters more than anyone admits. When I read a guide that skips the parameter tuning section, I immediately lose trust in everything else it says. Good guides show you the default parameters, explain what they do, and demonstrate what happens when you change them. Bad guides assume you already know.
One specific problem I ran into regularly involved data leakage in time series splits. I was working with retail sales data and accidentally used future information to predict past sales. The model performed perfectly on my validation set. It failed completely in production. The fix was implementing TimeSeriesSplit from Scikit-learn instead of the standard train_test_split function. This is one of those things that sounds obvious in hindsight but takes hours to diagnose when you're the one seeing perfect results that make no sense in the real world. For environment management, use conda or venv and never skip dependency pinning. I spent a Tuesday afternoon rebuilding my entire workflow because an auto-update changed NumPy from version 1.24 to 1.26 and broke three packages I depended on. A single requirements.txt or environment.yml file would have prevented that. This is the kind of thing that feels minor until it destroys a week of work. When it comes to learning resources, Kaggle notebooks are useful for seeing how other people structure their approaches, but they're terrible for building foundational understanding. The code often skips the explanation because the author assumes readers already know it. Pair Kaggle with official documentation for any library you're using. The Pandas documentation alone contains enough detail to replace three books. The problem is most people treat it as a reference instead of a primary learning tool.
Get the Full Details
Counter-intuitive insight: you don't need to master deep learning to be effective in data science. Linear models, gradient boosting, and random forests solve the vast majority of real business problems. I worked at a company where we replaced an LSTM model with XGBoost and improved accuracy by four percentage points while cutting inference time from 200 milliseconds to twelve. The stakeholders couldn't see the difference in output quality but the engineering team could definitely feel the difference in deployment cost. Version control for your data work is non-negotiable. I started using DVC about two years ago for experiment tracking instead of relying on folder naming conventions. Before that, I had seven different copies of the same experiment with slightly different preprocessing steps and no way to tell which one was the best. DVC tracks your data versions alongside your code versions. It takes about an hour to set up and saves you days of confusion later. If you're looking for a downloadable guide or starter template, I usually recommend building your own. There are a few community templates on GitHub that are decent starting points. The key is personalizing them immediately. A template that works for someone else's e-commerce dataset won't work for your sensor data without modification. Modify it on day one or you'll never develop the skills to adapt it later.
What To Avoid
Don't chase every new framework that launches. The data science ecosystem changes fast and most of the noise isn't worth your attention. Stick to one stack and learn it thoroughly. Python with Pandas, Scikit-learn, and either SQL or dbt for data transformation covers roughly 90% of what most data scientists do on a daily basis. Avoid the tutorial trap where you watch someone build a project but never struggle through it yourself. Understanding comes from the frustration of debugging your own code, not from watching someone else's clean implementation run perfectly on the first try. I still remember the exact feeling of spending six hours fixing a single shape mismatch in a matrix multiplication. That frustration is where actual learning happens. Don't ignore the boring parts. Data cleaning, validation, and documentation aren't glamorous but they consume most of the actual workday. I've seen too many people produce impressive visualizations built onvalidated data and then get embarrassed when someone asks where the numbers came from.
The field rewards depth over breadth in most cases. Being the person who knows how to properly handle missing data, detect leakage, and communicate results to non-technical stakeholders will get you further than being the person who has tried every library that was released this year. Pick a domain, go deep, and build a track record of solving actual problems instead of collecting certificates.