What They Actually Want When They Ask Big Data Architect Interview Questions
Most candidates walk into a Big Data Architect interview and immediately start name-dropping tools. They talk about Spark, Kafka, Hadoop, Airflow, and Delta Lake like they're reading from a product brochure. I've sat on both sides of that table more times than I care to count. The people who actually get offered the job are the ones who can explain why they chose one thing over another, and what broke when they picked wrong. Let me walk through how these interviews typically go and what separates a decent answer from one that makes you look like someone who's actually shipped things.Big Data Architect Interview Questions You Should Actually Prepare For
The questions fall into rough categories, but they overlap more than you'd think. You'll get scenario-based questions that test your tradeoff reasoning, technical deep-dives into specific systems, and architectural design questions where you're given a business problem and expected to sketch out a solution on a whiteboard or in a shared doc. Here are the ones that come up repeatedly: Scenario and tradeoff questions: "How would you design a system to ingest telemetry from 50,000 IoT devices sending data every 3 seconds?" "Walk me through how you'd handle a pipeline where the source data has schema drift." "Your batch job takes 6 hours. The business needs it in under 30 minutes. What do you change?"
Technical depth questions: "Explain how Spark's shuffle works and what happens when you hit an OOM." "What's the difference between Kafka consumers in a consumer group versus separate groups?" "When would you use a data lakehouse versus a traditional warehouse?" Architecture design questions: "Design a data platform for a company that needs real-time fraud detection and daily reporting." "How do you handle slowly changing dimensions at scale?" The pattern here isn't random. Interviewers are probing for three things: do you understand the fundamentals, can you reason through tradeoffs, and have you dealt with the messy reality of production data.
What Actually Separates Good Answers From Bad Ones
A bad answer lists technologies. A good answer explains constraints. Here's the difference in practice. Question: "How would you handle real-time analytics on streaming data?" Bad answer: "You'd use Kafka for ingestion, Spark Streaming for processing, and store the results in a data warehouse like Snowflake."
Get the Full Details

Good answer starts with: "It depends on what 'real-time' means to the business. Are we talking sub-second latency, or is 5 minutes acceptable? What's the volume, and what queries need to run against the results? Because if you're doing aggregations over large windows, a columnar store might outperform a stream processor for the query layer even if ingestion is real-time." Notice the second answer doesn't commit to a stack until the interviewer's constraints are clear. That's the whole game.
A Real Problem From My Experience That No One Prepares You For
Let me share something specific. A few years back I was designing a pipeline for a logistics company. They had tracking events flowing through Kafka at roughly 80,000 messages per second. The business wanted a dashboard showing the current location of every active shipment, updated within 30 seconds. Simple enough on paper. The problem was that the source system occasionally sent duplicate events due to network retries, and worse, it would sometimes send an older event after newer ones had already arrived. This is called out-of-order delivery, and it's not a corner case. It happens constantly in distributed systems, and most interview prep materials treat it like an advanced topic rather than the default state of affairs. The naive approach—process events in order and overwrite a lookup table—produced incorrect results during reconnection windows. Ships would appear to jump backward in their routes for 45 seconds while the pipeline caught up.
The workaround I ended up using was to maintain a separate changelog stream in Kafka itself, keyed by shipment ID, and have the dashboard consumer apply a monotonic watermark before displaying state. Any event arriving after the watermark was pushed to a dead-letter queue for manual review rather than being silently applied. This kept the dashboard correct 99.7% of the time and gave us visibility into the 0.3% that wasn't. The monitoring side turned out to be more valuable than the deduplication logic itself, because the duplicates were a symptom of upstream retries that the logistics team needed to fix on their end. If someone asks you about out-of-order events in an interview, this is the kind of detail that signals actual experience. Most people haven't thought past the deduplication step.

Counter-Intuitive Things You Should Know
Here are a few things that aren't obvious but come up enough to matter. The Lambda architecture is mostly dead for new projects. Everyone learned about maintaining separate batch and speed layers from old conference talks. Modern stream processors like Flink and ksqlDB can do exactly what the batch layer did, just slower but still within acceptable windows for most use cases. Building both layers doubles your codebase and your failure surface. Unless you have a hard requirement for sub-second latency on something like fraud detection, stick to a single stream-processing layer and call it done. Schema-on-read is a trap if you don't also have schema enforcement at the point of consumption. Data lakes became popular because you could dump raw data in without thinking about structure first. The problem is that six months later nobody knows what any of the schemas were, and the "flexibility" becomes technical debt. The workaround that actually works is to define contracts at the ingestion boundary. Require producers to declare their schema through a registry, and reject non-compliant data at the gateway. You still get raw data in the lake, but it's raw data you can actually use.
Petabyte-scale architectures are overkill for most companies. I've seen teams build Hadoop clusters and custom Spark workflows for datasets that would fit comfortably in a single Snowflake or BigQuery account. The engineering overhead of managing those systems—monitoring, scaling, troubleshooting—costs more in person-hours than the cloud compute bills you're trying to save. Start simple. Scale when you have a real constraint, not because a blog post said you should.
The Questions That Trip People Up
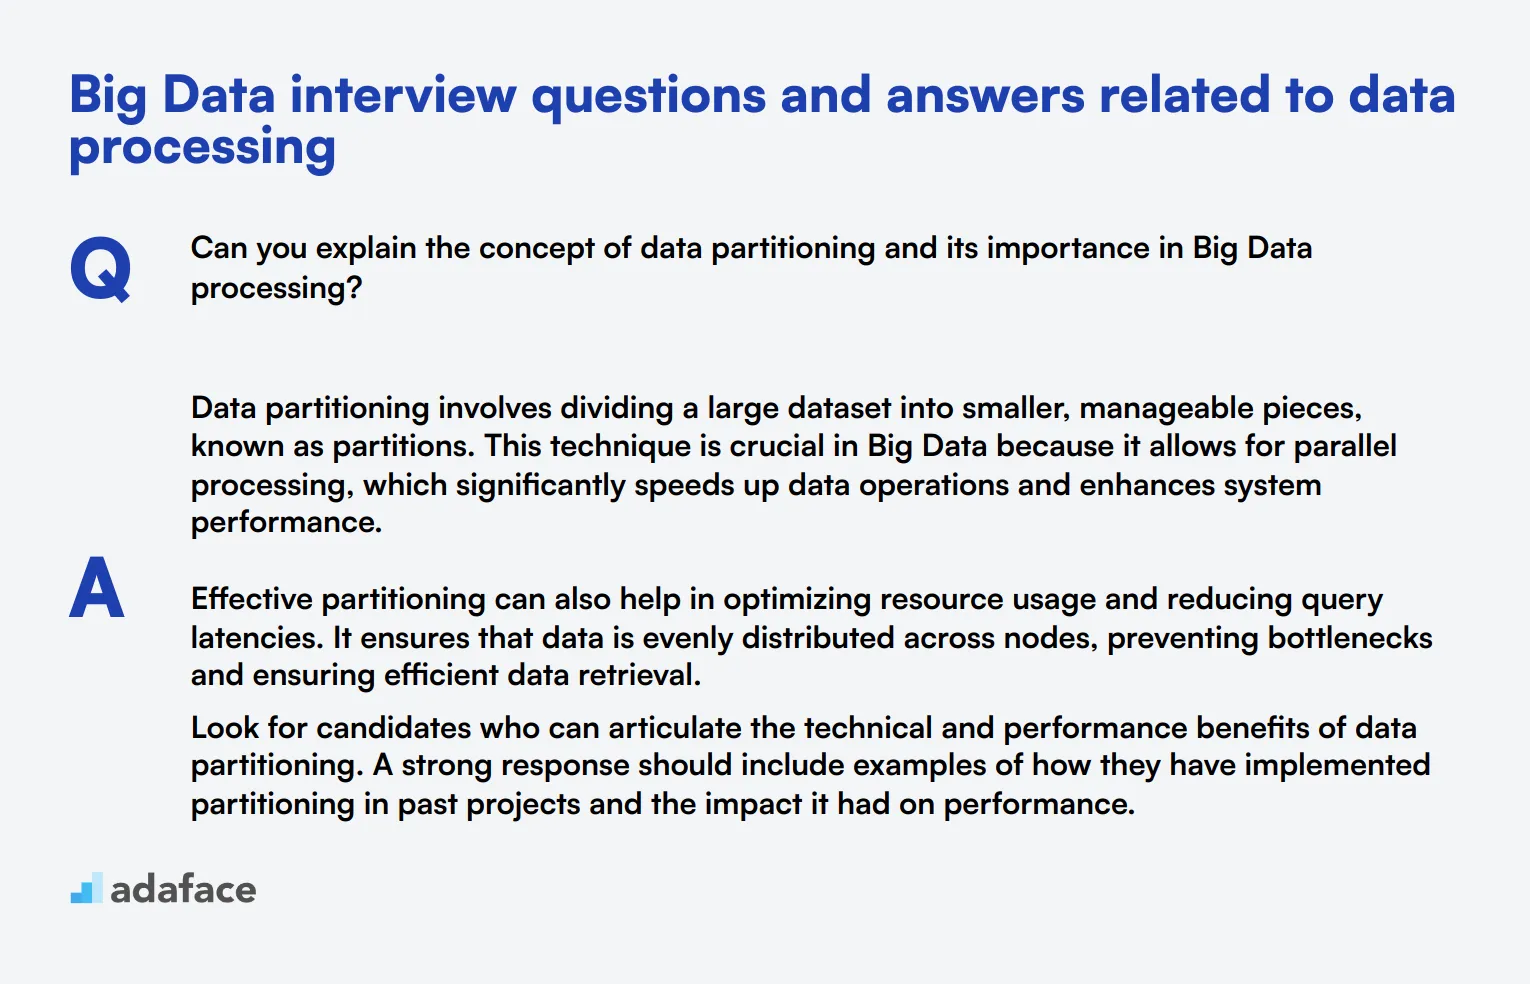
There's a subset of Big Data Architect Interview Questions that candidates consistently stumble on, not because the concept is hard, but because they've only ever worked in environments where someone else solved the problem. Data quality ownership. "Who is responsible for data quality in a pipeline?" The expected answer used to be "the data engineer." That's wrong. Data quality is the responsibility of whoever produces the data. Your job as an architect is to build guardrails—validation at ingestion, alerting on anomalies, schema enforcement—but if you think the data quality problem is yours to solve downstream, you'll spend your career cleaning up other people's mistakes. Put the cost of bad data on the team that creates it. Partitioning strategies. "How do you partition a table in a data warehouse?" Partitioning is one of those topics where everyone knows the definition but few have actually benchmarked the difference between good and bad choices. I once saw a table partitioned by date with 365 partitions per year on a dataset that was queried by customer region. Every query scanned all 365 partitions regardless of the filter. Switching to a composite partition on date and region cut query costs by 80% for that workload. The takeaway: partition keys should match your most common query patterns, not just the most obvious dimension.
Exactly-once semantics. This keeps coming up and most answers are technically incomplete. Kafka supports idempotent producers and transactional writes, which gives you exactly-once within a single broker. Cross-broker exactly-once requires a transactional sink like Kafka Connect with exactly-once semantics enabled or a framework like Flink with checkpointing. If the sink doesn't support transactions—say, a database that only acceptsINSERT—then you're back to at-least-once with deduplication logic. Don't claim exactly-once unless the entire chain supports it end to end.
How to Actually Prepare
Reading about architectures won't help you as much as having a mental model of what breaks. Here's what I'd recommend: Build something small and break it. Set up a Kafka topic, write a producer that sends malformed data occasionally, write a consumer that handles it, and add a dead-letter queue. Do this before an interview asks about it. The theory is fine, but having dealt with the actual error messages makes your answers more grounded. Review your own designs critically. Look at the last two systems you architected and write down what you'd do differently now. Interviewers love it when you can identify your own past mistakes. It shows you're not just reciting best practices but actually thinking about tradeoffs.
Understand the economics. Know roughly how much it costs to run a Kafka cluster of a given size, how Spark costs scale with shuffle volume, and what options exist for cold storage. Architects get asked about cost constraints constantly, and vague answers like "it depends" only work if you follow up with actual numbers.
What to Do When You Don't Know the Answer
You will get questions you can't answer on the spot. The right move isn't to bluff or reframe the question into something you do know. It's to walk through your reasoning out loud and admit where your knowledge ends. "I haven't worked directly with Iceberg, but based on my experience with Delta and Hudi, I'd expect it to support ACID transactions and time travel. I'd want to verify the snapshot isolation model, though, because that's where the differences usually show up." This does two things. It demonstrates that you can transfer knowledge across tools, and it shows intellectual honesty. Both matter more than any single technical fact. The people who ace these interviews aren't the ones who know every tool. They're the ones who can think clearly under pressure and communicate their reasoning in a way that lets the interviewer follow along. Everything else is details you can look up.