Why People Still Bother With Standardized Relational Query Languages
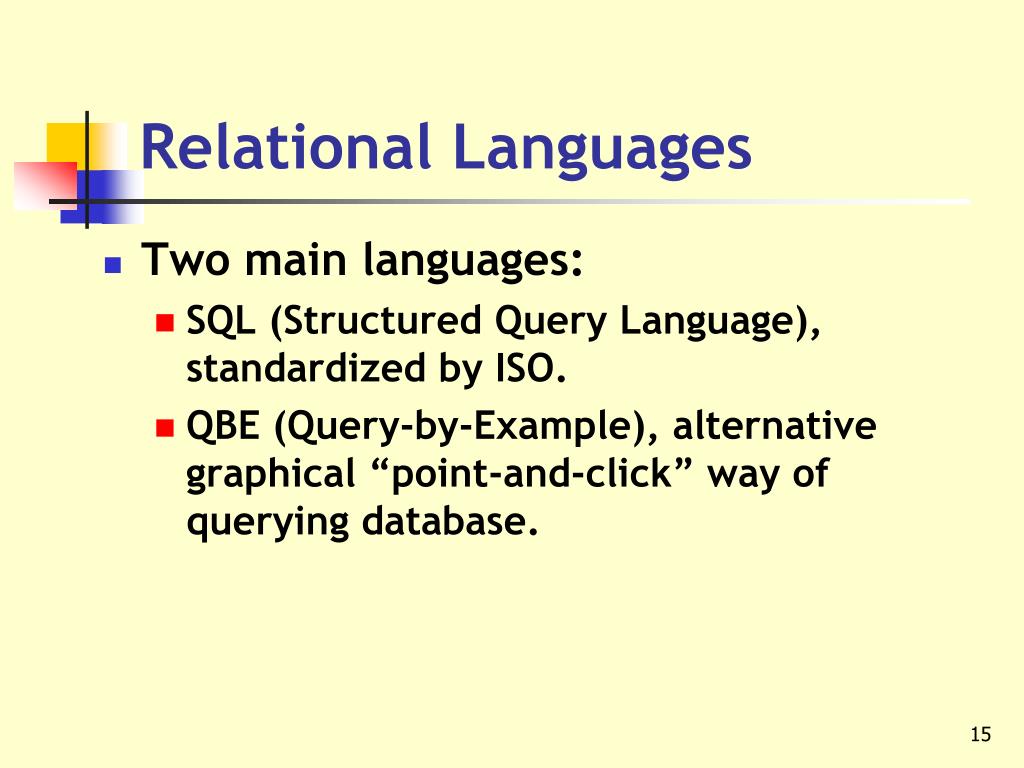
Most people think SQL is just the thing you run against a database. It's not. The real benefit shows up when you have to move data between systems that were never designed to talk to each other. When I was managing an ETL pipeline for a logistics company, we had to pull shipping manifests from a legacy Oracle system, transform them through a Python middleware layer, and push them into a PostgreSQL warehouse. If every vendor had their own dialect, that pipeline would have required custom adapters for each source. Instead, the ANSI-standard SQL we wrote once ran against both systems with only minor index hints swapped out. It saved us probably three weeks of initial development and a half-day of debugging every time a new data source joined the stack. That's the core of it. A standard means a SELECT statement written for MySQL runs against PostgreSQL, SQL Server, and SQLite with minimal changes. You aren't reinventing the wheel every time your architect picks a different engine for staging versus production. The differences that do exist — things like string concatenation syntax or how NULL behaves in aggregations — show up as small, well-documented deviations. You learn them. You write wrapper functions. You move on. The standardization itself is maintained by ISO and IEC through the SQL standard, currently at the 2023 revision, though most commercial engines only implement a subset of that. That's fine. What matters is the intersection of features they all agree on: basic DDL, DML, JOINs, subqueries, CTEs, and window functions. Those are available everywhere, usually within a few percentage points of performance parity.
Here's something most beginners don't realize: SQL standard compliance doesn't actually guarantee your queries will behave identically across platforms. I learned this the hard way during a data migration project in 2019. We had a query that used RANK() OVER (PARTITION BY column ORDER BY column) to deduplicate records. In PostgreSQL it produced correct results. In SQL Server it was fine too. But when we ran the same query against our new Amazon Redshift cluster during a test migration, it silently produced duplicate rows because Redshift's implementation of the window function behaved differently with NULL values in the PARTITION BY clause. The standard says they should all produce the same ranking, but the engine author obviously made a different choice about NULL handling. The workaround was explicit COALESCE on the partition columns, which forces NULLs into a known value before the window function evaluates. It took me about forty-five minutes to track down because the output looked almost right — just enough duplicates to break downstream joins without throwing an error.
How To Write Portable SQL in Practice
The first rule is to avoid features that are vendor-specific extensions. CTEs, UNION ALL, INNER JOIN, LEFT JOIN, CASE expressions, and standard aggregate functions are your foundation. Everything else is a negotiation. When you need something outside that set — say, recursive queries — check whether your target platforms all support the same version. PostgreSQL has supported RECURSIVE CTEs since 8.4. SQL Server since 2005. MySQL only since 8.0. If you're targeting MySQL 5.7, you're writing a stored procedure or iterating with application logic instead. The second rule is to treat data types as a negotiation too. VARCHAR is standard but the maximum length varies — SQL Server defaults to 8,000 bytes for VARCHAR but only 4,000 for NVARCHAR, while PostgreSQL and MySQL treat VARCHAR length as character-based regardless of encoding. If you're building tables that will exist on multiple engines, use explicit length limits and document them. Don't rely on defaults. A third practical step is to write your queries in a way that separates logic from execution. Use parameterized queries or prepared statements for input values. Use views or materialized CTEs to isolate platform-specific behavior in one place rather than scattering it across dozens of queries. When you later swap databases, you know exactly where to look for incompatibilities.
Get the Full Details
There's a counter-intuitive insight here that most people miss: the more you try to make your SQL perfectly portable, the more you limit what you can do. Full-standard SQL is conservative. It avoids the powerful features that actually make databases worth using. The answer isn't to write pure standard SQL and suffer for it, or to write platform-specific SQL and lose portability. The answer is to write standard SQL for the common paths and isolate the non-portable parts behind an abstraction layer — a view, a stored procedure, or an ORM query builder. You get portability where it matters and performance where it counts.
Where Standardization Actually Fails
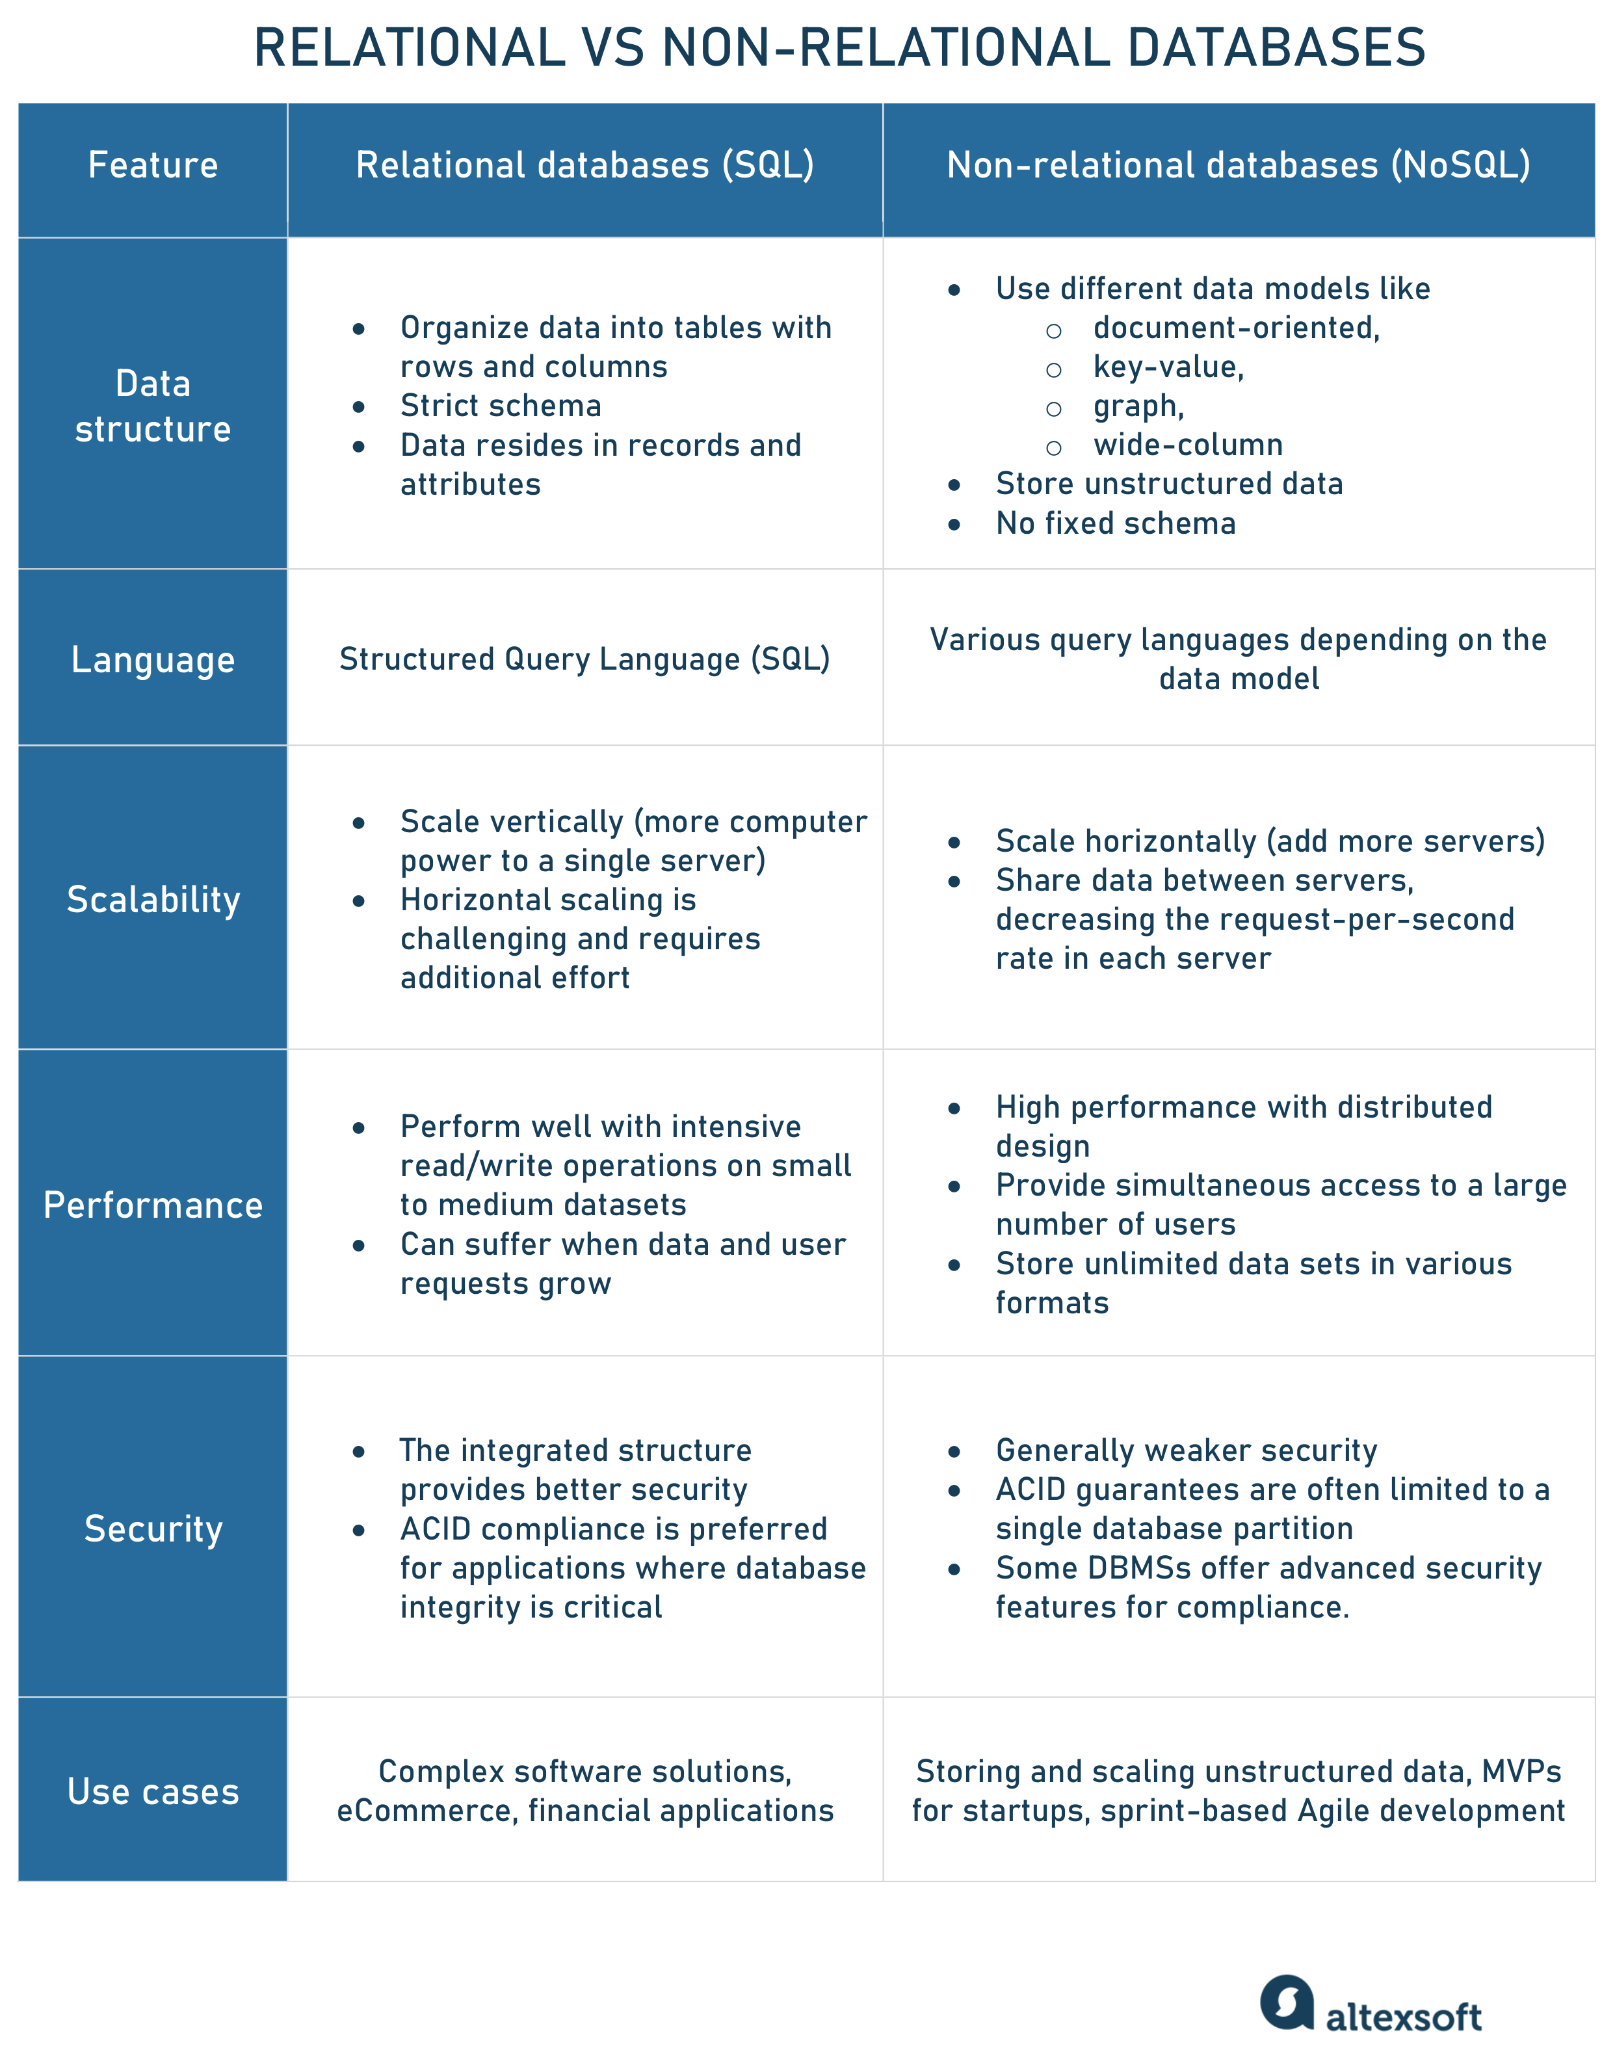
It fails when you hit feature gaps that matter for your workload. There is no standard for JSON path querying in the same way there is for relational operations, so every major engine handles JSON differently. PostgreSQL has -> and #> operators. SQL Server has OPENJSON. MySQL has JSON_EXTRACT. If your application stores semi-structured data, you will leave the standard world quickly. It also fails at the query planner level. Two databases executing the same standard SQL query can produce completely different execution plans because their cost models differ. Postgres uses a statistical cost-based optimizer. SQL Server uses a similar approach but with different heuristics. MariaDB recently switched its optimizer in ways that changed plan selection for complex joins. Portability of logic does not mean portability of performance. You will still need to tune queries for each engine, even when the syntax is identical. If your goal is complete cross-platform compatibility with zero maintenance, the honest answer is that you should probably look at an ORM or an abstraction layer like Prisma, Drizzle, or JDBC with parameterized queries. These tools generate the appropriate dialect for each backend based on your schema definition. They handle the type mapping, the NULL semantics, and the driver-specific quirks. You write once. The tool writes the SQL. The trade-off is that you give up direct control over the generated queries, which matters when you need fine-grained performance tuning on complex reports.
Standardization Is About Reducing Cost, Not Eliminating It
The benefits of a standardized relational language are real but finite. They reduce the number of adapters you need to write. They make it easier to hire people who already know the core syntax. They let you switch engines during migrations with less panic. But they don't eliminate the work of understanding how each engine actually executes your queries, and they certainly don't help with the non-relational parts of modern data workloads. I've been doing this long enough to stop expecting SQL to be the universal solution. It's a tool with a standard interface, and that standard interface has genuine value. Just don't confuse interface standardization with implementation uniformity. The two are related but they are not the same thing.