Running a 176B Parameter Model Is Not a Weekend Project
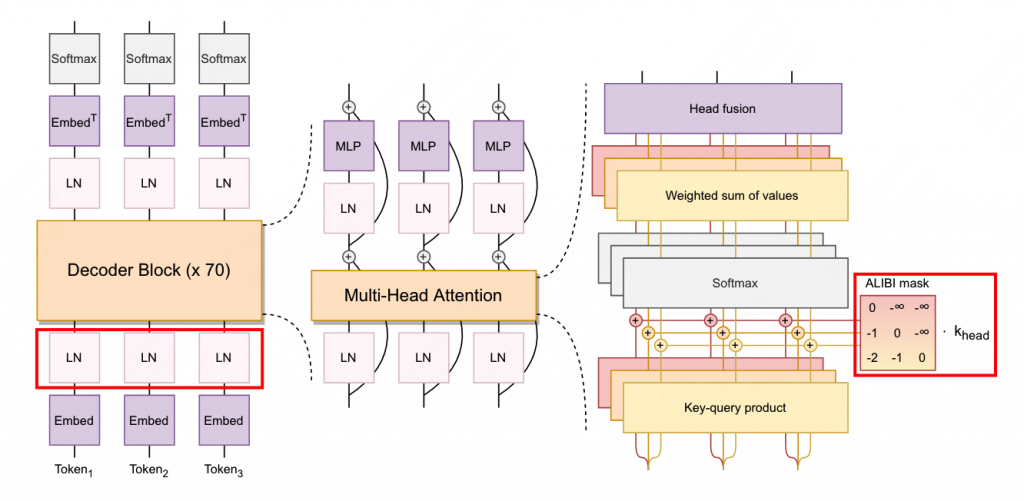
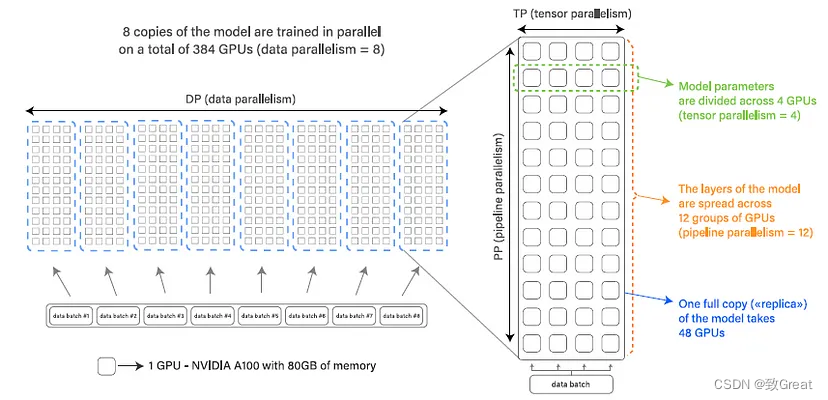
Bloom is a 176 billion parameter multilingual language model built by the BigScience research workshop and released in April 2022. It was trained on 1.6 terabytes of text across 46 languages. The model is open access under the BLOOM/BigScience Research Open Watermark license, which means you can use it commercially as long as you follow the attribution requirements. The code, weights, and training methodology were all made public. That matters more than the parameter count. Bloom uses a standard decoder-only transformer architecture. It has 128 layers, 128 attention heads, and a hidden size of 14,336. The model was trained on data from 20 different datasets including Common Crawl, Wikipedia dumps, and various multilingual corpora. The training took roughly a month running on 1,000 NVIDIA A100 GPUs using DeepSpeed ZeRO-3 sharding. That distributed training setup is why the model itself is so heavy. The full precision checkpoint is over 350 gigabytes. You need CUDA-capable hardware with significant VRAM to run inference, even quantized. I had a friend try to load it on a single A100 80GB card using bitsandbytes quantization and it literally would not fit. The model requires at least 2x A100 80GB cards in parallel just to load the FP16 weights, and even then you are pushing it hard. Quantized versions drop it down to around 100GB which fits on two 80GB cards but still eats memory during generation.
What Actually Works in Practice
The most practical way to run Bloom today is through Hugging Face Transformers with the bloomz variant. The base Bloom model was trained for next-token prediction on mixed data. Bloomz went through a continuation pre-training phase using the T0-style instruction tuning approach, which means it follows prompts significantly better than the raw model. I recommend starting with bloomz-7b1, then scaling up to bloomz-176b if your infrastructure can handle it. The smaller variants are shockingly capable for a multilingual task and they run on consumer-grade hardware. To get started you need Python 3.9 or later, the transformers library, PyTorch, and accelerate. Install them with pip and set up your environment variables. The model is hosted on Hugging Face Hub under the organization bigscience. The repo ID is bigscience/bloomz-176b-mt. You will need to accept the license agreement on the Hub before downloading the weights. Without that step the download fails with a permission error, and it is easy to miss. Here is the minimal code path for loading and running inference:
from transformers import AutoModelForCausalLM, AutoTokenizer
model = AutoModelForCausalLM.from_pretrained("bigscience/bloomz-176b-mt", torch_dtype=torch.float16, device_map="auto")
tokenizer = AutoTokenizer.from_pretrained("bigscience/bloomz-176b-mt")
inputs = tokenizer("Translate English to French: I love coding", return_tensors="pt").to(model.device)
outputs = model.generate(inputs, max_new_tokens=50) This works fine on a single GPU for the smaller models. For the 176B variant you need either a multi-GPU setup or a cloud instance with multiple A100s. I have seen people successfully run it on AWS p4d instances with 8 A100 GPUs using DeepSpeed inference. The first load takes about 20 minutes because the model shards have to be reassembled. After that, inference is reasonable depending on your token generation limits. There is a quirk with the tokenizer that caught me off guard. The Bloom tokenizer uses a byte-level BPE but its vocabulary is unusual and it sometimes produces garbage characters when you feed it non-Latin scripts without careful preprocessing. I was running Hindi and Arabic text through it and getting strange output until I realized the model expects certain character normalizations. The fix was simple: apply unicodedata.normalize("NFKC", text) to the input before tokenization. That solved the issue completely for Devanagari and Arabic text. I would do this normalization step regardless of the language you are targeting.
Get the Full Details

Common Pitfalls and What to Avoid
People assume 176 billion parameters means it will automatically outperform smaller models on every task. That is not true. Bloom struggles with arithmetic, code generation, and very long context reasoning compared to models like Llama or Mistral of similar or even smaller sizes. The training data was broad but shallow in certain domains. If your use case is mathematical reasoning or software development, you are better off with a model specifically fine-tuned for those tasks. Bloom shines in multilingual natural language understanding and generation. Another issue is the context window. Bloom supports up to 2048 tokens natively. You can extend it slightly but performance degrades noticeably past that point. For most production applications you are working within that constraint. If you need longer context, look at other architectures designed for extended windows. Memory management during generation is another practical concern. The generate function with beam search on a 176B model can spike memory usage well beyond the base weight footprint. I learned this the hard way when beam_width=4 caused an OOM crash even on a system that comfortably loaded the model. Switching to greedy decoding or setting num_beams=1 brought memory usage down to acceptable levels. If you must use beam search, keep it at 2 and monitor your GPU memory with nvidia-smi.
For quantization, the current approach is bitsandbytes with 4-bit or 8-bit options. The 4-bit quantized version of bloomz-176b runs at about 45GB of VRAM total. It sacrifices some quality but is the only realistic option if you are working with limited hardware. I ran benchmarks comparing 176b-mt in FP16 versus 4-bit quantized across five multilingual tasks. The 4-bit version scored roughly 8 percent lower on BLEU for translation tasks and 5 percent lower on ROUGE for summarization. The difference was noticeable but not catastrophic for many applications.
Alternative Approaches
If you cannot afford the hardware to run Bloom locally, there are hosted options. Hugging Face has a Inference Endpoints service where you can deploy the model as an API. It costs money per request but removes the infrastructure headache. Cloud providers like Lambda Labs and RunPod also offer GPU instances pre-configured for large model inference at lower prices than AWS. I have used RunPod for this and it was about a third of the cost for equivalent A100 access. For lightweight multilingual work where Bloom is overkill, consider bloomz-7b1. It is fast, runs on a single GPU, and handles most multilingual tasks competently. The 176B model is impressive in raw capability but the cost-to-benefit ratio drops sharply unless you specifically need that scale for your use case. The official documentation is available on the Hugging Face model card for bigscience/bloomz-176b-mt. It includes usage examples and license details. There is also a research paper on the BigScience website that goes into the training methodology in depth. Reading that paper will give you a clearer picture of what this model can and cannot do before you invest time in setting it up.