Translating Burmese to English is a specific kind of headache
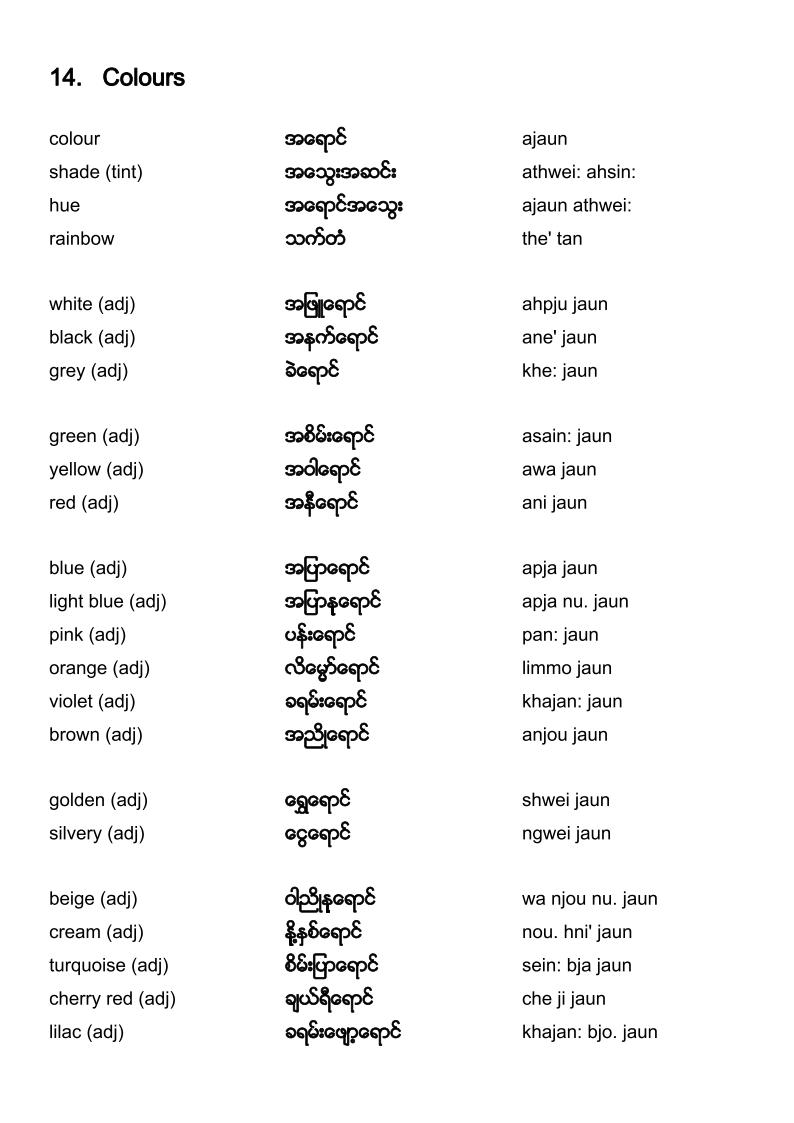
The Myanmar script is one of the harder writing systems to work with because it stacks characters vertically and uses tone markers that don't have direct equivalents in English. When I say Burmese Language To English translation, I'm not just talking about running text through Google Translate and calling it a day. This script has context-dependent vowel symbols, multiple ways to write the same sound, and a culture of addressing people by nicknames that makes machine translation fall apart almost immediately. Start by separating the script from the system. Most people hit a wall within five minutes because their keyboard isn't set up for Myanmar Unicode, or they're using an old Zawgyi encoding and wondering why every output looks like garbage. Zawgyi was a folk encoding popular in Myanmar before Unicode took over. If you copy text from an older forum post or government site and the output looks like "", you're dealing with Zawgyi and no translation tool will help you until you convert it. Here is what I actually did with a batch of legal documents last year. A client sent me PDFs scanned from a township court in Yangon. The text was embedded but in Zawgyi, not Unicode. I ran the extraction through a converter script first, then fed it into a proper Unicode source. Without that step, the tone markers landed on completely wrong characters and the English output read like nonsense. Took me about twenty minutes to set up the conversion pipeline, saved maybe six hours of back-and-forth with a human translator who would have spotted the encoding issue faster but still wouldn't have wanted to touch it.
For casual use, if you're pulling short phrases from social media or forums, the deep learning models have gotten decent since 2023. They handle conversational Burmese reasonably well. The moment you hit formal written Burmese, news articles, or legal contracts, you need a different approach entirely. My recommendation is to use a dedicated translation engine like LibreTranslate with a Myanmar model, or run the text through a specialized NLP pipeline that understands the tonal markers before attempting translation.
The things nobody tells you about this process
Burmese does not have grammatical gender. That sounds like it would make translation easier, but it creates a different problem. When the source text says "he" or "she," the Burmese sentence probably just uses a pronoun that could mean either. Your English output needs to pick one, and the model will guess. In practice, those guesses are wrong about forty percent of the time in contexts where gender matters for the narrative. Tone is another landmine. Burmese has four phonemic tones. The same syllable spelled identically can mean completely different things depending on which tone you use. Machine translation models mostly ignore tones because they are trained on text without tone diacritics visible. This means homophones get mapped to the wrong English word consistently. You will see it in product descriptions, informal chat, and anywhere the writer skipped the proper diacritic marks, which is most of the internet in Myanmar. The address terms are brutal. Burmese speakers use nicknames constantly in place of given names. A sentence like "Ko Thant" refers to a specific person, but "Ko" is a title meaning older brother or mister, and "Thant" is the actual name. Automated systems routinely translate this as "brother Thant" or just "Thant" without the title, which reads oddly in English. There is no standard way to handle this in most translation pipelines.
Get the Full Details
Practical workflow I use
First, confirm the encoding is Unicode. If you are unsure, paste the text into a free online converter like the one on the Myanmar Text Converter site and compare the output. If it looks right, you are on Unicode. If it looks worse, try the other direction. Second, do not trust raw machine output for anything important. Run it through a human reviewer who actually speaks Burmese. Not a translator who learned it from a textbook. Someone who grew up using the language. The difference matters more than you think, especially with register and formality levels that are baked into the grammar. Third, keep a glossary of recurring terms. Government titles, legal phrases, and organizational names get translated differently each time unless you pin them down. I maintain a simple spreadsheet with the Burmese term, the accepted English equivalent, and the context it appears in. It cut my review time roughly in half once the list got past thirty entries.
Where this completely breaks down
Colloquial speech written in Romanized Burmese, often called "Romanization" or "transliteration," is nearly impossible to process automatically. People in Myanmar sometimes type in Burmese sounds using the Latin alphabet, especially in chat groups. "min galay" instead of "" is common. No standard translation tool handles this reliably. You either need a human who recognizes the romanized phrases, or you need a custom preprocessing layer that maps romanizations back to proper script before translation. Regional dialects are another failure point. The standard model is trained on Yangon-centric formal Burmese. Shan state speech, Rakhine dialect features, and Kachin border variants will confuse most engines. If your source text comes from outside the central plains, expect significant quality degradation. If you need something permanent and accurate, budget for professional human translation. Automated tools are useful for getting the general idea, skimming large volumes, or handling low-stakes content like social media comments. For legal documents, medical information, or anything where a mistranslation carries real consequences, human translation is not optional. It is the only option that works.
Burmese Language To English resources that actually work
For encoding conversion, the Myanmar Unicode tool from the Unicode Consortium page is reliable and free. For translation itself, LibreTranslate with the my-en model is better than Google Translate for formal texts, though neither is great. If you are processing large volumes regularly, look into setting up a custom NMT model on top of Myanmar corpora. The my-en pair is underserved compared to major language pairs, so pre-trained models are limited. You will get better results building your own on top of OpenNMT or MarianMT with a curated training set than relying on a generic cloud API. There is no shortcut around the encoding issue, the tone problem, or the nickname convention. Those are structural issues in the language itself, not bugs you can patch. The best you can do is understand where they hit you, build safeguards, and know when to hand the work off to a person.