The actual mechanics of keeping operations alive
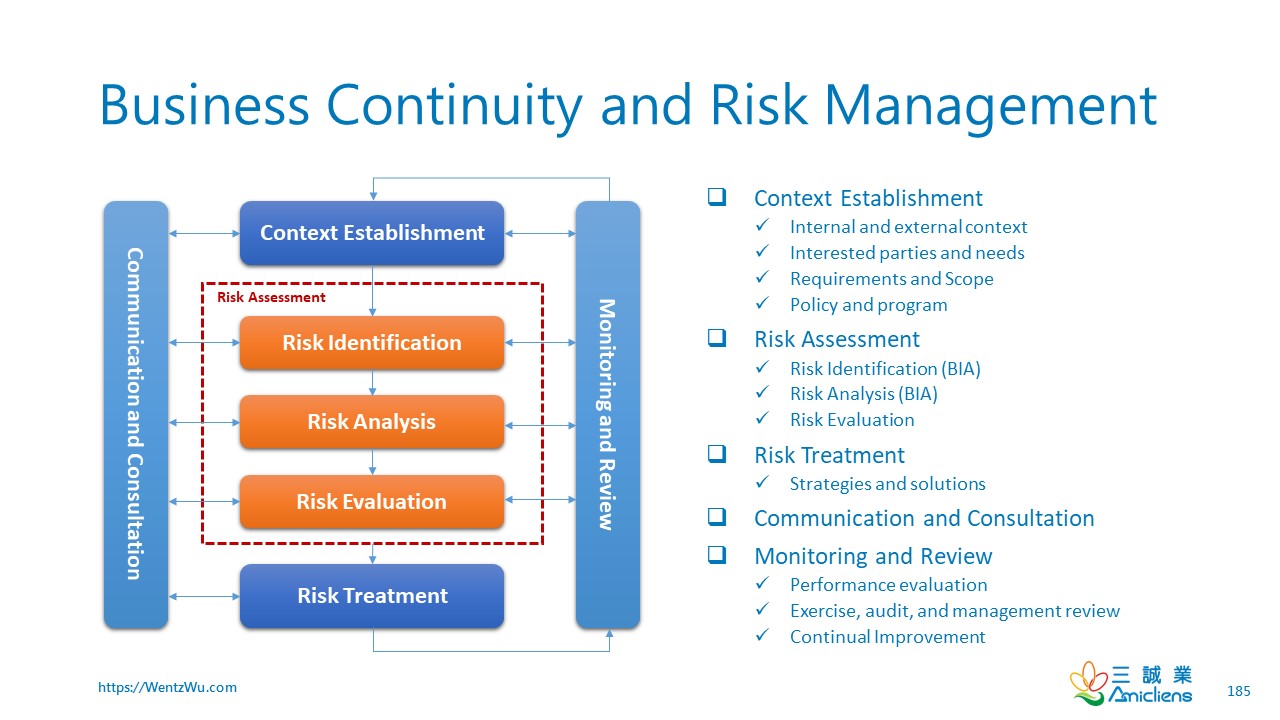
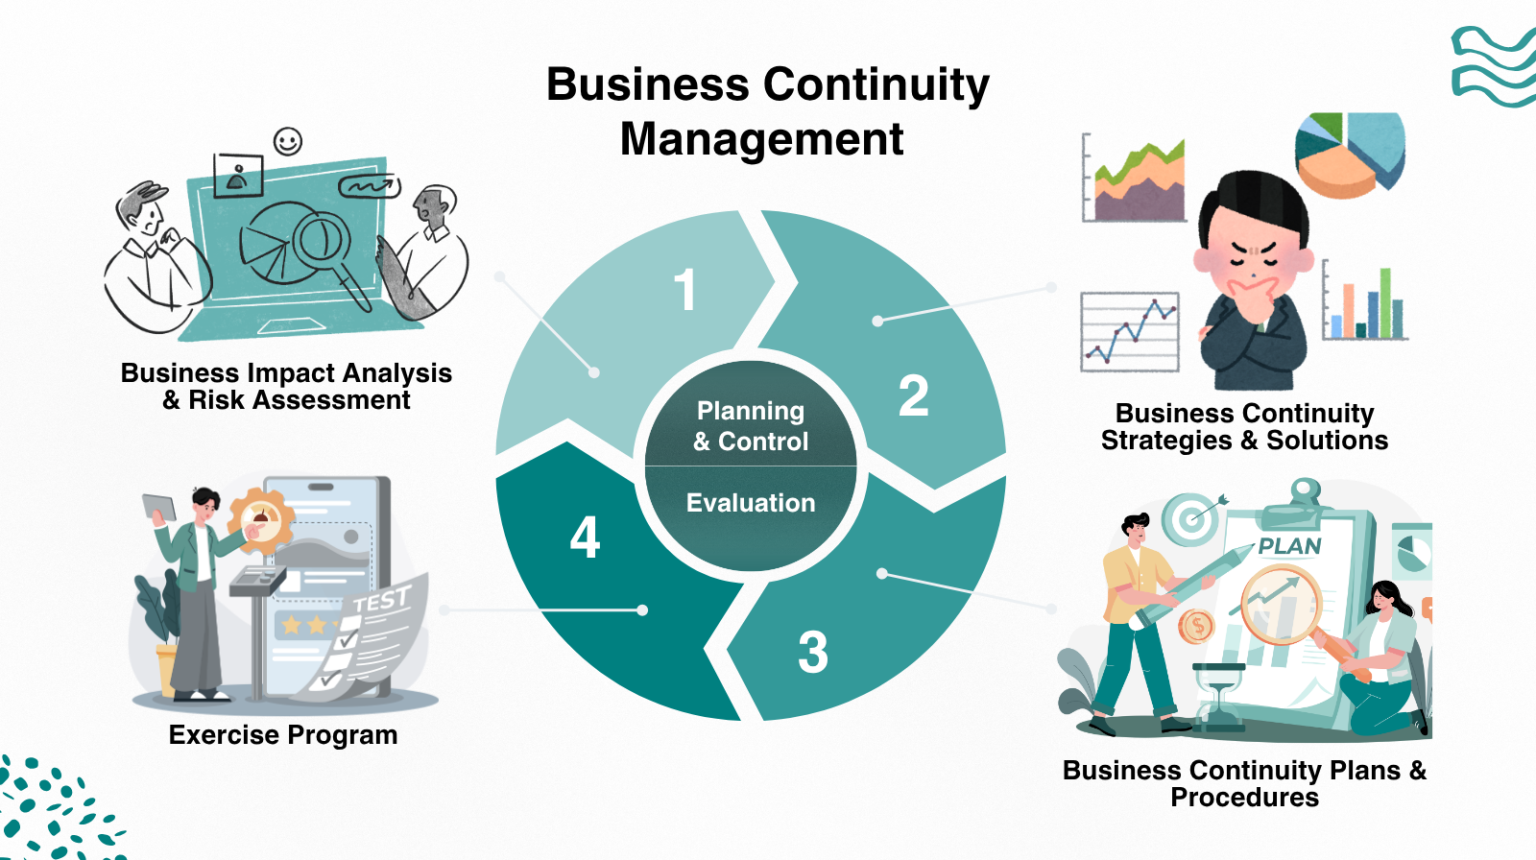
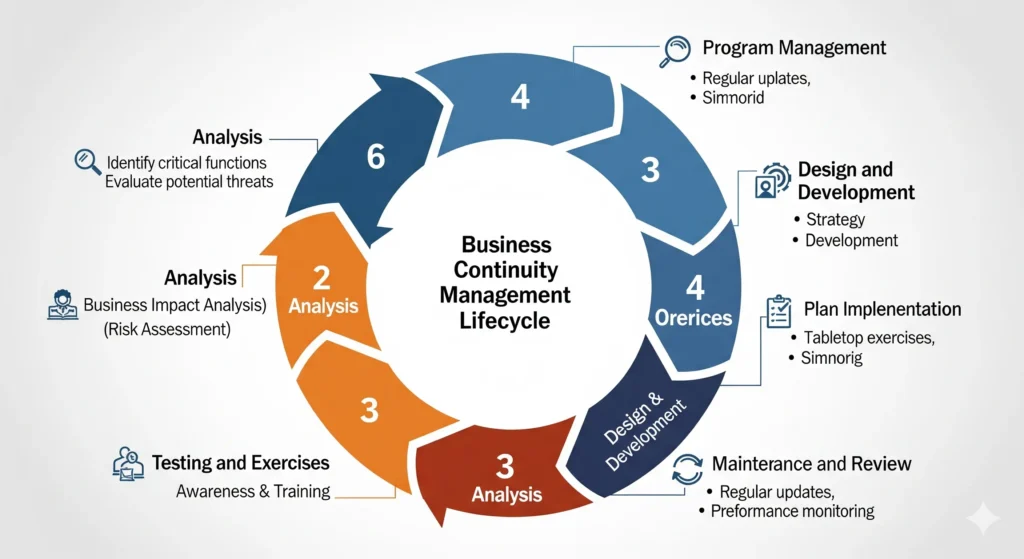
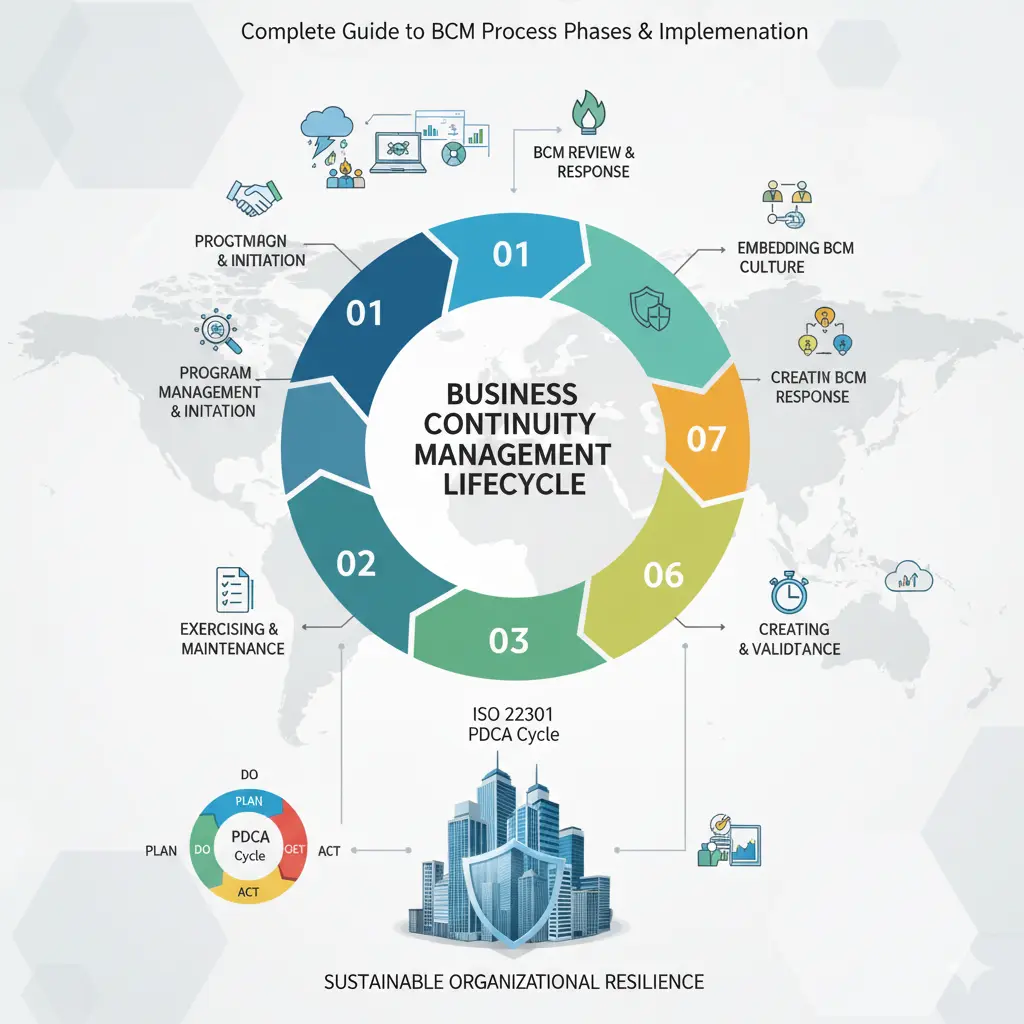
Most people approach Business Continuity Risk Management as a compliance checkbox exercise. They fill out templates, assign owners, and file it away until an auditor demands otherwise. That approach works right up until something actually breaks, and by then you've wasted twelve to eighteen months on paperwork that doesn't match reality. Start by mapping what actually keeps the business running. Not what your org chart says should happen, but what truly moves money, data, or product from one side to the other. I found this out the hard way after spending three months building continuity plans for departments that had been quietly redundant for two years due to previous system migrations nobody documented. The process breaks into four stages that don't happen in sequence. They overlap constantly.
Stage one: business impact analysis. This isn't about interviewing people and taking notes. It's about finding the single points of failure in each critical process. You need to know how long a function can go unsupported before the damage becomes irreversible. Revenue loss matters, but reputational damage and regulatory exposure often hit harder and faster. The usual output is a table showing maximum permissible downtime for each process, measured in hours or days depending on the function. Stage two: risk assessment. Now you layer threats onto those critical processes. Natural disasters, supply chain collapse, cyber incidents, key person dependency, vendor failure. Most organizations stop at listing these. The useful step is scoring them by likelihood and impact using actual historical data where available, not guesses. Check your industry's incident reports, review insurance claims history, and pull maintenance logs. A cloud provider having an outage twice a year is not theoretical. It's in your ticketing system. Stage three: strategy development. This is where most continuity programs fall apart. You need recovery strategies that match the tolerance levels from stage one. If a process can't go more than four hours without support, a weekly backup to tape stored offsite is not a strategy. It's a fantasy. You need redundant systems, alternate sites, or contractual agreements with vendors who can guarantee response times. Write those guarantees down. Verbal assurances from vendors change when pressure arrives.
Stage four: documentation and testing. Documentation should be usable by someone who hasn't worked in your company for six months. If your plan requires institutional knowledge to execute, it's not a plan. It's a hope. Testing is non-negotiable. Run tabletop exercises quarterly. Do full failover tests annually. I learned this when a power failure knocked out our primary data center during a DR drill and our "recovery" procedure required a password that had expired three months earlier because nobody had validated credentials as part of the test cycle. The workaround was pulling admin credentials from our password manager, which we hadn't included in the original plan because we assumed admins would remember them. The counter-intuitive part most beginners miss is that business continuity isn't about preventing disruption. It's about managing the gap between when things break and when you can function again. Prevention is important but separate. Your continuity plan should assume failure is inevitable and focus entirely on what happens after. Another thing people get wrong: they design recovery for worst-case scenarios that won't happen, while ignoring the boring failures that actually take systems down. A server crash is far more likely than a hurricane flooding your data center. Invest proportionally.
Get the Full Details
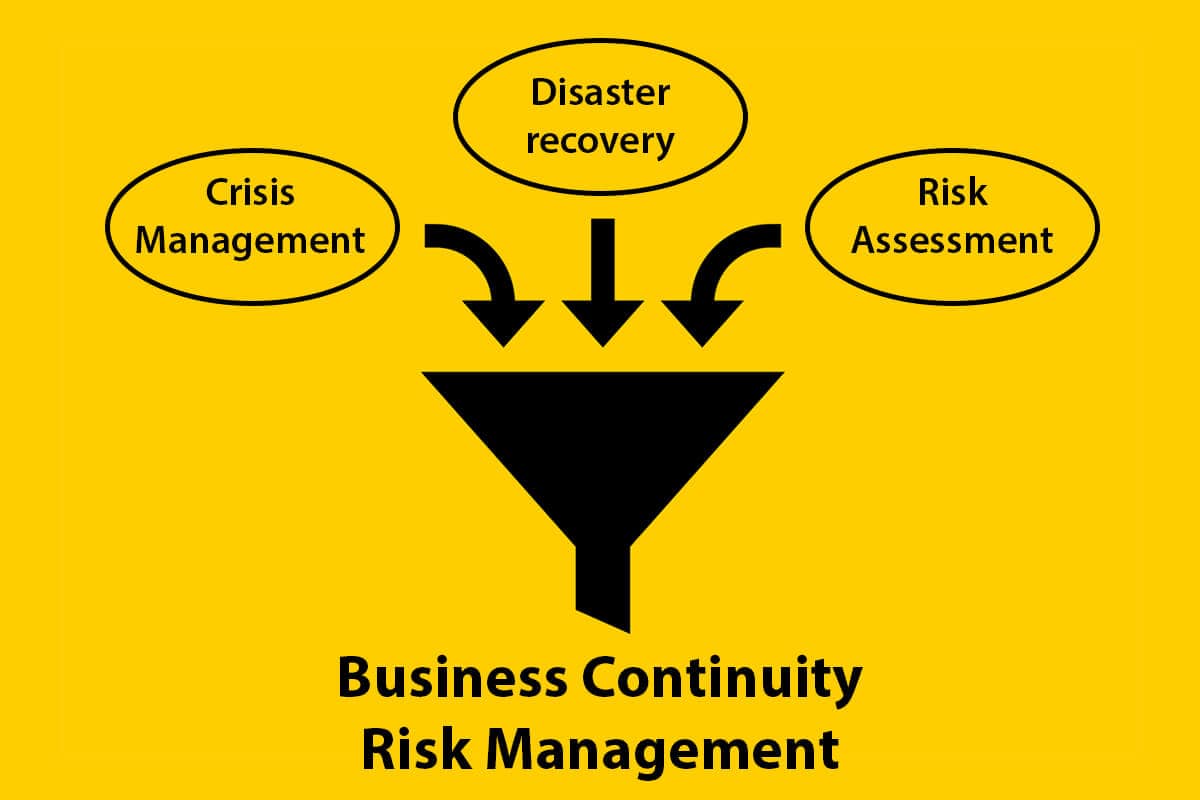
There are significant limitations to every continuity framework. BCP templates from professional organizations assume a level of resource allocation most mid-size companies can't sustain. A full hot site with real-time replication costs between two hundred thousand and five hundred thousand dollars annually. That's not available to everyone. The alternative is a warm site with daily snapshots, which reduces recovery time from minutes to several hours but costs a fraction. Choose honestly based on what you can afford, not what a textbook says you should have. Another bottleneck: continuity planning creates false confidence. Running a test once a year makes leadership feel secure even though the plan has probably drifted significantly from current operations in the intervening eleven months. The fix is shorter, more frequent testing cycles focused on specific components rather than full-scale exercises. Ten-minute checks on critical recovery procedures every month catch more problems than a single annual drill. For the actual documentation, most teams use a combination of a master continuity plan document, individual process recovery runbooks, and a contact list with fallback communication methods. Keep the master document under twenty pages. If it's longer, people won't read it. Put the details in appendices and runbooks.
The tools available range from spreadsheets to dedicated BCM platforms. Spreadsheets work if your organization has fewer than fifty critical processes and you're willing to maintain them manually. Anything larger and you need software with version control, notification routing, and testing tracking. I've used Disaster Recovery as a Service providers for smaller divisions and dedicated platforms like Workiva and Diligent for enterprise-level programs. Neither is perfect. Workiva is expensive and clunky. Diligent has better workflows but limited integrations with legacy systems still running in older infrastructure. If you're starting from zero, begin with a one-page map of your top ten critical processes and their current state of recovery readiness. That's it. Then build from there. Anything more elaborate as a first step is usually wasted effort because you don't yet know which processes matter enough to justify detailed planning.