Converting C to Assembly: What Actually Happens When You Press Build
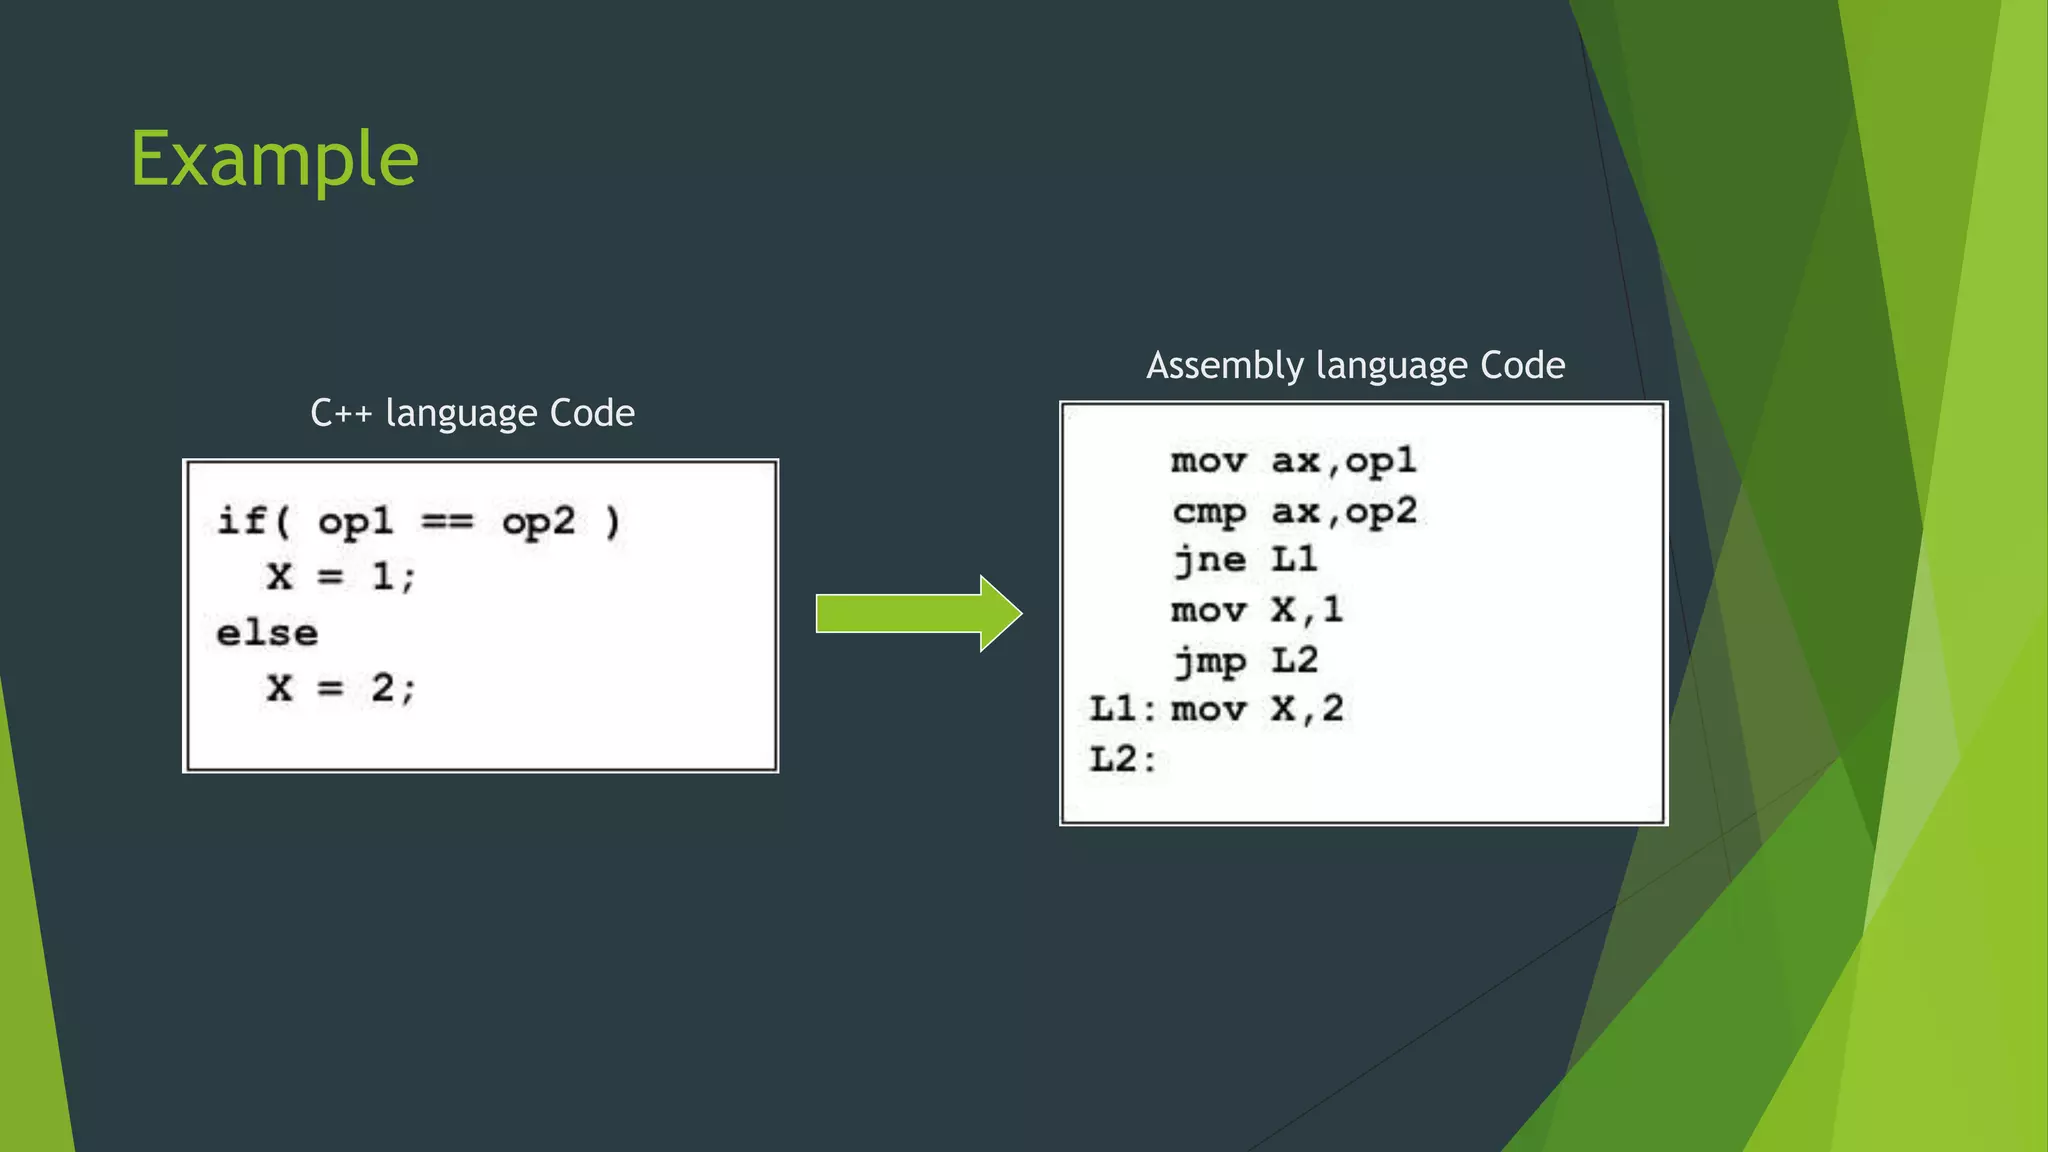
When you tell a C compiler to emit assembly, it doesn't just translate line by line. It rearranges your code, unrolls loops, spills variables to the stack, and sometimes produces something that bears almost no resemblance to what you wrote. The output depends entirely on which compiler you're using, what optimization flags are set, and what target architecture you're compiling for. I learned this the hard way trying to optimize a matrix multiplication routine that compiled differently between GCC and Clang even with identical flags. The most common path people take is using the compiler's built-in emission flags rather than trying to hand-write assembly from scratch. For GCC and Clang, the flag is -S. Run your normal compile command but swap the -o output for -S, and the compiler stops at the assembly stage. Add -O2 or -O3 if you want to see what optimized output looks like. Without optimization flags, the assembly is going to be verbose and full of dead stores — the compiler is just being literal with your code. That version is easier to read but not representative of what actually ships in production.
Understanding the C To Assembly Language Translation Process
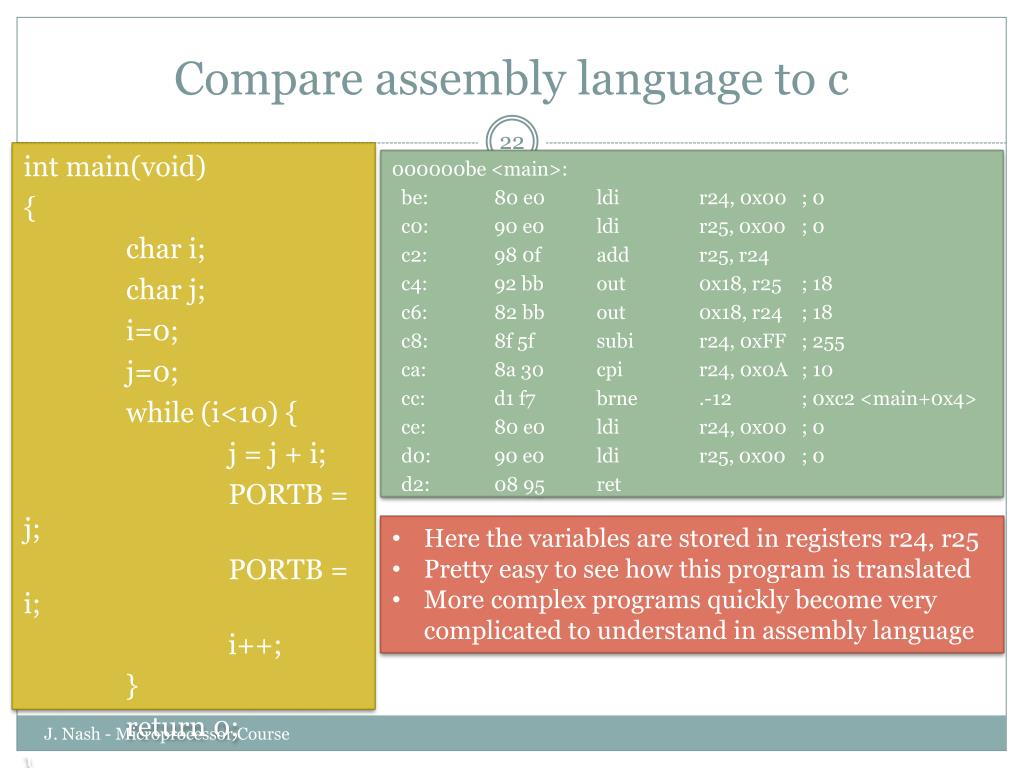
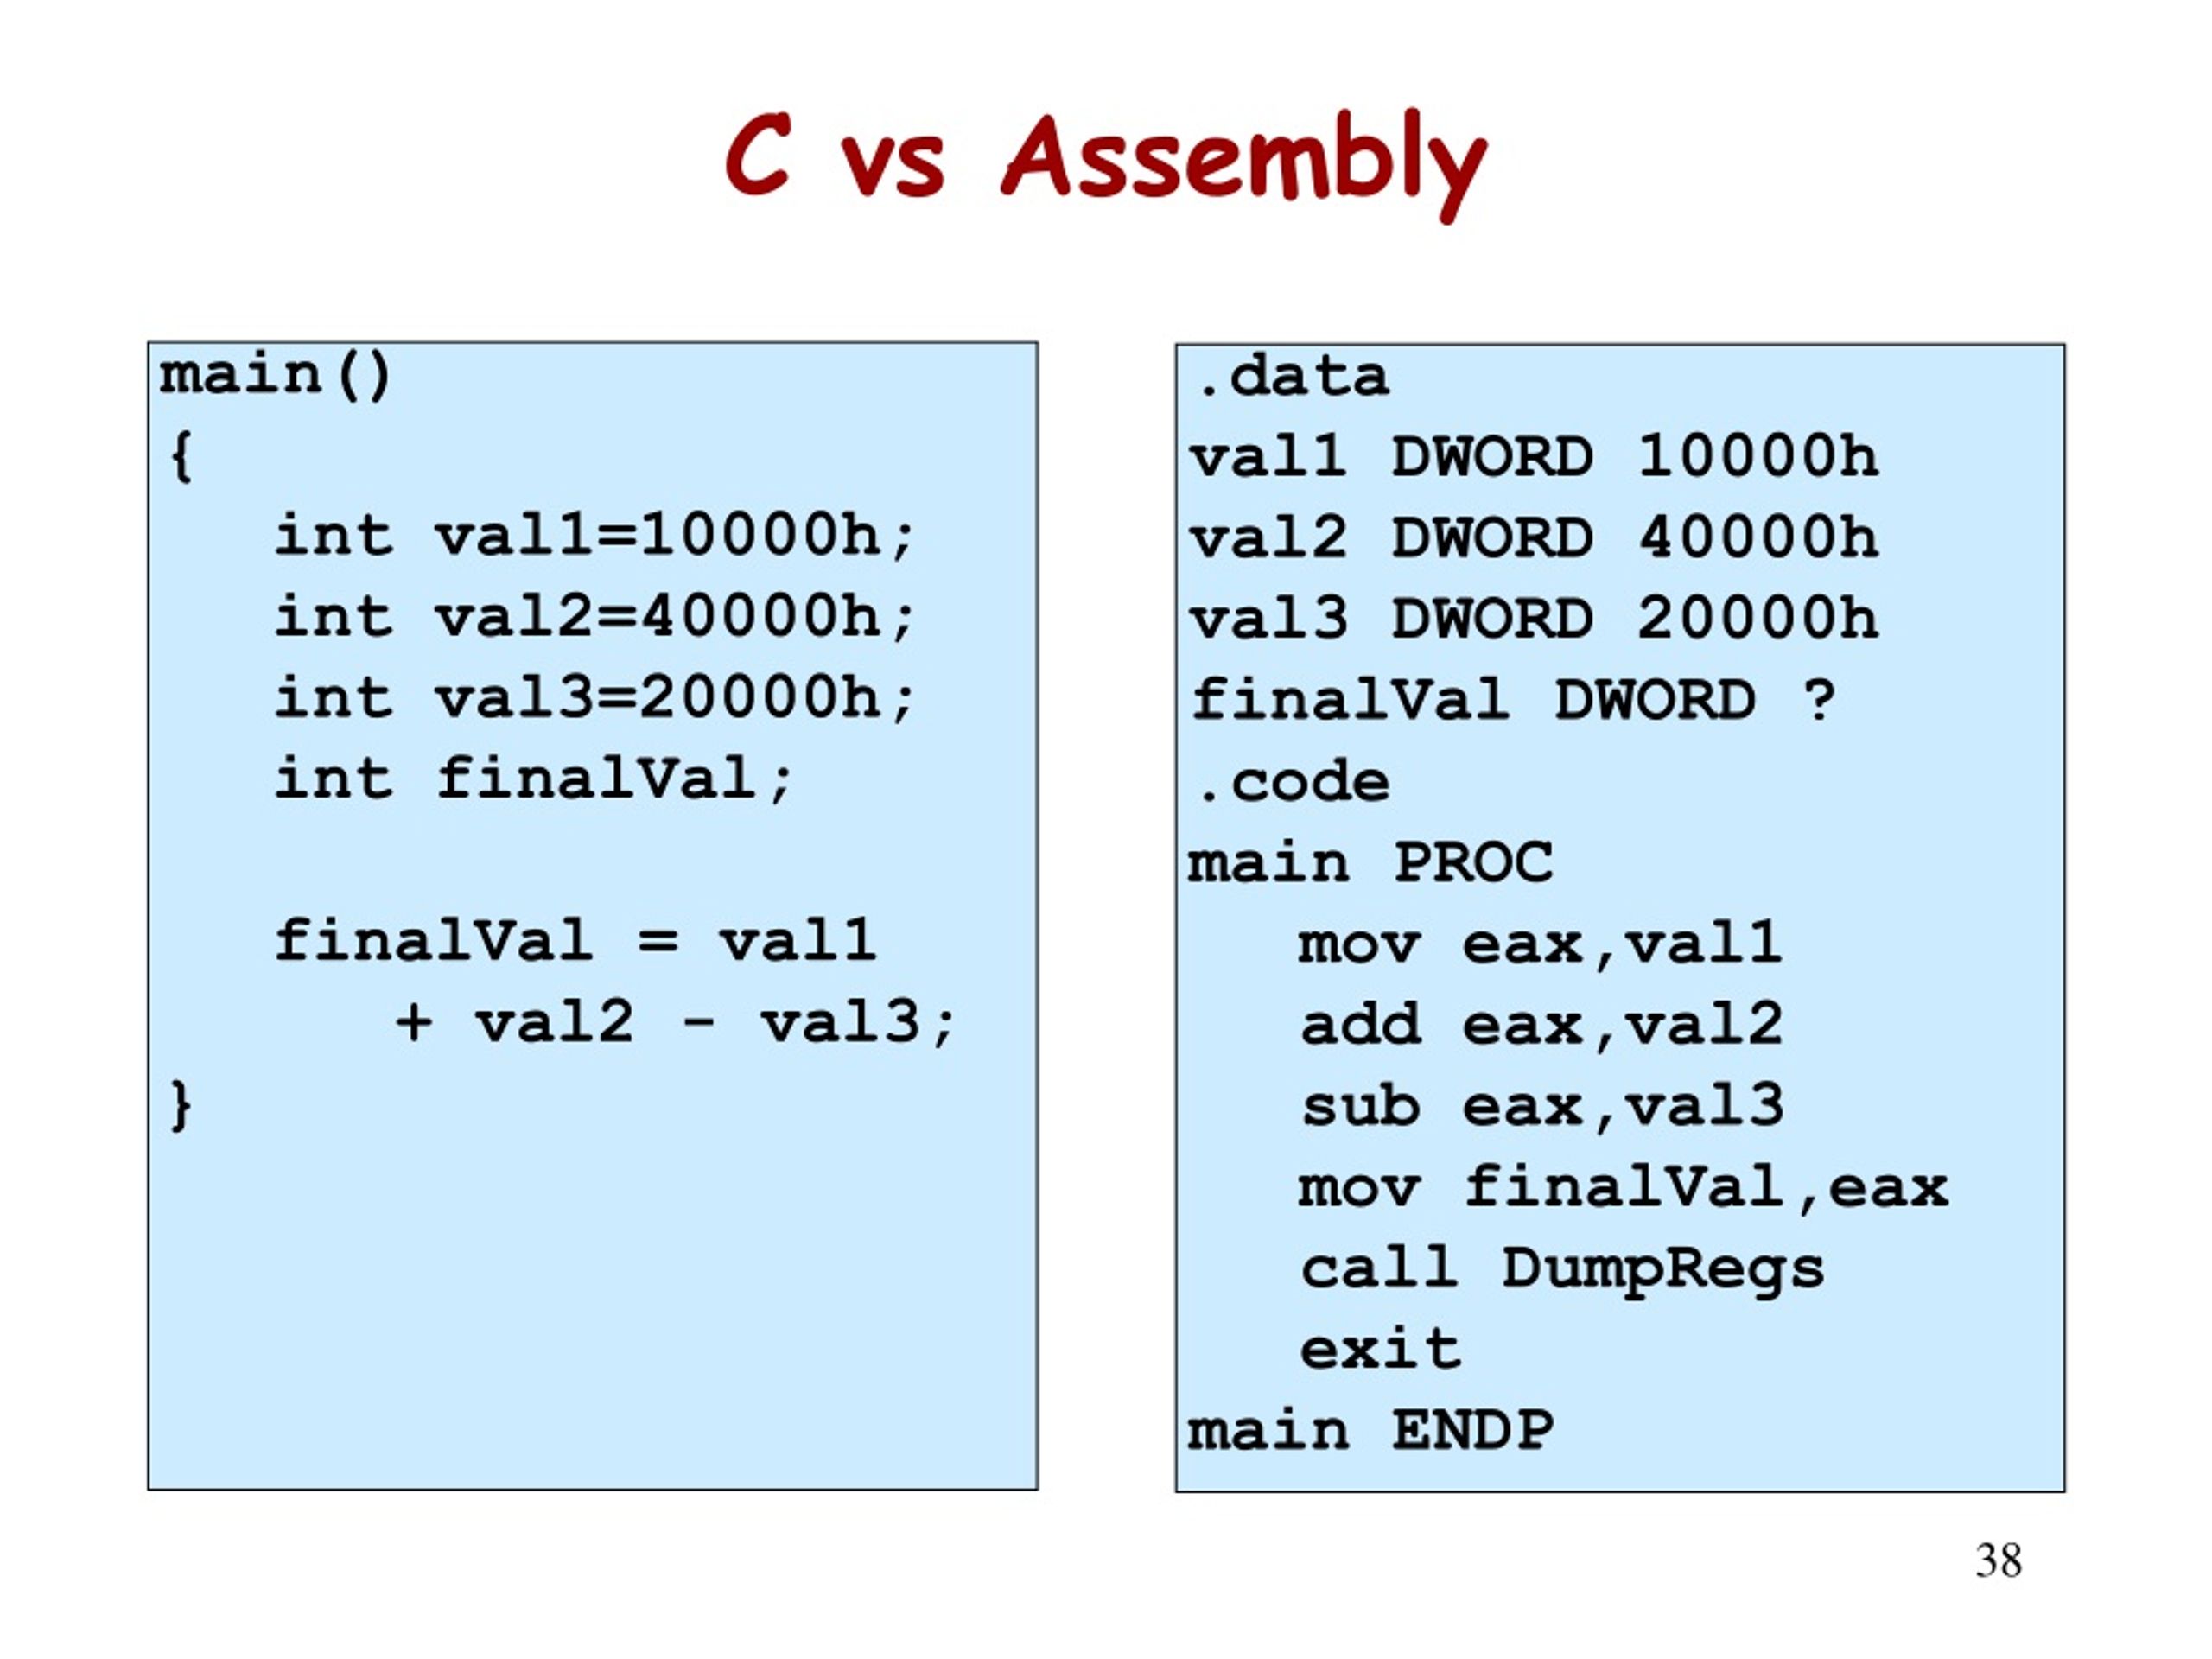
The compiler's intermediate representation does most of the heavy lifting before it ever touches assembly output. It builds a tree of operations, figures out register allocation, eliminates unreachable code, promotes memory loads to registers, and only then translates to machine instructions. This means two different C programs can produce nearly identical assembly, and one C program can produce wildly different assembly depending on context. I once had a function that compiled down to 40 lines of clean SSE instructions when called from one place, and 200 lines with stack probes and shadow space when called from another, purely because the compiler decided the calling convention and stack alignment requirements differed based on the caller's own setup. Let me show you a concrete example. Take this trivial C function: int add(int a, int b) { return a + b; }
Compiled with GCC at -O2 for x86-64, it becomes roughly: add: mov eax, edi add eax, esi ret That's three instructions. The arguments land in edi and esi because of the System V AMD64 calling convention. The result goes into eax. Nothing more. Now compile that same function with no optimization and you get something closer to ten instructions with unnecessary stack framing, because the compiler is being defensive about preserving registers and handling calls that might follow.
Get the Full Details

The register naming convention matters more than most beginners realize. On x86-64 System V ABI, the first six integer arguments come in rdi, rsi, rdx, rcx, r8, and r9. Return values go in rax. Stack space for local variables is allocated by subtracting from rsp, and you need to maintain 16-byte alignment before any call instruction. Miss the alignment and your program crashes inside library code you didn't write, which makes debugging unnecessarily painful. I ran into a specific issue once while working on a real-time signal processing library. I was comparing unoptimized and optimized assembly output for a circular buffer implementation. The unoptimized version had the ring buffer head and tail stored in memory and reloaded on every access, which was correct but slow. The optimized version kept them in registers but the compiler also inserted a stack probe because the function had a large alloca(). The probe added 16 nops at the function entry. It seemed pointless until I realized the Windows calling convention requires the OS to know your stack footprint for structured exception handling. On Linux with System V ABI, stack probes are usually omitted unless you have variable-length arrays or certain optimization levels trigger them. I removed the alloca() and replaced it with a fixed-size buffer, which eliminated the probe and dropped the function overhead by about 12 cycles per call. That might sound small, but when you're processing audio at 48kHz and calling that function thousands of times per frame, it adds up fast. Reading the assembly back is the skill that actually takes time to develop. Most people learn to recognize the calling convention setup first: push ebp / mov ebp, esp on older x86, or sub rsp, N on x86-64. Then they look for the actual computation, which is usually scattered across multiple basic blocks if optimizations are enabled. Control flow constructs like if-statements become conditional jumps (je, jne, jl, jg), loops become jump-back constructs with a decrement and a compare, and switch statements can turn into either a jump table or a series of compares depending on how sparse the cases are.
Function calls introduce another layer of complexity. The caller saves volatile registers it cares about, pushes arguments in reverse order for x86, executes call, and the callee follows its own prologue. After the call returns, the caller checks the return value in rax/eax and continues. But modern compilers often inline small functions entirely, so you won't see a call instruction at all. This is why reading optimized assembly can feel like solving a puzzle — the structure your C code had is gone, replaced by whatever the compiler decided was faster. If you need to preserve specific assembly output, the #pragma inline and __attribute__((noinline)) directives give you some control, but they're hints, not commands. The compiler can and will ignore them when inlining would clearly help. I spent an afternoon trying to force a particular helper function to stay out-of-line because I needed a stable symbol for a jump table, and GCC inlined it anyway despite the attribute. Clang respected it on the first try. Compiler differences like this are why assembly-level work usually requires picking a toolchain and sticking with it.
Practical Approaches to Working with Generated Assembly
The most practical starting point is generating assembly from a known-good C program and studying it. Write a small test file, compile with -S -O2, and open the .s file. Don't try to understand everything at once. Focus on one function at a time. Look for the prologue, find where your local variables live, trace how a loop compiles, and notice what the compiler does with conditions. After you've done this with maybe fifteen to twenty functions across different patterns, the output starts looking readable instead of alien. Compiler Explorer at godbolt.org is the standard tool for this. You paste C code on the left, see the generated assembly on the right, and can toggle optimization levels, target architectures, and different compilers instantly. It's faster than any local setup for initial exploration because you don't need to compile anything. Just paste and read. The tradeoff is that very large projects or those with specific include paths won't compile there, so you'll eventually need a local toolchain for serious work. For local development, a minimal setup needs GCC or Clang, gdb for stepping through assembly, and a text editor you can tolerate. The command sequence for iterative work looks like this:
gcc -O2 -S mycode.c gcc -O2 mycode.c -o mycode gdb ./mycode Inside gdb, you can set breakpoints at function boundaries and single-step through the assembly with stepi and nexti. The disassembler command shows you the current instruction stream. This combination lets you see exactly how your C maps to instructions at runtime, not just what the compiler claims it will do on paper. There's a persistent misconception that hand-written assembly is always faster than compiler output. In practice, this is wrong more often than not. Modern compilers are exceptionally good at register allocation, instruction scheduling, and vectorization. A hand-written version has to match all of that manually. I've seen developers spend weeks optimizing a critical loop by hand, only to find that switching from GCC to Clang or bumping the optimization level from -O2 to -O3 produced better code in an hour. The compiler also understands the specific CPU microarchitecture you're targeting. If you pass -march=native, GCC and Clang generate instructions tailored to your processor, including AVX512, FMA, and other extensions that are difficult to write correctly by hand without detailed knowledge of instruction latencies and throughput on your specific chip.
Another thing beginners miss is that assembly output varies significantly based on what libraries and headers are included. Including
Common Pitfalls and Where This Approach Falls Apart
Assembly generated from C is not meant to be modified directly and then re-linked into your C program in most cases. The compiler makes assumptions about stack layout, register usage, and calling conventions that break if you edit the .s file by hand and expect everything to still work. You can do it for small experiments, but it doesn't scale. If you need to insert assembly into a C project, use inline assembly or separate .S files that the compiler treats as standalone assembly units with their own conventions. Inline assembly in GCC uses the asm keyword with operand constraints. It's powerful but fragile. A misplaced constraint can cause the compiler to allocate the same register for two different inputs, producing silent correctness bugs. I once had a bug where an inline asm block compiled successfully and ran without crashing, but produced wrong results because I told the compiler a register was input-only when it was actually being clobbered. The compiler had placed another variable in that same register and overwrote it before the asm executed. The fix was adding the register to the clobber list, which forced the compiler to use a different register. This kind of bug is nearly impossible to catch with a debugger because the assembly itself looks correct. Portability is another hard limitation. Assembly written for x86-64 won't run on ARM, RISC-V, or any other architecture. If your project needs to support multiple platforms, relying on hand-written assembly or even studying x86 assembly for optimization insight can create a false sense of security. The same optimization strategy might not apply, and the instruction sets are fundamentally different. ARM has conditional execution flags built into most instructions, which x86 lacks. RISC-V is strictly load-store with no memory-to-memory operations. Understanding the concepts matters more than memorizing instruction sequences.

Some people try to reverse-engineer assembly back into C to understand what a binary does. This is possible with decompilers like Ghidra or IDA Pro, but the output is usually worse than the original C source. Variables get generic names, control flow becomes a mess of gotos, and type information is lost. It's useful for understanding what code does at a low level, but don't expect to recover readable, maintainable source. The best approach for learning is always starting from C and watching it compile down, not the other direction. There's also the question of whether you actually need to read assembly at all. For most application development, the answer is no. Compilers produce good enough code for general purposes. The cases where reading and understanding assembly matters are embedded systems programming, game engine development, cryptography, reverse engineering, and performance-critical numerical code. If you're building a web backend or a desktop app, you'll rarely benefit from this knowledge. If you're writing a database engine, a game physics core, or a real-time renderer, not knowing what the compiler generates is a real liability. The learning curve is steep but not infinite. I'd estimate that spending two to three weeks reading compiler output daily — even just ten minutes a day — builds functional literacy. You don't need to memorize every instruction. You need to recognize patterns: how loops compile, how recursion becomes iteration or stays recursive, how data structures map to memory access patterns. Once those patterns click, the assembly stops being a foreign language and starts being a slightly ugly dialect of the code you already write.