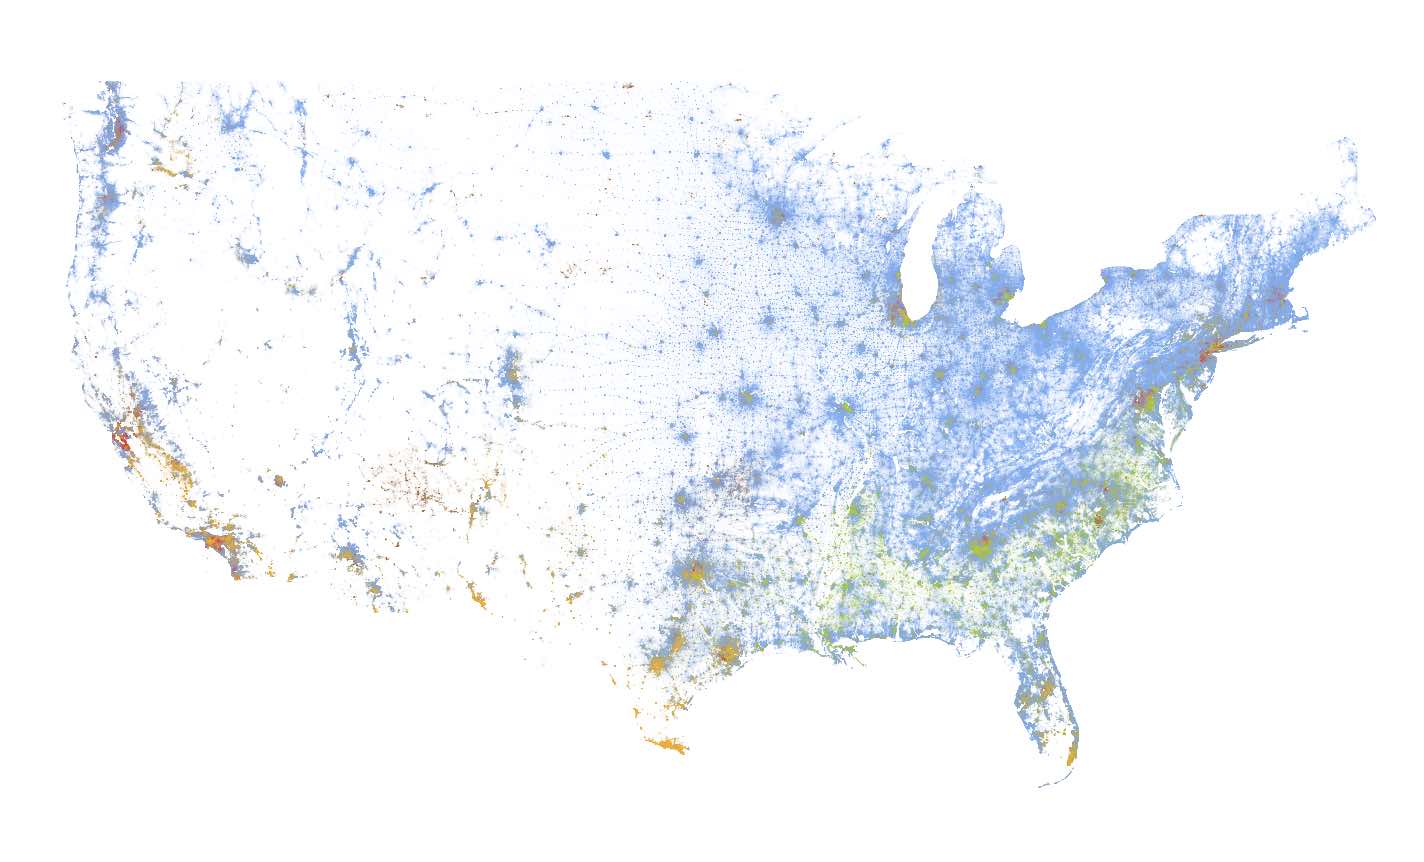
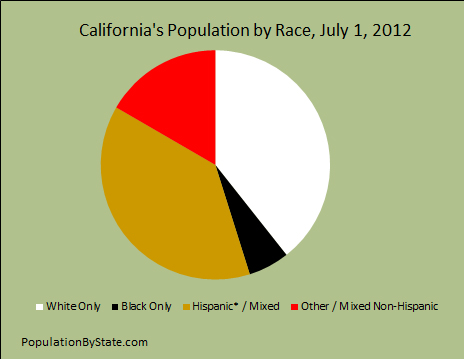
Working With California Racial Demographic Data
I spent a lot of time pulling and cleaning California population by race data over the years, mostly for grant applications and municipal planning reports. The data itself isn't hard to find, but the way the categories shift between sources makes merging datasets painful if you don't know what you're looking for. The U.S. Census Bureau's American Community Survey is the primary source. You can grab it from data.census.gov or use the Census API directly. For state-specific breakdowns, the California Department of Finance publishes annual P-D1 population estimates that break down by race and Hispanic origin. Those are hosted at dos.ca.gov. Another useful source is the California Health Interview Survey, though that's more health-outcome focused than pure demographic counts. For most people just needing headcounts, stick with the Census or the state P-D1 reports.
How the categories actually work
Here's the thing most guides skip: the Census race and Hispanic origin questions are separate. Hispanic is treated as an ethnicity, not a race. So when you see "White" in one table and "Hispanic" in another, those aren't mutually exclusive groups in the underlying data. A person can be counted in both depending on which table you pull from. The Census now uses six race categories: American Indian or Alaska Native, Asian, Black or African American, Native Hawaiian or Other Pacific Islander, White, and Some Other Race. There's also the Two or More Races option that has grown significantly since 2020 when they allowed marking multiple boxes more prominently. The California P-D1 estimates use a different category structure than the Census. They combine Some Other Race into the totals differently and their Asian breakdown goes into much finer detail — Chinese, Filipino, Vietnamese, Hmong, Korean, Japanese, and so on. If you're comparing source to source, mismatched category granularity will make your numbers look wrong even when they're not.
A practical workflow that actually works
I usually pull the ACS 5-year estimates for tract or county level work, and the P-D1 for quick state-level checks. Here's how I do it without losing my mind: First, I download the raw tables from data.census.gov as CSV. Then I write a quick Python script using pandas to normalize the column names across files. The key is matching on the GEOID — the geographic identifier — rather than city or county names, because spelling varies between sources and "San Fransico" appears more often than you'd think in older datasets. For the Hispanic/non-Hispanic split, I pull the B03002 table specifically, which gives Hispanic or Latino by race cross-tabs. Don't try to derive this from other tables. You'll get rounding errors that compound across geographies.
Get the Full Details
Common pitfall I ran into the hard way
I once merged Census tract data with school enrollment figures for a district allocation report and the numbers didn't add up. Took me two weeks to realize the issue: the Census treats group quarters — prisons, college dorms, military barracks, nursing facilities — separately from the civilian non-institutional population. My enrollment data included institutionalized people, my Census population data didn't. Schools in counties with large state institutions showed artificially low racial diversity ratios because the underlying denominator was missing roughly 8,000 people in my case. The fix was pulling the P1 table which includes group quarters populations and subtracting the institutionalized count before merging. It changed my percentages enough that three school boundaries needed reclassifying.
Counter-intuitive things to keep in mind
The 2020 Census saw a huge spike in the "Some Other Race alone" category in California — up over 40 percent from 2010. A lot of that shift didn't come from actual population change. It came from respondents interpreting the question differently after the formatting changed. The Census Bureau acknowledged this in their documentation but the numbers stayed inflated in early releases. If you're doing year-over-year comparisons, treat 2020 and later as a break in the series, not a continuation. Another thing: the Asian population breakdown in California is one of the most detailed in the country, but the ACS sample sizes get thin at the tracts level for specific subgroups like Nepali or Bhutanese. At the county level you're usually fine, but if you need tract-level data for South Asian subgroups, the margin of error will be enormous. I've seen MOEs exceed 200 percent for certain tracts. Don't publish those numbers without flagging them.
Limitations you should know about
Self-identification is the foundation of this data, which means it changes every decade as attitudes shift. The Census can't capture cultural identity, nativity, or immigration generation from race data alone. If your analysis needs those dimensions, you'll need to pull tables B05002 for nativity and B07414 for place of birth alongside the race tables. The ACS 1-year estimates only cover geographies with 65,000+ population. That excludes most of California's smaller cities and all rural counties at the city level. You'll need the 5-year estimates for those areas, but then you're working with a five-year window of data that may not reflect recent migration patterns, especially in fast-growing exurban areas. Hispanic origin data from the Census has known undercoverage issues in certain California counties according to post-enumeration surveys. The overcount/undercount estimates suggest Mexican-origin populations in parts of Central Valley agricultural counties may be undercounted by a few percentage points. For most planning purposes this is acceptable, but if you're doing funding allocation that depends on precise counts, factor in the uncertainty.

Downloading the data
Census data: data.census.gov — search "California race" and filter by table type. For the P-D1 estimates: dos.ca.gov/stats/pd1/. I keep a Google Sheet that maps the Census table IDs to readable names so I don't have to dig through documentation every time. The main ones you'll need repeatedly are B03002 for Hispanic origin by race, B02001 for race alone, and B02018 for race alone and in combination. The "in combination" tables are useful when you need the Two or More Races counts properly attributed. If you need pre-cleaned data rather than raw tables, the California Open Data Portal at data.ca.gov aggregates some of this, though the refresh cycles are slower than pulling direct from Census. For a one-off project it's fine. For anything you'll update regularly, go straight to the source and build your own pipeline.
The biggest time-saver I found was writing a single lookup function that handles the GEOID normalization once and reusing it across every project. Saved me roughly three hours per report compared to manual matching. Not glamorous, but that's where the real work lives in this stuff.