Getting the Data Right When You're Working With It
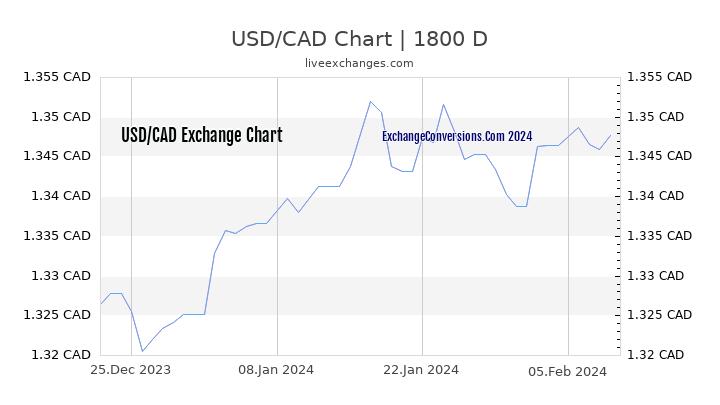
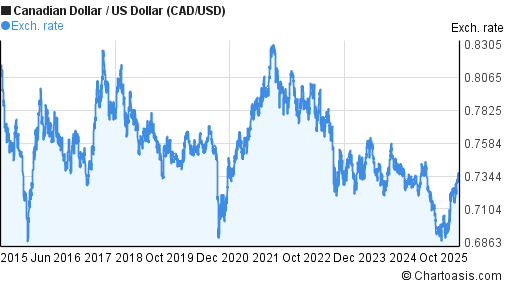
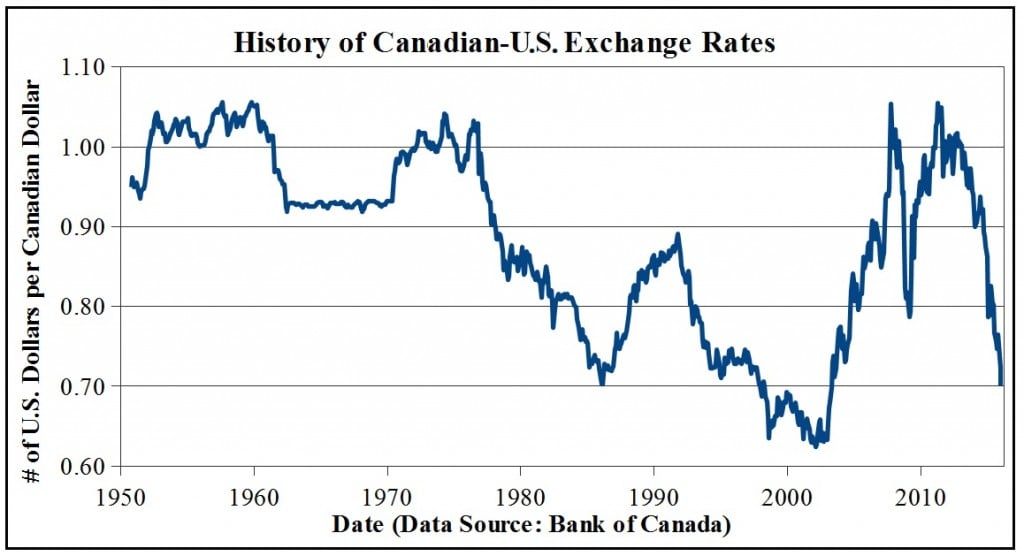
Most people pull the data from a handful of sources and assume they are interchangeable. They are not. The Bank of Canada publishes daily noon rates, the US Federal Reserve gives end-of-day fixes, and commercial banks like RBC or TD post their own intermediate rates that can drift a few basis points from the benchmark. If you are building a model or doing historical analysis, mixing these without tagging the source will corrupt your results. The long-term trend runs roughly between 0.63 and 1.10 CAD per USD over the past few decades. That range itself is misleading if you just look at it without context. The loonie spent years in the low 0.60s around 2002, climbed above parity in 2011 when oil hit $140 a barrel, then crashed back toward 0.70 during the 2014 oil slump. More recently it has bounced between 0.72 and 0.79. The pattern is not random. It tracks commodity prices, the interest rate differential between the Fed and the Bank of Canada, and occasional risk-off flows into the dollar. For raw data I usually go to the Bank of Canada's website. Their time series is clean, well-documented, and free. The ID is CAN/USD or sometimes listed as daily average noon spot rate. The downloadable file is a CSV, which is about as boring as it gets, but it has what you need: date, value, and clear notes about methodology. I have also used the FRED database for USD/CAD. FRED's series ID is EXUSCA. The upside is the API. The downside is the data gets revised occasionally, which is why I always download the latest version and re-parse before running any analysis.
How I Actually Work With This Data
I write a short script that pulls the data, handles the direction convention, and saves a local copy. I treat the direction convention as the first problem. Some sources quote CAD per USD, which is the standard from the Bank of Canada perspective. Others quote USD per CAD, which flips everything. If you do not check this, you will get returns backwards and it will look plausible until you compare against a chart and realize something is wrong. The conversion is straightforward. To flip CAD per USD to USD per CAD, you take one divided by the rate. So when the Bank of Canada reports 1.35 CAD per USD, that is about 0.7407 USD per CAD. I keep the primary series in CAD per USD because that is the industry standard for this pair, but I log the source and the direction convention in a metadata field. That metadata field has saved me more than once when I came back to old work and needed to know exactly what I was looking at. I store the data locally. Cloud APIs change, endpoints get deprecated, and free tiers introduce rate limits that make repeated pulls slow. I set a weekly cron job to refresh the CSV and compare the new rows against what I already have. Any discrepancies trigger a manual spot-check. Most of the time there are none, but the times there are, they are usually small revisions from the source, not actual market errors.
A Specific Problem I Hit and How I Fixed It
I was backtesting a simple pairs strategy against the loonie and the US dollar a few years ago. The strategy looked great on paper until I realized the historical data had a gap around a specific holiday period. The Bank of Canada does not publish on certain statutory holidays, and some commercial feeds skip weekend data entirely. My script was forward-filling the missing values, which is fine for visualizations but terrible for backtesting. You end up with artificial continuity that inflates performance. The workaround was to stop forward-filling for backtests and instead drop the gap days from the signal calculations, while keeping them in the returns computation only when both legs were actually traded. I also added a holiday calendar file and pre-emptively removed non-trading dates before generating any synthetic fills. This cut false signals and made the backtest match live execution much more closely. It added maybe twenty minutes to the setup, but it changed the results enough that I stopped trusting anything that used naive interpolation.
Get the Full Details
Common Pitfalls That Are Easy to Miss
One issue is survivorship bias in commercial datasets. Some vendors sell cleaned historical series that exclude periods of extreme volatility or early years when liquidity was thin. If you are analyzing regimes, that exclusion matters. The loonie's moves around the 2008 financial crisis and the 2020 pandemic flash crash are not anomalies you should smooth over. They are structural features of the pair. Another issue is confusing spot rates with forward rates. Forward curves embed the interest rate differential, so the forward rate will diverge from the spot rate over longer tenors. If you pull what you think is spot data but it is actually a forward quote, your spread calculations will be off. I always verify the tenor and label before using any dataset. The Bank of Canada clearly marks spot rates. Commercial bank pages sometimes do not. There is also the matter of rounding. Many public tables round to four decimal places. Four places is standard for most trading purposes, but if you are computing small spreads or doing high-frequency regression work, that rounding introduces noise. The raw data files usually have more precision, so I prefer the raw downloads over the summary tables.
What I Recommend for Different Use Cases
If you are doing basic research or a class project, the Bank of Canada CSV is sufficient. Download it, note the date format, and convert if needed. Most spreadsheet tools handle it without trouble. I use pandas for anything beyond casual lookups. A few lines of code to load the CSV, parse dates, and export to a cleaner format takes about five minutes once you have the template. If you need programmatic access, FRED's API is reliable and has generous rate limits for personal use. I typically pull the last twenty years in one call. For intraday data or tick-level history, you will need a commercial provider. The free sources simply do not go that granular. Even so, intraday data for USD/CAD is less noisy than you might expect because the pair is heavily traded and well-booked. The spreads stay tight during overlapping sessions and widen during Asian hours. For longer-term regime analysis, I combine the Bank of Canada daily data with monthly oil price data. The correlation is not perfect, but it is strong enough to be useful. I usually lag the oil price by one month to account for the time it takes for commodity shocks to flow through to the currency. That lag improves fit without overfitting, which is a better outcome than chasing a higher R-squared with too many lags.
A Few Practical Notes
Data is not going to be perfectly clean. Gaps appear. Revisions happen. Sources disagree by small amounts. The trick is to be explicit about what you are using and why. Keep a simple log: source name, series ID, download date, and any transformations applied. When someone asks where your numbers come from, you should be able to point to that log and reproduce the result in under an hour. The pair itself is straightforward to work with compared to exotic crosses. Liquidity is deep, spreads are tight, and the macro drivers are well-documented. The hard part is not the data availability. It is making sure you treat the data consistently and do not let convenience choices sneak into your methodology. A clean CSV from a reputable central bank beats a polished but poorly sourced dataset every time.