How I Actually Check Economics Work
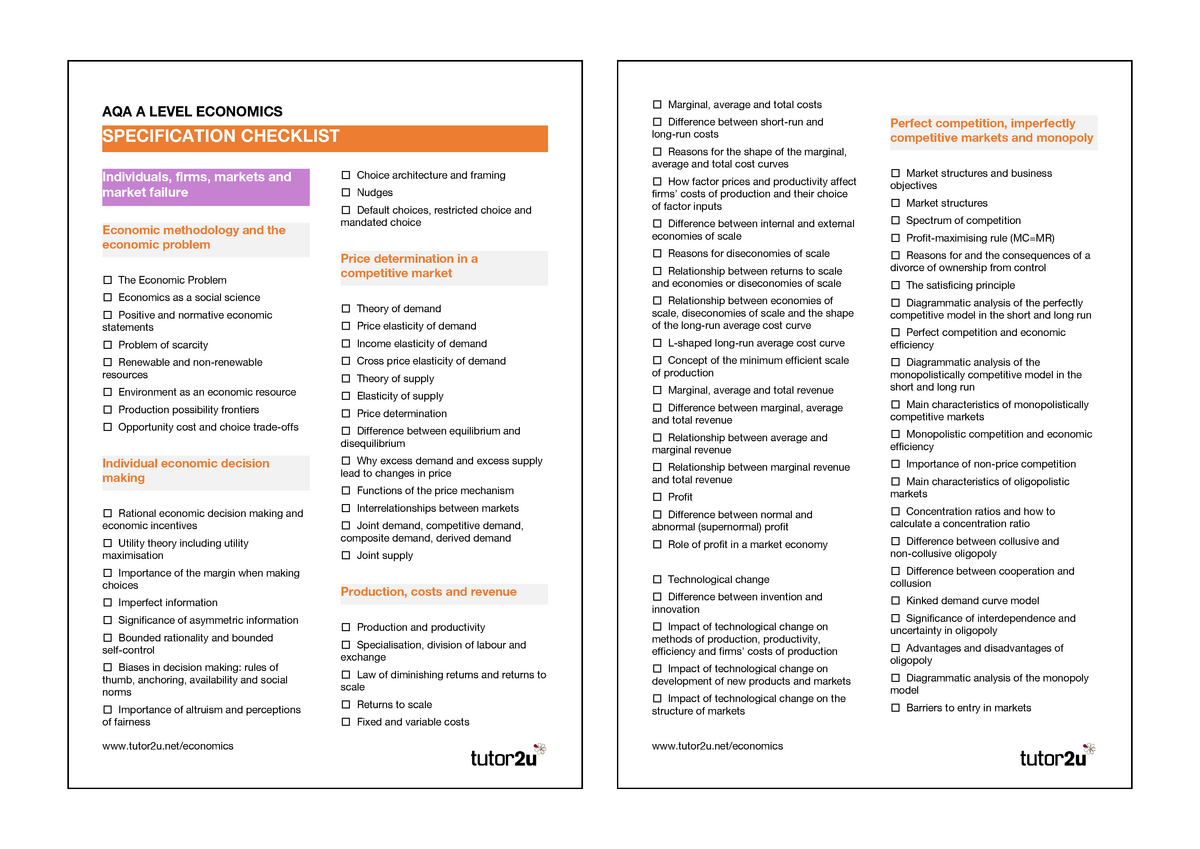
I spent three years working on a quantitative research team, and honestly the most useful thing I ever built wasn't some fancy model. It was a simple checklist I made for reviewing economics assignments and papers before they went out. You might be looking for Checklist For Economics Best practices, so here is what actually works in practice. Before you even look at the data, write down what you are testing. I see people skip this constantly. They run regressions first, then try to figure out what question they were answering. That is backwards. Your hypothesis should be written in plain language, not statistical notation. If you cannot explain your research question to someone outside economics in two sentences, you do not understand it well enough to test it. After the hypothesis comes the identification strategy. This is where most student papers fall apart. They show correlation and call it causation. A proper checklist forces you to ask: what would have to be true for this coefficient to actually represent a causal effect? The answer is usually "a lot of things that are clearly false." That is not a failure. It is information.
My Personal Battle With Stata
I had a paper once where the results looked perfect. R-squared of 0.87, coefficients significant at the 1 percent level, everything you want. Then I realized I had forgotten to cluster the standard errors at the right level. When I fixed it, the confidence intervals became so wide the results were completely insignificant. Took me four hours to debug because I had not checked my clustering assumption in the first pass. I now add a specific line to my checklist: "Are standard errors clustered appropriately? If not, document why." That one line has saved me from similar mistakes at least six times since. This is the part nobody likes but everyone needs. Before any analysis, verify these items: Variable types and units. Make sure every variable is what you think it is. I once analyzed a dataset where the income variable was actually in thousands but stored as a string with dollar signs. Spent two days running models before someone pointed out the format issue.
Missing values. Report the percentage missing for every variable. If more than 20 percent of your key independent variable is missing, your sample size just shrank dramatically without you realizing it. Document how many observations you lost at each cleaning step. Outliers. Do not delete them without checking. I had a case where a single outlier was actually a correct value for a legitimate observation. When I removed it, my results flipped direction completely. Verify the data entry before discarding anything.
Get the Full Details
Regression Diagnostics You Actually Need
Most textbooks list twelve diagnostic tests. You need about four. Run these after every regression: Variance inflation factors. Anything above 10 means you have multicollinearity problems. This is not theoretical. I once had a model where GDP growth and investment growth had a VIF of 23. The individual coefficients were meaningless even though the F-test was significant. Residual plots. Plot residuals against fitted values. If you see a pattern, your model is missing something. I spent weeks trying to fix significant results that were actually non-significant because I ignored the residual plot showing heteroskedasticity.
Sample size reporting. Always report N after every regression. Many students write results without mentioning how many observations they dropped. Your reader has no way to know if you analyzed 10,000 cases or 147.
The Identification Checklist That Actually Helps
For causal inference, work through these questions in order: First, is there a source of exogenous variation? Without this, you are doing descriptive statistics with extra steps. Natural experiments, policy changes, instrumental variables - something needs to break the correlation between your treatment and the error term. Second, check the parallel trends assumption if you are doing difference-in-differences. I ran a DiD analysis once where the pre-treatment trends were clearly diverging. The post-treatment results looked dramatic but were completely invalid. Always plot the trends before running the model.
Third, consider alternative explanations explicitly. Write down three other reasons your result might be wrong, then try to rule them out. This is what separates professional work from student papers. I once had a referee ask about omitted variable bias, and because I had already documented it in my checklist, I could respond with specific tests instead of panic.
Common Pitfalls I See Repeatedly
The biggest mistake is p-hacking without realizing it. Run twenty specifications, report the one that works. This is almost impossible to detect from the paper alone. Always pre-register your main specification if possible. If not, report all specifications and let readers decide. Another common error is ignoring sample selection. I analyzed labor market data where the sample only included employed workers. Any analysis of wages using this sample automatically biased results upward. Document your sample selection criteria explicitly. Time series data requires different checks. Test for stationarity before running regressions. I once regressed two non-stationary series and got an R-squared of 0.95. The relationship was completely spurious. Run unit root tests on every time series variable.
When Your Checklist Fails
Sometimes no amount of checking fixes bad data. I worked on a project once where the measurement error in the key variable was so large that even the best instrumental variable approach could not recover the true effect. The confidence intervals were enormous. In these cases, be honest about the limitations rather than pretending the results are robust. Some questions simply cannot be answered with observational data. If you cannot find a credible source of exogenous variation, acknowledge this upfront. I have seen many papers waste months trying to force identification where none exists. Better to state the limitation early and move on to a feasible question.
The Final Verification Step
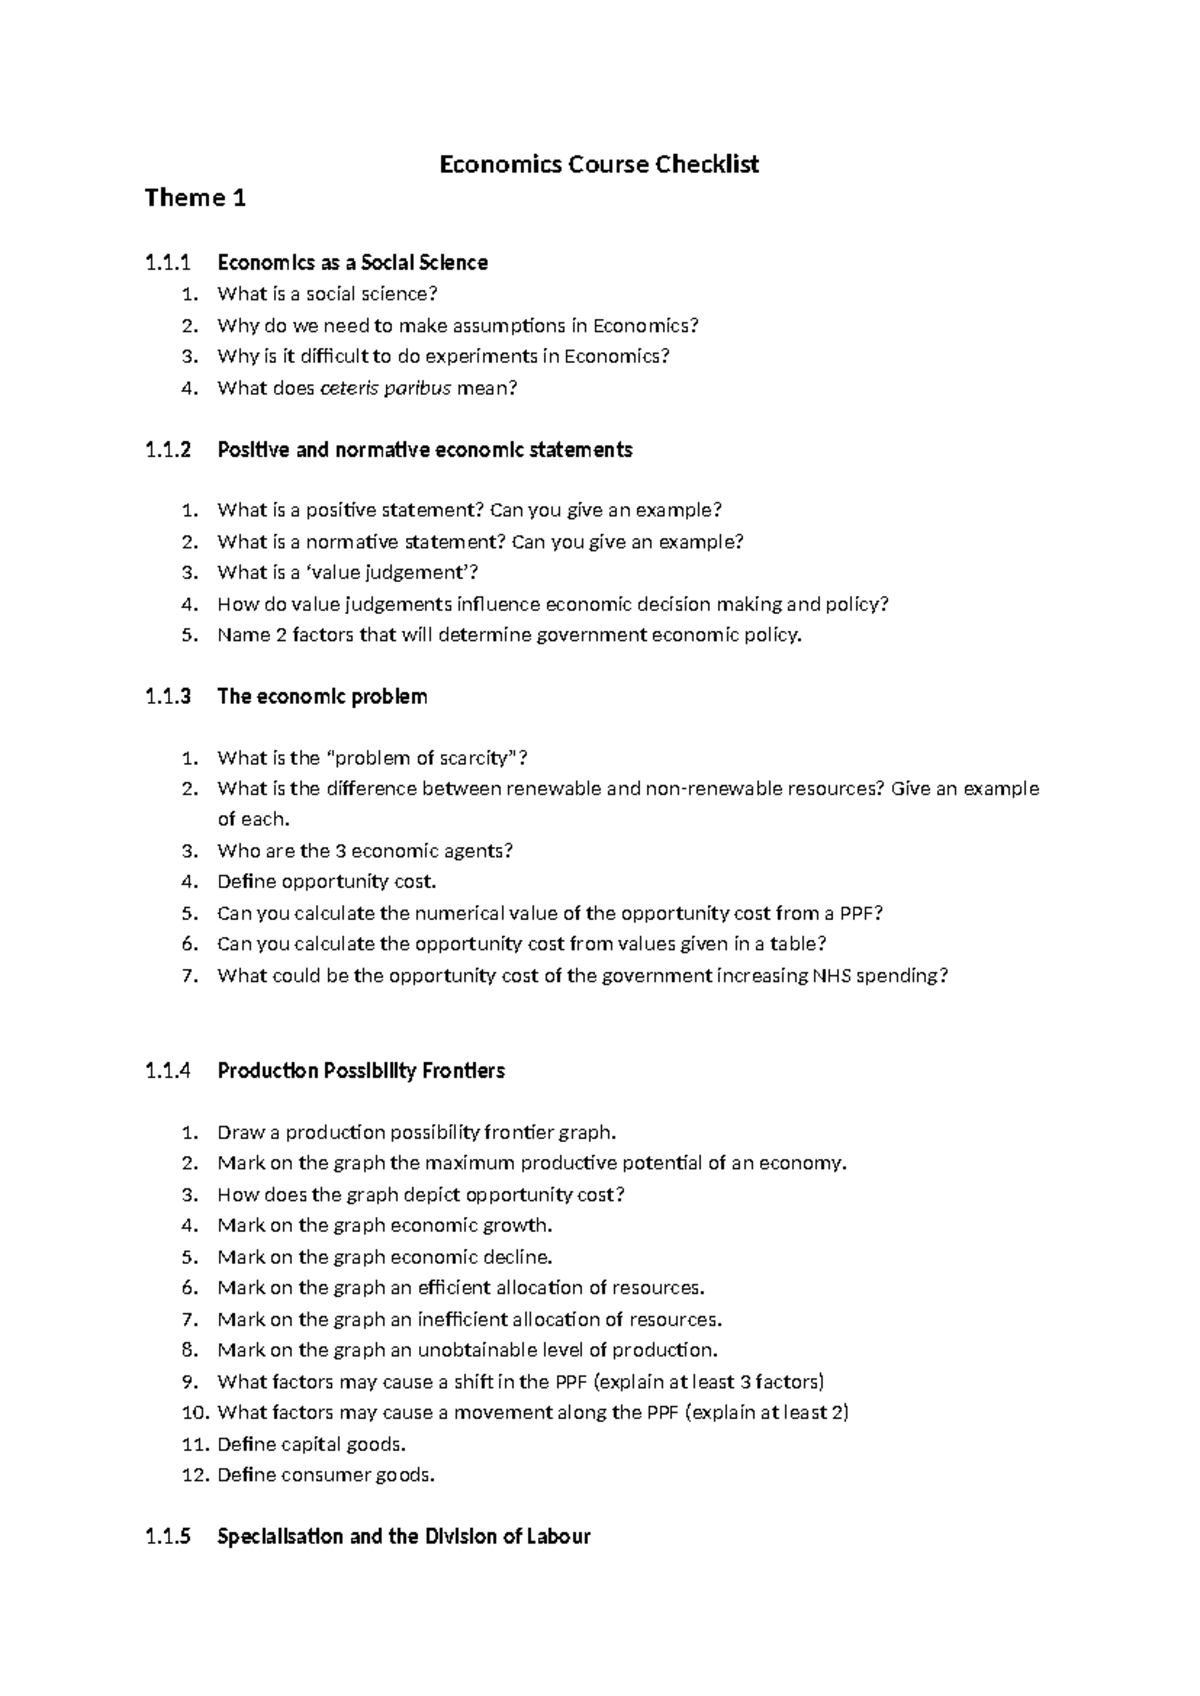
Before submitting any economics paper, run through this final checklist. Replicate your main result by hand with a small subset of data. If you cannot get the same coefficient by calculating it manually, something is wrong with your code. I spent an entire weekend debugging a paper because I had accidentally reversed two variable labels. The results looked reasonable but were completely backwards. Check your reference section formatting. I have seen papers rejected because the bibliography did not match the citation style requirements. This seems minor but matters more than you think. Read your paper aloud before submitting. You will catch errors that silent reading misses. I found three critical mistakes this way, including a sign error that flipped my main interpretation completely.