What Actually Happens When You Try to Keep Up With ML Every Month
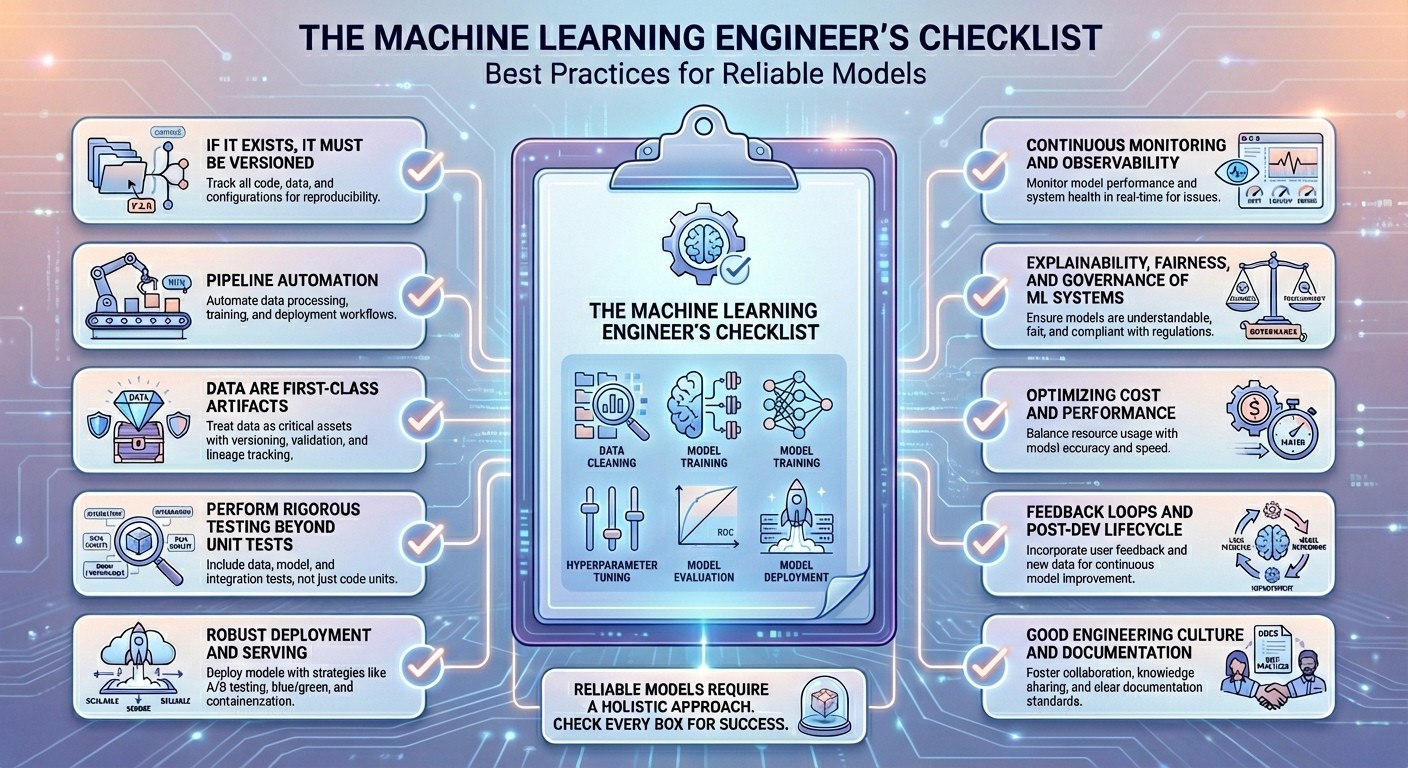
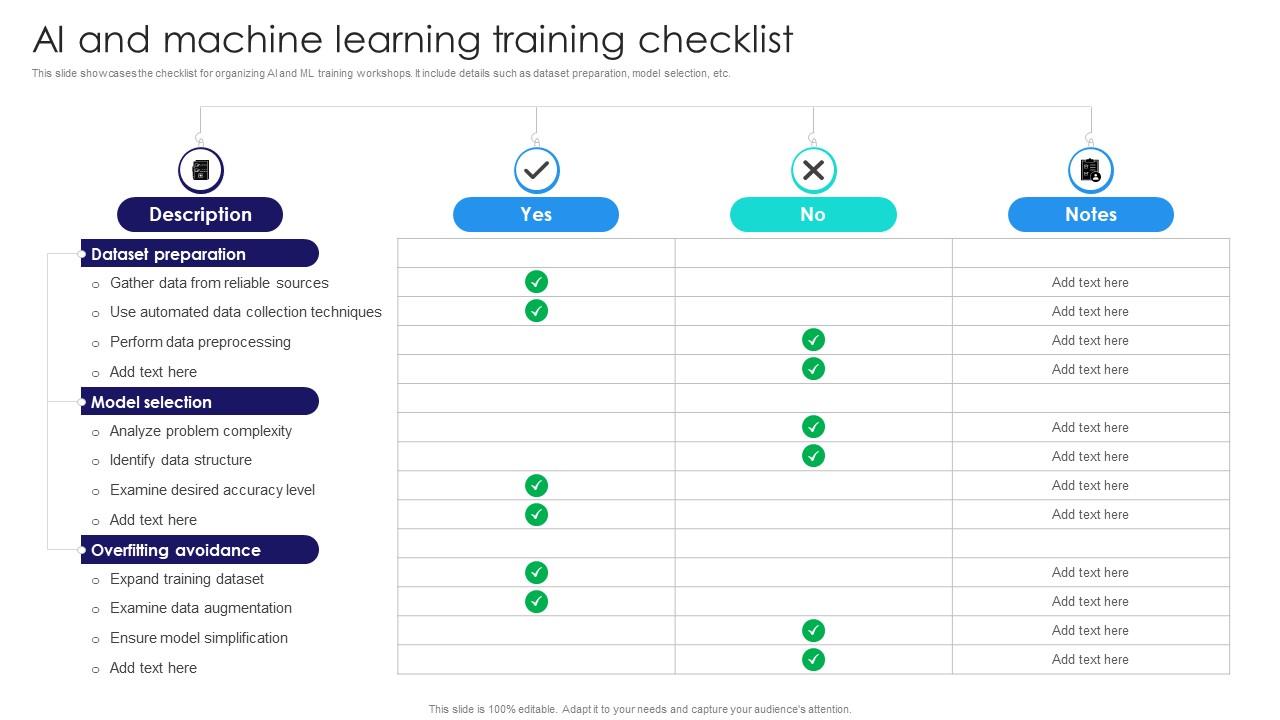
I keep a running document I call the Checklist For Machine Learning Monthly. It started as something informal when I was trying to track what my team was deploying and what was actually staying deployed. Most people treat it like a novelty project. It isn't. The problem is that the ML space moves fast enough that if you're not writing things down, you end up repeating the same mistakes in different clothing. I've seen teams re-implement the same data drift detection they solved two years ago because nobody documented the original fix. The checklist keeps that from happening. The format is simple. Every month I go through a set of categories that matter in our production environment. There are about thirty items spread across data quality, model performance, infrastructure, and governance. The trick isn't checking boxes. The trick is deciding what to change when a box lights up red. Last year I ran into this edge case where our feature store was reporting perfect latency numbers because the caching layer was serving stale results. The checkmark was green. The model predictions were garbage. I had to add a specific validation step that compares cached values against real-time computation on a random sample of ten percent of requests. That one issue cost us three weeks of debugging before we caught it. After that, the monthly checklist became a lot more useful because it included that exact scenario.
Download the Current Checklist For Machine Learning Monthly
You can find the latest version at mlchecklist.io/monthly. It's updated quarterly. The current version covers data validation, model monitoring, retraining pipelines, bias audits, and deployment health. It's free and open source. We don't sell a premium tier because there's no point. The checklist only works if you actually use it, and nobody pays for a document they should already be maintaining themselves. Here is the straightforward breakdown of how the checklist functions in practice. Start with the data section. Every month you need to verify that your training and production data distributions haven't diverged beyond acceptable thresholds. This isn't about running a single statistical test and calling it done. You need to look at individual feature distributions, check for missing value patterns that might indicate upstream failures, and confirm that your data ingestion pipeline hasn't silently dropped rows. I once spent an entire sprint investigating model degradation only to discover that our ETL pipeline had stopped ingesting a particular geographic region due to a timezone misconfiguration. The checklist would have caught that in under an hour if someone had actually run through it that month.
Moving to model performance. Check your primary metrics against the last three months of baseline. If you're only looking at accuracy you're already behind. You need F1 scores for imbalanced classes, calibration curves for probabilistic outputs, and inference latency percentiles. The 99th percentile latency matters more than the average. A model that responds in fifty milliseconds for most requests but takes eight seconds on edge cases is worse than a consistently slow model. We switched to using p95 and p99 latency as hard gates in our deployment pipeline. Models that fail those gates don't ship, regardless of how good their offline metrics look. Infrastructure and deployment health. Verify that your feature store is current. Check that your model registry contains the correct version tags. Confirm that your rollback procedures work by doing an actual rollback drill. I can't tell you how many teams skip this step and then discover during an incident that their previous model version was deleted three months ago during a cleanup. We now run a monthly backup verification that actually restores a previous model and validates its outputs. It takes about twenty minutes. Skipping it takes about six hours when something breaks on a Friday evening. Bias and fairness audits. This section gets skipped far too often. Run your demographic parity and equal opportunity difference calculations across your protected attributes. If you don't have protected attributes in your dataset, you still need to check for proxy variables. Zip code, device type, and purchase history can encode the same information in ways that are much harder to detect. I found a case where our model was effectively redlining neighborhoods because we used transaction velocity as a feature. The feature itself looked harmless. The monthly bias audit caught it because we were comparing performance across regions.
Get the Full Details

Governance and documentation. Log every model change, every data update, and every pipeline modification. If you can't reconstruct what happened in a given deployment window, you don't have governance. You have hope. We use simple Git-based audit trails combined with a weekly summary pushed to our internal wiki. It's not fancy. It works. The alternative is the panic that happens when a regulator or an internal audit team asks for a full history and you realize you've been keeping records in three different Slack channels and a personal spreadsheet.
Where This Approach Breaks Down
The checklist isn't universal. It assumes you're running a production ML system with enough volume to justify the overhead. If you're training a single model for a class project or a one-off experiment, this is overkill. You'd spend more time maintaining the checklist than you would saving by following it. The monthly cycle also assumes a steady-state deployment pattern. If you're shipping models weekly or daily, you might want to compress the checklist into a weekly format instead. We tried monthly reviews for a fast-moving recommendation system and found that drift wasn't detected until it was already affecting user engagement. We moved that team to weekly checks and cut the mean time to detection from three weeks to four days. Another limitation is that the checklist doesn't replace monitoring. It's a retrospective review tool. Real-time alerting still needs its own infrastructure. The checklist complements that infrastructure by asking questions that automated systems don't catch. Why did this feature distribution shift? Which upstream change caused this metric degradation? Are we still compliant with the policies we claimed to be compliant with? These are the kinds of questions that require human review, not a dashboard. The biggest practical constraint is consistency. The checklist only helps if you actually complete it every month. I've seen teams treat it like a compliance exercise where they rush through the items the last Friday of the month just to say they did it. That's worse than not having one. You get the false confidence of checked boxes without the actual risk reduction. I recommend scheduling it on the same week every month, ideally right after the sprint planning session. That way it becomes part of the rhythm instead of an afterthought.
One final thing that isn't obvious. The checklist should evolve. Every quarter I review the list and remove items that have become redundant, add items for new risks we've encountered, and adjust thresholds based on what we've learned. The current version has about forty percent more items than the original draft. That's normal. If your checklist hasn't changed in six months, you're probably missing something that became relevant during that time.