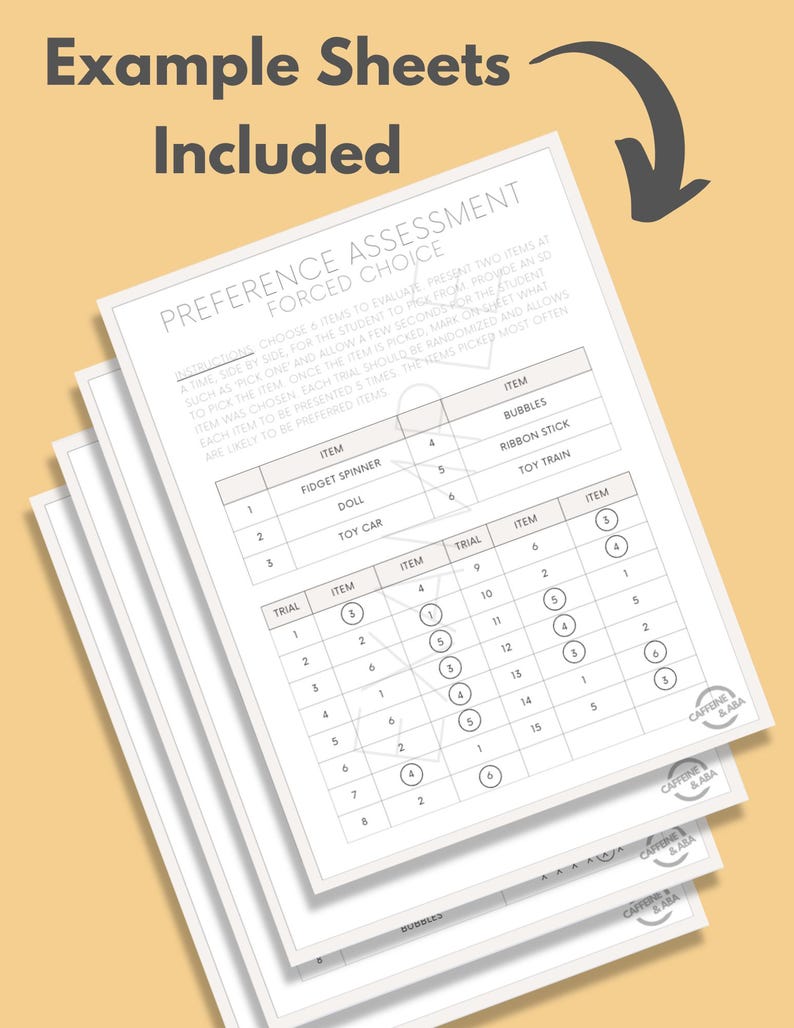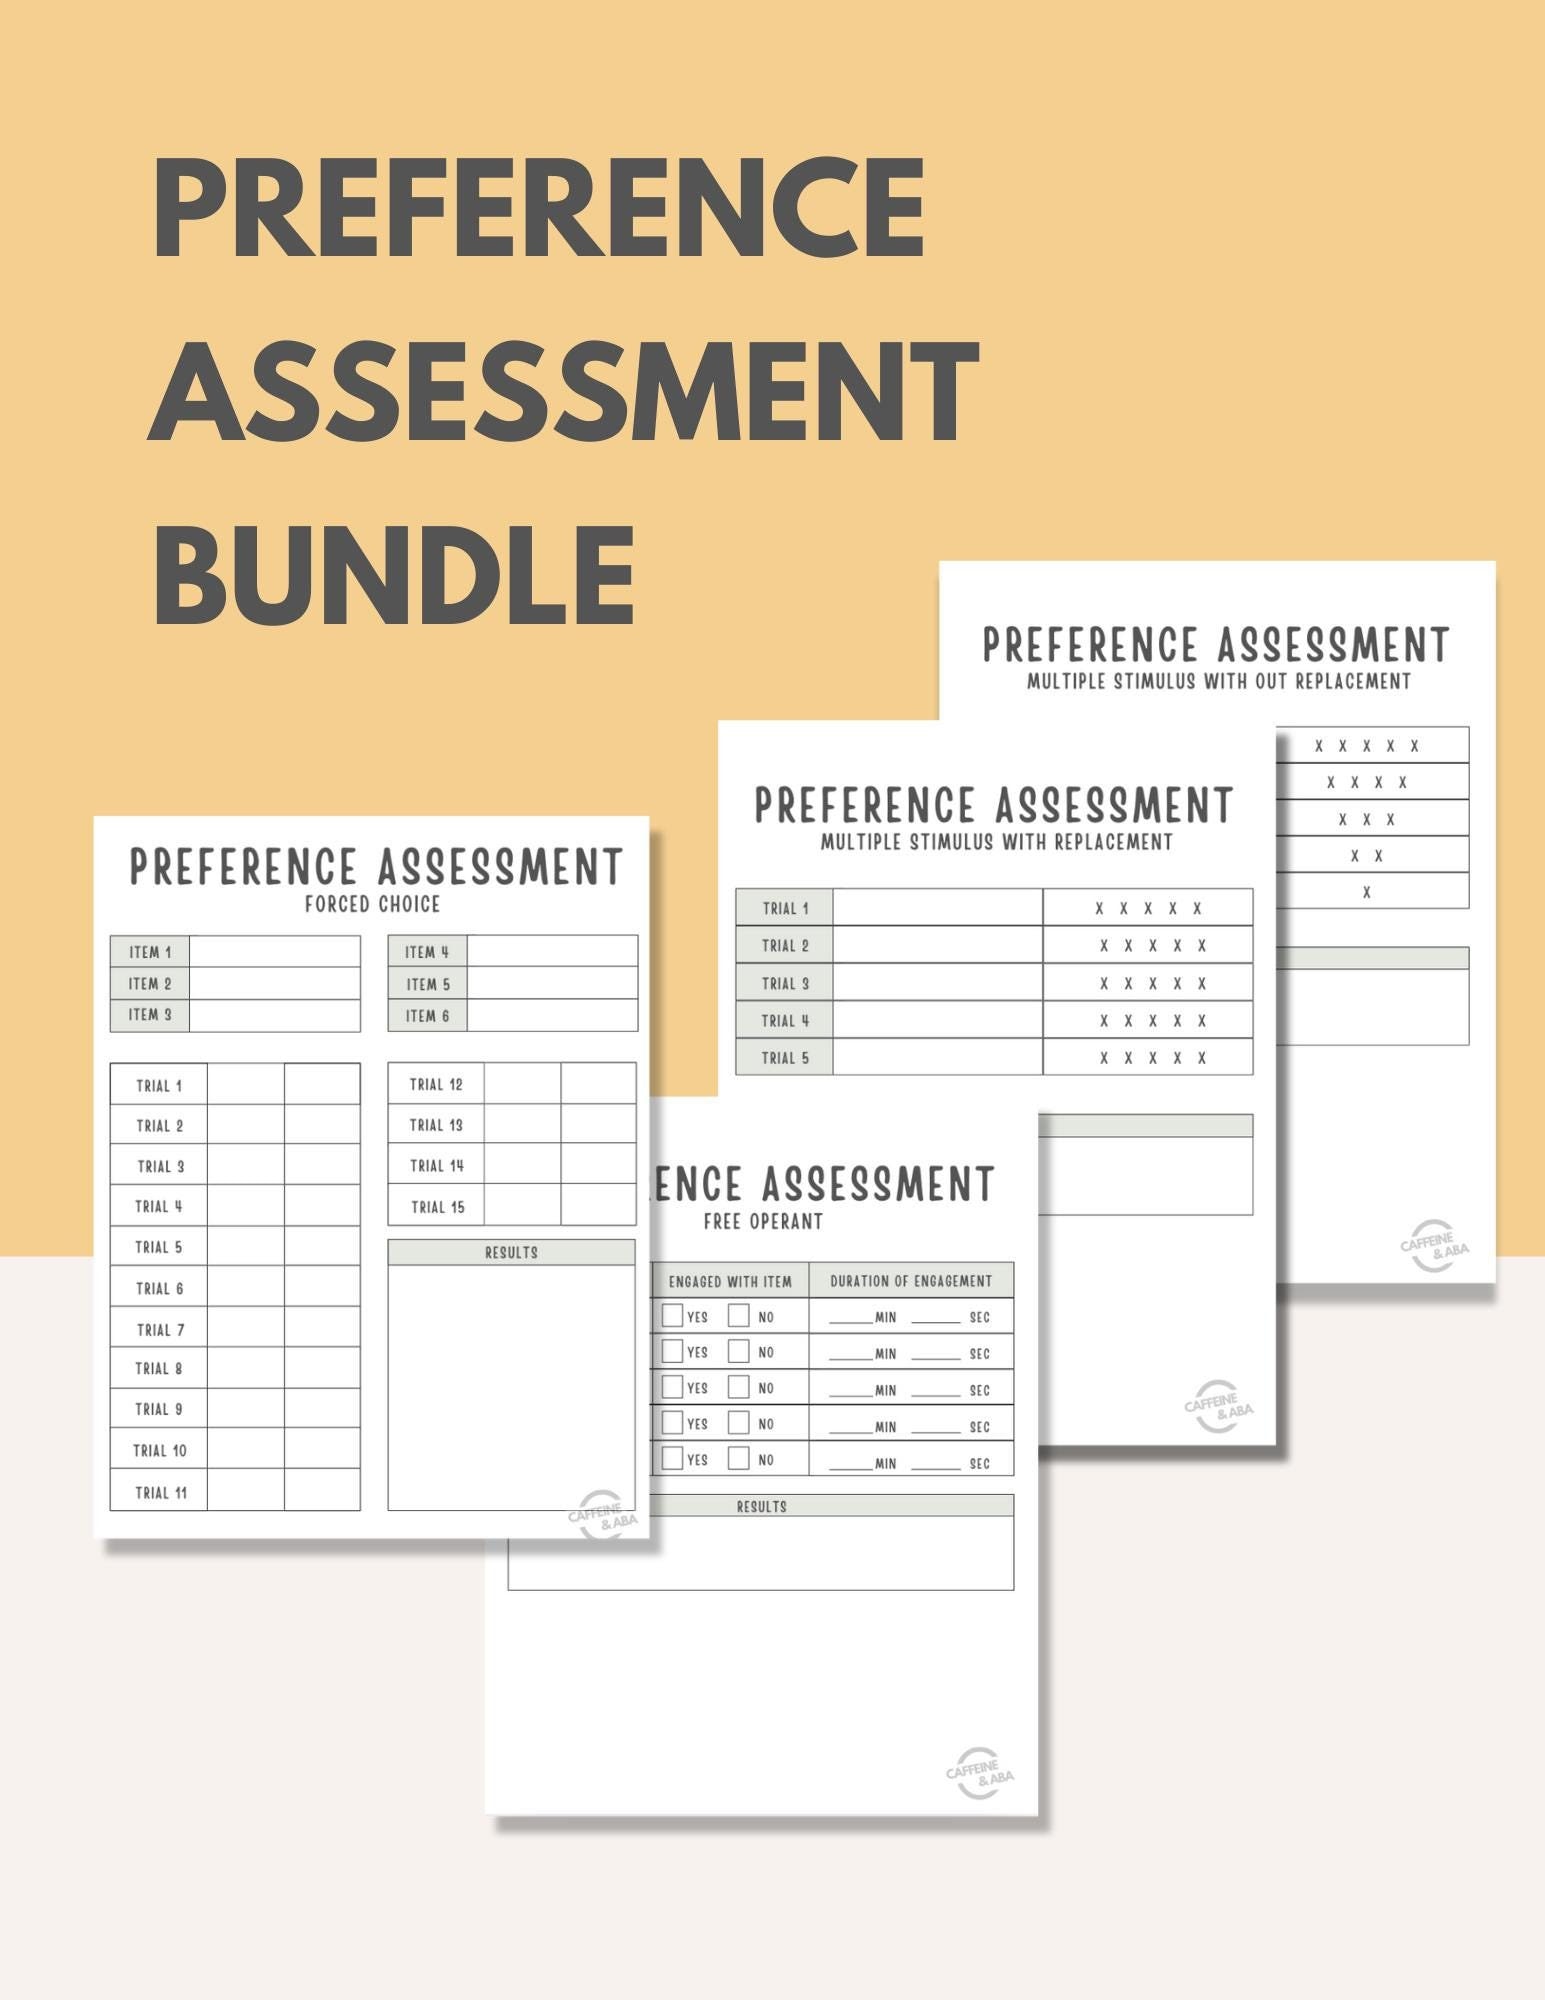
What Choice Preference Assessment Actually Looks Like in Practice
Most people treat Choice Preference Assessment like it's some mystical survey tool that spits out perfect answers. It doesn't. It's a structured way of forcing respondents to choose between real tradeoffs so you can map what they actually value versus what they say they value when nobody's watching. I've run these for product launches, feature prioritization, pricing studies, you name it. The method itself is straightforward, but the execution is where everything falls apart if you're not careful.
The Choice Preference Assessment Method
Here's how it works on the ground. You present respondents with a series of choice tasks, each showing multiple alternatives with varying attributes and prices. They pick one. Or they pick "none of these." You repeat this across many scenarios with different attribute combinations, then model the results to extract part-worth utilities for each attribute level. The whole point is that forced choice reveals more than ranking or rating ever will. When someone rates five features from one to five, they'll usually give them all fours or fives because that's how people fill out surveys. But when you show them two product bundles side by side and say "pick one," you get honest data about what they'd actually do at the shelf or on the website. I once worked on a consumer electronics project where we were trying to figure out whether customers would pay more for a longer battery life or a lighter device. The Choice Preference Assessment data showed battery life dominated at every price point. But here's the thing nobody tells you — if you don't include a "no purchase" option, your model will force someone to pick between two products they wouldn't buy anyway. That inflates perceived demand. Always include the no-choice alternative unless you're specifically studying brand switching behavior rather than market-level demand.
Setting this up correctly matters more than most people realize. Your attribute levels need to reflect real market conditions, not hypothetical extremes. I've seen studies where researchers used price ranges so far outside what customers would actually encounter that the part-worth utilities came out meaningless. If your product sells for $49 to $129, don't test at $10, $200, and $500 just to get "variation." The model will give you mathematically clean but practically useless results. Another thing that catches people off guard is the number of choice tasks required. For a standard main-effects design with six attributes at three levels each, you're looking at somewhere between 8 and 16 choice tasks per respondent. Fewer than that and the parameter estimates get wobbly. More than that and respondents start clicking randomly because they're bored. The sweet spot depends on how many attributes you're testing, but most projects I've seen land around twelve tasks per person. You'll also need to think about how you're generating the experimental design. Full factorial designs are impossible once you get beyond three or four attributes. You use a D-efficient or orthogonal design instead, typically generated through software like Conjoint Analytics, Sawtooth, or R packages like DiceOptim. The output is a design matrix you can plug straight into your survey platform.
Get the Full Details
Analysis is the part people struggle with most. The standard approach is a multinomial logit model, sometimes a mixed logit if you need to capture preference heterogeneity. Most commercial tools handle this automatically. The tricky part is interpreting the output correctly. Part-worth utilities tell you the relative importance of each attribute level, not absolute willingness to pay. To get WTP, you take the ratio of part-worth differences to the price coefficient. That sounds simple, but if your price coefficient is near zero because you didn't vary prices enough, your WTP estimates explode into nonsense. Common Choice Preference Assessment mistakes I see repeatedly:
- Attributes with overlapping or ambiguous level definitions
- Too few choice tasks for the number of attributes
- Forcing a choice when a no-option is the realistic answer
- Ignoring screen-out logic so respondents see combinations that make no sense together
- Analyzing with vanilla logit when the data clearly shows segment-specific preferences
There's also a specific edge case I ran into that took me three weeks to figure out. We were running a Choice Preference Assessment for a SaaS product where one attribute was "number of user seats." The initial design had levels at 1, 5, 10, and 25 seats. When I looked at the individual-level parameters, the utility for 5 seats was nearly identical to 10 seats, which didn't make sense given how the client priced those tiers. Turns out the respondents were treating the seat attribute as irrelevant because they assumed the price difference was fixed regardless of seats — they weren't actually processing the bundle structure we'd designed. The workaround was to reframe the choice task so the price explicitly adjusted per seat tier and add a practice round that walked them through how the pricing worked. After that, the data cleaned up significantly. If your project is small — say you're testing just two or three attributes with two levels each — you might not need a full conjoint setup. A simple paired-comparison survey or even a best-worst selection task can get you in the right direction with less respondent burden. Choice Preference Assessment is overkill when you're making minor feature tweaks. It's worth the investment when you're shaping a product strategy or pricing model where getting the tradeoff structure wrong costs real money. The other thing that trips people up is sample size. For aggregate-level analysis, 200 to 300 complete respondents is usually fine. But if you're doing segmentation — which is where this method actually becomes powerful — you need at least 80 to 120 per segment to get stable clustering. I've seen teams try to run a six-segment solution on 150 total respondents and then wonder why the segments kept shifting between runs.
If you need a starting point for building your own design, the free resources out there are decent. The Sawtooth Software website has a methodology section that covers design generation, sample size recommendations, and analysis basics. For open-source options, the Apollo choice modeling package in R is thorough if you're comfortable coding. There's also the ChoiceExperiment Python library if you want something lighter. Bottom line, Choice Preference Assessment gives you real tradeoff data instead of polite survey responses. It's not fast, it's not cheap, and it demands careful design work upfront. But when you need to know what customers will actually choose between competing options, it's still the best tool available. Just don't treat it like a checkbox exercise — the quality of your output is directly tied to how seriously you take the setup phase.