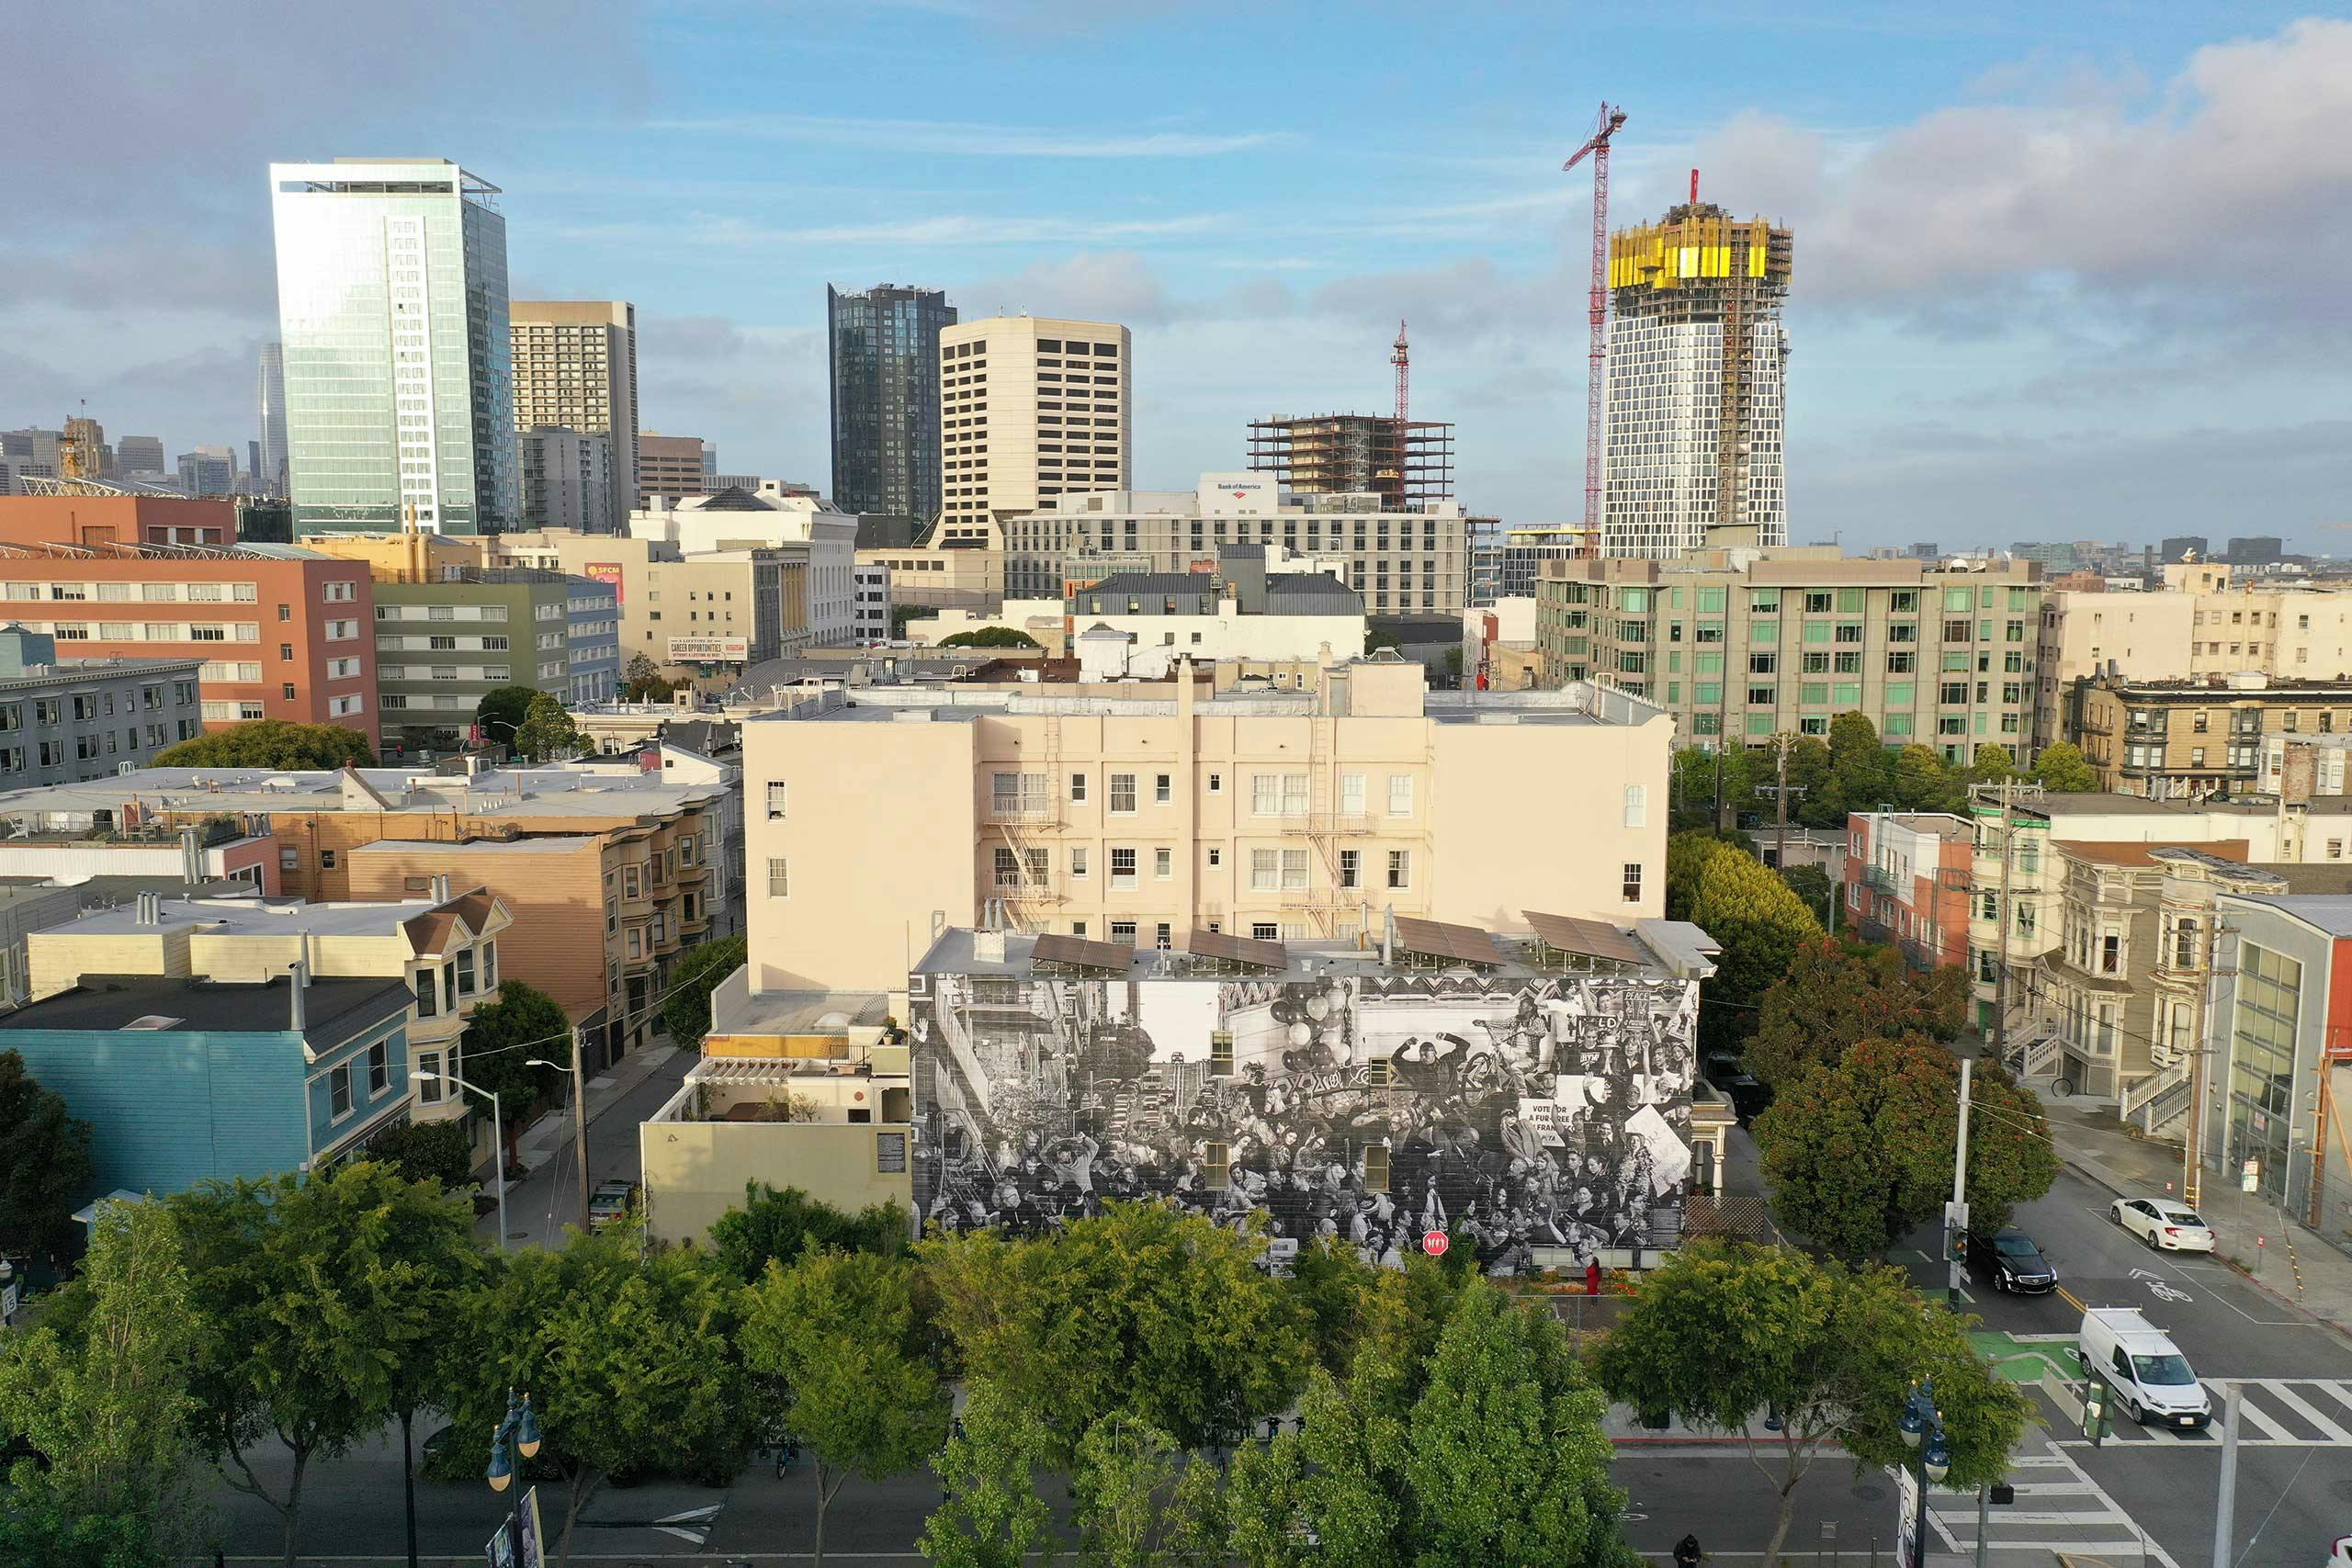
Getting Your Head Around Chronicles Of San Francisco
Chronicles Of San Francisco is a community-maintained archive that pulls together historical documents, oral histories, and digitized records from across the city. It started as a grassroots project when researchers realized the municipal archives were fragmented across seventeen different departments with zero interoperability. Most people stumble onto it when they are trying to track a building's ownership history, verify a neighborhood's original street layout, or dig into civil rights era correspondence that never made it into official databases. The interface itself is unglamorous. The search treats every entry like a flat text record, which sounds limiting until you realize you can chain boolean operators and date ranges together. I spend most of my time there running queries like "1890 AND Ocean View AND survey" because the early land plats get misfiled under neighborhood names that were changed decades later. The OCR quality on pre-1920 documents is hit or miss, and the system does not run deduplication, so you will see the same document appear three times under slightly different catalog numbers. What most people do not expect is how valuable the raw scan metadata is. Each entry carries a digitization date, scanner model, and sometimes the name of the archivist who handled the original box. When I was cross-referencing 1906 earthquake relief distributions, I found that entries scanned by the same person clustered together in result rankings, which let me reverse-engineer which boxes had priority handling and which sat in a basement drawer for twenty years. That pattern is not documented anywhere in the help files.
Download and access options
You can pull bulk data through the API endpoint if you register for a research key. The rate limit sits at two requests per second for unauthenticated users and roughly thirty for approved academic keys. The download format defaults to JSON with embedded base64 thumbnail strings, which slows everything down if you are pulling more than a thousand records at once. Strip the thumbnail field out and you get clean structured text in about a third of the time. For anyone working locally rather than through the API, there is a CSV export that covers title, date range, creator, and abstract fields. It does not include full transcripts. If you need the complete text you have to open individual records or use the API. I keep a local SQLite mirror of whatever I am actively researching and sync it weekly through a simple Python script. It takes roughly eight minutes to pull a fresh snapshot of a typical five-thousand-record topic cluster on a decent connection.
Working around the common pitfalls
The biggest headache is the inconsistent place-name normalization. "Mission" and "Mission District" are treated as separate entities. "SOMA" shows up as both "Southeast Market" and "South of Market" depending on the decade of the source document. I wrote a lookup table that maps every known variant to a canonical label before running any analysis, and it saved me from spending an entire weekend reconciling what turned out to be the same record appearing twice under different denominations. The mapping file itself is not provided by the project, so you have to build yours. Start with the city's own historical boundary maps from 1947 and work backward from there. Another issue that catches people off guard is the date parsing. The system accepts multiple formats, but it normalizes everything to ISO 8601 internally. If you enter a date like "Spring 1898" it stores it as an approximate range rather than throwing an error. That sounds convenient until you try to sort chronologically and half your results float to the middle of the decade instead of anchoring to a specific year. I learned that after wasting two hours debugging why my timeline visualization kept breaking. The workaround is to filter for records with explicit year stamps first, then handle the fuzzy dates separately in post-processing.
Get the Full Details

When Chronicles Of San Francisco falls short
It is not comprehensive. The Fire Department's inspection logs from the 1970s are almost entirely missing. The health department's cholera records from the 1870s were digitized years ago but never fully integrated into the public search. If you are looking for labor union correspondence, the International Longshoremen's files are partially housed here but the bulk remains at the labor archive across town. Be aware that community submissions can contain transcription errors, and there is no formal review process for them. I have seen three separate cases where a crowd-sourced entry flipped a first name and nobody noticed for over a year. For deeper municipal records, the San Francisco City Clerk's office still maintains a separate system that overlaps with about forty percent of what Chronicles Of San Francisco covers. If you need official land deeds or permit histories, you are better off going straight to the Clerk's database and using Chronicles Of San Francisco as a supplement rather than a primary source. The overlap is useful for contextual documents but not reliable for legal verification. If you are just starting out, spend the first hour browsing the advanced search filters and noting which fields actually return results. Many of the dropdown menus pull from deprecated taxonomies that no longer match current records. The basic keyword box and the date range slider are the only parts of the interface that stay reliably accurate. Everything else is a nice-to-have that requires manual validation before you trust it in a paper or report.
, 2019 | JR ...")