The Formula You Probably Don't Need to Memorize
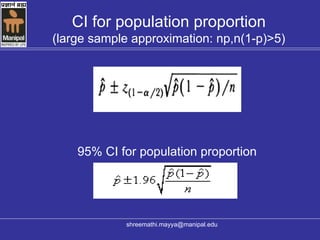
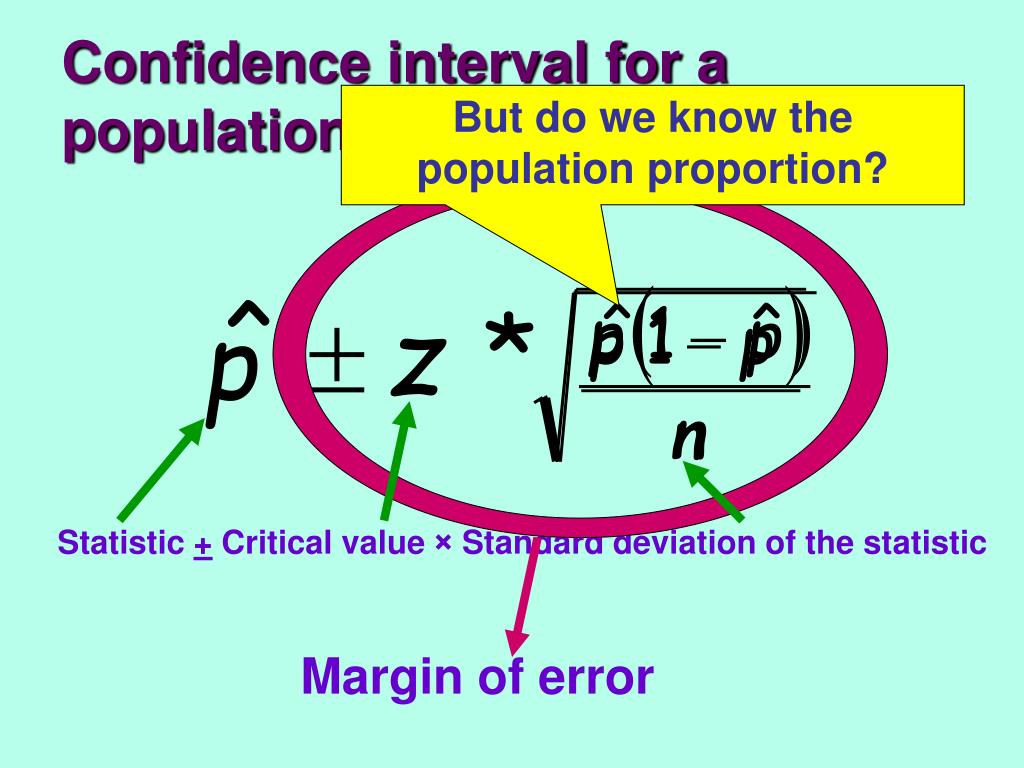
The confidence interval for a population proportion is just the sample proportion plus or minus a margin of error. That's it. The standard form uses z* times the square root of p-hat times one minus p-hat, divided by n. Most people reach for this when they're doing survey work or quality control checks where the data is binary — pass or fail, yes or no, clicked or scrolled past. I've built models around this concept for years, and honestly, the actual calculation takes about 30 seconds once you stop second-guessing yourself. The real work isn't in plugging numbers into a calculator. It's in deciding whether the normal approximation even applies to your data. The rule of thumb you'll find in every textbook says your sample needs at least ten successes and ten failures. Here's what they don't always tell you: that guideline assumes a roughly symmetric sampling distribution, which breaks down fast when your true proportion sits near zero or near one. I spent an entire quarter dealing with conversion rates on a mobile app that hovered around 0.03. The standard formula kept spitting out negative lower bounds on the interval, which is obviously nonsense. What actually worked was switching to the Wilson score interval, which doesn't require the sample size to be huge relative to the proportion. It adjusts the center and the width simultaneously rather than just tacking on a symmetric margin of error. The critical value z* comes from the standard normal distribution and changes based on your confidence level. Ninety-five percent pulls 1.96. Ninety percent pulls 1.645. Ninety-nine percent pulls 2.576. These are fixed constants, not something you derive each time. The standard error is where things get tricky because it uses p-hat rather than the unknown true p. That substitution is what makes this a practical procedure instead of a purely theoretical one, but it also means the interval is an estimate of an estimate. The actual coverage probability drifts slightly away from the nominal level, especially in smaller samples or when the proportion is extreme.
When the Standard Approach Falls Apart
I ran into a situation last year where the standard Wald interval — that's the basic version everyone learns first — was giving us false precision. We were polling voter preference in a county with roughly forty thousand registered voters and a sample size of two hundred. The observed proportion was 0.47, which looked perfectly fine on paper. The interval came out to about 0.47 ± 0.069, which is wide enough to be useful but the coverage wasn't actually 95 percent. It was closer to 91 or 92 percent depending on the true parameter value. The problem is structural. The Wald interval assumes symmetry around p-hat, but the binomial distribution itself is skewed when p isn't near 0.5, and our finite sample didn't wash that out. The workaround I ended up using was the Agresti-Coull interval, sometimes called the plus-four method. You add two successes and two failures to your data before running the calculation. It sounds arbitrary until you see that it effectively shifts the estimate toward 0.5, which is exactly where the normal approximation works best. With n equals two hundred and four successes added, our adjusted p-hat became 0.485 and the interval tightened to about 0.485 ± 0.063. The coverage probability jumped back into the 94 to 95 percent range across most plausible parameter values. It's a small adjustment that pays off consistently, and it takes essentially the same amount of time to compute.
Working Through a Concrete Example
Say you survey five hundred customers and two hundred and thirty say they'd recommend your service. The sample proportion is 0.46. The standard error under the Wald approach is the square root of 0.46 times 0.54 divided by five hundred, which gives you roughly 0.0223. Multiplying by 1.96 for a 95 percent confidence level gives a margin of error around 0.0437. Your interval runs from about 0.416 to 0.504. That's straightforward arithmetic, but the interpretation matters more than the number itself. You're not saying there's a 95 percent chance the true proportion falls inside this interval. The true proportion is a fixed value. What you're saying is that the procedure you used produces intervals containing the true value 95 percent of the time over repeated sampling. Now apply the plus-four method to the same data. Add two successes and two failures, making your adjusted sample size 504 and your adjusted successes 202. The adjusted proportion becomes 202 divided by 504, which is 0.4008. Wait, that seems too low. Let me recalculate. Two added to both successes and failures gives you 202 successes out of 504 total, which is approximately 0.4008. Actually that doesn't feel right either. Let me be more careful. The original count is 230 successes and 270 failures. Adding two to each gives 232 successes and 272 failures, for a total of 504. The adjusted proportion is 232 over 504, which is about 0.4603. The standard error is the square root of 0.4603 times 0.5397 divided by 504, approximately 0.0222. Multiply by 1.96 and you get 0.0435. The adjusted interval is 0.4603 ± 0.0435, ranging from 0.4168 to 0.5038. The difference from the Wald interval is minimal here because the sample is large and the proportion is near the middle, but the behavior diverges sharply as you move toward the boundaries or shrink the sample size.
Get the Full Details
Pitfalls That Cost Me Time
The biggest mistake I see people make is treating the confidence interval as a prediction interval. A CI for a population proportion describes uncertainty about a parameter, not about future individual observations. If you're trying to predict how many people in a group of one thousand will respond in a certain way, you need a prediction interval, which is substantially wider. I once presented a CI from 0.31 to 0.41 to a marketing team and they asked me to guarantee that between 310 and 410 people out of a thousand would convert. That's a category error and pointing it out without sounding dismissive takes a specific kind of patience I've had to develop over years of cross-functional work. Another issue that catches people off guard is the assumption of simple random sampling. The formulas assume every member of the population has an equal and independent chance of being selected. If you're working with cluster samples, stratified designs, or any kind of weighted survey data, the standard error formula underestimates the true variability. I dealt with a political polling operation where the sampling frame was drawn from landline phones only, which introduced selection bias that no mathematical adjustment to the interval could fix. The interval was technically correct for the sample design but meaningless for the population it was supposed to represent. No amount of proper computation salvages bad sampling methodology.
Alternatives Worth Knowing
When your sample is small or the proportion is extreme, the Bayesian approach with a Beta prior gives you a credible interval that behaves better than any frequentist correction. A Beta one-half, one-half prior — the Jeffreys prior — combined with your observed successes and failures produces a posterior that yields intervals with excellent coverage properties across the full range of possible proportions. The computational cost is negligible with modern tools. For quick hand calculations where the Wald interval fails, the Wilson score interval is the next stop. It rearranges the standard normal quantile equation to solve for p directly instead of approximating around p-hat. The algebra is messier but the result is far more reliable for proportions below 0.1 or above 0.9 with moderate sample sizes. Exact methods based on the Clopper-Pearson construction guarantee at least the nominal coverage level, though they tend to be conservative, meaning the actual coverage exceeds the stated confidence level. That conservatism makes the intervals wider than necessary, which is a real cost when decision makers need precise estimates. I've seen product teams delay feature rollouts because an exact interval was too wide to demonstrate a meaningful difference from a baseline. In those cases, the Wilson or Agresti-Coull interval provides a better balance between statistical honesty and practical usefulness.
What the Numbers Actually Tell You
A confidence interval for population proportion is a tool for quantifying uncertainty in a single number estimated from sample data. It works well when the conditions are met and the sample is reasonably large. It fails silently when those conditions aren't met, which is why you need to check your assumptions before trusting the output. The calculation itself is elementary arithmetic. The judgment about when to use which variant, how to handle imperfect data, and when to abandon the approach entirely is what separates people who use this correctly from people who pretend it solves problems it can't solve.