Understanding Client And Networking Components In Practice
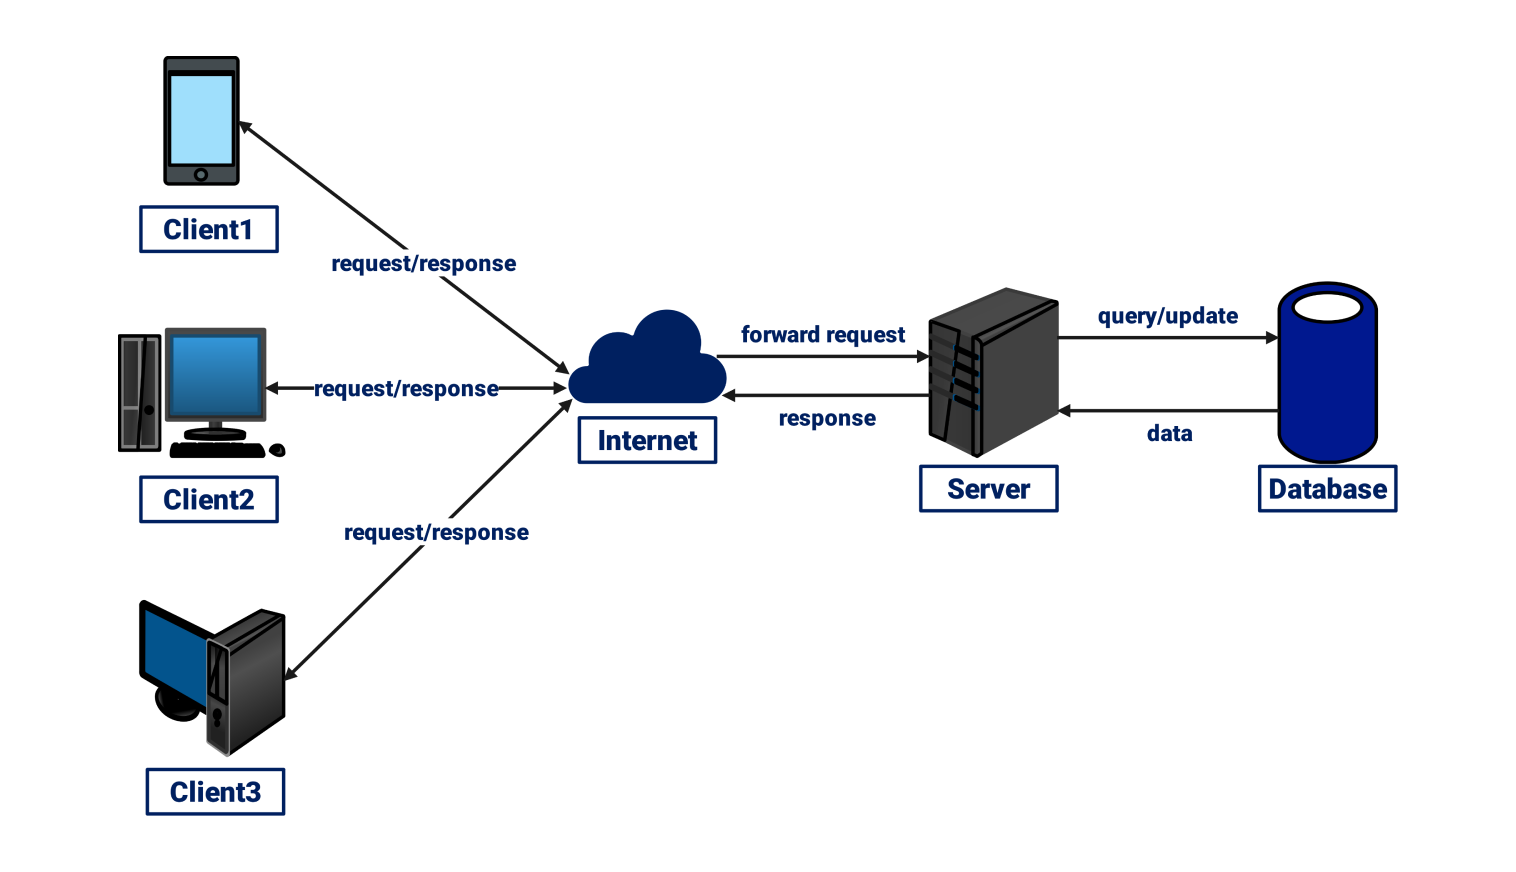
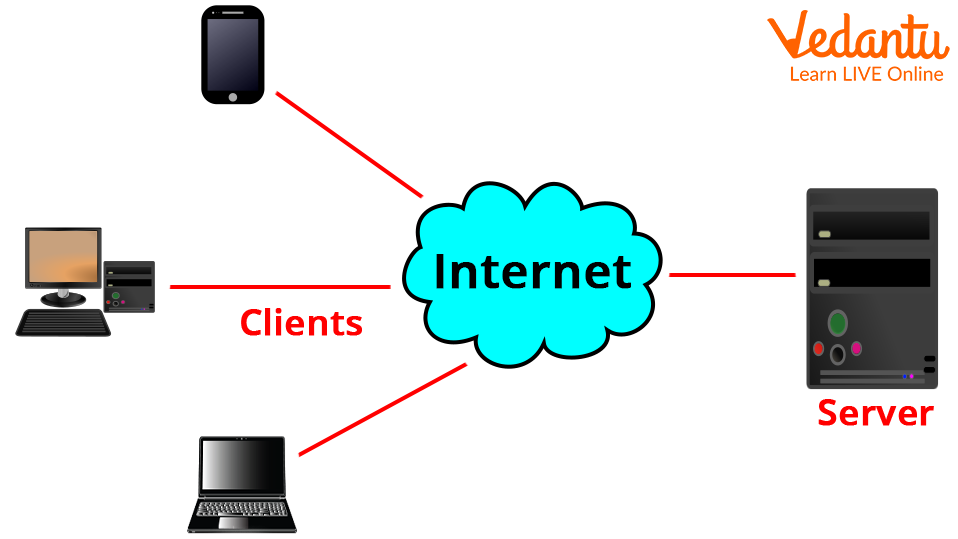
Client and networking components form the foundation of almost every distributed system you will ever build or maintain. The client handles requests from users or other systems, while the networking layer manages communication over networks. That sounds straightforward until something breaks in production at 2 AM. I have spent years debugging issues that trace back to a misunderstanding of how these components interact under stress. Most beginners treat the client side as an afterthought. They get the API endpoints working, run a quick test, and move on. That approach works fine until your latency numbers spike or your connection pool dries up during a traffic burst.
The Role Of Client And Networking Components In Modern Systems
At their core, client components are responsible for three things: constructing requests, handling responses, and managing state between calls. Networking components deal with transport protocols, connection pooling, timeout management, and retry logic. When these two layers work together cleanly, your application performs well. When they do not, you end up with timeouts that look like application bugs but are actually networking issues. One thing most tutorials skip is the concept of connection multiplexing. Instead of opening a new TCP connection for every request, modern clients reuse connections through HTTP/2 or HTTP/3. This dramatically reduces handshake overhead. I worked on a system where switching from HTTP/1.1 to HTTP/2 cut our average request latency from 120ms down to about 45ms without changing any business logic. The server configuration had to support it, and we needed to adjust our pooling settings, but the gain was immediate and measurable.
Building A Reliable Client Layer
Start by choosing your client library carefully. In enterprise environments, you will typically see OkHttp for Java, axios or node-fetch for JavaScript, or the built-in HttpClient in .NET. Each has different defaults around connection pooling, timeout behavior, and retry logic. Reading the documentation for an hour upfront will save you days of debugging later. The most common mistake I see is ignoring the default timeout values. Many libraries default to infinite timeouts or values that are far too generous. A request that hangs for five minutes before failing will tie up your thread pool and make your system look unresponsive long before the error surfaces. Set explicit timeouts early. I recommend a connect timeout of 5 seconds, a read timeout of 10 seconds, and a write timeout of 5 seconds for most internal service-to-service communication. Adjust based on your SLA requirements. Another area people get wrong is error classification. Not every failed request should be retried. Network timeouts are retryable. Authentication errors are not. Rate limiting responses need exponential backoff. I built a classification system once that categorized errors into transient, recoverable, and terminal. Transient errors triggered retries with backoff. Recoverable errors triggered a single retry with a longer delay. Terminal errors were logged and returned immediately. This reduced our overall failure rate by roughly 60 percent compared to a simple retry-on-failure approach.
Get the Full Details
Networking Layer Considerations
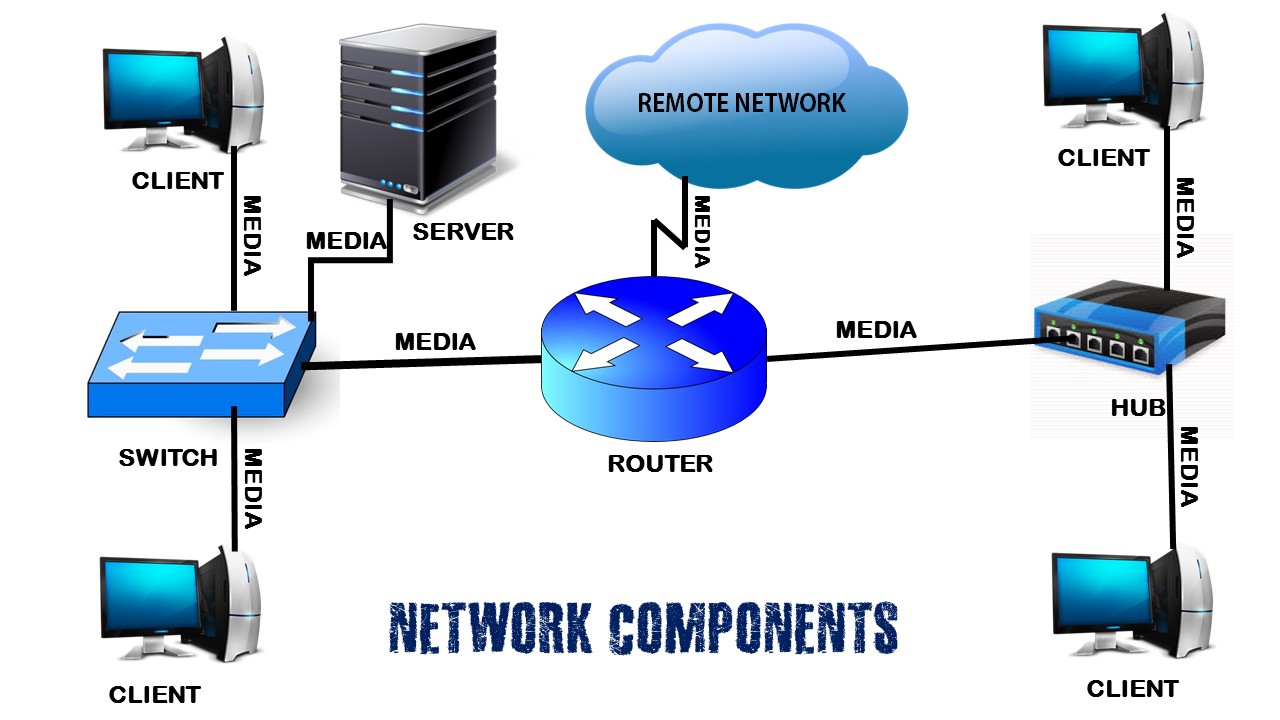
The networking component sits between your client code and the actual network. It handles DNS resolution, TCP connection management, TLS handshakes, and data serialization. When you configure this layer, you need to think about connection pools, keep-alive settings, and DNS caching. Connection pooling deserves its own attention. A pool that is too small creates bottlenecks. A pool that is too large wastes resources and can overwhelm the remote service. The optimal size depends on your concurrency model, your expected traffic patterns, and the capabilities of the server you are connecting to. As a starting point, I use a pool size of 10 to 20 connections per host for most internal APIs. For high-throughput services, 50 to 100 may be appropriate. Monitor your connection metrics and adjust. TLS adds complexity that is easy to underestimate. Certificate validation, SNI, cipher suite selection, and session resumption all affect performance and security. I encountered a specific issue once where a TLS 1.3 handshake was causing intermittent failures because an intermediate load balancer did not properly handle the TLS extensions. The error messages were misleading and pointed to application-level problems. The workaround was to configure the client to support TLS 1.2 fallback with a clear precedence rule. We added a diagnostic check that logged the TLS version used for each connection, which made future debugging much faster.
Client And Networking Components Debugging Strategies
When something goes wrong, your first step should always be to isolate the layer. Is the issue in the client code, the network, or the server? Use packet captures like tcpdump or Wireshark when you need visibility. For application-level debugging, enable detailed logging with correlation IDs that span across client and server boundaries. A single request ID that flows from your client through proxies and load balancers to the target service is worth more than a thousand log statements. Monitoring is non-negotiable. Track connection pool utilization, request latency percentiles, error rates by category, and TLS handshake times. Without these metrics, you are flying blind. I use a combination of Prometheus for metrics collection and Grafana for visualization. The dashboards are not complicated, but they make patterns visible that would otherwise take hours to identify manually. One counter-intuitive point that catches people off guard: sometimes the best fix for a networking issue is to add controlled delays. This sounds backwards, but in systems where multiple clients are hammering a service simultaneously, a small artificial delay can actually improve overall throughput. It gives the server time to process requests instead of having all of them arrive at once and get queued. This is essentially a brute-force approach to avoiding thundering herd problems. It is not elegant, but it is effective when you cannot change the server architecture.
Common Pitfalls To Avoid
Hardcoding hostnames instead of using DNS names is a recurring mistake. DNS allows you to change infrastructure without redeploying client code. If you hardcode IPs and an IP changes, your client stops working until you update it. Use hostnames and configure appropriate TTL expectations in your DNS settings. Another pitfall is assuming that a successful response from one endpoint means all endpoints are reachable. Network conditions vary. A service might be perfectly responsive on one network path but unreachable on another due to routing issues or firewall rules. Test connectivity to multiple endpoints across different network paths when possible. Resource leaks in client code are also common and particularly damaging because they accumulate slowly. Every open connection, every unread response stream, and every uncancelled request timer consumes memory and file descriptors. I have seen production systems crash because someone forgot to close a response body in a loop. Always use try-with-resources in Java, context managers in Python, or similar patterns in your language of choice. Make it a habit so you do not have to think about it.
Tooling And Libraries
For Java, OkHttp and Apache HttpClient are the standard choices. OkHttp has better defaults out of the box and requires less configuration. For Go, the standard library net/http package is generally sufficient if you configure the Transport object properly. Python developers should prefer httpx over requests for async support, though requests remains fine for simple synchronous use cases. If you are building something that requires heavy connection management or custom protocol support, you may want to look at dedicated libraries like gRPC for RPC-style communication or WebSocket clients for bidirectional streaming. These come with their own trade-offs. gRPC requires protobuf definitions and a supporting server infrastructure. WebSockets require persistent connections and careful reconnection logic. There is no universal best library. The right choice depends on your language, your architecture, and your performance requirements. Benchmark your options with realistic workloads before committing to one.
When Client And Networking Components Fail Completely
Some architectures simply cannot be fixed at the client or networking layer. If your upstream service is consistently slow or unstable, no amount of retry logic or connection tuning will solve the root problem. In those cases, you need circuit breakers, bulkheads, and graceful degradation strategies at the application level. The Netflix Hystrix library and its successors like Resilience4j provide these patterns, though they require deliberate integration into your codebase. Circuit breakers have a failure threshold and a recovery timeout. When failures exceed the threshold, the circuit opens and requests fail fast instead of piling onto an already struggling service. After the recovery timeout, the circuit allows a limited number of probe requests through. If those succeed, the circuit closes and normal traffic resumes. This prevents cascading failures across your entire system. The main downside of circuit breakers is that they add complexity and can mask underlying issues if configured too aggressively. A circuit that opens too easily will degrade your service availability even when the upstream problem is temporary. Start with conservative thresholds and adjust based on observed behavior. Monitor your circuit breaker states closely during the first few weeks of deployment.
Practical Next Steps
Review your current client configuration for timeout values, connection pool sizes, and retry logic. Audit your error handling to see how many failures are being silently retried or completely ignored. Set up basic monitoring for the metrics I mentioned earlier. Even a simple log file with request timestamps and status codes is better than nothing. From there, iterate based on what you observe rather than what you expect.