Working With Averages When You Need Reliable Results
I spent three years in a logistics role where our whole scheduling system depended on accurate mean and median calculations. We had a dashboard that would pull daily shipping times, calculate the mean, and use it to set carrier expectations. I learned pretty fast that "just compute the average" is nowhere near as simple as it sounds on paper. A few bad data points — a driver who got stuck at a port for six hours, a warehouse shift change that added forty minutes to every delivery — would skew the mean so badly that the forecasted arrival windows became useless within a week. When people search for Understand Mean And Mad I Ready Answers, they're usually looking for either a specific quiz solution or guidance on how to actually work through problems involving mean, median, mode, and range. The "mad" part often refers to mean absolute deviation, which is a measure of how spread out a data set is around the mean. This is a standard topic in middle school and high school statistics, and it shows up in standardized tests, placement exams, and online homework platforms like IXL and Khan Academy. The actual concept isn't complicated, but the way questions are framed can be tricky. You'll see problems where you're given a mean and one missing value and asked to find it. Others will ask you to interpret what the mean absolute deviation tells you about consistency in a data set. I've seen students nail the calculation but completely miss the interpretation part, which is usually worth half the points on these kinds of assessments.
How to Calculate Mean, Median, Mode, and Range Step by Step
Start with the mean. Add all the numbers in your data set, then divide by how many numbers there are. That's it. No shortcuts that are actually correct. People try to shortcut this by averaging two middle numbers or ignoring outliers, and that's where mistakes creep in. For the median, you have to order the data first. If there's an odd number of values, the median is the middle one. If there's an even number, average the two middle values. I used to make students do this by hand for small data sets because they need to internalize the ordering step before they start relying on calculators. You'd be surprised how many people skip the sort and just grab the middle number from the unsorted list. The mode is the most frequent value. A data set can have no mode, one mode, or multiple modes. That last part trips people up constantly. If your data set is 3, 5, 7, 5, 8, 3, then both 3 and 5 are modes. It's bimodal, not wrong.
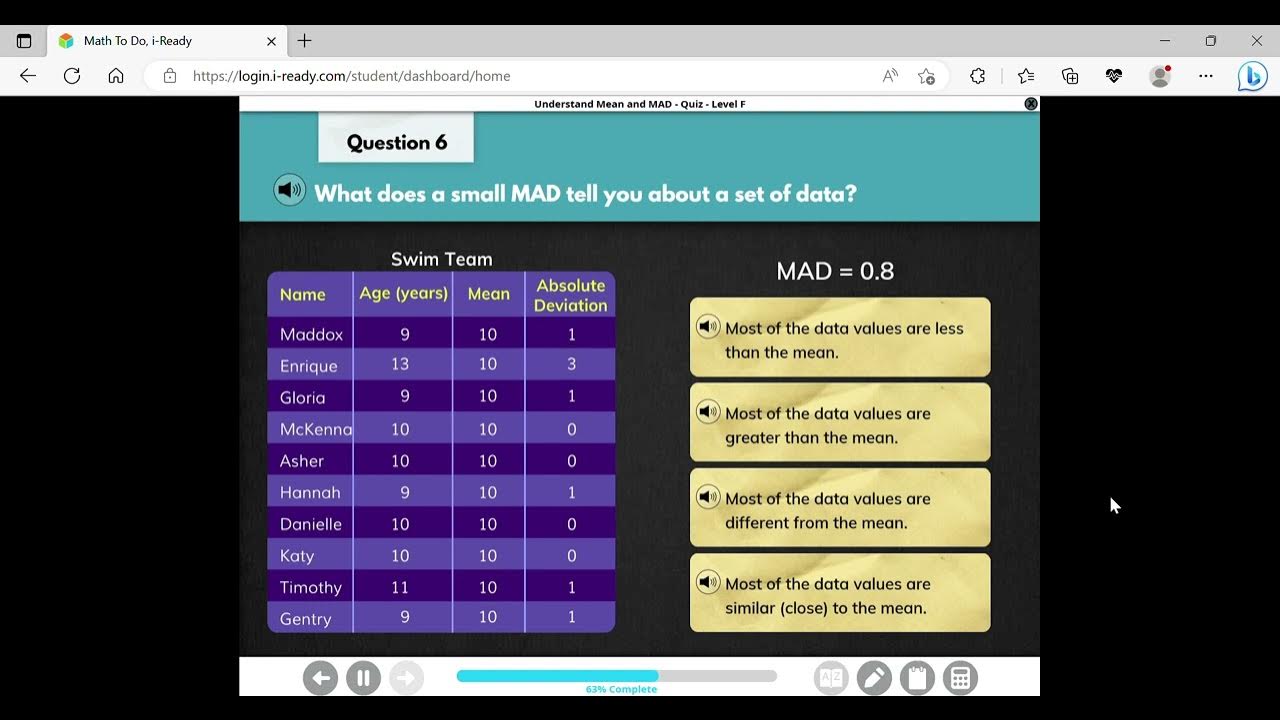
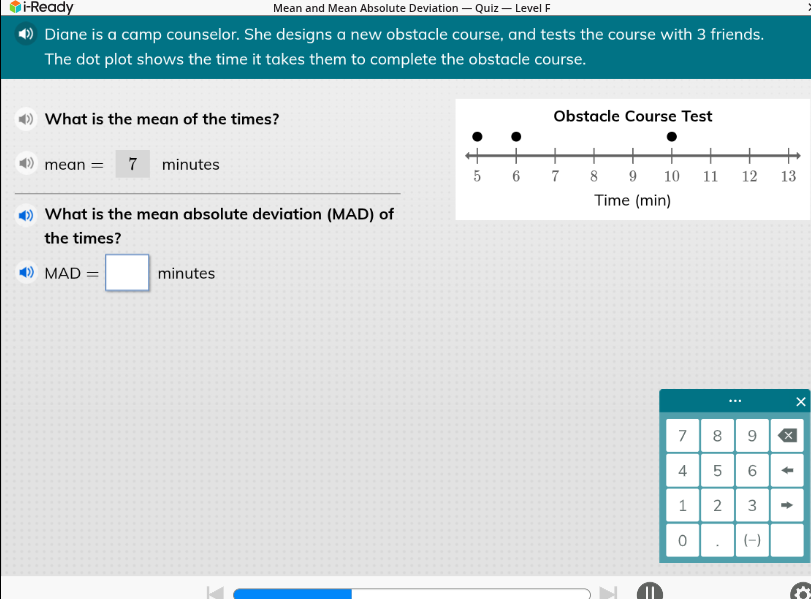
Range is the difference between the highest and lowest values. Simple subtraction. The mean absolute deviation requires more steps: find the mean first, then calculate the absolute difference between each data point and the mean, then average those differences. That final average is your MAD. It tells you, on average, how far each value sits from the mean. A low MAD means the data is clustered tightly. A high MAD means it's spread out.
Get the Full Details
A Problem I Actually Faced With Real Data
Once, I was working with a data set of 47 delivery times that had a mean of 3.2 hours and a MAD of 0.4 hours. Everything looked normal on the surface. Then I noticed three outliers — deliveries that took over 8 hours each. These were caused by a specific loading dock that had structural issues that week. When I included those outliers, the mean jumped to 4.1 hours and the MAD went to 1.6. The forecast model broke completely because it was built on the unadjusted mean. My workaround was to flag any data point more than two standard deviations from the mean as a potential outlier and run the calculations both ways — with and without the flagged values. I documented both results and let the operations team decide which version to trust for their planning. Including the outliers gave a realistic worst-case picture. Excluding them gave a cleaner operational baseline. Neither answer was wrong. They just served different purposes.
Common Pitfalls That Cost Me Points on Exams
The biggest mistake I see is confusing mean and median when the data set is skewed. If you have a group of salaries where most people earn between $40,000 and $55,000 but one person earns $500,000, the mean will be pulled way up and won't represent the typical person in that group. The median stays stable. Test questions love this scenario, and they want you to pick the right measure, not just compute it correctly. Another trap is rounding too early. If you calculate the mean as 12.3333 and immediately round it to 12.3 before using it to find the mean absolute deviation, your final answer will be slightly off. Keep extra decimal places through intermediate steps and round only at the end. I usually keep four decimal places minimum during multi-step problems. There's also the issue of weighted means that show up in unexpected places. A grade calculation might look like a simple average of test scores, but if the final exam is worth 25% and quizzes are worth 5% each, it's a weighted mean. The formula changes — you multiply each value by its weight, sum those products, and divide by the sum of the weights. This comes up in education contexts all the time, and it's easy to miss if the problem doesn't explicitly use the word "weighted."
When These Methods Don't Work
Mean and MAD assume your data is roughly symmetric and doesn't have extreme outliers. If your distribution is heavily skewed — income data, house prices, response times with occasional massive delays — the mean becomes a poor summary statistic. In those cases, the median is more representative, and interquartile range is a better measure of spread than MAD. No amount of careful calculation will fix a bad choice of statistics for the data at hand. Small sample sizes are another limitation. With fewer than five data points, the mean is unstable. One new value can swing it dramatically. I've seen people present mean-based forecasts from samples of three or four observations and call it data-driven. It isn't. It's a guess with extra steps.
Practical Tips for Tackling These Problems
Always write out the data set in order before calculating anything. This single step catches most errors early. Use a calculator or spreadsheet for the arithmetic, but show your work if the question asks for it. Partial credit matters more than people realize on timed tests. When interpreting MAD, think in terms of predictability. If the mean delivery time is 3 hours with a MAD of 0.3 hours, you can reasonably expect most deliveries to fall within about 2.4 to 3.6 hours. If the MAD is 1.5 hours, the same mean of 3 hours tells you almost nothing useful about when a delivery will actually arrive. The number itself is the insight. For online homework platforms, read the question twice before computing. Some ask for the mean rounded to the nearest tenth. Others want the exact value. A few want you to select the best measure of center for a given context. The math might be the same, but the answer format changes everything.
If you're preparing for a test and want to practice, work through problems with real data — your weekly screen time, commute durations, quiz scores. Abstract numbers make the mechanics clearer, but real numbers make the interpretation stick. That's what most exams actually test, and that's what you'll need in any job that involves making decisions based on data.