Building Code Without the Fluff
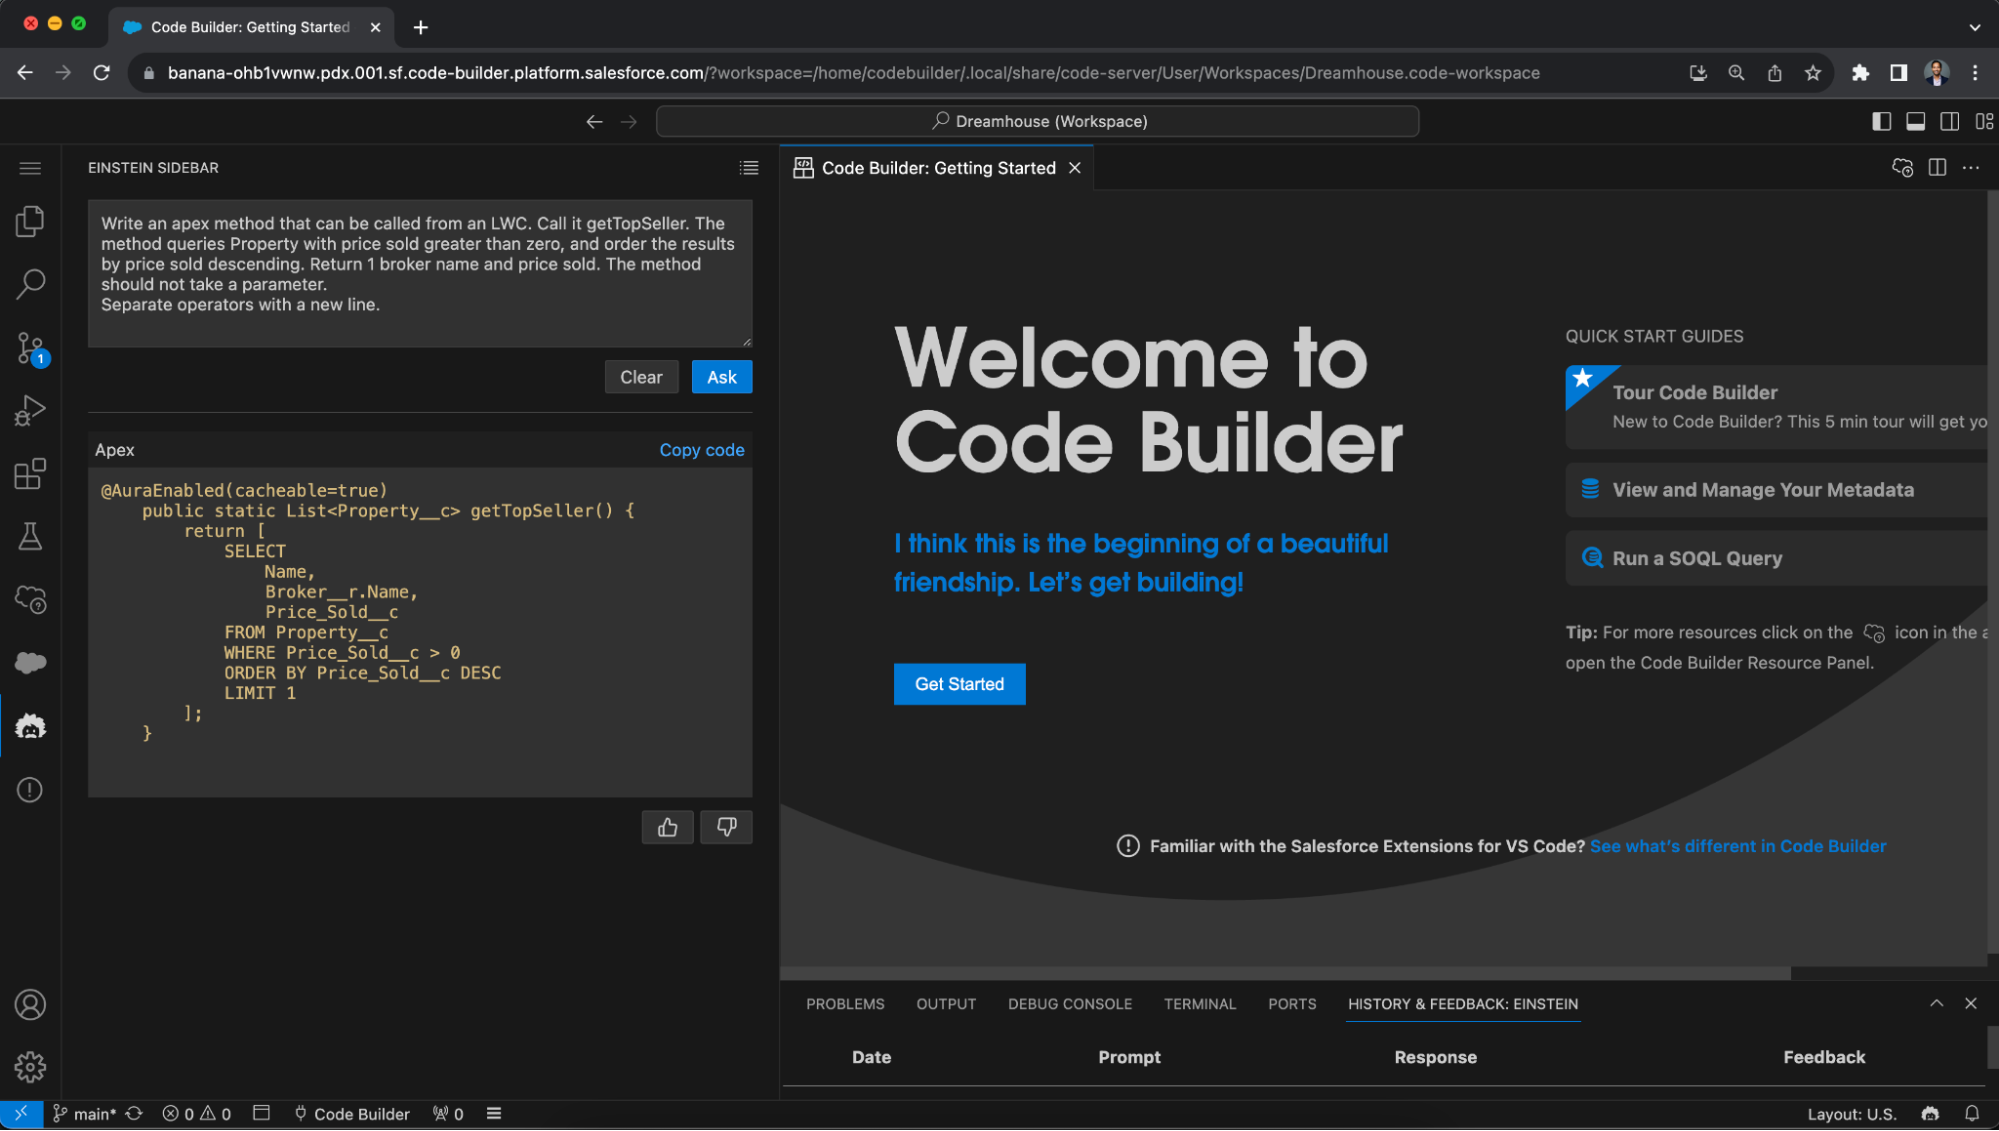
The most common mistake I see people make with Code Builder is treating it like a magic box that writes perfect programs on its own. It doesn't. It generates scaffolding. The actual logic, the edge cases, the stuff that makes it work in production — that's still on you. I've spent years watching developers waste hours trying to force Code Builder to produce polished, production-ready code. It just doesn't do that out of the box. You need to understand the underlying architecture before it becomes useful. At its core, a Code Builder is a tool or framework that automates the generation of boilerplate code structures. It parses your requirements, maps them against known patterns, and produces a starting point for your project. Think of it as a very efficient first draft writer. The difference between a good result and a garbage result usually comes down to how specifically you define your inputs. I ran into a real headache last year working on a Python data pipeline where the Code Builder was generating standard ORM models for a Postgres database. Everything looked correct syntactically. The generated code compiled, the migrations ran clean. But when we hit actual concurrent write loads above 500 requests per second, the generated model definitions had no connection pooling configuration at all. The boilerplate templates simply assumed single-threaded usage. My workaround was to write a custom post-generation patch script that injected async connection management directly into the model files after build. Takes about ten minutes once you have the pattern figured out. Saves you from digging through three hundred lines of generated code trying to find where to manually add it.
The thing beginners miss is that Code Builder outputs are templates, not finished products. They're meant to be modified. The generated code follows conventions and defaults that are generally safe but almost never optimal for your specific constraints. Understanding what those defaults are and why they exist is what separates people who use Code Builder effectively from people who just copy-paste and hope.
How It Works Under the Hood
Most Code Builder implementations follow a similar pipeline. You define a schema or configuration file that describes your project structure, dependencies, and target language. The builder reads that file, matches it against a library of known patterns and templates, fills in the blanks with your specific values, and outputs the resulting source files. Some modern versions integrate AI-based code suggestion layers on top of this template engine, which can produce more context-aware snippets but introduces a different set of reliability concerns. The template matching step is where a lot of subtle bugs hide. If your configuration doesn't explicitly override a default, the builder falls back to whatever the template author considered standard practice. Standard practice from five years ago in a popular framework might not be standard practice today. I learned this the hard way when a Code Builder setup I inherited was generating React component files using an older class-based pattern instead of functional components with hooks. The code worked. It just looked wrong and caused review friction every time someone new joined the team. Changing the template configuration to enforce current conventions fixed it across the entire project instantly. Here's another counter-intuitive point that most tutorials don't cover: more options in your Code Builder configuration usually produces worse output. When you leave defaults in place, the builder makes coherent decisions across all the pieces it generates. The template author has already thought through how the pieces fit together. The moment you start toggling every available option to customize things, you can create inconsistencies between generated parts. A handler that expects one data format paired with a model that generates a different format. It compiles fine. It fails at runtime in ways that are genuinely difficult to debug because the error message points to completely unrelated parts of your codebase.
Get the Full Details

Getting Started Practically
If you want to actually use a Code Builder for something useful, start with a small, well-documented project type. Don't try to generate an entire microservices architecture on your first attempt. Pick a single service, a single language, and a straightforward use case. Get the generated output running, then modify one thing at a time and observe what breaks. The installation process varies depending on which Code Builder you're using. Most are distributed as npm packages, pip modules, or standalone CLI tools. Check the official documentation for your specific version. The community around each tool determines how reliable the templates are. A builder with an active contributor base and recent commits will catch breaking changes faster than one that's been stagnant for two years.
When Code Builder Fails You
There are scenarios where Code Builder simply cannot help you and pushing forward with it wastes everyone's time. Custom domain-specific logic that doesn't fit existing patterns. Projects requiring unusual performance characteristics that demand non-standard architecture. Teams working in languages or frameworks with minimal template coverage. In these cases, manual scaffolding or a different toolchain is faster than fighting the builder to produce something it wasn't designed for. Another hard limit: dependency management. Code Builder tools typically pin versions of their generated dependencies to ensure template compatibility. This means you might end up months behind on security patches or new features in your stack. I've seen this cause real problems in production environments where a critical vulnerability was patched in a newer version of a dependency but the builder's pinned version hadn't been updated. Always audit the dependency tree the builder generates before deploying anything. The honest assessment is that Code Builder is a productivity multiplier for repetitive structural work, not a replacement for understanding your codebase. It cuts the initial scaffolding time from hours to minutes for standard patterns. It does not reduce the time you spend debugging logic errors, optimizing performance, or maintaining the code after generation. If your goal is to skip learning how the underlying technology works, you're setting yourself up for a slow and painful correction later.
For most teams, the realistic workflow looks like this: use Code Builder to generate the initial project structure, review every generated file for template defaults that don't match your requirements, run the tests immediately to verify the output actually functions, and only then proceed with writing your actual application logic. Skipping any of those steps is where the time savings disappear.