What You're Actually Looking For With the Codex Gigas
The Codex Gigas is a massive 13th-century manuscript, often called the Devil's Bible, containing the entire Vulgate, works of Josephus, Isidore of Seville, and a collection of medical texts. It's currently held at the National Library of Sweden in Stockholm. Most people searching for a "Codex Gigas Pdf Translated In English" are looking for either a full English translation of the text or a digitized version with translation annotations. Neither exists as a single, clean product, and here's why that matters when you're actually trying to use one. There is no single authoritative complete English translation of the Codex Gigas that has been published in PDF format. The standard academic translations are scattered across various publications. The most accessible English translation effort comes from Dr. Robert Clavaud and others who have worked on portions of the text. What you will find online as a "translated PDF" usually falls into two categories: a digitized image set with a separate translation document, or an OCR-generated PDF that attempts to read the medieval Latin and overlay English text underneath. I've downloaded and worked with several of these. The ones that try to OCR the medieval script are almost always garbage. The Latin abbreviations, the scribal marks, the damage from centuries of storage — standard OCR engines treat all of that as noise and produce text that looks like someone fed a keyboard. The workaround I ended up using was to download the high-resolution image sets from the Swedish National Library's website and then cross-reference with the printed translations by Kauffman and Mengel, which are out of print but available through academic libraries.
Where to Actually Get the Files
The Swedish National Library offers the full Codex Gigas as a free digitized resource. You can find it at kunglib.se/codex-gigas. The images are in tiff format at around 400 DPI, which means individual files range from 80 to 200 megabytes each. You can request them as a combined PDF through their order system, but this takes a few weeks and they charge a processing fee. Some university libraries have already compiled these into a single PDF and uploaded them to their repositories. I found one through a Czech university's digital library that had the full image set assembled — approximately 620 pages, totaling about 4.2 gigabytes. For the English translation component, you'll need to layer it on separately. The most complete public domain translation effort is the one by Michael Everson, who has worked extensively on making medieval Latin accessible. His translations are not bound into the same PDF as the images, but you can download his work independently and reference it alongside the manuscript images. There's also the earlier translation by William Reed and others that appears in various academic preprints.
The Practical Problem With Large Manuscript PDFs
Here's something nobody tells you about working with the Codex Gigas PDF: it is enormous and most consumer hardware chokes on it. A complete 620-page high-resolution PDF of the manuscript will be anywhere from 3 to 6 gigabytes. Opening that in a standard PDF reader like Adobe Acrobat or Preview on a machine with less than 16 gigabytes of RAM will cause freezing, crashing, or extremely slow page navigation. The thumbnail generation alone can take 20 to 30 minutes on a modern laptop. The workaround is straightforward but not obvious if you've never dealt with manuscript files this large. Split the PDF into two-volume chunks of roughly 300 pages each. You can do this with a tool like pdfseparate from the Poppler utilities, which is command-line based. The command is something like pdfseparate -f 1 -l 310 codex_gigas_full.pdf codex_gigas_part_%d.pdf. This creates two separate files, each around 1.5 to 2 gigabytes, which any reasonable machine can handle without issue. The page numbers carry over correctly between the two parts, so you can reference them consistently. I spent about three hours troubleshooting a crash loop before I figured this out and now I split all large manuscript PDFs on first open without hesitation.
Get the Full Details

Reading the Translation With the Images
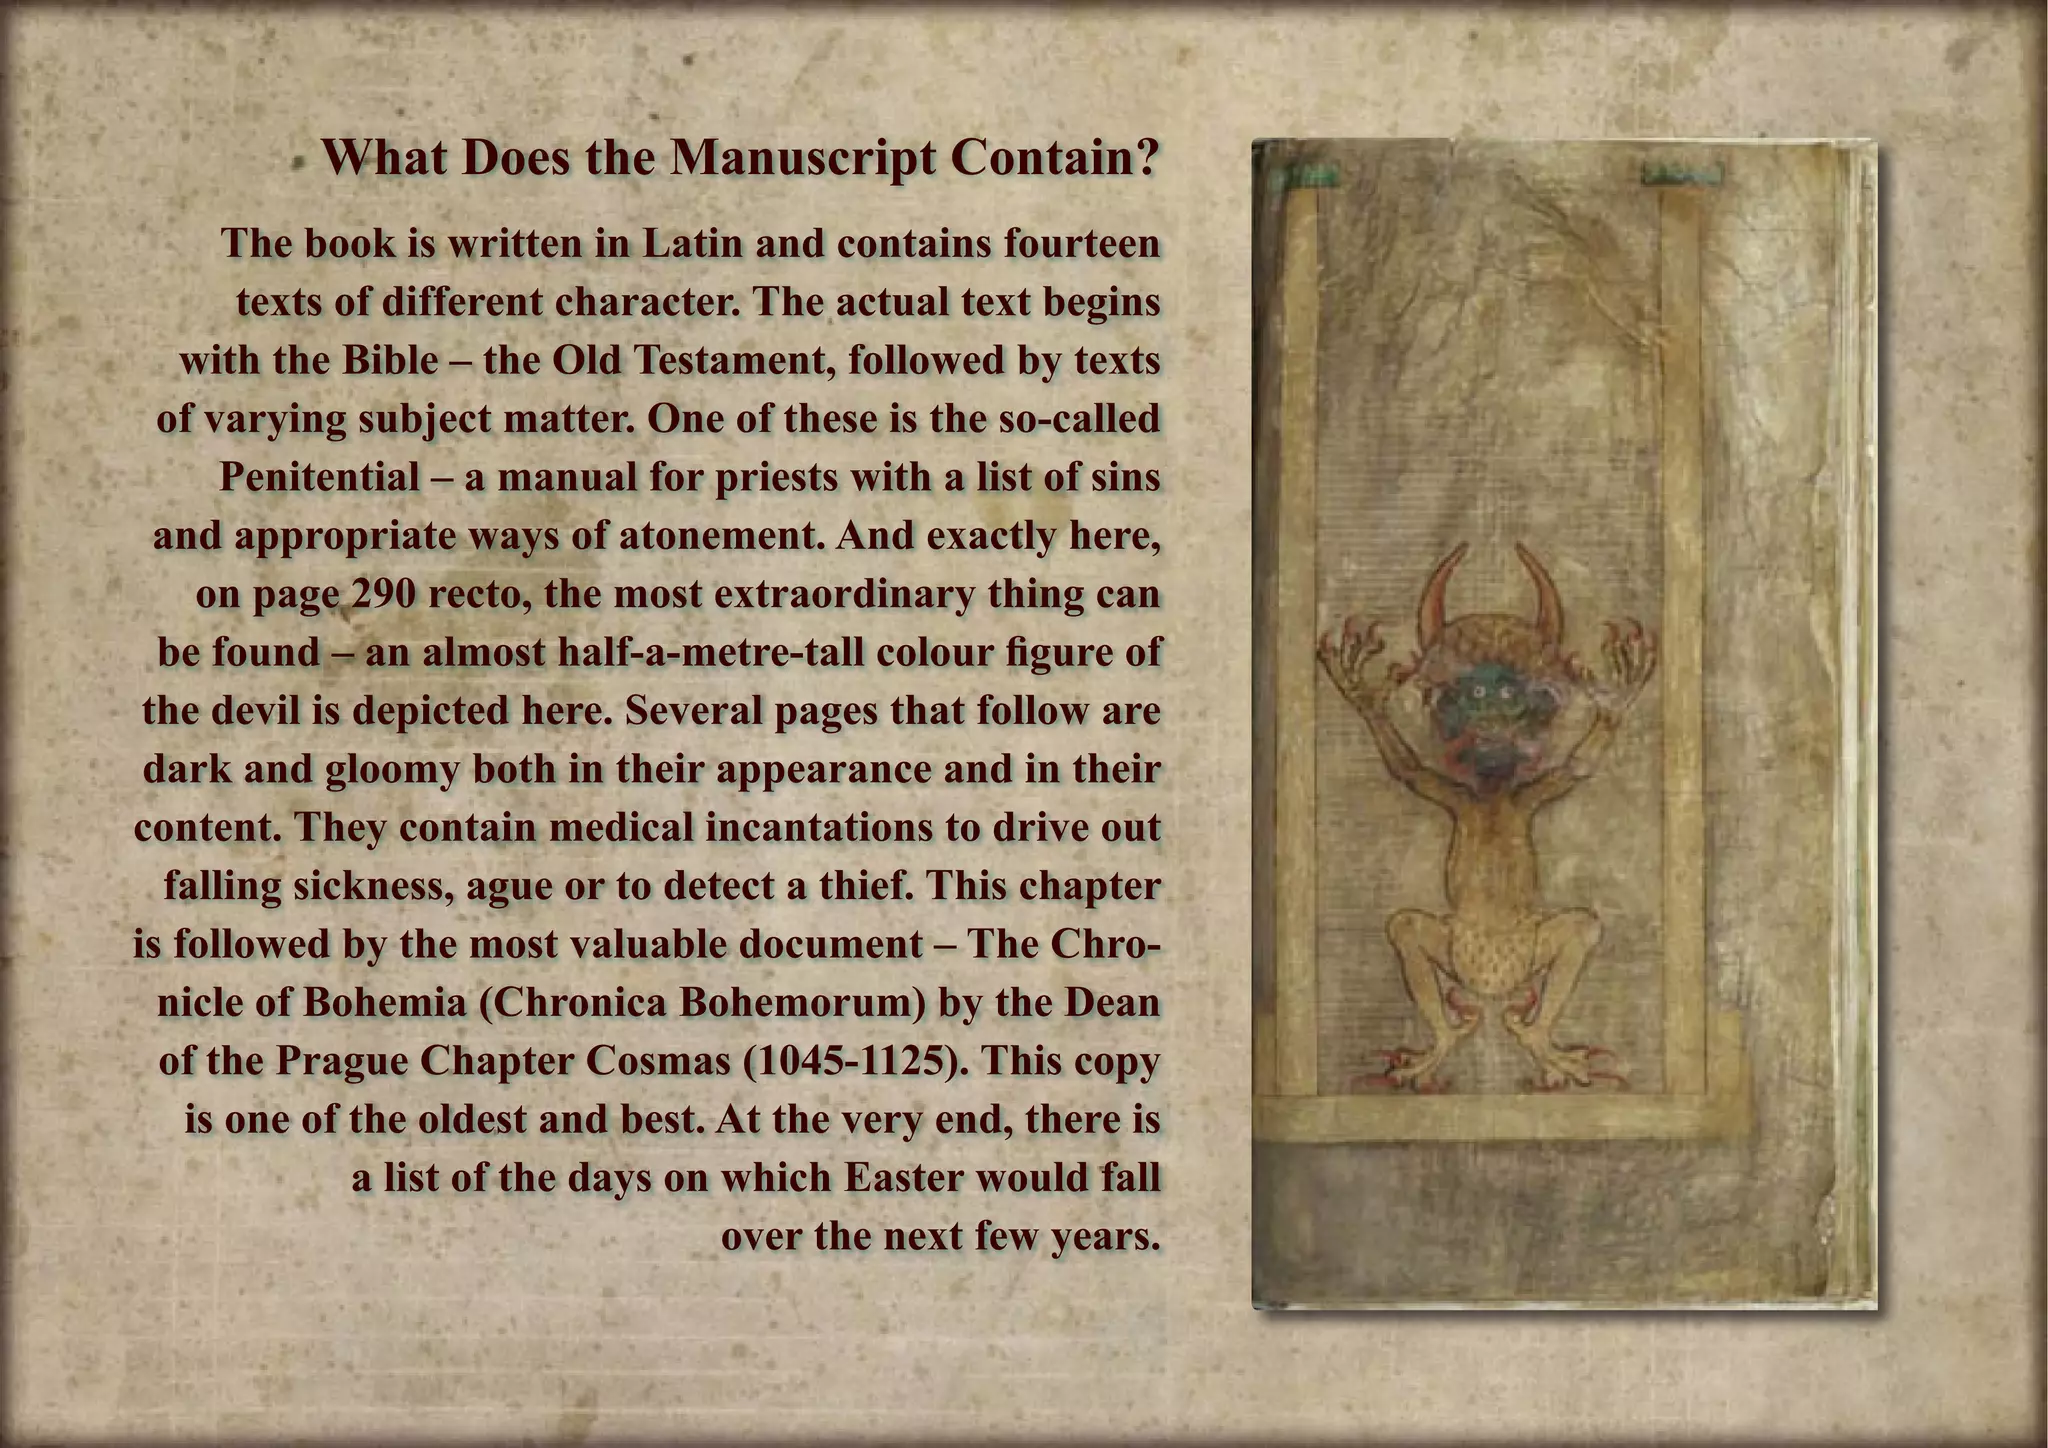
Once you have both the image PDF and the translation documents, the actual reading process requires a specific setup. I recommend using a dual-pane viewer or simply opening two windows side by side. The Latin text in the Codex Gigas is in a late medieval bookhand that is relatively legible, but the spelling varies significantly from classical Latin. Abbreviations are extensive — you'll see things like q standing for que (and), for non, and ē with a macron for em or um. If you're working through the Biblical portions, having a parallel Bible handy helps enormously because many passages match the Vulgate you'd encounter in any standard Latin Bible. The non-Biblical portions, particularly the medical and astronomical texts, don't have that luxury and require more careful checking against the translation documents. Most people assume the Codex Gigas was written by a single scribe. It wasn't. Paleographic analysis shows at least four different hands, possibly five, working in what appears to have been a Bohemian monastery around 1204 to 1230. The variation in script quality and layout suggests different sections were added at different times, potentially over several decades. This matters because when you're reading the translated text, the style and quality shift noticeably between sections. The Biblical texts are generally more carefully laid out and more consistently spelled. The appendices and marginalia — particularly the confessional and medical sections — show more variation and more scribal errors. A single English translation often smooths over these differences, making it seem like a uniform work when it isn't. Another thing that catches people off guard: the famous full-page illustration of the Devil is actually inserted into the page stream at a point that disrupts the layout of the surrounding text. The pages immediately before and after it show signs of being hastily completed, with smaller lettering and tighter spacing. This suggests the illustration was a later addition or that the scribe recognized it would require special planning and possibly disrupted the flow of work. It's one reason why the Devil illustration is always discussed in isolation — it doesn't quite fit the rest of the manuscript's structure.
Limitations You Should Know About
No existing English translation of the Codex Gigas is complete. The portions that are translated are primarily the Biblical books and some of the more prominent historical texts. Significant sections, particularly many of the medical recipes and the astronomical tables, remain inadequately translated or untranslated in any widely accessible format. Even the most thorough published efforts cover roughly 60 to 70 percent of the total content at a detailed level. The remainder is either in summary form or referenced only in passing. The digitized images themselves have their own issues. The original manuscript has suffered from moisture damage, insect activity, and general aging. Some folios are heavily stained or partially illegible. The Swedish National Library's digitization does an excellent job with what's recoverable, but there are spots where the text is simply lost to damage and no translation can help you there. I encountered this directly when trying to read a passage in the chronicle section where a significant portion of a page had been damaged by water. The translation documents I had available only covered what was legible, leaving a gap that no amount of cross-referencing could fill. The only honest answer in those cases is to check recent scholarly articles that may have proposed reconstructions based on other manuscript witnesses. If your goal is simply to understand the general content of the Codex Gigas, there are better starting points than diving into the raw PDF. Books like The Devil's Picture: The True Story of the Codex Gigas by Jan Melvil and Bjørn-Ove Åkerman provide context and selective translations that are more manageable. The full manuscript PDF is best suited for people who need to examine the original text directly — researchers, students of medieval Latin, or anyone working on a detailed project. For everyone else, the effort required to navigate the untranslated portions and deal with the file size issues often outweighs the benefit.