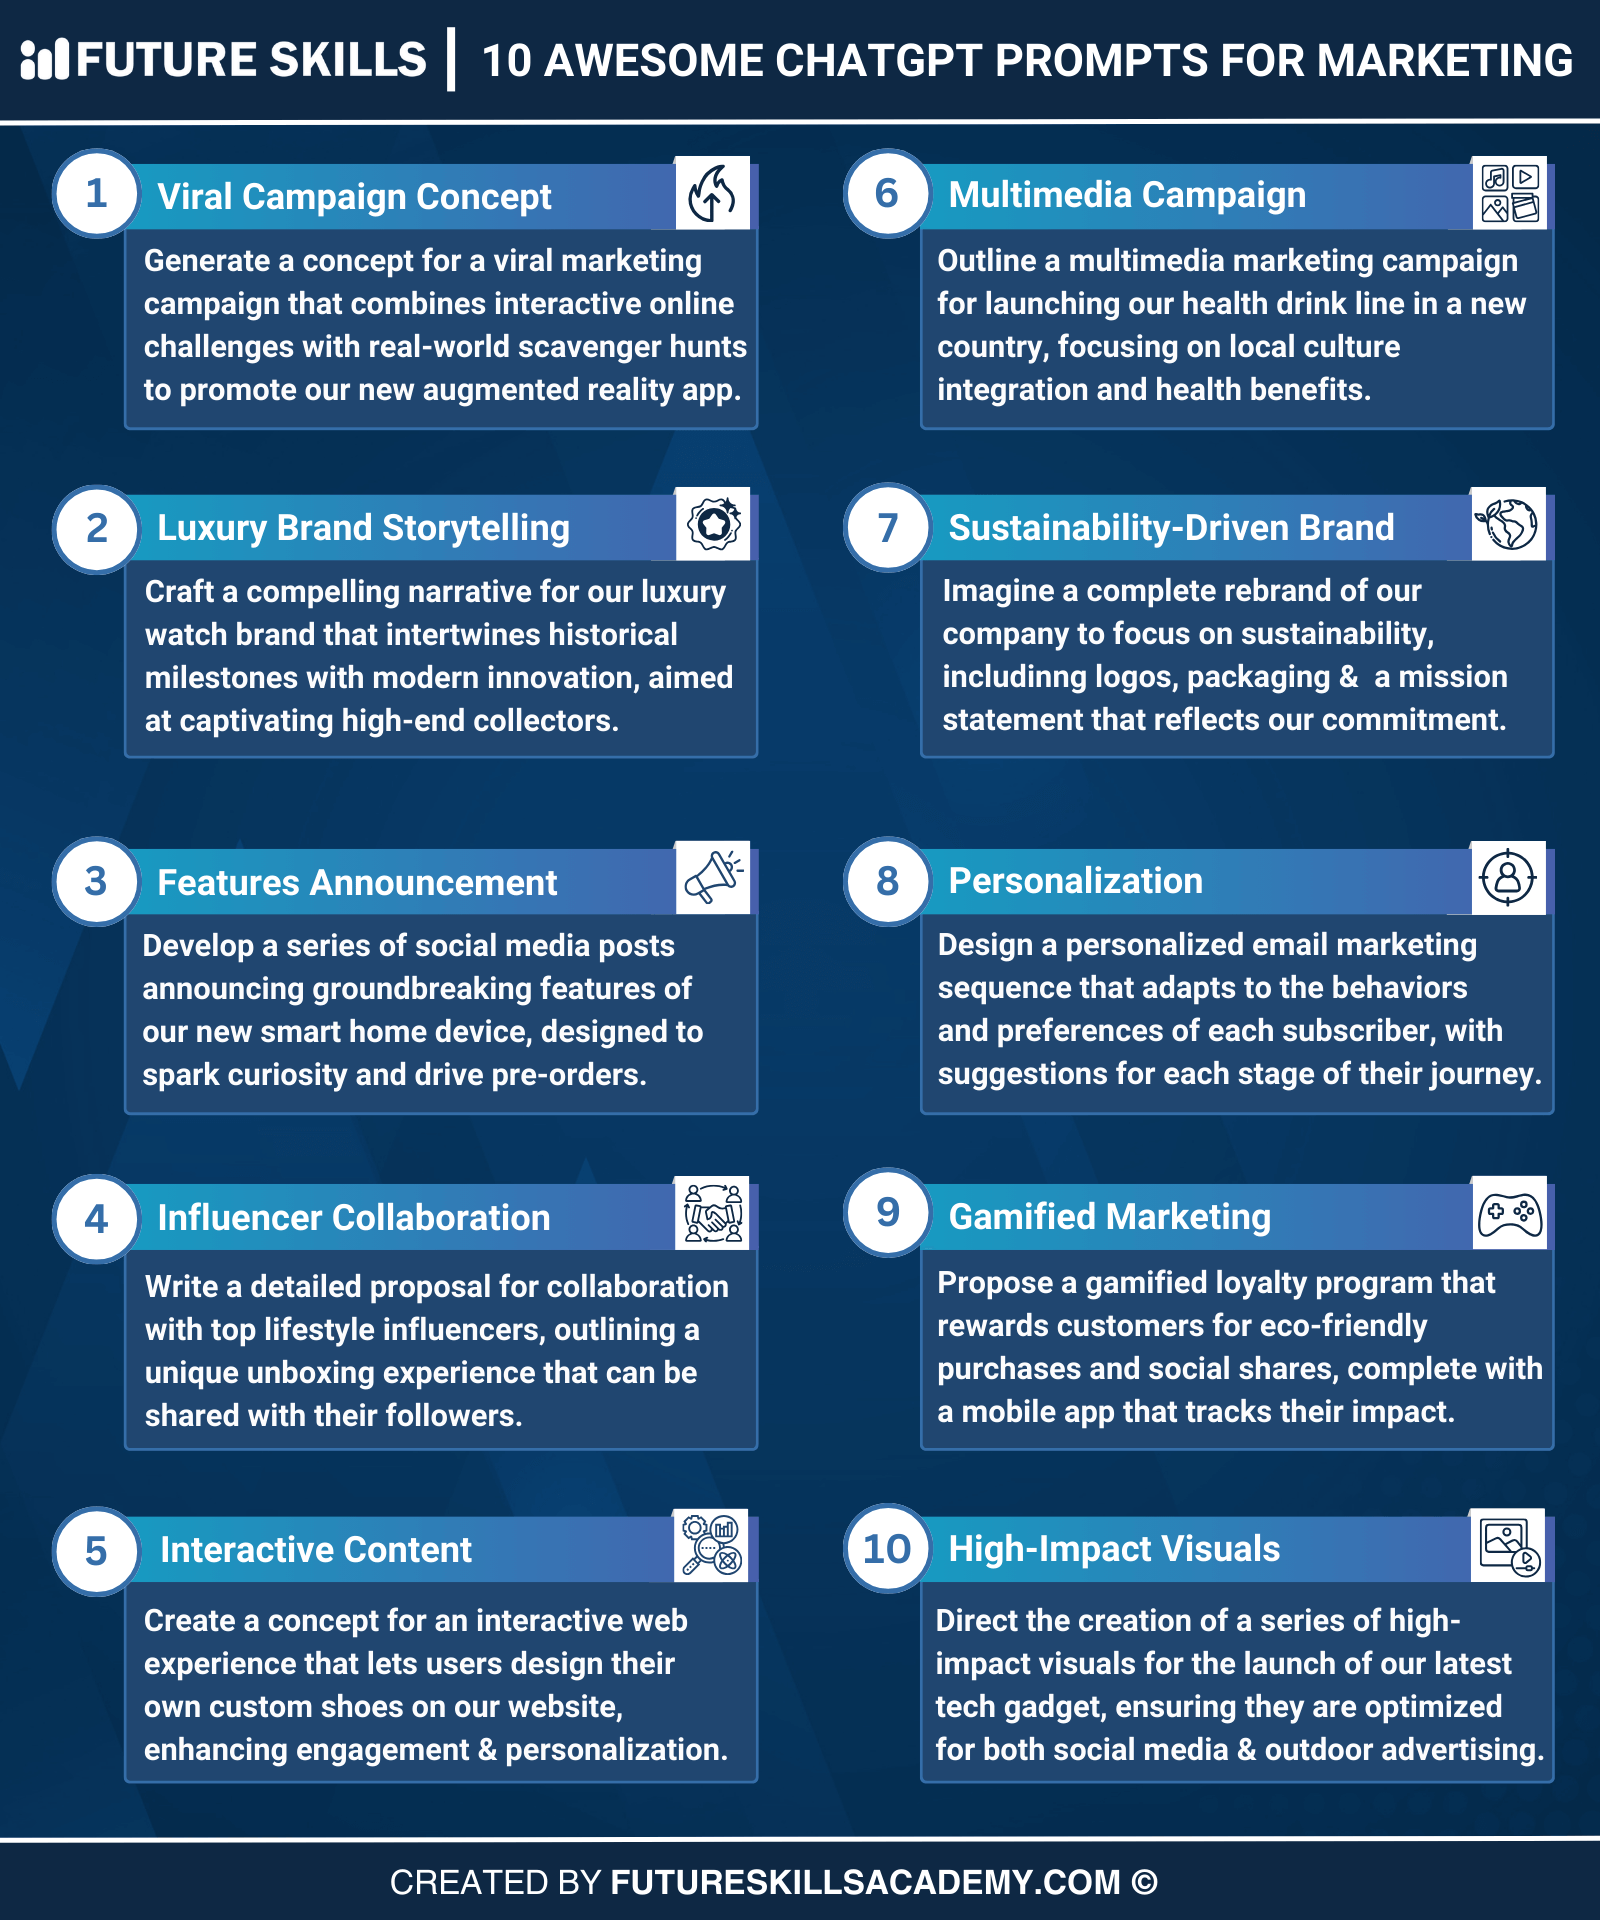
Marketing Prompt Engineering: A Practical Framework
Most people approach prompt writing the same way they approach spreadsheets - they open a blank screen, type something generic, and hope the output lands close enough to useful. I have watched teams burn through thousands of dollars on AI subscriptions only to produce content that sounds like it came from a corporate communications intern who has never actually met a customer. The problem is not the technology. The problem is structural. Marketing teams rarely invest time in understanding how their prompts actually function before they start generating at scale. I spent three years building prompt libraries for a B2B SaaS company. We started with ad copy variations for Google Ads. Within six months we were running campaigns across twelve countries with different language models producing everything from LinkedIn posts to technical documentation. The turning point came when we realized our prompts needed a consistent architecture. Not because it looked clean. Because without it, every new hire added their own variations and within two weeks we had forty-seven different versions of the same basic request competing for budget.
Understanding Comprehensive Marketing Prompts
Comprehensive Marketing Prompts refers to structured request templates that cover the full lifecycle of marketing content creation. This includes everything from initial strategy alignment through final distribution. The framework I use breaks into five layers. The first layer covers objective definition. Before you write a single word of output, your prompt must specify what success looks like numerically. Click-through rate targets. Conversion thresholds. Brand voice parameters. Vague objectives like "increase engagement" produce vague results. I learned this the hard way when a campaign targeting "brand awareness" generated content that was so generic our metrics plateaued after week three. The second layer addresses audience segmentation. Most marketers skip this or treat it as an afterthought. Your prompt should include demographic data, psychographic triggers, and known pain points. When I built a prompt set for a medical device company, we included specific physician specialization details. A neurosurgeon in their fifth year practices differently than one near retirement. The prompts had to reflect that nuance or the output would sound like it was written for a general practitioner.
Building Your First Prompt Architecture
Start with the context block. This includes your brand voice guidelines, target audience specifications, and historical performance data. Next comes the instruction layer. Be explicit about format, length, tone, and any constraints. Then add the examples section. Provide three to five high-performing pieces of content as reference material. Finally, include validation criteria. How will you know if the output meets your standards? Test this yourself before deploying it to your team. One counter-intuitive finding from my experience: longer prompts do not always produce better results. There is a threshold where additional context starts confusing the model. In practice, I found that 150 to 200 words of precise instructions outperform 500 words of loose guidance. The difference comes down to token efficiency. Models process information differently when you structure it with clear boundaries versus dumping raw context.
Get the Full Details

Common Pitfalls That Kill Performance
Beginners routinely over-specify tone. Writing "professional yet approachable and warm but not condescending" creates ambiguity. The model picks one interpretation and sticks with it. Better to define tone through concrete examples. Show three pieces of writing that match your desired outcome and let the model infer the pattern. This approach reduced our revision cycles by roughly forty percent in the first quarter of implementation. Another frequent mistake involves ignoring platform constraints. A prompt designed for LinkedIn will produce different results than one meant for Instagram captions. Platform algorithms favor different structures. LinkedIn rewards long-form storytelling with strategic paragraph breaks. Instagram captions perform better with conversational hooks and emoji placement. I stopped using single prompts across platforms and built separate architectures for each channel. Output quality improved measurably.
Measuring What Actually Matters
Track response quality against your validation criteria. Create a scoring rubric that rates outputs on accuracy, brand alignment, engagement potential, and conversion likelihood. Run A/B tests between your manual drafts and AI-generated content. When I compared prompts against human-written copy for email subject lines, the AI version won on open rates but lost on click-through rates. The prompts needed adjustment for the second step of the funnel. This revealed a gap in how my original design handled multi-step marketing workflows. Data collection should happen at the prompt level. Log which templates produce the best results for each content type. Build a performance database over six months. The patterns will surprise you. Technical documentation might respond well to shorter, more directive prompts while case studies benefit from elaborate background context. Do not assume one architecture fits all marketing deliverables.
Scaling Without Losing Quality
Once you have validated prompts, create a version control system. Document changes, track which team members modified which templates, and maintain a archive of successful variations. I use a simple spreadsheet with columns for prompt ID, modification date, author, intended use case, and performance metrics. When someone needs to update a template, they fill out the row and explain their reasoning. This created accountability and made it easier to rollback changes that degraded output quality. Training new team members should include hands-on prompt testing. Give them fifty prompts to evaluate against your rubric before they submit work. Most junior marketers can write good copy but struggle with prompt construction. The skill set overlaps but is not identical. Understanding how to sequence instructions, define constraints, and validate outputs requires separate development time.

When Prompts Fall Short
Not every marketing task responds well to prompt engineering. Highly creative brand campaigns often require human intuition that current models cannot replicate through text alone. Strategic messaging decisions involving sensitive corporate positioning should remain with experienced marketers. I recommend using prompt-based systems for repetitive, volume-heavy content like social media updates, email subject lines, and basic product descriptions. Reserve human judgment for campaigns where tone ambiguity could damage brand perception. If your team is struggling with output consistency, consider whether you actually need better prompts or a different tool. Some platforms handle context retention better than others. Enterprise clients often prefer Claude or GPT-4 class models for complex marketing workflows due to their extended context windows. Consumer-facing teams might find that lighter models plus better prompting produces sufficient quality at lower cost. The comprehensive marketing prompts framework saves time but only when implemented correctly. I recommend starting with one content type, testing thoroughly, measuring results, and expanding gradually. Teams that try to deploy fifty prompts simultaneously usually end up with nothing working well. Slow implementation beats rushed complexity every time.