Constants and Variables in Scientific Experiments
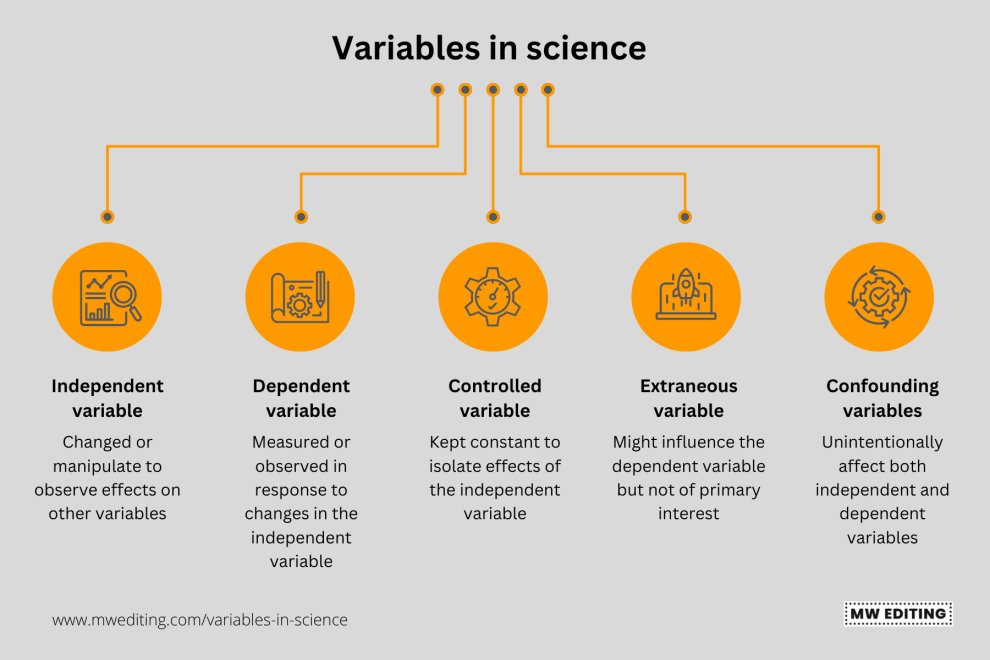
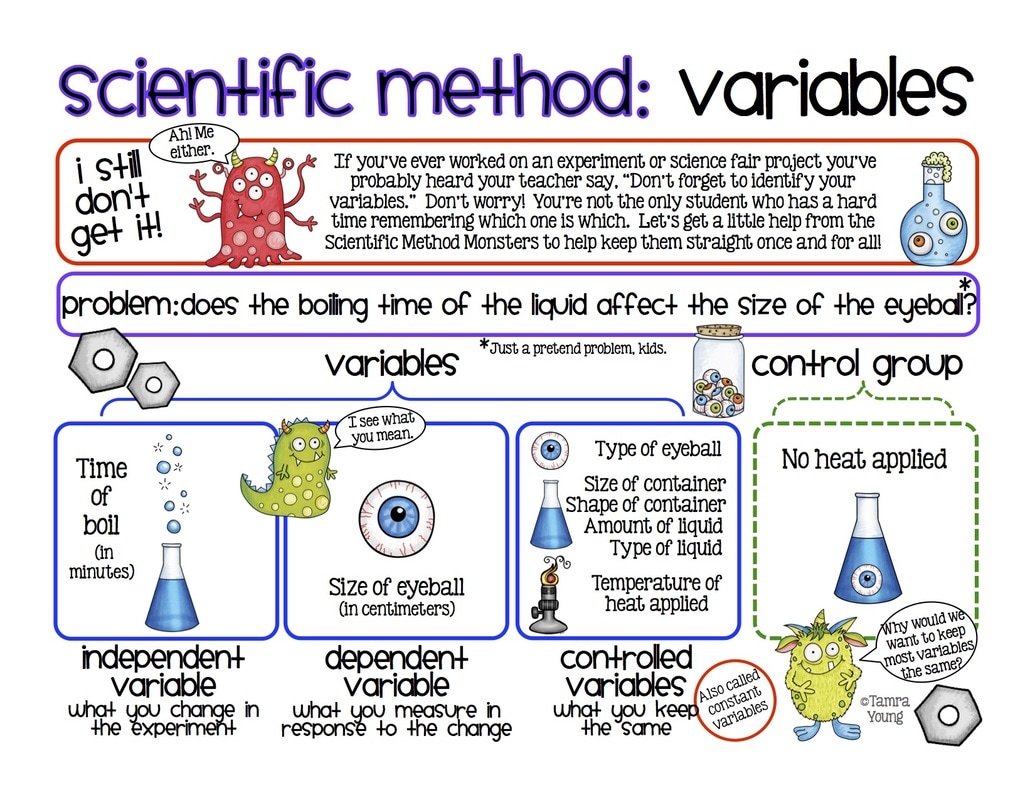
You run into this stuff early in any lab course. The idea is simple enough, but people still mess it up because they don't think carefully about what actually changes during an experiment. Here's how it works in practice. A controlled experiment has three types of variables. Your independent variable is the one you deliberately manipulate. Your dependent variable is what you measure in response. Your constant variables—sometimes called controlled variables—are everything you keep the same so the test stays fair. If you change two things at once, you have no idea which one caused the result. That's the whole point of identifying constants.
What Is a Constant Variable Example Science Classroom?
Let me give you a real example that comes up constantly in teaching labs. You're testing how light intensity affects the rate of photosynthesis in Elodea plants. Your independent variable is the distance of the lamp from the plant. Your dependent variable is the number of oxygen bubbles produced per minute. Your constant variables include the species of plant, the volume and concentration of sodium bicarbonate in the water, the temperature of the water, the size of the plant cutting, and the wavelength of light from the same bulb. Every single one of those has to stay identical across all trials. If you switch to a different plant species mid-experiment or let the water warm up because the lamp ran too long, your data is garbage. I learned that last piece the hard way. I was running a straightforward kinetics experiment where students measured enzyme reaction rates at different pH levels. The textbook procedure said to keep temperature constant at 25°C. I had six water baths going, and I thought using household ice baths was sufficient. About halfway through the week, I noticed the reaction times were drifting inconsistently between trials, not just randomly but with a slow trend. It took me two days of troubleshooting before I realized the ice was melting and the bath temperatures were slowly climbing by about 0.5 degrees per hour. The enzyme was warming up during the later trials, and it looked like pH was having some weird secondary effect when really it was just temperature creep. I ended up switching to a proper circulator water bath and recalibrating the entire dataset. Not a fun experience, and my students lost a full lab period because of it. That's the thing nobody warns you about. Constant variables aren't just settings you write down and ignore. They actively drift. Temperature shifts. Solution concentrations change as solvents evaporate. Humidity affects balance readings. Even the time of day can matter if you're working with biological samples that have circadian rhythms. Your constants are fighting entropy constantly, and you have to monitor them, not just set them once at the beginning.
Here's a nuance that trips people up: sometimes what looks like a constant variable actually shouldn't be. If you're doing an experiment across multiple trials on different days, ambient room temperature might legitimately vary, and that variation could be scientifically interesting rather than something to suppress. In that case, you're not controlling it as a constant, you're measuring it as a secondary independent variable. The distinction matters for your statistical analysis. If you blindly treat everything as a constant, you'll either miss real effects or worse, hide confounding factors that invalidate your conclusions. The practical workflow I use is pretty standard now. Before running anything, I write out a variable map on the bench. Three columns: independent, dependent, constant. For each constant, I note exactly how I'm controlling it and how I'm verifying it stays that way. "Temperature kept at 25°C" is not sufficient. "Temperature monitored with calibrated probe logged every 10 minutes to CSV" is sufficient. The difference is whether you can defend your results when someone asks questions later. If you want to download a template for tracking this, the University of Bristol has a free variable control spreadsheet that handles this well, and the HHMI BioInteractive site puts out a solid lab planning worksheet. Both are plain enough to adapt to any level of science class.
Get the Full Details

One more thing worth noting. There's a tendency among beginners to over-control. You don't need to lock down every possible variable in existence. Pick the ones that are relevant to the question you're actually asking. If you're testing how fertilizer concentration affects tomato growth, you don't need to control the exact humidity in the greenhouse unless humidity is part of your hypothesis. Adding unnecessary constraints just makes the experiment harder to run and introduces new failure points without improving the quality of your answer. Focus on the variables that could plausibly confound your specific independent-dependent relationship. Everything else is noise you can safely ignore. The hardest part is always figuring out what that list actually is. You have to understand the mechanism well enough to predict what could go wrong. That's why experienced researchers are better at designing clean experiments. They've seen which variables sneak in and bite you. It's not magic, it's just accumulated mistakes.